RFC 3275
(Extensible Markup Language) XML-Signature Syntax and Processing
RFC 3275: XML-Signature Syntax and Processing 💖
Okay bestie, this is RFC 3275, a Standards Track spec, so it's the real deal 👑 It's titled "(Extensible Markup Language) XML-Signature Syntax and Processing" and it's from the Network Working Group. It was written by D. Eastlake 3rd (Motorola), J. Reagle (W3C), and D. Solo (Citigroup), and it's dated March 2002. It obsoletes RFC 3075 and doesn't list anything it updates ✨
Status of this Memo 🎀
This is an Internet standards track protocol for the Internet community, and they are literally asking for your discussion and suggestions 🦋 For where it stands officially, check the current "Internet Official Protocol Standards" (STD 1). Distribution is unlimited, so share away 💅
Copyright Notice 🌈
Copyright (c) 2002 The Internet Society & W3C (MIT, INRIA, Keio), All Rights Reserved.
Abstract 🧚
So this doc spells out the rules and syntax for XML (Extensible Markup Language) digital signature processing 💜 XML Signatures give you integrity, message authentication, and/or signer authentication for data of any type. It doesn't matter if that data lives inside the XML with the signature or somewhere else 🫶
Table of Contents 🍓
1. Introduction...................................................  3
1.1 Editorial and Conformance Conventions.........................  4
1.2 Design Philosophy.............................................  4
1.3 Versions, Namespaces and Identifiers..........................  4
1.4 Acknowledgements..............................................  6
1.5 W3C Status....................................................  6
2. Signature Overview and Examples................................  7
2.1 Simple Example (Signature, SignedInfo, Methods, and References) 8
2.1.1 More on Reference...........................................  9
2.2 Extended Example (Object and SignatureProperty)............... 10
2.3 Extended Example (Object and Manifest)........................ 12
3.0 Processing Rules.............................................. 13
3.1 Core Generation............................................... 13
3.1.1 Reference Generation........................................ 13
3.1.2 Signature Generation........................................ 13
3.2 Core Validation............................................... 14
3.2.1 Reference Validation........................................ 14
3.2.2 Signature Validation........................................ 15
4.0 Core Signature Syntax......................................... 15
4.0.1 The ds:CryptoBinary Simple Type............................. 17
4.1 The Signature element......................................... 17
4.2 The SignatureValue Element.................................... 18
4.3 The SignedInfo Element........................................ 18
4.3.1 The CanonicalizationMethod Element.......................... 19
4.3.2 The SignatureMethod Element................................. 21
4.3.3 The Reference Element....................................... 21
4.3.3.1 The URI Attribute......................................... 22
4.3.3.2 The Reference Processing Model............................ 23
4.3.3.3 Same-Document URI-References.............................. 25
4.3.3.4 The Transforms Element.................................... 26
4.3.3.5 The DigestMethod Element.................................. 28
4.3.3.6 The DigestValue Element................................... 28
4.4 The KeyInfo Element........................................... 29
4.4.1 The KeyName Element......................................... 31
4.4.2 The KeyValue Element........................................ 31
4.4.2.1 The DSAKeyValue Element................................... 32
4.4.2.2 The RSAKeyValue Element................................... 33
4.4.3 The RetrievalMethod Element................................. 34
4.4.4 The X509Data Element........................................ 35
4.4.5 The PGPData Element......................................... 38
4.4.6 The SPKIData Element........................................ 39
4.4.7 The MgmtData Element........................................ 40
4.5 The Object Element............................................ 40
5.0 Additional Signature Syntax................................... 42
5.1 The Manifest Element.......................................... 42
5.2 The SignatureProperties Element............................... 43
5.3 Processing Instructions in Signature Elements................. 44
5.4 Comments in Signature Elements................................ 44
6.0 Algorithms.................................................... 44
6.1 Algorithm Identifiers and Implementation Requirements......... 44
6.2 Message Digests............................................... 46
6.2.1 SHA-1....................................................... 46
6.3 Message Authentication Codes.................................. 46
6.3.1 HMAC........................................................ 46
6.4 Signature Algorithms.......................................... 47
6.4.1 DSA......................................................... 47
6.4.2 PKCS1 (RSA-SHA1)............................................ 48
6.5 Canonicalization Algorithms................................... 49
6.5.1 Canonical XML............................................... 49
6.6 Transform Algorithms.......................................... 50
6.6.1 Canonicalization............................................ 50
6.6.2 Base64...................................................... 50
6.6.3 XPath Filtering............................................. 51
6.6.4 Enveloped Signature Transform............................... 54
6.6.5 XSLT Transform.............................................. 54
7. XML Canonicalization and Syntax Constraint Considerations...... 55
7.1 XML 1.0, Syntax Constraints, and Canonicalization............. 56
7.2 DOM/SAX Processing and Canonicalization....................... 57
7.3 Namespace Context and Portable Signatures..................... 58
8.0 Security Considerations....................................... 59
8.1 Transforms.................................................... 59
8.1.1 Only What is Signed is Secure............................... 60
8.1.2 Only What is 'Seen' Should be Signed........................ 60
8.1.3 'See' What is Signed........................................ 61
8.2 Check the Security Model...................................... 62
8.3 Algorithms, Key Lengths, Certificates, Etc.................... 62
9. Schema, DTD, Data Model, and Valid Examples.................... 63
10. Definitions................................................... 63
Appendix: Changes from RFC 3075................................... 67
References........................................................ 67
Authors' Addresses................................................ 72
Full Copyright Statement.......................................... 73
1. Introduction 🦋
Okay so this spec is all about the XML syntax and processing rules for making and representing digital signatures 💅 You can slap an XML Signature on basically any digital content (data object), XML included, and one signature can cover the content of one or more resources ✨
There are three flavors to know. Enveloped or enveloping signatures cover data inside the same XML document as the signature. Detached signatures cover data that lives outside the signature element 🎀 The spec defines an XML signature element type and an XML signature application. The conformance requirements for each are set out in schema definitions and prose respectively. It also has extra types for referencing collections of resources, algorithms, and keying and management info 💜
Here's the lowkey important part 👀 An XML Signature links a key to referenced data (octets). It does not normatively say how keys get tied to people or institutions, or what the referenced and signed data actually means 🙈 So even though this spec is a big piece of secure XML apps, it can't handle every app-level security and trust concern on its own. That's especially true if you're using signed XML (or other data formats) as the basis for human-to-human communication and agreement 😭 An app like that has to specify its own key, algorithm, processing, and rendering requirements. For more, check Security Considerations (section 8) 🔥
1.1 Editorial and Conformance Conventions 🧚
Real talk, for readability, brevity, and historic reasons, this doc uses the word "signature" to mean digital authentication values of all types 💖 Strictly speaking, though, "signature" is for authentication values based on public keys that give you signer authentication. When they're talking about authentication values based on symmetric secret key codes, they say authenticators or authentication codes instead. (See Check the Security Model, section 8.3.) 🌸
This spec comes with an XML Schema [XML-schema] and a DTD [XML]. The schema definition is the normative one ✨
Now the key words. The key words "MUST", "MUST NOT", "REQUIRED", "SHALL", "SHALL NOT", "SHOULD", "SHOULD NOT", "RECOMMENDED", "MAY", and "OPTIONAL" in this specification are to be interpreted as described in RFC2119 [KEYWORDS]:
"they MUST only be used where it is actually required for interoperation or to limit behavior which has potential for causing harm (e.g., limiting retransmissions)"
So these capitalized key words are how the spec unambiguously pins down requirements over protocol and application features and behavior that affect interoperability and security 🫶 They're not used in capitals to describe XML grammar, because schema definitions already describe that stuff clearly. The authors want to save that prominence for the natural-language parts of the protocol. For example, an XML attribute might be described as being "optional." Compliance with the Namespaces in XML specification [XML-ns] is described as "REQUIRED." 🎀
1.2 Design Philosophy 💅
If you want the design philosophy and requirements behind all this, the XML-Signature Requirements document [XML-Signature-RD] has you covered 🌈
1.3 Versions, Namespaces and Identifiers ✨
okay so there's no version number slot in this syntax 🙈 if we ever need a future version, it's getting its own namespace bestie. the XML namespace [XML-ns] URI that implementations MUST use for this (dated) spec is:
xmlns="http://www.w3.org/2000/09/xmldsig#"this namespace also doubles as the prefix for the algorithm identifiers in this spec 🎀 applications MUST support XML and XML namespaces, but using internal entities [XML] or our "dsig" XML namespace prefix and the defaulting/scoping conventions is OPTIONAL. we only use those tricks to make the examples compact and readable 💖
this spec uses Uniform Resource Identifiers [URI] to identify resources, algorithms, and semantics. the URI in the namespace declaration above is also the prefix for URIs under this spec's control 🦋 for stuff we don't control, we use the designated Uniform Resource Names [URN] or Uniform Resource Locators [URL] from its normative external spec. if an external spec hasn't allocated itself a URI, we allocate one under our own namespace. for example:
SignaturePropertiesis identified and defined by this spec's namespace:http://www.w3.org/2000/09/xmldsig#SignatureProperties- XSLT is identified and defined by an external URI:
http://www.w3.org/TR/1999/REC-xslt-19991116 - SHA1 is identified via this spec's namespace and defined via a normative reference:
http://www.w3.org/2000/09/xmldsig#sha1FIPS PUB 180-1. Secure Hash Standard. U.S. Department of Commerce/National Institute of Standards and Technology.
and to keep namespace declarations terse 🧚 we sometimes use XML internal entities [XML] inside URIs. like this:
<?xml version='1.0'?>
<!DOCTYPE Signature SYSTEM
  "xmldsig-core-schema.dtd" [ <!ENTITY dsig
  "http://www.w3.org/2000/09/xmldsig#"> ]>
<Signature xmlns="&dsig;" Id="MyFirstSignature">
  <SignedInfo>
  ...
1.4 Acknowledgements 🫶
the Working Group members who contributed to this spec get so much love 💜 thank you all:
- Mark Bartel, Accelio (Author)
- John Boyer, PureEdge (Author)
- Mariano P. Consens, University of Waterloo
- John Cowan, Reuters Health
- Donald Eastlake 3rd, Motorola (Chair, Author/Editor)
- Barb Fox, Microsoft (Author)
- Christian Geuer-Pollmann, University Siegen
- Tom Gindin, IBM
- Phillip Hallam-Baker, VeriSign Inc
- Richard Himes, US Courts
- Merlin Hughes, Baltimore
- Gregor Karlinger, IAIK TU Graz
- Brian LaMacchia, Microsoft (Author)
- Peter Lipp, IAIK TU Graz
- Joseph Reagle, W3C (Chair, Author/Editor)
- Ed Simon, XMLsec (Author)
- David Solo, Citigroup (Author/Editor)
- Petteri Stenius, DONE Information, Ltd
- Raghavan Srinivas, Sun
- Kent Tamura, IBM
- Winchel Todd Vincent III, GSU
- Carl Wallace, Corsec Security, Inc.
- Greg Whitehead, Signio Inc.
and the Last Call comments came from these legends too 🌸
- Dan Connolly, W3C
- Paul Biron, Kaiser Permanente, on behalf of the XML Schema WG.
- Martin J. Duerst, W3C; and Masahiro Sekiguchi, Fujitsu; on behalf of the Internationalization WG/IG.
- Jonathan Marsh, Microsoft, on behalf of the Extensible Stylesheet Language WG.
1.5 W3C Status 🌈
the World Wide Web Consortium Recommendation that matches this RFC lives at:
http://www.w3.org/TR/2002/REC-xmldsig-core-20020212/
2. Signature Overview and Examples 🔥
this section gives you the overview and examples of XML digital signature syntax 💅 the actual processing is in Processing Rules (section 3), and the formal syntax is in Core Signature Syntax (section 4) and Additional Signature Syntax (section 5).
in this section we use an informal representation and examples to show the structure of the XML signature syntax. they might skip some attributes, details and features that get fully explained later, so don't panic if something's missing 🙈
XML Signatures get applied to arbitrary digital content (data objects) through an indirection 🦋 the data objects get digested, the resulting value goes into an element (with other info), and then that element gets digested and cryptographically signed. XML digital signatures are represented by the Signature element, which looks like this (where "?" means zero or one occurrence; "+" means one or more occurrences; and "*" means zero or more occurrences):
<Signature ID?>
   <SignedInfo>
     <CanonicalizationMethod/>
     <SignatureMethod/>
     (<Reference URI? >
       (<Transforms>)?
       <DigestMethod>
       <DigestValue>
     </Reference>)+
   </SignedInfo>
   <SignatureValue>
  (<KeyInfo>)?
  (<Object ID?>)*
 </Signature>
signatures link to data objects through URIs [URI] 🧚 inside an XML document, signatures link to local data objects through fragment identifiers. that local data can be included within an enveloping signature, or it can enclose an enveloped signature. detached signatures cover external network resources or local data objects that live in the same XML document as sibling elements. in that case the signature is neither enveloping (signature is parent) nor enveloped (signature is child) 🎀 and since a Signature element (and its Id value/name) may co-exist or be combined with other elements (and their IDs) in a single XML document, care should be taken in choosing names so there are no later collisions that break the ID uniqueness validity constraint [XML]. this one's important bestie, don't skip it 😭
2.1 Simple Example (Signature, SignedInfo, Methods, and References) 💖
this example is a detached signature over the content of the HTML4 in XML specification 🍓
 [s01] <Signature Id="MyFirstSignature"
xmlns="http://www.w3.org/2000/09/xmldsig#">
 [s02]   <SignedInfo>
 [s03]   <CanonicalizationMethod
Algorithm="http://www.w3.org/TR/2001/REC-xml-c14n-20010315"/>
 [s04]   <SignatureMethod
Algorithm="http://www.w3.org/2000/09/xmldsig#dsa-sha1"/>
 [s05]   <Reference
URI="http://www.w3.org/TR/2000/REC-xhtml1-20000126/">
 [s06]     <Transforms>
 [s07]       <Transform
Algorithm="http://www.w3.org/TR/2001/REC-xml-c14n-20010315"/>
 [s08]     </Transforms>
 [s09]     <DigestMethod
Algorithm="http://www.w3.org/2000/09/xmldsig#sha1"/>
 [s10]     <DigestValue>j6lwx3rvEPO0vKtMup4NbeVu8nk=</DigestValue>
 [s11]   </Reference>
 [s12] </SignedInfo>
 [s13]   <SignatureValue>MC0CFFrVLtRlk=...</SignatureValue>
 [s14]   <KeyInfo>
 [s15a]    <KeyValue>
 [s15b]      <DSAKeyValue>
 [s15c]        <P>...</P><Q>...</Q><G>...</G><Y>...</Y>
 [s15d]      </DSAKeyValue>
 [s15e]    </KeyValue>
 [s16]   </KeyInfo>
 [s17] </Signature>
[s02-12] the required SignedInfo element is the info that actually gets signed 👑 core validation of SignedInfo has two mandatory processes: validating the signature over SignedInfo, and validating each Reference digest within SignedInfo. also, the algorithms used to calculate the SignatureValue are included in the signed info, even though the SignatureValue element sits outside SignedInfo. main character energy 💅
[s03] the CanonicalizationMethod is the algorithm used to canonicalize the SignedInfo element before it gets digested as part of the signature operation 🧚 heads up, this example (and every example in this spec) is not in canonical form, so don't be confused 🙈
[s04] the SignatureMethod is the algorithm that turns the canonicalized SignedInfo into the SignatureValue 🔥 it's a combo of a digest algorithm, a key dependent algorithm, and maybe other stuff like padding, for example RSA-SHA1. the algorithm names are signed so nobody can sneak in a weaker algorithm 🔒 to keep things interoperable between apps, we specify a set of signature algorithms that MUST be implemented, though whether to use them is up to the signature creator. we also specify additional algorithms as RECOMMENDED or OPTIONAL for implementation, and the design lets you plug in arbitrary user specified algorithms too 🌈
[s05-11] each Reference element includes the digest method and the resulting digest value, calculated over the identified data object 🦋 it can also include the transforms that produced the input to the digest operation. a data object gets signed by computing its digest value and then a signature over that value. the signature gets checked later through reference and signature validation ✨
[s14-16] KeyInfo tells you which key to use to validate the signature 🎀 the possible ways to identify it include certificates, key names, and key agreement algorithms and info, but we only define a few of those here. KeyInfo is optional for two reasons 🫶 first, the signer might not want to reveal key info to every document processing party. second, the info might already be known from the app's context, so it doesn't need to be written out explicitly. and since KeyInfo sits outside SignedInfo, if the signer wants to bind the keying info to the signature, a Reference can easily point at the KeyInfo and include it as part of the signature 💜
2.1.1 More on Reference ✨
okay so let's zoom in on that Reference element 🔍 💖
    [s05]   <Reference
   URI="http://www.w3.org/TR/2000/REC-xhtml1-20000126/">
    [s06]     <Transforms>
    [s07]       <Transform
   Algorithm="http://www.w3.org/TR/2001/REC-xml-c14n-20010315"/>
    [s08]     </Transforms>
    [s09]     <DigestMethod
   Algorithm="http://www.w3.org/2000/09/xmldsig#sha1"/>
    [s10]     <DigestValue>j6lwx3rvEPO0vKtMup4NbeVu8nk=</DigestValue>
    [s11]   </Reference>
[s05] okay so the optional URI attribute is how the Reference says which data object is getting signed 🎀 And here's the tea: it can be left out on at most one Reference in a Signature. The spec does this so every reference and object can be matched up without any confusion 🧩
[s05-08] this bit, plus the transforms, is basically the signer's diary entry about how they got the signed data and what it looked like when they digested it (the digested content, bestie 📖). The verifier is allowed to get the digested content another way, as long as the digest checks out ✅ Like, they could grab it from a local store instead of the URI. Main character flexibility 🦋
[s06-08] Transforms is an optional, ordered list of processing steps that got applied to the resource's content before it was digested 🧁 The list can have stuff like canonicalization, encoding and decoding (compression and inflation count too), XSLT, XPath, XML schema validation, or XInclude. The XPath transforms are the sneaky-cute ones 🙈 they let the signer build an XML document that leaves some parts of the source out, so those left-out parts can change without breaking the signature. For example, if the signed resource wraps around the signature itself, you have to use a transform like that to kick the signature value out of its own calculation 💀 If there's no Transforms element, the content just gets digested straight up. And while the Working Group came up with mandatory (and optional) canonicalization and decoding algorithms, user-specified transforms are also allowed 💜
[s09-10] DigestMethod is the algorithm that runs on the data after the Transforms (if there are any) to produce the DigestValue 🔐 Signing that DigestValue is what ties a resource's content to the signer's key. Iconic bond behavior 👑
2.2 Extended Example (Object and SignatureProperty)
Okay, plot twist: this spec does not try to handle statements or assertions 🙅♀️ What it does do is define what it means for something to be signed by an XML Signature, meaning integrity, message authentication, and/or signer authentication 🛡️ If an app wants other kinds of meaning, it has to lean on other tech, like [XML, RDF]. For instance, an app could slap a foo:assuredby attribute in its own markup to point at a Signature element 🌸 So it's the app's job to understand that and make trust calls based on whether the signature is valid and what assuredby syntax means. We also define a SignatureProperties element type so you can include assertions about the signature itself, like the signature semantics, the time of signing, or the serial number of the hardware used for the crypto stuff ⏰ Those assertions can be signed too, by putting a Reference to the SignatureProperties inside SignedInfo ✍️ The signing app should be super careful about what it signs (it should understand what's in the SignatureProperty), but a receiving app has zero obligation to understand that semantic, though its parent trust engine might want to 🧠 Any content about how the signature was generated can live inside the SignatureProperty element. And the mandatory Target attribute points at the Signature element the property belongs to 🎯
Okay, now let's look at the previous example, but with an extra Reference to a local Object that holds a SignatureProperty element 🧚 (A signature like this would be not only detached [p02] but also enveloping [p03]. Double threat 😭)
    [   ]  <Signature Id="MySecondSignature" ...>
    [p01]  <SignedInfo>
    [   ]   ...
    [p02]   <Reference URI="http://www.w3.org/TR/xml-stylesheet/">
    [   ]   ...
    [p03]   <Reference URI="#AMadeUpTimeStamp"
    [p04]
   Type="http://www.w3.org/2000/09/xmldsig#SignatureProperties">
    [p05]    <DigestMethod
   Algorithm="http://www.w3.org/2000/09/xmldsig#sha1"/>
    [p06]    <DigestValue>k3453rvEPO0vKtMup4NbeVu8nk=</DigestValue>
    [p07]   </Reference>
    [p08]  </SignedInfo>
    [p09]  ...
    [p10]  <Object>
    [p11]   <SignatureProperties>
    [p12]     <SignatureProperty Id="AMadeUpTimeStamp"
   Target="#MySecondSignature">
    [p13]        <timestamp xmlns="http://www.ietf.org/rfcXXXX.txt">
    [p14]          <date>19990908</date>
    [p15]          <time>14:34:34:34</time>
    [p16]        </timestamp>
    [p17]     </SignatureProperty>
    [p18]   </SignatureProperties>
    [p19]  </Object>
    [p20]</Signature>
[p04] okay so the optional Type attribute of a Reference gives info about the resource the URI points to 💫 It can say the thing is an Object, a SignatureProperty, or a Manifest element. Apps can use that to kick off special handling for certain Reference elements ✨ References to an XML data element inside an Object element SHOULD identify the actual element being pointed at 🎯 If the element content isn't XML (maybe it's binary or encoded data), the reference should identify the Object instead, and if a Reference Type is given, it SHOULD indicate Object 📦 Also, Type is advisory. Core behavior doesn't require acting on it or checking that it's right 🤷♀️
[p10] Object is an optional element for stuffing data objects inside the signature element, or somewhere else 🎁 It can be optionally typed and/or encoded 💅
[p11-18] Signature properties, like the time of signing, can optionally be signed by pointing at them from a Reference 🕰️ (People call these signature "attributes," even though that word has nothing to do with the XML term "attribute" 🙃 so yes, it's confusing, and yes, I'm already tired of it.)
2.3 Extended Example (Object and Manifest)
The Manifest element exists to cover extra needs that the mandatory parts of this spec don't handle directly 📋 Here are two of those needs and how the Manifest fixes them.
First, apps often need to sign a bunch of data objects efficiently, even when the signature operation is an expensive public key one 💸 You can do this by putting multiple Reference elements inside SignedInfo, since each digest secures the data it covers 🔒 BUT some apps don't want the core validation that comes with that, because it makes every Reference in SignedInfo go through reference validation (the DigestValue elements get checked) 😤 Those apps may want to keep the reference validation decision logic for themselves 👑 For example, an app might get a signature-valid SignedInfo with three Reference elements. If one of them fails (the data object, when digested, doesn't give the specified DigestValue), the signature fails core validation. But the app might want to treat the signature over the two good Reference elements as valid, or do different things depending on which one failed 🧐 To make that happen, SignedInfo refers to a Manifest element that holds one or more Reference elements (same structure as the ones in SignedInfo). Then reference validation of the Manifest is under the app's control 🎀
Second, think about an app where lots of signatures (using different keys) get applied to a huge pile of documents 📚 A wasteful approach would be to repeatedly sign one big SignedInfo element (with tons of References) once per key, separately 🙄 A much better move is to put all those references into a single Manifest, then reference that Manifest from multiple Signature elements 🧚♀️
The example below has a Reference that signs a Manifest sitting inside the Object element 🌈
    [   ] ...
    [m01]   <Reference URI="#MyFirstManifest"
    [m02]     Type="http://www.w3.org/2000/09/xmldsig#Manifest">
    [m03]     <DigestMethod
   Algorithm="http://www.w3.org/2000/09/xmldsig#sha1"/>
    [m04]     <DigestValue>345x3rvEPO0vKtMup4NbeVu8nk=</DigestValue>
    [m05]   </Reference>
    [   ] ...
    [m06] <Object>
    [m07]   <Manifest Id="MyFirstManifest">
    [m08]     <Reference>
    [m09]     ...
    [m10]     </Reference>
    [m11]     <Reference>
    [m12]     ...
    [m13]     </Reference>
    [m14]   </Manifest>
    [m15] </Object>
3.0 Processing Rules 🧠
okay so this section walks through the operations you do during signature generation and validation 🛠️
3.1 Core Generation
The REQUIRED steps include generating Reference elements and the SignatureValue over SignedInfo 🔥 These are non-negotiable, bestie 😤
3.1.1 Reference Generation
For each data object being signed 💖
- Apply the Transforms, as the application decides, to the data object.
- Calculate the digest value over the resulting data object.
- Create a
Referenceelement. It includes the (optional) identification of the data object, any (optional) transform elements, the digest algorithm, and theDigestValue. (Note, it's the canonical form of these references that gets signed in 3.1.2 and validated in 3.2.1 🧾)
3.1.2 Signature Generation
- Create a
SignedInfoelement withSignatureMethod,CanonicalizationMethod, andReference(s) ✨ - Canonicalize, and then calculate the
SignatureValueoverSignedInfobased on the algorithms specified inSignedInfo🧮 - Construct the
Signatureelement. It includesSignedInfo,Object(s) (if you want, the encoding can be different from the one used for signing),KeyInfo(if it's required), and theSignatureValue🎀
Note, if the Signature includes same-document references, [XML] or [XML-schema] validation of the document might introduce changes that break the signature 😭 So apps should be careful to process the document consistently, or just avoid external contributions (like defaults and entities) 🙈
3.2 Core Validation
The REQUIRED steps of core validation include (1) reference validation, which means verifying the digest contained in each Reference in SignedInfo, and (2) the cryptographic signature validation of the signature calculated over SignedInfo 🔐
Note, there may be valid signatures that some signature apps can't validate 🫤 Reasons for this include not implementing optional parts of this spec, being unable or unwilling to run the specified algorithms, or being unable or unwilling to dereference the specified URIs (some URI schemes may cause undesirable side effects), and so on 🌀
Comparison of values in reference and signature validation happens over the numeric (e.g., integer) or decoded octet sequence of the value 🔢 Different implementations may produce different encoded digest and signature values when processing the same resources, because of differences in encoding, like accidental white space 🫧 But if you use numeric or octet comparison (pick one!) on both the stated and computed values, those problems go away ✨
3.2.1 Reference Validation
- Canonicalize the SignedInfo element based on the CanonicalizationMethod in SignedInfo. 🎀
- For each Reference in SignedInfo: ✨
- 2.1 Obtain the data object to be digested. (For example, the signature application may dereference the URI and execute Transforms provided by the signer in the Reference element, or it may obtain the content through other means such as a local cache.) 🧚
- 2.2 Digest the resulting data object using the DigestMethod specified in its Reference specification. 💖
- 2.3 Compare the generated digest value against DigestValue in the SignedInfo Reference. If there is any mismatch, validation fails. 💀
Okay so, step 1 canonicalizes SignedInfo, which is the whole point 🫶. The application has to make sure the CanonicalizationMethod has no dangerous side affects, like rewriting URIs (see CanonicalizationMethod (section 4.3)), and that it Sees What is Signed, which is the canonical form. Main character energy means checking that what you verify is exactly what got signed 👑.
3.2.2 Signature Validation
- Obtain the keying information from KeyInfo or from an external source. 🔑
- Obtain the canonical form of the SignatureMethod using the CanonicalizationMethod and use the result (and previously obtained KeyInfo) to confirm the SignatureValue over the SignedInfo element. ✅
Note, KeyInfo (or some transformed version thereof) may be signed via a Reference element. Transformation and validation of this reference (3.2.1) is orthogonal to Signature Validation, which uses the KeyInfo as parsed. It's giving two separate checks that don't step on each other 🦋.
Additionally, the SignatureMethod URI may have been altered by the canonicalization of SignedInfo (e.g., absolutization of relative URIs), and it is the canonical form that MUST be used. However, the required canonicalization [XML-C14N] of this specification does not change URIs. So the URI you verify with is the canonical one, and for this spec's required canonicalization that's literally the same string 🌸.
4.0 Core Signature Syntax
The general structure of an XML signature is described in Signature Overview (section 2). This section provides detailed syntax of the core signature features. Features described in this section are mandatory to implement unless otherwise indicated. The syntax is defined via DTDs and [XML-Schema] with the following XML preamble, declaration, and internal entity. ✨
Schema Definition:
<?xml version="1.0" encoding="utf-8"?>
<!DOCTYPE schema
  PUBLIC "-//W3C//DTD XMLSchema 200102//EN"
"http://www.w3.org/2001/XMLSchema.dtd"
   [
     <!ATTLIST schema
       xmlns:ds CDATA #FIXED "http://www.w3.org/2000/09/xmldsig#">
     <!ENTITY dsig 'http://www.w3.org/2000/09/xmldsig#'>
     <!ENTITY % p ''>
     <!ENTITY % s ''>
    ]>

  <schema xmlns="http://www.w3.org/2001/XMLSchema"
          xmlns:ds="http://www.w3.org/2000/09/xmldsig#"
          targetNamespace="http://www.w3.org/2000/09/xmldsig#"
          version="0.1" elementFormDefault="qualified">
DTD:
<!--

The following entity declarations enable external/flexible content
in the Signature content model.

#PCDATA emulates schema:string; when combined with element types
it emulates schema mixed="true".

%foo.ANY permits the user to include their own element types from
other namespaces, for example:
  <!ENTITY % KeyValue.ANY '| ecds:ECDSAKeyValue'>
  ...
  <!ELEMENT ecds:ECDSAKeyValue (#PCDATA)  >

-->

<!ENTITY % Object.ANY ''>
<!ENTITY % Method.ANY ''>
<!ENTITY % Transform.ANY ''>
<!ENTITY % SignatureProperty.ANY ''>
<!ENTITY % KeyInfo.ANY ''>
<!ENTITY % KeyValue.ANY ''>
<!ENTITY % PGPData.ANY ''>
<!ENTITY % X509Data.ANY ''>
<!ENTITY % SPKIData.ANY ''>
4.0.1 The ds:CryptoBinary Simple Type
This specification defines the ds:CryptoBinary simple type for representing arbitrary-length integers (e.g., "bignums") in XML as octet strings. The integer value is first converted to a "big endian" bitstring. The bitstring is then padded with leading zero bits so that the total number of bits == 0 mod 8 (so that there are an integral number of octets). If the bitstring contains entire leading octets that are zero, these are removed (so the high-order octet is always non-zero). This octet string is then base64 [MIME] encoded. (The conversion from integer to octet string is equivalent to IEEE 1363's I2OSP [1363] with minimal length.) 🍓
This type is used by "bignum" values such as RSAKeyValue and DSAKeyValue. If a value can be of type base64Binary or ds:CryptoBinary, they are defined as base64Binary. For example, if the signature algorithm is RSA or DSA, then SignatureValue represents a bignum and could be ds:CryptoBinary. However, if HMAC-SHA1 is the signature algorithm, then SignatureValue could have leading zero octets that must be preserved. Thus SignatureValue is generically defined as of type base64Binary. 💅
Schema Definition:
<simpleType name="CryptoBinary">
  <restriction base="base64Binary">
  </restriction>
</simpleType>
4.1 The Signature element
The Signature element is the root element of an XML Signature. Implementation MUST generate laxly schema valid [XML-schema] Signature elements as specified by the following schema. 🌈
Schema Definition:
<element name="Signature" type="ds:SignatureType"/>
<complexType name="SignatureType">
  <sequence>
    <element ref="ds:SignedInfo"/>
    <element ref="ds:SignatureValue"/>
    <element ref="ds:KeyInfo" minOccurs="0"/>
    <element ref="ds:Object" minOccurs="0" maxOccurs="unbounded"/>
  </sequence>
  <attribute name="Id" type="ID" use="optional"/>
</complexType>
DTD:
<!ELEMENT Signature (SignedInfo, SignatureValue, KeyInfo?,
Object*)  >
<!ATTLIST Signature
 xmlns   CDATA   #FIXED 'http://www.w3.org/2000/09/xmldsig#'
 Id      ID  #IMPLIED >
4.2 The SignatureValue Element
The SignatureValue element contains the actual value of the digital signature; it is always encoded using base64 [MIME]. While we identify two SignatureMethod algorithms, one mandatory and one optional to implement, user specified algorithms may be used as well. 🦋
Schema Definition:
<element name="SignatureValue" type="ds:SignatureValueType"/>
<complexType name="SignatureValueType">
  <simpleContent>
    <extension base="base64Binary">
      <attribute name="Id" type="ID" use="optional"/>
    </extension>
  </simpleContent>
</complexType>
DTD:
<!ELEMENT SignatureValue (#PCDATA) >
<!ATTLIST SignatureValue
          Id  ID      #IMPLIED>
4.3 The SignedInfo Element
The structure of SignedInfo includes the canonicalization algorithm, a signature algorithm, and one or more references. The SignedInfo element may contain an optional ID attribute that will allow it to be referenced by other signatures and objects. 🫶
SignedInfo does not include explicit signature or digest properties (such as calculation time, cryptographic device serial number, etc.). If an application needs to associate properties with the signature or digest, it may include such information in a SignatureProperties element within an Object element. Lowkey the right place for all the extra details 🎀.
Schema Definition:
<element name="SignedInfo" type="ds:SignedInfoType"/>
<complexType name="SignedInfoType">
  <sequence>
    <element ref="ds:CanonicalizationMethod"/>
    <element ref="ds:SignatureMethod"/>
    <element ref="ds:Reference" maxOccurs="unbounded"/>
  </sequence>
  <attribute name="Id" type="ID" use="optional"/>
</complexType>
DTD:
<!ELEMENT SignedInfo (CanonicalizationMethod,
 SignatureMethod,  Reference+)  >
<!ATTLIST SignedInfo
 Id   ID      #IMPLIED
4.3.1 The CanonicalizationMethod Element ✨
okay bestie, CanonicalizationMethod is a required element 💅 it tells you which canonicalization algorithm gets run over the SignedInfo element before any signature math happens. It uses the usual algorithm-identifier setup from section 6.1 (Algorithm Identifiers and Implementation Requirements). Implementations MUST support the REQUIRED canonicalization algorithms 🫶
Other options, like Canonical XML with Comments (section 6.5.1) or a minimal canonicalization such as CRLF and charset normalization, MAY be explicitly specified, but they are NOT REQUIRED (section 6.5 is the list of the REQUIRED ones) 🌸 So they might not interoperate with apps that don't support them, see XML Canonicalization and Syntax Constraint Considerations in section 7. Non-XML-aware canonicalization can also get messy with entity processing and comments if it isn't properly constrained, so check section 8.2: Only What is "Seen" Should be Signed 😭
How SignedInfo gets handed to the canonicalization method depends on the method. For algorithms that process XML as nodes or characters:
- XML based canonicalization implementations MUST be provided with a [XPath] node-set that was originally formed from the document containing the SignedInfo, and that currently indicates the SignedInfo, its descendants, and the attribute and namespace nodes of SignedInfo and its descendant elements. 🦋
- Text based canonicalization algorithms (such as CRLF and charset normalization) should be provided with the UTF-8 octets that represent the well-formed SignedInfo element, from the first character to the last character of the XML representation, inclusive. That covers the whole start and end tags of SignedInfo, plus all the descendant markup and character data (aka the text) between those tags. Text based canonicalization of SignedInfo is NOT RECOMMENDED 🙈
We recommend that apps doing text-based canonicalization instead of XML-based, like resource-constrained apps, generate canonicalized XML as their output serialization. That helps with the interop and security stuff 🧚 For instance, that kind of implementation SHOULD (at least) generate standalone XML instances [XML] ✨
NOTE: The signature application must exercise great care in accepting and executing an arbitrary CanonicalizationMethod. 💀 For example, the canonicalization method could rewrite the URIs of the References being validated. Or it could massively transform SignedInfo so that validation always succeeds (like turning it into a trivial signature with a known key over trivial data). Since CanonicalizationMethod lives inside SignedInfo, the canonical form could erase itself from SignedInfo, or modify SignedInfo so it looks like a different canonicalization function was used! So a Signature that seems to authenticate the desired data with the desired key, DigestMethod, and SignatureMethod can be meaningless if a capricious CanonicalizationMethod is used. Not me being dramatic, but this is literally the whole vibe of a security warning 😭
Here's the schema and DTD:
Schema Definition:

<element name="CanonicalizationMethod"
         type="ds:CanonicalizationMethodType"/>
<complexType name="CanonicalizationMethodType" mixed="true">
  <sequence>
    <any namespace="##any" minOccurs="0" maxOccurs="unbounded"/>
    <!-- (0,unbounded) elements from (1,1) namespace -->
  </sequence>
  <attribute name="Algorithm" type="anyURI" use="required"/>
</complexType>

DTD:

<!ELEMENT CanonicalizationMethod (#PCDATA %Method.ANY;)* >
<!ATTLIST CanonicalizationMethod
 Algorithm CDATA #REQUIRED >
4.3.2 The SignatureMethod Element 🎀
SignatureMethod is a required element that specifies the algorithm used for signature generation and validation. This one is the big boss 👑 because it identifies ALL the crypto functions in the signature operation (hashing, public key algorithms, MACs, padding, and so on). It uses the general structure from section 6.1: Algorithm Identifiers and Implementation Requirements. There's a single identifier, but that identifier may specify a format containing multiple distinct signature values 🔥
Schema Definition:

<element name="SignatureMethod" type="ds:SignatureMethodType"/>
<complexType name="SignatureMethodType" mixed="true">
  <sequence>
    <element name="HMACOutputLength" minOccurs="0"
             type="ds:HMACOutputLengthType"/>
    <any namespace="##other" minOccurs="0" maxOccurs="unbounded"/>
    <!-- (0,unbounded) elements from (1,1) external namespace -->
   </sequence>
 <attribute name="Algorithm" type="anyURI" use="required"/>
</complexType>

DTD:

<!ELEMENT SignatureMethod
          (#PCDATA|HMACOutputLength %Method.ANY;)* >
<!ATTLIST SignatureMethod
 Algorithm CDATA #REQUIRED >
4.3.3 The Reference Element 🦋
Reference is an element that may show up one or more times ✨ It specifies a digest algorithm and digest value, and optionally an identifier for the object being signed, the object's type, and/or a list of transforms to run before digesting. The identification (URI) and transforms describe how the digested content (the input to the digest method) was created. The Type attribute helps with processing the referenced data. For example, this spec makes no requirements over external data, but an application may wish to signal that the referent is a Manifest 🧚 An optional ID attribute lets a Reference be referenced from somewhere else. Reference-ception 🤯
Schema Definition:

<element name="Reference" type="ds:ReferenceType"/>
<complexType name="ReferenceType">
  <sequence>
    <element ref="ds:Transforms" minOccurs="0"/>
    <element ref="ds:DigestMethod"/>
    <element ref="ds:DigestValue"/>
  </sequence>
  <attribute name="Id" type="ID" use="optional"/>
  <attribute name="URI" type="anyURI" use="optional"/>
  <attribute name="Type" type="anyURI" use="optional"/>
</complexType>

DTD:

<!ELEMENT Reference (Transforms?, DigestMethod, DigestValue)  >
<!ATTLIST Reference
 Id  ID  #IMPLIED
 URI CDATA   #IMPLIED
 Type    CDATA   #IMPLIED>
4.3.3.1 The URI Attribute 🌈
The URI attribute identifies a data object using a URI-Reference, as specified by RFC2396 [URI]. The allowed characters for URI attributes are the same as for XML, which is [Unicode]. BUT some Unicode characters are disallowed from URI references, including all non-ASCII characters and the excluded characters listed in RFC2396 [URI, section 2.4]. The number sign (#), percent sign (%), and square bracket characters re-allowed in RFC 2732 [URI-Literal] are permitted though 💖 Disallowed characters must be escaped like this:
- Each disallowed character is converted to [UTF-8] as one or more octets.
- Any octets corresponding to a disallowed character are escaped with the URI escaping mechanism (that is, converted to %HH, where HH is the hexadecimal notation of the octet value).
- The original character is replaced by the resulting character sequence.
XML signature applications MUST be able to parse URI syntax 🫶 We RECOMMEND they be able to dereference URIs in the HTTP scheme. Dereferencing a URI in the HTTP scheme MUST comply with the Status Code Definitions of [HTTP] (e.g., 302, 305 and 307 redirects are followed to obtain the entity-body of a 200 status code response). Applications should also be cognizant that protocol parameter and state information (like HTTP cookies, HTML device profiles, or content negotiation) may affect the content yielded by dereferencing a URI 🍓
If a resource is identified by more than one URI, the most specific should be used. For example, http://www.w3.org/2000/06/interop-pressrelease.html.en instead of http://www.w3.org/2000/06/interop-pressrelease. (See the Reference Validation (section 3.2.1) for further information on reference processing.) 🔥
If the URI attribute is omitted altogether, the receiving application is expected to know the identity of the object. For example, a lightweight data protocol might omit this attribute, since the identity of the object is part of the application context. This attribute may be omitted from at most one Reference in any particular SignedInfo, or Manifest 🙈
The optional Type attribute contains information about the type of object being signed. It's represented as a URI, for example:
Type="http://www.w3.org/2000/09/xmldsig#Object"
Type="http://www.w3.org/2000/09/xmldsig#Manifest"
The Type attribute applies to the item being pointed at, not its contents. For example, a reference that identifies an Object element containing a SignatureProperties element is still of type #Object 💅 The type attribute is advisory. No validation of the type information is required by this specification, so no drama there 🌸
4.3.3.2 The Reference Processing Model 🦋
Note: XPath is RECOMMENDED. Okay bestie, so signature apps don't have to fully follow the [XPath] spec to count as conforming 💅 The XPath data model, definitions like node-sets, and syntax are used in here so people who want to process XML-as-XML (instead of octets) can describe what they're doing. If you're into that, a conformant [XPath] implementation is one way to get there, but it's not required 🌸 You could also use a sufficiently functional stand-in for a node-set and only build the XPath expression behaviors REQUIRED by this specification. We're mostly going to talk in XPath terms without repeating this on every point, but "XPath node-sets" requirements can be met with a node-set equivalent, and XPath processing requirements can be met with application behaviors that match the XPath behavior ✨
The data-type of the result of URI dereferencing or subsequent Transforms is either an octet stream or an XPath node-set 🎀
The Transforms in this document are defined based on the input they need. Here's the default signature application behavior, and it's giving clear rules 💖
- If the data object is an octet stream and the next transform requires a node-set, the signature application MUST attempt to parse the octets yielding the required node-set via [XML] well-formed processing.
- If the data object is a node-set and the next transform requires octets, the signature application MUST attempt to convert the node-set to an octet stream using Canonical XML [XML-C14N].
Users can specify alternative transforms that override these defaults when moving between transforms that expect different inputs 🧚 The final octet stream holds the data octets being secured. Then the digest algorithm specified by DigestMethod gets applied to those data octets, which gives you the DigestValue 🔥
Unless the URI-Reference is a 'same-document' reference as defined in [URI, Section 4.2], the result of dereferencing the URI-Reference MUST be an octet stream. So an XML document identified by a URI doesn't get parsed by the signature application unless the URI is a same-document reference or a transform that needs XML parsing gets applied. (See Transforms (section 4.3.3.1).) 🙈
When a fragment comes after an absolute or relative URI in the URI-Reference, the meaning of the fragment is defined by the resource's MIME type. Even for XML documents, URI dereferencing (including the fragment processing) might be handled by a proxy for the signature application 😭 That means reference validation might fail if fragment processing isn't done in a standard way (as defined in the following section for same-document references). So we RECOMMEND that the URI attribute not include fragment identifiers, and that this processing get specified as an additional XPath Transform 🫶
When a fragment doesn't come after a URI in the URI-Reference, XML signature applications MUST support the null URI and barename XPointer 💅 We RECOMMEND support for the same-document XPointers '#xpointer(/)' and '#xpointer(id('ID'))' if the application also plans to support any canonicalization that preserves comments. (Otherwise URI="#foo" will automatically remove comments before the canonicalization can even be invoked.) Every other XPointer support is OPTIONAL 🌈 That especially goes for barename and other XPointers in external resources, since the application may not control how the fragment is generated (which leads to interoperability problems and validation failures) 💀
The following examples show what the URI attribute identifies and how it gets dereferenced 🍓
URI="http://example.com/bar.xml": Identifies the octets that represent the external resource 'http://example.com/bar.xml', which is probably an XML document given its file extension.URI="http://example.com/bar.xml#chapter1": Identifies the element with ID attribute value 'chapter1' of the external XML resource 'http://example.com/bar.xml', provided as an octet stream. Again, for the sake of interoperability, the element identified as 'chapter1' should be obtained using an XPath transform rather than a URI fragment (barename XPointer resolution in external resources is not REQUIRED in this specification).URI="": Identifies the node-set (minus any comment nodes) of the XML resource containing the signature.URI="#chapter1": Identifies a node-set containing the element with ID attribute value 'chapter1' of the XML resource containing the signature. XML Signature (and its applications) modify this node-set to include the element plus all descendents including namespaces and attributes -- but not comments. ✨
4.3.3.3 Same-Document URI-References 🌸
Dereferencing a same-document reference MUST result in an XPath node-set suitable for use by Canonical XML [XML-C14N]. Specifically, dereferencing a null URI (URI="") MUST result in an XPath node-set that includes every non-comment node of the XML document containing the URI attribute 🧁 In a fragment URI, the characters after the number sign ('#') character conform to the XPointer syntax [Xptr]. When processing an XPointer, the application MUST behave as if the root node of the XML document containing the URI attribute were used to initialize the XPointer evaluation context. The application MUST behave as if the result of XPointer processing were a node-set derived from the resultant location-set as follows:
- discard point nodes
- replace each range node with all XPath nodes having full or partial content within the range
- replace the root node with its children (if it is in the node-set)
- replace any element node E with E plus all descendants of E (text, comment, PI, element) and all namespace and attribute nodes of E and its descendant elements.
- if the URI is not a full XPointer, then delete all comment nodes
The second to last replacement is necessary because XPointer usually points at a subtree of an XML document's parse tree by using just the element node at the root of that subtree 🦋 Canonical XML, on the other hand, treats a node-set as a set of nodes, so if descendant nodes are missing, their text is missing from the canonical form too 🫠
The last step is done for null URIs, barename XPointers and child sequence XPointers. It's needed because when [XML-C14N] gets passed a node-set, it processes that node-set as is, with or without comments. It only invokes its own XPath expressions (default or without comments) when it's called with an octet stream 👑 So to keep the default of stripping comments when passed a node-set, they get removed in the last step if the URI is not a full XPointer. To keep comments while selecting an element by an identifier ID, use the following full XPointer: URI='#xpointer(id('ID'))'. To keep comments while selecting the entire document, use the following full XPointer: URI='#xpointer(/)'. This XPointer has a simple XPath expression that includes the root node, which the second to last step above replaces with all nodes of the parse tree (all descendants, plus all attributes, plus all namespaces nodes) 🧚
4.3.3.4 The Transforms Element 💜
The optional Transforms element holds an ordered list of Transform elements, and these describe how the signer got the data object that was digested 🎀 The output of each Transform is the input to the next one. The input to the first Transform is the result of dereferencing the URI attribute of the Reference element. The output from the last Transform is the input for the DigestMethod algorithm. When transforms get applied, the signer isn't signing the native (original) document, but the resulting (transformed) document 😭 (See Only What is Signed is Secure (section 8.1).)
Each Transform has an Algorithm attribute, plus content parameters if any apply to that algorithm 🌈 The Algorithm attribute value names the algorithm to run, and the Transform content gives extra data to control how the algorithm processes the transform input. (See Algorithm Identifiers and Implementation Requirements (section 6).) As described in The Reference Processing Model (section 4.3.3.2), some transforms take an XPath node-set as input while others need an octet stream. If the actual input matches what the transform needs, the transform works on the unaltered input. If the transform's input requirement is different from the format of the actual input, then the input has to be converted 🍓
Some Transforms may need explicit MIME type, charset (IANA registered "character set"), or other such information about the data they receive from an earlier Transform or the source data, even though no Transform algorithm specified in this document needs that explicit information 🙈 Data characteristics like that are given as parameters to the Transform algorithm and should be described in the specification for that algorithm.
Examples of transforms include but are not limited to base64 decoding [MIME], canonicalization [XML-C14N], XPath filtering [XPath], and XSLT [XSLT] 💅 The generic definition of the Transform element also allows application-specific transform algorithms. For example, the transform could be a decompression routine given by a Java class appearing as a base64 encoded parameter to a Java Transform algorithm. However, applications should refrain from using application-specific transforms if they want their signatures to be verifiable outside of their application domain 🫶 Transform Algorithms (section 6.6) define the list of standard transformations ✨
Schema Definition:
<element name="Transforms" type="ds:TransformsType"/>
<complexType name="TransformsType">
  <sequence>
    <element ref="ds:Transform" maxOccurs="unbounded"/>
  </sequence>
</complexType>

<element name="Transform" type="ds:TransformType"/>
<complexType name="TransformType" mixed="true">
  <choice minOccurs="0" maxOccurs="unbounded">
    <any namespace="##other" processContents="lax"/>
    <!-- (1,1) elements from (0,unbounded) namespaces -->
    <element name="XPath" type="string"/>
  </choice>
  <attribute name="Algorithm" type="anyURI" use="required"/>
</complexType>
DTD:
<!ELEMENT Transforms (Transform+)>

<!ELEMENT Transform (#PCDATA|XPath %Transform.ANY;)* >
<!ATTLIST Transform
 Algorithm    CDATA    #REQUIRED >

<!ELEMENT XPath (#PCDATA) >
4.3.3.5 The DigestMethod Element 🌸
okay so DigestMethod is required, bestie 💅 It tells you which digest algorithm gets applied to the signed object. This element uses the general structure here for algorithms specified in Algorithm Identifiers and Implementation Requirements (section 6.1).
If the result of the URI dereference and application of Transforms is an XPath node-set (or sufficiently functional replacement implemented by the application), then it must be converted as described in the Reference Processing Model (section 4.3.3.2). If the result of URI dereference and application of transforms is an octet stream, then no conversion occurs (comments might be present if the Canonical XML with Comments was specified in the Transforms). The digest algorithm is applied to the data octets of the resulting octet stream. 🦋
Schema Definition:
<element name="DigestMethod" type="ds:DigestMethodType"/>
<complexType name="DigestMethodType" mixed="true">
  <sequence>
    <any namespace="##other" processContents="lax"
         minOccurs="0" maxOccurs="unbounded"/>
  </sequence>
  <attribute name="Algorithm" type="anyURI" use="required"/>
</complexType>
DTD:
<!ELEMENT DigestMethod (#PCDATA %Method.ANY;)* >
<!ATTLIST DigestMethod
 Algorithm       CDATA   #REQUIRED >
4.3.3.6 The DigestValue Element 🍓
DigestValue is the element that holds the encoded value of the digest. The digest is always encoded using base64 [MIME]. 💖
Schema Definition:
<element name="DigestValue" type="ds:DigestValueType"/>
<simpleType name="DigestValueType">
  <restriction base="base64Binary"/>
</simpleType>
DTD:
<!ELEMENT DigestValue  (#PCDATA)  >
<!-- base64 encoded digest value -->
4.4 The KeyInfo Element 🔑
okay this one is so iconic 😭 KeyInfo is an optional element that helps the recipient(s) get the key they need to validate the signature. KeyInfo may contain keys, names, certificates and other public key management information, such as in-band key distribution or key agreement data. This specification defines a few simple types, but applications can extend those types or totally replace them with their own key identification and exchange semantics using the XML namespace facility. [XML-ns] However, questions of trust for that key information (e.g., its authenticity or strength) are out of scope of this specification and left to the application. ✨
If KeyInfo is omitted, the recipient is expected to be able to identify the key based on application context. Multiple declarations within KeyInfo refer to the same key. Applications may define and use any mechanism they choose through inclusion of elements from a different namespace, but compliant versions MUST implement KeyValue (section 4.4.2) and SHOULD implement RetrievalMethod (section 4.4.3). 🎀
The schema and DTD specifications of many of KeyInfo's children (e.g., PGPData, SPKIData, X509Data) allow their content to be extended or complemented with elements from another namespace. This may be done only if it is safe to ignore these extension elements while claiming support for the types defined in this specification. Otherwise, external elements, including alternative structures to those defined by this specification, MUST be a child of KeyInfo. For example, should a complete XML-PGP standard be defined, its root element MUST be a child of KeyInfo. (Of course, new structures from external namespaces can incorporate elements from the &dsig; namespace via features of the type definition language. For instance, they can create a DTD that mixes their own and dsig qualified elements, or a schema that permits, includes, imports, or derives new types based on &dsig; elements.) 🧚
The following list summarizes the KeyInfo types that are allocated an identifier in the &dsig; namespace. These can be used within the RetrievalMethod Type attribute to describe a remote KeyInfo structure:
http://www.w3.org/2000/09/xmldsig#DSAKeyValuehttp://www.w3.org/2000/09/xmldsig#RSAKeyValuehttp://www.w3.org/2000/09/xmldsig#X509Datahttp://www.w3.org/2000/09/xmldsig#PGPDatahttp://www.w3.org/2000/09/xmldsig#SPKIDatahttp://www.w3.org/2000/09/xmldsig#MgmtData
In addition to the types above, which have an XML structure defined here, we specify one more type to indicate a binary (ASN.1 DER) X.509 Certificate:
Schema Definition:
<element name="KeyInfo" type="ds:KeyInfoType"/>
<complexType name="KeyInfoType" mixed="true">
  <choice maxOccurs="unbounded">
    <element ref="ds:KeyName"/>
    <element ref="ds:KeyValue"/>
    <element ref="ds:RetrievalMethod"/>
    <element ref="ds:X509Data"/>
    <element ref="ds:PGPData"/>
    <element ref="ds:SPKIData"/>
    <element ref="ds:MgmtData"/>
    <any processContents="lax" namespace="##other"/>
    <!-- (1,1) elements from (0,unbounded) namespaces -->
  </choice>
  <attribute name="Id" type="ID" use="optional"/>
</complexType>
DTD:
<!ELEMENT KeyInfo (#PCDATA|KeyName|KeyValue|RetrievalMethod|
            X509Data|PGPData|SPKIData|MgmtData %KeyInfo.ANY;)* >
<!ATTLIST KeyInfo
 Id  ID   #IMPLIED >
4.4.1 The KeyName Element 🏷️
The KeyName element holds a string value (in which white space is significant) that the signer can use to tell the recipient a key identifier. Typically, KeyName contains an identifier related to the key pair used to sign the message, but it may contain other protocol-related information that indirectly identifies a key pair. (Common uses of KeyName include simple string names for keys, a key index, a distinguished name (DN), an email address, etc.) 💅
Schema Definition:
<element name="KeyName" type="string"/>DTD:
<!ELEMENT KeyName (#PCDATA) >4.4.2 The KeyValue Element 💜
The KeyValue element contains a single public key that may be useful in validating the signature. Structured formats for defining DSA (REQUIRED) and RSA (RECOMMENDED) public keys are defined in Signature Algorithms (section 6.4). The KeyValue element may include externally defined public key values represented as PCDATA or as element types from an external namespace. 🌈
Schema Definition:
<element name="KeyValue" type="ds:KeyValueType"/>
<complexType name="KeyValueType" mixed="true">
 <choice>
   <element ref="ds:DSAKeyValue"/>
   <element ref="ds:RSAKeyValue"/>
   <any namespace="##other" processContents="lax"/>
 </choice>
</complexType>
DTD:
<!ELEMENT KeyValue (#PCDATA|DSAKeyValue|RSAKeyValue
                    %KeyValue.ANY;)* >
4.4.2.1 The DSAKeyValue Element 🔐
- Identifier:
Type="http://www.w3.org/2000/09/xmldsig#DSAKeyValue"(this can be used within a RetrievalMethod or Reference element to identify the referent's type)
DSA keys and the DSA signature algorithm are specified in [DSS]. DSA public key values can have the following fields:
P: a prime modulus meeting the [DSS] requirementsQ: an integer in the range2**159 < Q < 2**160which is a prime divisor ofP-1G: an integer with certain properties with respect to P and QY:G**X mod P(where X is part of the private key and not made public)J:(P - 1) / Qseed: a DSA prime generation seedpgenCounter: a DSA prime generation counter
Parameter J is available for inclusion solely for efficiency, as it is calculatable from P and Q. Parameters seed and pgenCounter are used in the DSA prime number generation algorithm specified in [DSS]. As such, they are optional, but must either both be present or both be absent. This prime generation algorithm is designed to provide assurance that a weak prime is not being used, and it yields a P and Q value. Parameters P, Q, and G can be public and common to a group of users. They might be known from application context. As such, they are optional, but P and Q must either both appear or both be absent. If all of P, Q, seed, and pgenCounter are present, implementations are not required to check if they are consistent and are free to use either P and Q or seed and pgenCounter. All parameters are encoded as base64 [MIME] values. 🧠
Arbitrary-length integers (e.g., "bignums" such as RSA moduli) are represented in XML as octet strings, as defined by the ds:CryptoBinary type.
Schema Definition:
<element name="DSAKeyValue" type="ds:DSAKeyValueType"/>
<complexType name="DSAKeyValueType">
  <sequence>
    <sequence minOccurs="0">
      <element name="P" type="ds:CryptoBinary"/>
      <element name="Q" type="ds:CryptoBinary"/>
    </sequence>
    <element name="G" type="ds:CryptoBinary" minOccurs="0"/>
    <element name="Y" type="ds:CryptoBinary"/>
    <element name="J" type="ds:CryptoBinary" minOccurs="0"/>
    <sequence minOccurs="0">
      <element name="Seed" type="ds:CryptoBinary"/>
      <element name="PgenCounter" type="ds:CryptoBinary"/>
    </sequence>
  </sequence>
</complexType>
DTD Definition:
<!ELEMENT DSAKeyValue ((P, Q)?, G?, Y, J?, (Seed, PgenCounter)?) >
<!ELEMENT P (#PCDATA) >
<!ELEMENT Q (#PCDATA) >
<!ELEMENT G (#PCDATA) >
<!ELEMENT Y (#PCDATA) >
<!ELEMENT J (#PCDATA) >
<!ELEMENT Seed (#PCDATA) >
<!ELEMENT PgenCounter (#PCDATA) >
4.4.2.2 The RSAKeyValue Element 🦄
- Identifier:
Type="http://www.w3.org/2000/09/xmldsig#RSAKeyValue"(this can be used within a RetrievalMethod or Reference element to identify the referent's type)
RSA key values have two fields: Modulus and Exponent. 👑
<RSAKeyValue>
  <Modulus>
   xA7SEU+e0yQH5rm9kbCDN9o3aPIo7HbP7tX6WOocLZAtNfyxSZDU16ksL6W
   jubafOqNEpcwR3RdFsT7bCqnXPBe5ELh5u4VEy19MzxkXRgrMvavzyBpVRg
   BUwUlV5foK5hhmbktQhyNdy/6LpQRhDUDsTvK+g9Ucj47es9AQJ3U=
  </Modulus>
  <Exponent>AQAB</Exponent>
</RSAKeyValue>
Arbitrary-length integers (e.g., "bignums" such as RSA moduli) are represented in XML as octet strings, as defined by the ds:CryptoBinary type. ⭐
Schema Definition:
<element name="RSAKeyValue" type="ds:RSAKeyValueType"/>
<complexType name="RSAKeyValueType">
  <sequence>
    <element name="Modulus" type="ds:CryptoBinary"/>
    <element name="Exponent" type="ds:CryptoBinary"/>
  </sequence>
</complexType>
DTD Definition:
<!ELEMENT RSAKeyValue (Modulus, Exponent) >
<!ELEMENT Modulus (#PCDATA) >
<!ELEMENT Exponent (#PCDATA) >
4.4.3 The RetrievalMethod Element ✨
okay so a RetrievalMethod element inside KeyInfo is how you point at some KeyInfo info that lives somewhere else 🧚 for example, lots of signatures in one doc might all use a key that's verified by an X.509v3 certificate chain. that chain can sit once in the doc, or out in a totally different place. instead of copying the whole chain into every single signature's KeyInfo with a pile of X509Certificate elements, each one can just use one RetrievalMethod and point at it. so clean 💅
RetrievalMethod uses the same syntax and dereferencing behavior as the Reference element's URI (section 4.3.3.1) and the Reference Processing Model (section 4.3.3.2). the difference is that there are no DigestMethod or DigestValue child elements, and the URI is mandatory 🔥
Type is an optional identifier for the kind of data you're fetching 🦋 when you dereference a RetrievalMethod for any of the KeyInfo types this spec defines (section 4.4) that have a matching XML structure, what you get back is an XML element or document with that element as the root. the rawX509Certificate KeyInfo type has no XML structure, so it hands back a binary X509 certificate instead 🌸
Schema Definition:
<element name="RetrievalMethod" type="ds:RetrievalMethodType"/>
<complexType name="RetrievalMethodType">
  <sequence>
    <element ref="ds:Transforms" minOccurs="0"/>
  </sequence>
  <attribute name="URI" type="anyURI"/>
  <attribute name="Type" type="anyURI" use="optional"/>
</complexType>
DTD:
<!ELEMENT RetrievalMethod (Transforms?) >
<!ATTLIST RetrievalMethod
   URI   CDATA #REQUIRED
   Type  CDATA #IMPLIED >
4.4.4 The X509Data Element 🎀
Identifier Type="http://www.w3.org/2000/09/xmldsig#X509Data" (this can be used within a RetrievalMethod or Reference element to identify the referent's type) 💜
An X509Data element inside KeyInfo holds one or more identifiers of keys or X509 certificates. that can be a certificate's identifier, or a revocation list too 🫶 the content of X509Data works like this:
- At least one element, from the following set of element types. any of these may appear together or more than once if (if and only if) each instance describes or is related to the same certificate:
- The
X509IssuerSerialelement, which contains an X.509 issuer distinguished name/serial number pair that SHOULD be compliant with RFC 2253 [LDAP-DN], - The
X509SubjectNameelement, which contains an X.509 subject distinguished name that SHOULD be compliant with RFC 2253 [LDAP-DN], - The
X509SKIelement, which contains the base64 encoded plain (i.e., non-DER-encoded) value of a X509 V.3 SubjectKeyIdentifier extension. - The
X509Certificateelement, which contains a base64-encoded [X509v3] certificate, and - Elements from an external namespace which accompanies/complements any of the elements above.
- The
X509CRLelement, which contains a base64-encoded certificate revocation list (CRL) [X509v3].
- The
okay now the rules that really matter 👑 any X509IssuerSerial, X509SKI, and X509SubjectName elements that show up MUST refer to the certificate or certificates containing the validation key. all the ones that point at one particular certificate MUST be grouped inside a single X509Data element, and if that certificate shows up in the doc, it MUST also be in that same X509Data element 😭
any X509IssuerSerial, X509SKI, and X509SubjectName elements that relate to the same key but different certificates MUST be grouped within a single KeyInfo, but they MAY occur in multiple X509Data elements. flexible!! 🌈
every certificate in an X509Data element MUST relate to the validation key, either by containing it or by being part of a certification chain that ends at a certificate containing the validation key 🔥
there's no ordering implied by all the stuff above. the comments in the following instance show these constraints in action 🍓
<KeyInfo>
  <X509Data> <!-- two pointers to certificate-A -->
    <X509IssuerSerial>
      <X509IssuerName>CN=TAMURA Kent, OU=TRL, O=IBM,
        L=Yamato-shi, ST=Kanagawa, C=JP</X509IssuerName>
      <X509SerialNumber>12345678</X509SerialNumber>
    </X509IssuerSerial>
    <X509SKI>31d97bd7</X509SKI>
  </X509Data>
  <X509Data><!-- single pointer to certificate-B -->
    <X509SubjectName>Subject of Certificate B</X509SubjectName>
  </X509Data>
  <X509Data> <!-- certificate chain -->
    <!--Signer cert, issuer CN=arbolCA,OU=FVT,O=IBM,C=US, serial 4-->
    <X509Certificate>MIICXTCCA..</X509Certificate>
    <!-- Intermediate cert subject CN=arbolCA,OU=FVT,O=IBM,C=US
         issuer CN=tootiseCA,OU=FVT,O=Bridgepoint,C=US -->
    <X509Certificate>MIICPzCCA...</X509Certificate>
    <!-- Root cert subject CN=tootiseCA,OU=FVT,O=Bridgepoint,C=US -->
    <X509Certificate>MIICSTCCA...</X509Certificate>
  </X509Data>
</KeyInfo>
Note, there's no direct way to include a PKCS#7 encoded "bag" of certificates or CRLs 🙈 but you can put a set of certificates and CRLs inside one X509Data element, and you can have multiple X509Data elements inside a KeyInfo. also, whenever multiple certificates sit in one X509Data element, at least one of them has to contain the public key that verifies the signature 💅
now for DNames (X509IssuerSerial, X509SubjectName, and KeyName if appropriate). the strings should be encoded like this 🧚
- Treat the string as a sequence of Unicode characters.
- Escape occurrences of the following special characters by prefixing them with the
\character: a#character occurring at the beginning of the string, or any of the characters,,+,",\,<,>or; - Escape all occurrences of ASCII control characters (Unicode range
\x00 - \x 1f) by replacing them with\followed by a two digit hex number showing its Unicode number. - Escape any trailing white space by replacing
\with\20. - Since an XML document logically consists of characters, not octets, the resulting Unicode string is finally encoded according to the character encoding used for producing the physical representation of the XML document.
Schema Definition:
<element name="X509Data" type="ds:X509DataType"/>
<complexType name="X509DataType">
  <sequence maxOccurs="unbounded">
    <choice>
      <element name="X509IssuerSerial"
               type="ds:X509IssuerSerialType"/>
      <element name="X509SKI" type="base64Binary"/>
      <element name="X509SubjectName" type="string"/>
      <element name="X509Certificate" type="base64Binary"/>
      <element name="X509CRL" type="base64Binary"/>
      <any namespace="##other" processContents="lax"/>
    </choice>
  </sequence>
</complexType>
<complexType name="X509IssuerSerialType">
  <sequence>
    <element name="X509IssuerName" type="string"/>
    <element name="X509SerialNumber" type="integer"/>
  </sequence>
</complexType>
DTD:
<!ELEMENT X509Data ((X509IssuerSerial | X509SKI | X509SubjectName
                     | X509Certificate | X509CRL)+ %X509.ANY;)>
<!ELEMENT X509IssuerSerial (X509IssuerName, X509SerialNumber) >
<!ELEMENT X509IssuerName (#PCDATA) >
<!ELEMENT X509SubjectName (#PCDATA) >
<!ELEMENT X509SerialNumber (#PCDATA) >
<!ELEMENT X509SKI (#PCDATA) >
<!ELEMENT X509Certificate (#PCDATA) >
<!ELEMENT X509CRL (#PCDATA) >

<!-- Note, this DTD and schema permit X509Data to be empty; this is
precluded by the text in KeyInfo Element (section 4.4) which states
that at least one element from the dsig namespace should be present
in the PGP, SPKI, and X509 structures.  This is easily expressed for
the other key types, but not for X509Data because of its rich
structure. -->
4.4.5 The PGPData Element 🦋
Identifier Type="http://www.w3.org/2000/09/xmldsig#PGPData" (this can be used within a RetrievalMethod or Reference element to identify the referent's type) 🌸
the PGPData element inside KeyInfo carries info about PGP public key pairs and signatures on those keys. the PGPKeyID value is a base64Binary sequence holding a standard PGP public key identifier, as defined in [PGP, section 11.2]. the PGPKeyPacket holds a base64-encoded Key Material Packet, as defined in [PGP, section 5.5]. other elements from an external namespace can join these child elements as siblings inside PGPData, or you can swap out PGPData entirely for a different PGP XML structure as a child of KeyInfo ✨ PGPData has to contain one PGPKeyID and/or one PGPKeyPacket, plus 0 or more elements from an external namespace 💖
Schema Definition:
<element name="PGPData" type="ds:PGPDataType"/>
<complexType name="PGPDataType">
  <choice>
    <sequence>
      <element name="PGPKeyID" type="base64Binary"/>
      <element name="PGPKeyPacket" type="base64Binary"
               minOccurs="0"/>
      <any namespace="##other" processContents="lax" minOccurs="0"
       maxOccurs="unbounded"/>
    </sequence>
    <sequence>
      <element name="PGPKeyPacket" type="base64Binary"/>
      <any namespace="##other" processContents="lax" minOccurs="0"
       maxOccurs="unbounded"/>
    </sequence>
  </choice>
</complexType>
DTD:
<!ELEMENT PGPData ((PGPKeyID, PGPKeyPacket?) | (PGPKeyPacket)
                  %PGPData.ANY;) >
<!ELEMENT PGPKeyPacket  (#PCDATA)  >
<!ELEMENT PGPKeyID  (#PCDATA)  >
4.4.6 The SPKIData Element 🧚
Identifier Type="http://www.w3.org/2000/09/xmldsig#SPKIData" (this can be used within a RetrievalMethod or Reference element to identify the referent's type) 💜
the SPKIData element inside KeyInfo carries info about SPKI public key pairs, certificates, and other SPKI data. SPKISexp is the base64 encoding of a SPKI canonical S-expression. SPKIData needs at least one SPKISexp. other elements from an external namespace can be siblings of SPKISexp inside SPKIData, or you can swap SPKIData out completely for an alternative SPKI XML structure as a child of KeyInfo 🫶
Schema Definition:
<element name="SPKIData" type="ds:SPKIDataType"/>
<complexType name="SPKIDataType">
  <sequence maxOccurs="unbounded">
    <element name="SPKISexp" type="base64Binary"/>
    <any namespace="##other" processContents="lax" minOccurs="0"/>
  </sequence>
</complexType>
DTD:
<!ELEMENT SPKIData (SPKISexp %SPKIData.ANY;)  >
<!ELEMENT SPKISexp  (#PCDATA)  >
4.4.7 The MgmtData Element 🙈
Identifier Type="http://www.w3.org/2000/09/xmldsig#MgmtData" (this can be used within a RetrievalMethod or Reference element to identify the referent's type) 🍓
the MgmtData element inside KeyInfo is a string value used to pass along in-band key distribution or agreement data, like DH key exchange, RSA key encryption, and so on. ngl, using this element is NOT RECOMMENDED 💀 it's basically just a syntactic hook where in-band key distribution or agreement data can go. but the W3C XML Encryption Working Group is specifying way better interoperable child elements of KeyInfo for sending encrypted keys and for key agreement, so you should use those instead of MgmtData 👑
Schema Definition:
<element name="MgmtData" type="string"/>DTD:
<!ELEMENT MgmtData (#PCDATA)>4.5 The Object Element ✨
Identifier: Type="http://www.w3.org/2000/09/xmldsig#Object" (this can be used within a Reference element to identify the referent's type) 🦋
Okay so, Object is an optional element, and you can have one or more of them 💅 When it's there, it can hold any data at all. It can also carry optional MIME type, ID, and encoding attributes. Iconic flexibility 🌈
The Encoding attribute can point to a URI that identifies how the object is encoded (for example, a binary file) 🎀
The MimeType attribute is optional too. It describes the data inside the Object, separate from how that data is encoded. Its value is a string with values defined by [MIME]. For example, if the Object holds base64 encoded PNG, you could set the Encoding to 'base64' and the MimeType to 'image/png' 🍓 This attribute is purely advisory, so this specification doesn't require anyone to validate the MimeType information. 🙈 But if an application needs normative type and encoding information for signature validation, it should use Transforms that have well defined resulting types and/or encodings. Get the receipts, bestie 💜
The Object's Id is commonly referenced from a Reference in SignedInfo or Manifest 🔥 This element is typically used for enveloping signatures, where the object being signed goes inside the signature element itself. The digest is calculated over the entire Object element, including the start and end tags ✨
Note: if the application wants to exclude the <Object> tags from the digest calculation, the Reference must identify the actual data object (easy for XML documents), or a transform must be used to remove the Object tags (likely where the data object is non-XML). 💀 Excluding the object tags can be wanted when you need the signature to stay valid after the data object is moved from inside a signature to outside it (or the other way around). It can also come up when the Object's content is an encoding of an original binary document, and you want to extract and decode it so you can sign the original bitwise representation. Lowkey galaxy brain 🧚
Schema Definition:
<element name="Object" type="ds:ObjectType"/>
<complexType name="ObjectType" mixed="true">
  <sequence minOccurs="0" maxOccurs="unbounded">
    <any namespace="##any" processContents="lax"/>
  </sequence>
  <attribute name="Id" type="ID" use="optional"/>
  <attribute name="MimeType" type="string" use="optional"/>
  <attribute name="Encoding" type="anyURI" use="optional"/>
</complexType>
DTD:
<!ELEMENT Object (#PCDATA|Signature|SignatureProperties|Manifest
                  %Object.ANY;)* >
<!ATTLIST Object
 Id  ID  #IMPLIED
 MimeType    CDATA   #IMPLIED
 Encoding    CDATA   #IMPLIED >
5.0 Additional Signature Syntax 🌸
This section covers the optional-to-implement Manifest and SignatureProperties elements, plus how XML processing instructions and comments get handled. For Manifest and SignatureProperties, this section lays out the syntax but barely says how they should behave. That part is up to the application 🧚 These elements can show up anywhere the parent's content model allows. The Signature content model only lets them live inside Object 💅
5.1 The Manifest Element 🎀
Identifier: Type="http://www.w3.org/2000/09/xmldsig#Manifest" (this can be used within a Reference element to identify the referent's type)
The Manifest element is basically a list of References 📝 The difference from the list in SignedInfo is that the application decides which digests (if any) actually get checked against the referenced objects. It also decides what to do if an object can't be accessed or the digest compare fails 👑 If a Manifest is pointed to from SignedInfo, the core signature validation behavior checks the digest over the Manifest itself. The digests inside that Manifest get checked at the application's discretion 🫶 And if a Manifest is referenced from another Manifest, even the overall digest of that two-level-deep Manifest might not get checked. Chaos, but make it structured 💀
Schema Definition:
<element name="Manifest" type="ds:ManifestType"/>
<complexType name="ManifestType">
  <sequence>
    <element ref="ds:Reference" maxOccurs="unbounded"/>
  </sequence>
  <attribute name="Id" type="ID" use="optional"/>
</complexType>
DTD:
<!ELEMENT Manifest (Reference+)  >
<!ATTLIST Manifest
          Id ID  #IMPLIED >
5.2 The SignatureProperties Element 🦋
Identifier: Type="http://www.w3.org/2000/09/xmldsig#SignatureProperties" (this can be used within a Reference element to identify the referent's type)
Extra info about how the signature(s) got made can go inside a SignatureProperty element 🌈 Think date/time stamps, or the serial number of the cryptographic hardware used to generate the signature 🔐
Schema Definition:
<element name="SignatureProperties"
         type="ds:SignaturePropertiesType"/>
<complexType name="SignaturePropertiesType">
  <sequence>
    <element ref="ds:SignatureProperty" maxOccurs="unbounded"/>
  </sequence>
  <attribute name="Id" type="ID" use="optional"/>
</complexType>

<element name="SignatureProperty"
         type="ds:SignaturePropertyType"/>
<complexType name="SignaturePropertyType" mixed="true">
  <choice maxOccurs="unbounded">
    <any namespace="##other" processContents="lax"/>
    <!-- (1,1) elements from (1,unbounded) namespaces -->
  </choice>
  <attribute name="Target" type="anyURI" use="required"/>
  <attribute name="Id" type="ID" use="optional"/>
</complexType>
DTD:
<!ELEMENT SignatureProperties (SignatureProperty+)  >
<!ATTLIST SignatureProperties
          Id     ID      #IMPLIED  >

<!ELEMENT SignatureProperty (#PCDATA %SignatureProperty.ANY;)* >
<!ATTLIST SignatureProperty
          Target CDATA   #REQUIRED
          Id     ID      #IMPLIED  >
5.3 Processing Instructions in Signature Elements 🌟
No XML processing instructions (PIs) are used by this specification 🙅♀️
Heads up though: if an application puts PIs inside SignedInfo, they'll get signed, unless the CanonicalizationMethod algorithm throws them away. (This is true for any signed XML content, periodt 💅) All of the CanonicalizationMethods identified in this specification keep PIs. When a PI is part of signed content (like inside SignedInfo or in referenced XML documents), changing the PI will obviously cause a signature failure 😭
5.4 Comments in Signature Elements 💬
XML comments are not used by this specification 🤐
Same vibe here: unless CanonicalizationMethod removes comments from SignedInfo or any other referenced XML (and Canonical XML [XML-C14N] does), they'll get signed. So if comments are kept, changing one will cause a signature failure ✨ In the same way, the XML signature over any XML data will be sensitive to comment changes, unless a comment-ignoring canonicalization/transform method, such as Canonical XML [XML-C14N], is specified 🫠
6.0 Algorithms 🧮
This section names the algorithms used with the XML digital signature specification. Each entry lists the identifier you put in Signature elements, a reference to the formal specification, and, where it applies, definitions for how keys and cryptographic results are represented 🔥
6.1 Algorithm Identifiers and Implementation Requirements 💖
Algorithms get identified by URIs that show up as an attribute on the element that names the algorithm's role (DigestMethod, Transform, SignatureMethod, or CanonicalizationMethod). Every algorithm here takes parameters, but a lot of the time they're implicit. For example, a SignatureMethod is implicitly given two parameters: the keying info, and the output of CanonicalizationMethod 🧠 Explicit extra parameters for an algorithm show up as content elements inside the algorithm role element. Those parameter elements have a descriptive element name, which is often algorithm specific, and they MUST be in the XML Signature namespace or an algorithm specific namespace 👑
This specification defines a set of algorithms, their URIs, and implementation requirements. The requirements are about implementation, not about what's required for signature use 🎀 The mechanism is also extensible, so signature applications can use alternative algorithms too 🌈
Digest
   1. Required SHA1
      http://www.w3.org/2000/09/xmldsig#sha1
Encoding
   1. Required base64
      http://www.w3.org/2000/09/xmldsig#base64
MAC
   1. Required HMAC-SHA1
      http://www.w3.org/2000/09/xmldsig#hmac-sha1
Signature
   1. Required DSAwithSHA1 (DSS)
      http://www.w3.org/2000/09/xmldsig#dsa-sha1
   2. Recommended RSAwithSHA1
      http://www.w3.org/2000/09/xmldsig#rsa-sha1
Canonicalization
   1. Required Canonical XML (omits comments)
      http://www.w3.org/TR/2001/REC-xml-c14n-20010315
   2. Recommended Canonical XML with Comments
      http://www.w3.org/TR/2001/REC-xml-c14n-20010315#WithComments
Transform
   1. Optional XSLT
      http://www.w3.org/TR/1999/REC-xslt-19991116
   2. Recommended XPath
      http://www.w3.org/TR/1999/REC-xpath-19991116
   3. Required Enveloped Signature*
      http://www.w3.org/2000/09/xmldsig#enveloped-signature
Footnote for the asterisk: the Enveloped Signature transform removes the Signature element from the signature calculation when the signature sits inside the content it's signing. This MAY be done with the RECOMMENDED XPath specification from 6.6.4: Enveloped Signature Transform, but it MUST have the same effect as the XPath Transform specified there 🫶
6.2 Message Digests 🍓
Only one digest algorithm is defined here. That said, people expect one or more additional strong digest algorithms to come out of the US Advanced Encryption Standard effort 🌸 Using MD5 [MD5] is NOT RECOMMENDED, because recent advances in cryptanalysis have made people doubt its strength 💀
6.2.1 SHA-1 🔐
Identifier: http://www.w3.org/2000/09/xmldsig#sha1
The SHA-1 algorithm [SHA-1] takes no explicit parameters. Here's an example of a SHA-1 DigestAlg element:
<DigestMethod Algorithm="http://www.w3.org/2000/09/xmldsig#sha1"/>A SHA-1 digest is a 160-bit string. The content of the DigestValue element shall be the base64 encoding of this bit string, viewed as a 20-octet octet stream 🧁 For example, the message digest:
A9993E36 4706816A BA3E2571 7850C26C 9CD0D89Dfrom Appendix A of the SHA-1 standard would turn into this DigestValue element:
<DigestValue>qZk+NkcGgWq6PiVxeFDCbJzQ2J0=</DigestValue>6.3 Message Authentication Codes 🔑
MAC algorithms take two implicit parameters: their keying material, which is determined from KeyInfo, and the octet stream output by CanonicalizationMethod. MACs and signature algorithms are syntactically identical, but a MAC implies a shared secret key 🦋
6.3.1 HMAC 💖
Identifier: http://www.w3.org/2000/09/xmldsig#hmac-sha1
okay so HMAC is giving main character energy ✨. It follows RFC2104 [HMAC] and takes a truncation length in bits as a parameter. If you don't specify one, you get every single bit of the hash back 🫶. Here's an example SignatureMethod element, bestie:
<SignatureMethod
   Algorithm="http://www.w3.org/2000/09/xmldsig#hmac-sha1">
         <HMACOutputLength>128</HMACOutputLength>
      </SignatureMethod>
The output is basically the chosen digest algorithm's output, possibly chopped down. It has to be base64 encoded the same simple way the digest algorithms do it 🌸. Let's look at the HMAC-SHA1 digest from the [HMAC] test vectors:
9294727A 3638BB1C 13F48EF8 158BFC9DOnce it's base64 encoded, the SignatureValue element ends up looking like this 🦋:
<SignatureValue>kpRyejY4uxwT9I74FYv8nQ==</SignatureValue>Schema Definition:
<simpleType name="HMACOutputLengthType">
  <restriction base="integer"/>
</simpleType>
DTD:
<!ELEMENT HMACOutputLength (#PCDATA)>6.4 Signature Algorithms 🔥
Signature algorithms take two implicit parameters. One is the keying material pulled from KeyInfo, and the other is the octet stream that comes out of CanonicalizationMethod. Signature and MAC algorithms look identical syntactically, but a signature means you're using public key cryptography 🔑.
6.4.1 DSA 💅
Identifier: http://www.w3.org/2000/09/xmldsig#dsa-sha1
The DSA algorithm [DSS] takes no explicit parameters, so it's very low maintenance 🧚. Here's an example of a DSA SignatureMethod element:
<SignatureMethod
 Algorithm="http://www.w3.org/2000/09/xmldsig#dsa-sha1"/>
The DSA output is a pair of integers, usually called (r, s). The signature value is the base64 encoding of two octet streams glued together, one from r and one from s, in that order. Integer-to-octet conversion must be done according to the I2OSP operation defined in RFC 2437 [PKCS1], with the l parameter set to 20 ✨. For example, here's a DSA signature (r, s) with the values written in hexadecimal:
r = 8BAC1AB6 6410435C B7181F95 B16AB97C 92B341C0
s = 41E2345F 1F56DF24 58F426D1 55B4BA2D B6DCD8C8
Those values come from Appendix 5 of the DSS standard, and the SignatureValue element would look like this 🎀:
<SignatureValue>
 i6watmQQQ1y3GB+VsWq5fJKzQcBB4jRfH1bfJFj0JtFVtLotttzYyA==
</SignatureValue>
6.4.2 PKCS1 (RSA-SHA1) 🌈
Identifier: http://www.w3.org/2000/09/xmldsig#rsa-sha1
When this document says "RSA algorithm", it means the RSASSA-PKCS1-v1_5 algorithm described in RFC 2437 [PKCS1]. The RSA algorithm takes no explicit parameters either 💜. Here's an example of an RSA SignatureMethod element:
<SignatureMethod
 Algorithm="http://www.w3.org/2000/09/xmldsig#rsa-sha1"/>
The SignatureValue content for an RSA signature is the base64 [MIME] encoding of the octet string computed the way RFC 2437 [PKCS1, section 8.1.1: Signature generation for the RSASSA-PKCS1-v1_5 signature scheme] describes. Now the important part 👀. As specified in the EMSA-PKCS1-V1_5-ENCODE function in RFC 2437 [PKCS1, section 9.2.1], the value fed into the signature function MUST contain a pre-pended algorithm object identifier for the hash function. However, a signature verifier doesn't need an ASN.1 parser or OID recognition 🙈. The PKCS#1 v1.5 representation looks like this:
CRYPT (PAD (ASN.1 (OID, DIGEST (data))))The padded ASN.1 has this form:
01 | FF* | 00 | prefix | hashHere "|" means concatenation, and "01", "FF", and "00" are fixed octets with those hexadecimal values. "hash" is the SHA1 digest of the data. "prefix" is the ASN.1 BER SHA1 algorithm designator prefix that PKCS1 [RFC 2437] requires, which is:
hex 30 21 30 09 06 05 2B 0E 03 02 1A 05 00 04 14This prefix is there to make it easier to use standard cryptographic libraries 🧁. The FF octet MUST be repeated the maximum number of times so that the thing being CRYPTed is exactly one octet shorter than the RSA modulus.
The resulting base64 [MIME] string becomes the child text node of the SignatureValue element, like so:
<SignatureValue>
 IWijxQjUrcXBYoCei4QxjWo9Kg8D3p9tlWoT4t0/gyTE96639
 In0FZFY2/rvP+/bMJ01EArmKZsR5VW3rwoPxw=
</SignatureValue>
6.5 Canonicalization Algorithms 🫧
If you canonicalize over octets, the canonicalization algorithms take two implicit parameters: the content and its charset. The charset comes from the rules of the transport protocols and media types. For example, RFC2376 [XML-MT] defines the media types for XML 📄. This info is necessary to sign and verify documents correctly, and it often needs careful server side configuration, so be nice to your sysadmin 😭.
A bunch of canonicalization algorithms need to convert to [UTF-8]. The two algorithms below understand at least [UTF-8] and [UTF-16] as input encodings. We RECOMMEND that externally specified algorithms do the same. Knowing other encodings is OPTIONAL 🌍.
Lots of canonicalization algorithms also transcode from a non-Unicode encoding to Unicode. The two algorithms below do text normalization while they transcode [NFC, NFC-Corrigendum]. We RECOMMEND that externally specified canonicalization algorithms do this too. (Heads up, converting existing charsets to Unicode can get ambiguous. For an example, check out the XML Japanese Profile [XML-Japanese] Note 🎌.)
6.5.1 Canonical XML 🌸
Identifier for REQUIRED Canonical XML (omits comments): http://www.w3.org/TR/2001/REC-xml-c14n-20010315
Identifier for Canonical XML with Comments: http://www.w3.org/TR/2001/REC-xml-c14n-20010315#WithComments
Here's an example XML canonicalization element:
<CanonicalizationMethod
 Algorithm="http://www.w3.org/TR/2001/REC-xml-c14n-20010315"/>
The normative spec for Canonical XML is [XML-C14N]. The algorithm can take either an octet stream or an XPath node-set (or a sufficiently functional alternative) as input, and it spits out an octet stream. It's also easily parameterized with an extra URI so you can omit or keep comments 💬.
6.6 Transform Algorithms 🦋
A Transform algorithm has one implicit parameter: an octet stream from the Reference or the output of an earlier Transform.
Application developers are strongly encouraged to support all the transforms in this section as RECOMMENDED, unless their application environment has resource constraints that make that impractical 🥹. Following this recommendation maximizes application interoperability, and libraries should be around to add support for these transforms without tons of development work 💖.
6.6.1 Canonicalization ✨
Any canonicalization algorithm that can be used for CanonicalizationMethod (like the ones in Canonicalization Algorithms (section 6.5)) can also be used as a Transform 🔁.
6.6.2 Base64 🍓
Identifiers: http://www.w3.org/2000/09/xmldsig#base64
The normative spec for base64 decoding transforms is [MIME]. The base64 Transform element has no content, and the algorithms do the decoding on the input. This transform is handy when an application needs to sign the raw data behind the encoded content of an element 🧾.
This transform needs an octet stream as input. If you give it an XPath node-set (or a sufficiently functional alternative) instead, it gets converted to an octet stream by doing things that are logically equivalent to 1) applying an XPath transform with the expression self::text(), and then 2) taking the string-value of the node-set. So if an XML element is identified by a barename XPointer in the Reference URI, and its content is only base64 encoded character data, this transform automatically strips off the start and end tags of that element and any of its descendant elements, plus any descendant comments and processing instructions. The output of this transform is an octet stream 🌟.
6.6.3 XPath Filtering ✨
Identifier: http://www.w3.org/TR/1999/REC-xpath-19991116
okay so the normative spec for XPath expression evaluation is [XPath] 🦋. The XPath expression you want to run goes in the character content of a transform parameter child element named XPath. 💖
The input this transform needs is an XPath node-set. ngl, there's a catch: if your actual input is an XPath node-set that came from a null URI or barename XPointer dereference, comment nodes have already been omitted 🙈. If your actual input is an octet stream, the application MUST convert the octet stream to an XPath node-set suitable for Canonical XML with Comments. (A later application of the REQUIRED Canonical XML algorithm would strip those comments away again 💅.) So the input node-set should match what you'd get from this process:
- Initialize an XPath evaluation context by setting the initial node equal to the input XML document's root node, and set the context position and size to 1.
- Evaluate the XPath expression
(//. | //@* | //namespace::*)
Evaluating that expression includes all of the document's nodes (comments included) in the node-set that represents the octet stream. 🌸
The transform output is also an XPath node-set. The XPath expression in the XPath parameter gets evaluated once for each node in the input node-set. The result is converted to a boolean. If the boolean is true, the node is included in the output node-set. If the boolean is false, the node is left out of the output node-set. ✨
Note: Even if the input node-set has had comments removed, the comment nodes still exist in the underlying parse tree and can separate text nodes. For example, the markup<e>Hello, <!-- comment -->world!</e>contains two text nodes. Therefore, the expressionself::text()[string()="Hello, world!"]would fail. Should this problem arise in the application, it can be solved by either canonicalizing the document before the XPath transform to physically remove the comments or by matching the node based on the parent element's string value (e.g., by using the expressionself::text()[string(parent::e)="Hello, world!"]). 🧚
The main purpose of this transform is to make sure that only specifically defined changes to the input XML document are allowed after the signature is affixed 🔥. It does this by leaving out exactly those nodes that are allowed to change once the signature is affixed, and including all the other input nodes in the output. It is the responsibility of the XPath expression author to include all nodes whose change could affect the interpretation of the transform output in the application context. 👑
An important scenario is a document that requires two enveloped signatures. Each signature has to leave itself out of its own digest calculations, but it's also necessary to exclude the second signature element from the digest calculations of the first signature, so that adding the second signature doesn't break the first signature. 😭
The XPath transform sets up the following evaluation context for each node of the input node-set:
- A context node equal to a node of the input node-set.
- A context position, initialized to 1.
- A context size, initialized to 1.
- A library of functions equal to the function set defined in [XPath] plus a function named here.
- A set of variable bindings. No means for initializing these is defined. Thus, the set of variable bindings used when evaluating the XPath expression is empty, and use of a variable reference in the XPath expression results in an error.
- The set of namespace declarations in scope for the XPath expression.
Because of the context node setting, the XPath expressions in this transform will look a lot like the ones used in [XSLT], except the size and position are always 1 to reflect the fact that the transform is automatically visiting every node (in XSLT, you'd recursively call the command apply-templates to visit the nodes of the input tree). 🦋
The function here() is defined as follows:
Function: node-set here()
The here function returns a node-set containing the attribute or processing instruction node, or the parent element of the text node, that directly bears the XPath expression. This expression results in an error if the containing XPath expression does not appear in the same XML document against which the XPath expression is being evaluated. 💅
Here's an example of creating an enveloped signature (a Signature element that is a descendant of an element being signed). Even though the signed content shouldn't change after signing, the elements inside the Signature element are changing (e.g., the digest value must be put inside the DigestValue and the SignatureValue must be calculated afterwards). One way to stop those changes from invalidating the digest value in DigestValue is to add an XPath Transform that leaves out all Signature elements and their descendants. For example:
<Document>
...
<Signature xmlns="http://www.w3.org/2000/09/xmldsig#">
  <SignedInfo>
   ...
    <Reference URI="">
      <Transforms>
        <Transform
Algorithm="http://www.w3.org/TR/1999/REC-xpath-19991116">
          <XPath xmlns:dsig="&dsig;">
          not(ancestor-or-self::dsig:Signature)
          </XPath>
        </Transform>
      </Transforms>
      <DigestMethod
Algorithm="http://www.w3.org/2000/09/xmldsig#sha1"/>
      <DigestValue></DigestValue>
    </Reference>
  </SignedInfo>
  <SignatureValue></SignatureValue>
 </Signature>
 ...
</Document>
Because the Reference URI in this example is null, the XPath transform input node-set contains all nodes in the entire parse tree starting at the root node (except the comment nodes). For each node in this node-set, the node is included in the output node-set unless the node, or one of its ancestors, has a tag of Signature that is in the namespace given by the replacement text for the entity &dsig;. 🎀
A more elegant solution uses the here function to leave out only the Signature containing the XPath Transform, which lets enveloped signatures sign other signatures. In the example above, use the XPath element:
<XPath xmlns:dsig="&dsig;">
count(ancestor-or-self::dsig:Signature |
here()/ancestor::dsig:Signature[1]) >
count(ancestor-or-self::dsig:Signature)</XPath>
Since the XPath equality operator converts node sets to string values before comparing them, we have to use the XPath union operator (|) instead. For each node of the document, the predicate expression is true if and only if the node-set containing the node and its Signature element ancestors does not include the enveloped Signature element that contains the XPath expression (the union doesn't produce a larger set if the enveloped Signature element is in the node-set given by ancestor-or-self::Signature). 🧠💜
6.6.4 Enveloped Signature Transform 🦋
Identifier: http://www.w3.org/2000/09/xmldsig#enveloped-signature
An enveloped signature transform T removes the whole Signature element containing T from the digest calculation of the Reference element containing T. The entire string of characters an XML processor uses to match the Signature with the XML production element is removed. The output of the transform is equivalent to what you'd get by replacing T with an XPath transform containing the following XPath parameter element:
<XPath xmlns:dsig="&dsig;">
count(ancestor-or-self::dsig:Signature |
here()/ancestor::dsig:Signature[1]) >
count(ancestor-or-self::dsig:Signature)</XPath>
The input and output requirements of this transform are identical to those of the XPath transform, but it may only be applied to a node-set from its parent XML document. Note that you don't need an XPath expression evaluator to create this transform 🌈. However, this transform MUST produce output in exactly the same manner as the XPath transform parameterized by the XPath expression above. 💀
6.6.5 XSLT Transform 👑
Identifier: http://www.w3.org/TR/1999/REC-xslt-19991116
The normative spec for XSL Transformations is [XSLT] 🌸. Specifying a namespace-qualified stylesheet element, which MUST be the sole child of the Transform element, tells you that the specified style sheet should be used. Whether this sets up inline processing of local XSLT declarations within the resource depends on the XSLT processing model. The ordered application of multiple stylesheets may require multiple Transforms. No special provision is made for identifying a remote stylesheet at a given URI, because it can be communicated via an xsl:include or xsl:import within the stylesheet child of the Transform. 🦋
This transform requires an octet stream as input. If the actual input is an XPath node-set, the signature application should try to convert it to octets (apply Canonical XML]) as described in the Reference Processing Model (section 4.3.3.2). ✨
The output of this transform is an octet stream. The processing rules for the XSL style sheet or transform element are stated in the XSLT specification [XSLT]. We RECOMMEND that XSLT transform authors use an output method of xml for XML and HTML. Since XSLT implementations don't produce consistent serializations of their output, we further RECOMMEND inserting a transform after the XSLT transform to canonicalize the output 💖. These steps help make sure the resulting signatures interoperate among applications that support the XSLT transform. Note that if the output is actually HTML, the result of these steps is logically equivalent [XHTML]. 🫶
7. XML Canonicalization and Syntax Constraint Considerations ✨
okay bestie, digital signatures are super picky 😭 the verification math has to run on exactly the same bits that got signed. if the surface look of the signed data can change between signing and verifying, you need a way to standardize that changeable part first. like, even plain ASCII text has at least three line ending styles floating around 🙈 if signed text can switch from one line ending style to another between signing and verifying, the line endings need to be canonicalized to a standard form before signing and verification, or the signatures literally break 💀
XML is giving "surface representation changes" and also throws away some surface info when it gets processed 💅 so XML digital signatures have a spot for naming the canonicalization methods right in the signature. that way the verifier can use the same canonicalization as the signer. iconic behavior 👑
we're gonna separate the canonicalization of a Signature element from other signed XML data objects 🦋 an isolated XML document can be treated as plain binary data so nothing can change. then the digest won't change and you don't need to canonicalize it if you sign and verify it that way. BUT XML that gets read and processed with standard XML parsing is super likely to get changed so some of its surface info is lost or modified 😩 this happens a lot to the Signature and the enclosed SignedInfo elements, since they (and maybe the whole XML document around them) get processed as XML.
same deal for Manifest, Object, and SignatureProperties elements if they've been digested, their DigestValue is getting checked, and they're being processed as XML 🌸
the kinds of XML changes that might need canonicalizing come in four categories 🧚 first, the basic [XML] stuff, covered in 7.1 below. second, [DOM], [SAX], or similar processing, covered in 7.2 below. third, coded character set conversion, like going between UTF-8 and UTF-16 (both of which every [XML] compliant processor is required to support), which is in the paragraph right below this one. and fourth, changes related to namespace declarations and the XML namespace attribute context, covered in 7.3 below 🎀
any canonicalization algorithm should give output in one specific fixed coded character set. every canonicalization algorithm in this document uses UTF-8 (without a byte order mark (BOM)) and does not do character normalization 🍓 we RECOMMEND that signature applications create XML content (Signature elements and their descendants/content) in Normalization Form C [NFC, NFC-Corrigendum], and check that any XML they consume is in that form too. (if it's not, signatures may fail to validate 😬) also, none of these algorithms do data type normalization. apps that normalize data types in different formats (like (true, false) or (1,0)) might not be able to validate each other's signatures 🙈
7.1 XML 1.0, Syntax Constraints, and Canonicalization
okay so XML 1.0 [XML] sets up an interface where a conformant app reading XML gets certain info from that XML and NOT other info 👀 specifically:
- line endings get normalized to the single character #xA. you drop any #xD that's immediately followed by a #xA, and replace every other #xD with #xA 💖
- missing attributes that are declared to have default values get handed to the app as if they were present with the default value 🌈
- character references get replaced with the matching character ✨
- entity references get replaced with the matching declared entity 🦋
- attribute values get normalized by:
- 5.1 replacing character and entity references like above,
- 5.2 replacing occurrences of #x9, #xA, and #xD with #x20 (space), except that the sequence #xD#xA becomes a single space, and
- 5.3 if the attribute is not declared to be CDATA, stripping all leading and trailing spaces and replacing all interior runs of spaces with a single space 💅
rn, items (2), (4), and (5.3) depend on the presence of a schema, DTD, or similar declarations 😭 the Signature element type is laxly schema valid [XML-schema], which means external XML, or even XML in the same document as the signature, might be (only) well-formed or come from another namespace (where the signature schema permits it). then those items might not be present at all. so a signature with that kind of content will only be verifiable by other signature apps if the following syntax constraints are followed when generating any signed material, including the SignedInfo element 🫶
- attributes having default values MUST be explicitly present,
- all entity references (except "amp", "lt", "gt", "apos", "quot", and other character entities not representable in the encoding chosen) MUST be expanded,
- attribute value white space MUST be normalized
7.2 DOM/SAX Processing and Canonicalization
so on top of the canonicalization and syntax constraints we just went over, lots of XML apps use the Document Object Model [DOM] or the Simple API for XML [SAX] 🧚 DOM maps XML into a tree of nodes and usually assumes you'll use it on a whole document with later processing done on that tree. SAX turns XML into a series of events, like a start tag, content, and so on. either way, a lot of surface stuff like the ordering of attributes and insignificant white space inside start/end tags just gets lost 😩 also, namespace declarations get mapped over the nodes they apply to, which loses the namespace prefixes from the source text and, in most cases, loses where the namespace declarations originally showed up in the instance.
if an XML Signature is going to be produced or verified on a system using DOM or SAX processing, you need a canonical method to serialize the relevant part of a DOM tree or sequence of SAX events 🎀 XML canonicalization specs, like [XML-C14N], are only based on info that DOM and SAX actually preserve. for an XML Signature to be verifiable by an implementation using DOM or SAX, you not only have to follow the XML 1.0 syntax constraints from the previous section, you also MUST specify an appropriate XML canonicalization so the verifier can re-serialize the DOM/SAX input into the same octet stream that was signed 💖
7.3 Namespace Context and Portable Signatures
okay this part is so relatable 🥹 in [XPath] and therefore the Canonical XML data model, an element has namespace nodes that match the declarations inside that element and its ancestors:
"Note: An element E has namespace nodes that represent its namespace declarations as well as any namespace declarations made by its ancestors that have not been overridden in E's declarations, the default namespace if it is non-empty, and the declaration of the prefix xml." [XML-C14N]
so when you serialize a Signature element, or signed XML data that's the child of other elements in these data models, that Signature element and its children might carry namespace declarations from the ancestor context 🌸 also, the Canonical XML and Canonical XML with Comments algorithms pull all xml namespace attributes (like xml:lang) from the nearest ancestor where they're declared up to the apex node of the canonicalized XML, unless they're already declared on that node 😤 this can totally undercut the signer's goal of making a signature in one context that stays valid in another. for example, say a signature is a child of B and a grandchild of A:
<A xmlns:n1="&foo;">
  <B xmlns:n2="&bar;">
    <Signature xmlns="&dsig;">   ...
      <Reference URI="#signme"/> ...
    </Signature>
    <C ID="signme" xmlns="&baz;"/>
  </B>
</A>
now, when either element B or the signed element C gets moved into a [SOAP] envelope for transport:
      <SOAP:Envelope
   xmlns:SOAP="http://schemas.xmlsoap.org/soap/envelope/">
    ...
    <SOAP:Body>
      <B xmlns:n2="&bar;">
        <Signature xmlns="&dsig;">
          ...
        </Signature>
        <C ID="signme" xmlns="&baz;"/>
      </B>
    </SOAP:Body>
  </SOAP:Envelope>
the canonical form of the signature in this context will pick up new namespace declarations from the SOAP:Envelope context, and that invalidates the signature 💀 also, the canonical form will be missing namespace declarations it might have had from element A's context, which also invalidates it. to avoid these problems, the application may:
- rely on the enveloping application to properly divorce its body (the signature payload) from the context (the envelope) before the signature is validated. or,
- use a canonicalization method that "repels/excludes" ancestor context instead of "attracts" it. [XML-C14N] purposefully attracts such context.
8.0 Security Considerations ⚠️
ngl this section is serious business 🔥 the XML Signature spec gives you a very flexible digital signature mechanism. implementors MUST give consideration to their application threat models and to the following factors.
8.1 Transforms
okay so one requirement of this spec is letting signatures "apply to a part or totality of a XML document." (See [XML-Signature-RD, section 3.1.3].) the Transforms mechanism meets that by letting you sign data derived from processing the content of the identified resource 🦋 for instance, an app that wants to sign a form but still let users enter limited field data without breaking a previous signature on the form might use [XPath] to exclude the portions the user needs to change. transforms can be specified pretty freely and can include encoding transforms, canonicalization instructions, or even XSLT transformations 🧚 three cautions about this feature come up in the following sections.
Note, core validation behavior does NOT confirm that the signed data was obtained by applying each step of the indicated transforms. (Though it does check that the digest of the resulting content matches the one specified in the signature.) for example, some apps might be fine verifying an XML signature over a cached copy of already transformed data. other apps might require that content be freshly dereferenced and transformed. 🙈💀
8.1.1 Only What is Signed is Secure ✨
First, obviously, signatures over a transformed document do not secure any information discarded by transforms. Only what is signed is secure 🔒
Okay, so the use of Canonical XML [XML-C14N] makes sure that all internal entities and XML namespaces get expanded within the content being signed 🫶 Every entity gets swapped for its definition, and the canonical form spells out the namespace an element would otherwise just inherit. Applications that do not canonicalize XML content (especially the SignedInfo element) SHOULD NOT use internal entities, and they SHOULD represent the namespace explicitly within the content being signed, since they can't rely on canonicalization to do it for them 💅 Also, if you care about the integrity of the element type definitions tied to the XML instance being signed, you may wish to sign those definitions too (the schema, DTD, or natural language description associated with the namespace/identifier) 🌸
Second, an envelope containing signed information is not secured by the signature 😭 For instance, when an encrypted envelope contains a signature, the signature does not protect the authenticity or integrity of unsigned envelope headers, nor its ciphertext form. It only secures the plaintext that was actually signed. Not me going "wait, the outside is unprotected?!" 💀
8.1.2 Only What is 'Seen' Should be Signed 👀
Additionally, the signature secures any information introduced by the transform. Only what is "seen" (that which is represented to the user via visual, auditory or other media) should be signed 🦋 If signing is supposed to convey a user's judgment or consent (an automated mechanism or person), then it is normally necessary to secure as exactly as practical the information that was presented to that user 🎀
Note that you can do this by literally signing what was presented, like the screen images shown to a user. However, this may give you data that is hard for later software to manipulate 🙈 So instead, you can sign the data along with whatever filters, style sheets, client profile or other information that affects how it gets presented ✨
8.1.3 'See' What is Signed 🔍
Just like a user should only sign what they "sees," persons and automated mechanisms that trust the validity of a transformed document based on a valid signature should operate over the data that was transformed (including canonicalization) and signed, not the original pre-transformed data 💜 This applies to transforms specified within the signature as well as those included as part of the document itself. For instance, if an XML document includes an embedded style sheet [XSLT], it is the transformed document that should be represented to the user and signed. To meet this, where a document references an external style sheet, the content of that external resource should also be signed via a signature Reference. Otherwise, the content of that external content might change, which alters the resulting document without invalidating the signature 😱
Some applications might operate over the original or intermediary data, but they should be extremely careful about potential weaknesses introduced between the original and transformed data 🧐 This is a trust decision about the character and meaning of the transforms, and an application needs to make it with caution. Consider a canonicalization algorithm that normalizes character case (lower to upper) or character composition ('e and accent' to 'accented-e'). An adversary could introduce changes that are normalized, and therefore inconsequential to signature validity, but still material to a DOM processor. For instance, by changing the case of a character, one might influence the result of an XPath selection. A serious risk shows up if that change is normalized for signature validation, but the processor operates over the original data and returns a different result than intended 🚨
As a result:
- All documents operated upon and generated by signature applications MUST be in [NFC, NFC-Corrigendum] (otherwise intermediate processors might unintentionally break the signature) 💖
- Encoding normalizations SHOULD NOT be done as part of a signature transform. Or, to say it another way, if normalization does occur, the application SHOULD always "see" (operate over) the normalized form 🫶
8.2 Check the Security Model 🛡️
This specification uses public key signatures and keyed hash authentication codes. These have substantially different security models 🌈 Furthermore, it permits user specified algorithms, which may have other models.
With public key signatures, any number of parties can hold the public key and verify signatures, while only the parties with the private key can create signatures 👑 The number of holders of the private key should be minimized, and preferably be one. Confidence by verifiers in the public key they are using, and in its binding to the entity or capabilities represented by the corresponding private key, is an important issue. It's usually addressed by certificate or online authority systems 🎀
Keyed hash authentication codes, based on secret keys, are typically much more efficient in terms of the computational effort required. But they have the characteristic that all verifiers need to have possession of the same key as the signer. So any verifier can forge signatures 💀
This specification permits user provided signature algorithms and keying information designators. Such user provided algorithms may have different security models. For example, methods involving biometrics usually depend on a physical characteristic of the authorized user that cannot be changed the way public or secret keys can be, and they may have other security model differences 🧚
8.3 Algorithms, Key Lengths, Certificates, Etc. 🔐
The strength of a particular signature depends on all links in the security chain 🔗 That includes the signature and digest algorithms used, the strength of the key generation [RANDOM] and the size of the key, the security of key and certificate authentication and distribution mechanisms, certificate chain validation policy, protection of cryptographic processing from hostile observation and tampering, etc.
Care must be exercised by applications when executing the various algorithms that may be specified in an XML signature, and when processing any "executable content" that might be provided to such algorithms as parameters, such as XSLT transforms ⚠️ The algorithms specified in this document will usually be implemented via a trusted library, but even there, perverse parameters might cause unacceptable processing or memory demand. Even more care may be warranted with application defined algorithms 😤
The security of an overall system will also depend on the security and integrity of its operating procedures, its personnel, and on the administrative enforcement of those procedures 🏢 All the factors listed in this section are important to the overall security of a system. However, most are beyond the scope of this specification ✨
9. Schema, DTD, Data Model, and Valid Examples 🍓
XML Signature Schema Instance 📜
http://www.w3.org/Signature/Drafts/xmldsig-core/xmldsig-core-schema.xsdValid XML schema instance based on the 20001024 Schema/DTD [XML-Schema].
XML Signature DTD 📄
http://www.w3.org/Signature/Drafts/xmldsig-core/xmldsig-core-schema.dtdRDF Data Model 🗺️
http://www.w3.org/Signature/Drafts/xmldsig-core/xmldsig-datamodel-20000112.gif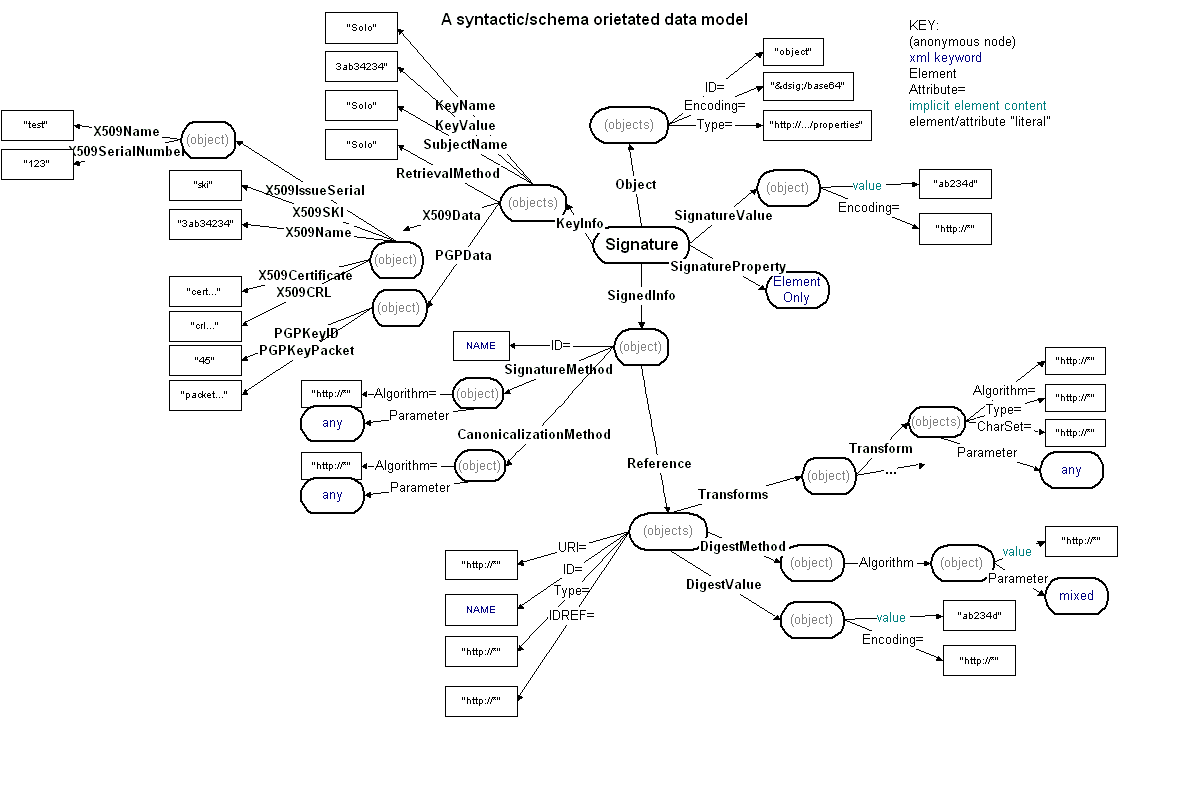
XML Signature Object Example 🌟
http://www.w3.org/Signature/Drafts/xmldsig-core/signature-example.xmlA cryptographically fabricated XML example that includes foreign content and validates under the schema. It also uses schemaLocation to aid automated schema fetching and validation 🎀
RSA XML Signature Example 💜
http://www.w3.org/Signature/Drafts/xmldsig-core/signature-example-rsa.xmlAn XML Signature example with generated cryptographic values by Merlin Hughes and validated by Gregor Karlinger 🫶
DSA XML Signature Example 🦋
http://www.w3.org/Signature/Drafts/xmldsig-core/signature-example-dsa.xmlSimilar to above, but uses DSA 💅
10. Definitions 💅
okay bestie, time for the glossary, and it's giving very precise vocab 📖 these terms are the foundation for everything else, so read carefully 🫶
Authentication Code (Protected Checksum) 🔐 This is a value made by running a shared key over a message with a cryptographic algorithm. It gives you message authentication and integrity, but NOT signer authentication. Another way to say it is "a checksum that is computed for a data object by means that protect against active attacks that would attempt to change the checksum to make it match changes made to the data object." [SEC]
Authentication, Message ✨ This is the property that, given an authentication code or protected checksum, lets you still catch tampering. Even if someone changes both the data and the checksum so it looks intact, the change gets detected. As the ABA's Digital Signature Guidelines put it: "A signature should identify what is signed, making it impracticable to falsify or alter either the signed matter or the signature without detection." [Digital Signature Guidelines, ABA]
Authentication, Signer 🪪 This is the property that the signer really is who they claim to be. The ABA's Digital Signature Guidelines say: "A signature should indicate who signed a document, message or record, and should be difficult for another person to produce without authorization." [Digital Signature Guidelines, ABA] Heads up: whether the signing key actually matches a specific identity is an application decision. This spec supports that, but it doesn't handle it itself 🙈
Checksum 🧮 "A value that (a) is computed by a function that is dependent on the contents of a data object and (b) is stored or transmitted together with the object, for the purpose of detecting changes in the data." [SEC]
Core 🎀 This means the syntax and processing this specification defines, including core validation. We use the word to separate it from other markup, processing, and application semantics that aren't ours.
Data Object (Content/Document) 📦 This is the actual binary or octet data that an application transforms, digests, or signs. Often it's an HTTP entity [HTTP]. Note that the proper noun Object means one specific XML element, so don't mix them up 😭 Sometimes we just say document or resource's content. Element content is the stuff between XML start and end tags [XML], and an XML document is data that follows the XML specification [XML].
Integrity 🛡️ "The property that data has not been changed, destroyed, or lost in an unauthorized or accidental manner." [SEC] A simple checksum can protect against accidental changes to data. Message authentication is similar, but it also guards against an active attacker who changes the data and also changes the checksum to match 👀
Object 🧺 This is an XML Signature element where arbitrary, non-core data can go. An Object element is just one kind of digital data (or document) that a Reference can sign.
Resource 🌐 "A resource can be anything that has identity. Familiar examples include an electronic document, an image, a service (e.g., 'today's weather report for Los Angeles'), and a collection of other resources.... The resource is the conceptual mapping to an entity or set of entities, not necessarily the entity which corresponds to that mapping at any particular instance in time. Thus, a resource can remain constant even when its content---the entities to which it currently corresponds---changes over time, provided that the conceptual mapping is not changed in the process." [URI] Also, so the word "entity" doesn't collide between the URI and XML specs, we use data object, content, or document for the actual bits and octets being worked on 🫠
Signature ✍️ Formally, this is a value made by running a private key over a message with a cryptographic algorithm, so that it has integrity, message authentication, and/or signer authentication. We sometimes use "signature" loosely to include authentication code values too, but we're careful to flag the difference whenever signer authentication matters. A signature can be described (not exclusively) as detached, enveloping, or enveloped.
Signature, Application 💻 This is an application that implements the MANDATORY (REQUIRED/MUST) parts of this specification. These conformance requirements cover application behavior, the structure of the Signature element type and its children (including SignatureValue), and the specified algorithms.
Signature, Detached ✂️ The signature covers content that lives outside the Signature element, and that content can be identified by a URI or a transform. That's why it's "detached" from what it signs. This usually means separate data objects, but it also covers the case where the Signature and the data object are in the same XML document as sibling elements.
Signature, Enveloping 🎁 The signature covers content found inside an Object element of the signature itself. The Object (or its content) is identified through a Reference, using a URI fragment identifier or a transform.
Signature, Enveloped 🧣 The signature covers the XML content that contains the signature as an element. That content provides the root XML document element. Obviously, enveloped signatures have to be careful not to include their own value when calculating the SignatureValue 🤯
Transform 🔄 This is the processing of data from its source into its derived form. Typical transforms include XML Canonicalization, XPath, and XSLT.
Validation, Core ✅ These are the core processing requirements of this specification that call for signature validation and SignedInfo reference validation.
Validation, Reference 🔍 The hash value of the identified and transformed content, as specified by Reference, matches its specified DigestValue.
Validation, Signature 🖊️ The SignatureValue matches the result of processing SignedInfo with CanonicalizationMethod and SignatureMethod, as specified in Core Validation (section 3.2).
Validation, Trust/Application 👑 The application decides that the semantics tied to a signature are valid. For example, an application might validate timestamps or the integrity of the signer key. That behavior sits outside this core specification, though 💖
Appendix: Changes from RFC 3075 🌸
Plenty of small editorial tweaks went in here. On top of those, these substantive changes were made based on interoperation experience and other considerations 🧩
- Minor but incompatible changes in the representation of DSA keys. In particular, the optionality of several fields was changed and two fields were re-ordered. 🔑
- Minor change in the X509Data KeyInfo structure to allow multiple CRLs to be grouped with certificates and other X509 information. Previously CRLs had to occur singly and each in a separate X509Data structure. 📜
- Incompatible change in the type of PGPKeyID, which had previously been string, to the more correct base64Binary since it is actually a binary quantity. 🧠
- Several warnings have been added. Of particular note, because it reflects a problem actually encountered in use and is the only warning added that has its own little section, is the warning of canonicalization problems when the namespace context of signed material changes. ⚠️✨
References ✨
okay bestie, this is the bibliography, and it's literally a whole squad of standards and papers that the spec leans on 📚🫶
- [ABA] Digital Signature Guidelines.
http://www.abanet.org/scitech/ec/isc/dsgfree.html - [DOM] Document Object Model (DOM) Level 1 Specification. W3C Recommendation. V. Apparao, S. Byrne, M. Champion, S. Isaacs, I. Jacobs, A. Le Hors, G. Nicol, J. Robie, R. Sutor, C. Wilson, L. Wood. October 1998.
http://www.w3.org/TR/1998/REC-DOM-Level-1-19981001/ - [DSS] FIPS PUB 186-2 . Digital Signature Standard (DSS). U.S. Department of Commerce/National Institute of Standards and Technology.
http://csrc.nist.gov/publications/fips/fips186-2/fips186-2.pdf - [HMAC] Krawczyk, H., Bellare, M. and R. Canetti, "HMAC: Keyed-Hashing for Message Authentication", RFC 2104, February 1997.
- [HTTP] Fielding, R. Gettys, J., Mogul, J., Frystyk, H., Masinter, L., Leach, P. and T. Berners-Lee, "Hypertext Transfer Protocol -- HTTP/1.1", RFC 2616, June 1999.
- [KEYWORDS] Bradner, S., "Key words for use in RFCs to Indicate Requirement Levels", BCP 14, RFC 2119, March 1997.
- [LDAP-DN] Wahl, M., Kille, S. and T. Howes, "Lightweight Directory Access Protocol (v3): UTF-8 String Representation of Distinguished Names", RFC 2253, December 1997.
- [MD5] Rivest, R., "The MD5 Message-Digest Algorithm", RFC 1321, April 1992.
- [MIME] Freed, N. and N. Borenstein, "Multipurpose Internet Mail Extensions (MIME) Part One: Format of Internet Message Bodies", RFC 2045, November 1996.
- [NFC] TR15, Unicode Normalization Forms. M. Davis, M. Drst. Revision 18: November 1999.
http://www.unicode.org/unicode/reports/tr15/tr15-18.html. NFC-Corrigendum Normalization Corrigendum. The Unicode Consortium.http://www.unicode.org/unicode/uni2errata/Normalization_Corrigendum.html. - [PGP] Callas, J., Donnerhacke, L., Finney, H. and R. Thayer, "OpenPGP Message Format", RFC 2440, November 1998.
- [RANDOM] Eastlake, 3rd, D., Crocker, S. and J. Schiller, "Randomness Recommendations for Security", RFC 1750, December 1994.
- [RDF] Resource Description Framework (RDF) Schema Specification 1.0. W3C Candidate Recommendation. D. Brickley, R.V. Guha. March 2000.
http://www.w3.org/TR/2000/CR-rdf-schema-20000327/Resource Description Framework (RDF) Model and Syntax Specification. W3C Recommendation. O. Lassila, R. Swick. February 1999.http://www.w3.org/TR/1999/REC-rdf-syntax-19990222/ - [1363] IEEE 1363: Standard Specifications for Public Key Cryptography. August 2000.
- [PKCS1] Kaliski, B. and J. Staddon, "PKCS #1: RSA Cryptography Specifications Version 2.0", RFC 2437, October 1998.
- [SAX] SAX: The Simple API for XML. D. Megginson, et al. May 1998.
http://www.megginson.com/SAX/index.html(THIS PAGE OUT OF DATE; GO TO www.saxproject.org) - [SEC] Shirey, R., "Internet Security Glossary", FYI 36, RFC 2828, May 2000.
- [SHA-1] FIPS PUB 180-1. Secure Hash Standard. U.S. Department of Commerce/National Institute of Standards and Technology.
http://csrc.nist.gov/publications/fips/fips180-1/fip180-1.txt - [SOAP] Simple Object Access Protocol (SOAP) Version 1.1. W3C Note. D. Box, D. Ehnebuske, G. Kakivaya, A. Layman, N. Mendelsohn, H. Frystyk Nielsen, S. Thatte, D. Winer. May 2001.
http://www.w3.org/TR/2000/NOTE-SOAP-20000508/ - [Unicode] The Unicode Consortium. The Unicode Standard.
http://www.unicode.org/unicode/standard/standard.html - [UTF-16] Hoffman, P. and F. Yergeau, "UTF-16, an encoding of ISO 10646", RFC 2781, February 2000.
- [UTF-8] Yergeau, R., "UTF-8, a transformation format of ISO 10646", RFC 2279, January 1998.
- [URI] Berners-Lee, T., Fielding, R. and L. Masinter, "Uniform Resource Identifiers (URI): Generic Syntax", RFC 2396, August 1998.
- [URI-Literal] Hinden, R., Carpenter, B. and L. Masinter, "Format for Literal IPv6 Addresses in URL's", RFC 2732, December 1999.
- [URL] Berners-Lee, T., Masinter, L. and M. McCahill, "Uniform Resource Locators (URL)", RFC 1738, December 1994.
- [URN] Moats, R., "URN Syntax", RFC 2141, May 1997.
- [X509v3] ITU-T Recommendation X.509 version 3 (1997). "Information Technology - Open Systems Interconnection - The Directory Authentication Framework" ISO/IEC 9594-8:1997.
- [XHTML 1.0] XHTML(tm) 1.0: The Extensible Hypertext Markup Language. W3C Recommendation. S. Pemberton, D. Raggett, et al. January 2000.
http://www.w3.org/TR/2000/REC-xhtml1-20000126/ - [XLink] XML Linking Language. W3C Recommendation. S. DeRose, E. Maler, D. Orchard. June 2001.
http://www.w3.org/TR/2000/REC-xlink-20010627/ - [XML] Extensible Markup Language (XML) 1.0 (Second Edition). W3C Recommendation. T. Bray, E. Maler, J. Paoli, C. M. Sperberg-McQueen. October 2000.
http://www.w3.org/TR/2000/REC-xml-20001006 - [XML-C14N] Boyer, J., "Canonical XML Version 1.0", RFC 3076, March 2001.
- [XML-Japanese] XML Japanese Profile. W3C Note. M. Murata April 2000
http://www.w3.org/TR/2000/NOTE-japanese-xml-20000414/ - [XML-MT] Whitehead, E. and M. Murata, "XML Media Types", RFC 2376, July 1998.
- [XML-ns] Namespaces in XML. W3C Recommendation. T. Bray, D. Hollander, A. Layman. January 1999.
http://www.w3.org/TR/1999/REC-xml-names-19990114 - [XML-schema] XML Schema Part 1: Structures. W3C Recommendation. D. Beech, M. Maloney, N. Mendelsohn, H. Thompson. May 2001.
http://www.w3.org/TR/2001/REC-xmlschema-1-20010502/XML Schema Part 2: Datatypes W3C Recommendation. P. Biron, A. Malhotra. May 2001.http://www.w3.org/TR/2001/REC-xmlschema-2-20010502/ - [XML-Signature-RD] Reagle, J., "XML Signature Requirements", RFC 2807, July 2000.
- [XPath] XML Path Language (XPath) Version 1.0. W3C Recommendation. J. Clark, S. DeRose. October 1999.
http://www.w3.org/TR/1999/REC-xpath-19991116 - [XPointer] XML Pointer Language (XPointer). W3C Working Draft. S. DeRose, R. Daniel, E. Maler. January 2001.
http://www.w3.org/TR/2001/WD-xptr-20010108 - [XSL] Extensible Stylesheet Language (XSL). W3C Proposed Recommendation. S. Adler, A. Berglund, J. Caruso, S. Deach, P. Grosso, E. Gutentag, A. Milowski, S. Parnell, J. Richman, S. Zilles. August 2001.
http://www.w3.org/TR/2001/PR-xsl-20010828/ - [XSLT] XSL Transforms (XSLT) Version 1.0. W3C Recommendation. J. Clark. November 1999.
http://www.w3.org/TR/1999/REC-xslt-19991116.html
Authors' Addresses 🎀
meet the authors, the people who literally wrote this and are reachable 💌
Donald E. Eastlake 3rd
Motorola, 20 Forbes Boulevard
Mansfield, MA 02048 USA

Phone: 1-508-851-8280
EMail: Donald.Eastlake@motorola.com


Joseph M. Reagle Jr., W3C
Massachusetts Institute of Technology
Laboratory for Computer Science
NE43-350, 545 Technology Square
Cambridge, MA 02139

Phone: +1.617.258.7621
EMail: reagle@w3.org


David Solo
Citigroup
909 Third Ave, 16th Floor
NY, NY 10043 USA

Phone +1-212-559-2900
EMail: dsolo@alum.mit.edu
Full Copyright Statement 📜
Copyright (c) 2002 The Internet Society & W3C (MIT, INRIA, Keio), All Rights Reserved.
This document and translations of it may be copied and furnished to others, and derivative works that comment on or otherwise explain it or assist in its implementation may be prepared, copied, published and distributed, in whole or in part, without restriction of any kind, provided that the above copyright notice and this paragraph are included on all such copies and derivative works. However, this document itself may not be modified in any way, such as by removing the copyright notice or references to the Internet Society or other Internet organizations, except as needed for the purpose of developing Internet standards in which case the procedures for copyrights defined in the Internet Standards process must be followed, or as required to translate it into languages other than English.
The limited permissions granted above are perpetual and will not be revoked by the Internet Society or its successors or assigns.
This document and the information contained herein is provided on an "AS IS" basis and THE INTERNET SOCIETY AND THE INTERNET ENGINEERING TASK FORCE DISCLAIMS ALL WARRANTIES, EXPRESS OR IMPLIED, INCLUDING BUT NOT LIMITED TO ANY WARRANTY THAT THE USE OF THE INFORMATION HEREIN WILL NOT INFRINGE ANY RIGHTS OR ANY IMPLIED WARRANTIES OF MERCHANTABILITY OR FITNESS FOR A PARTICULAR PURPOSE.
Acknowledgement 🫶
Funding for the RFC Editor function is currently provided by the Internet Society. 💖
📦 where this page comes from
- ietf: rfc3275 2002-03
- 💖 girlified by claude-haiku-5-5 on : a language model's rewrite of the original, under its terms