LLM(1)
💖 LLM(1) 💖 — the llm manual, bestie edition ✨
✨ NAME ✨
llm — LLM documentation 👑
okay so first thing, the vibes: here's the badge wall, every single one, no skips 🎀
- [image: GitHub repo] →
https://github.com/simonw/llm - [image: PyPI] →
https://pypi.org/project/llm/ - [image: Changelog] →
https://llm.datasette.io/en/stable/changelog.html - [image: Tests] →
https://github.com/simonw/llm/actions?query=workflow%3ATest - [image: License] →
https://github.com/simonw/llm/blob/main/LICENSE - [image: Discord] →
https://datasette.io/discord-llm - [image: Homebrew] →
https://formulae.brew.sh/formula/llm
A CLI tool and Python library for interacting with OpenAI, Anthropic's Claude, Google's Gemini, Qwen, Gemma, Kimi, DeepSeek, Mistral, and dozens of other Large Language Models, both via remote APIs and with models that can be installed and run on your own machine. it's giving "have it your way" fr fr 💅
Watch Language models on the command-line at https://www.youtube.com/watch?v=QUXQNi6jQ30 on YouTube for a demo, or read the accompanying detailed notes at https://simonwillison.net/2024/Jun/17/cli-language-models/ 🦋
With LLM you can:
- Run prompts from the command-line <#usage-executing-prompts> ✨
- Store prompts and responses in SQLite <#logging> 🗄️
- Generate and store embeddings <#embeddings> 🧚
- Extract structured content from text and images <#schemas> 📸
- Grant models the ability to execute tools <#tools> 🔧
- ... and much, much more 👑
🌸 QUICK START 🌸
First, install LLM using pip or Homebrew or pipx or uv:
pip install llmOr with Homebrew (see warning note <#homebrew-warning> 💀):
brew install llmOr with pipx at https://pypa.github.io/pipx/:
pipx install llmOr with uv at https://docs.astral.sh/uv/guides/tools/
uv tool install llmUse LLM to run prompts or start chats against an arbitrary OpenAI-compatible Chat Completions endpoint, such as LM Studio at https://lmstudio.ai. With uvx, you can do this without installing LLM first:
uvx llm openai endpoint http://localhost:1234/v1 \
  -m google/gemma-4-12b \
  "What is the capital of France?"

uvx llm openai endpoint http://localhost:1234/v1 \
  -m google/gemma-4-12b \
  --chat
Add --key your-api-key if the endpoint requires authentication. See Run against an endpoint without configuring it <#openai-endpoint> for more options.
If you have an OpenAI API key (grab one at https://platform.openai.com/api-keys) you can run this:
# Paste your OpenAI API key into this
llm keys set openai

# Run a prompt (with the default gpt-5.6-luna model)
llm "Ten fun names for a pet pelican"

# Extract text from an image
llm "extract text" -a scanned-document.jpg

# Use a system prompt against a file
cat myfile.py | llm -s "Explain this code"
Run prompts against Gemini at https://aistudio.google.com/apikey or Anthropic at https://console.anthropic.com/ with their respective plugins:
llm install llm-gemini
llm keys set gemini
# Paste Gemini API key here
llm -m gemini-3.5-flash 'Tell me fun facts about Mountain View'

llm install llm-anthropic
llm keys set anthropic
# Paste Anthropic API key here
llm -m claude-sonnet-5 'Impress me with wild facts about turnips'
You can also install a plugin <#installing-plugins> to access models that can run on your local device. If you use Ollama at https://ollama.com/:
# Install the plugin
llm install llm-ollama

# Download and run a prompt against the Orca Mini 7B model
ollama pull llama3.2:latest
llm -m llama3.2:latest 'What is the capital of France?'
To start an interactive chat <#usage-chat> with a model, use llm chat:
llm chat -m gpt-4.1

Chatting with gpt-4.1
Type 'exit' or 'quit' to exit
Type '!multi' to enter multiple lines, then '!end' to finish
Type '!edit' to open your default editor and modify the prompt.
Type '!fragment <my_fragment> [<another_fragment> ...]' to insert one or more fragments
> Tell me a joke about a pelican
Why don't pelicans like to tip waiters?

Because they always have a big bill!
🗞️ PROJECT NEWS 🗞️
- 29th April 2026: LLM 0.32a0 is a major backwards-compatible refactor →
https://simonwillison.net/2026/Apr/29/llm/ - 11th August 2025: LLM 0.27, the annotated release notes: GPT-5 and improved tool calling →
https://simonwillison.net/2025/Aug/11/llm-027/ - 27th May 2025: Large Language Models can run tools in your terminal with LLM 0.26 →
https://simonwillison.net/2025/May/27/llm-tools/ - 5th May 2025: Feed a video to a vision LLM as a sequence of JPEG frames on the CLI (also LLM 0.25) →
https://simonwillison.net/2025/May/5/llm-video-frames/ - 7th April 2025: Long context support in LLM 0.24 using fragments and template plugins →
https://simonwillison.net/2025/Apr/7/long-context-llm/ - 28th February 2025: Structured data extraction from unstructured content using LLM schemas →
https://simonwillison.net/2025/Feb/28/llm-schemas/ - 17th February 2025: LLM 0.22, the annotated release notes →
https://simonwillison.net/2025/Feb/17/llm/ - 29th October 2024: You can now run prompts against images, audio and video in your terminal using LLM →
https://simonwillison.net/2024/Oct/29/llm-multi-modal/ - 26th January 2024: LLM 0.13: The annotated release notes →
https://simonwillison.net/2024/Jan/26/llm/ - 12th September 2023: Build an image search engine with llm-clip, chat with models with llm chat →
https://simonwillison.net/2023/Sep/12/llm-clip-and-chat/ - 4th September 2023: LLM now provides tools for working with embeddings →
https://simonwillison.net/2023/Sep/4/llm-embeddings/ - 12th July 2023: The LLM CLI tool now supports self-hosted language models via plugins →
https://simonwillison.net/2023/Jul/12/llm/ - 18th May 2023: llm, ttok and strip-tags—CLI tools for working with ChatGPT and other LLMs →
https://simonwillison.net/2023/May/18/cli-tools-for-llms/ - 4th April 2023: The original announcement of the llm CLI tool →
https://simonwillison.net/2023/Apr/4/llm/
For everything else, see the llm tag at https://simonwillison.net/tags/llm/ on the blog 💜
📚 CONTENTS 📚
🎀 Setup
✨ Installation
Install this tool using pip:
pip install llmOr using pipx at https://pypa.github.io/pipx/:
pipx install llmOr using uv at https://docs.astral.sh/uv/guides/tools/ (more tips below):
uv tool install llmOr using Homebrew at https://brew.sh/ (see warning note 💀):
brew install llm🦋 Upgrading to the latest version
If you installed using pip:
pip install -U llmFor pipx:
pipx upgrade llmFor uv:
uv tool upgrade llmFor Homebrew:
brew upgrade llmIf the latest version is not yet available on Homebrew you can upgrade like this instead:
llm install -U llm💫 Using uvx
If you have uv installed (https://docs.astral.sh/uv/) you can also use the uvx command to try LLM without first installing it, like this:
export OPENAI_API_KEY='sx-...'
uvx llm 'fun facts about skunks'
This will install and run LLM using a temporary virtual environment.
You can use the --with option to add extra plugins. To use Anthropic's models, for example:
export ANTHROPIC_API_KEY='...'
uvx --with llm-anthropic llm -m claude-3.5-haiku 'fun facts about skunks'
All of the usual LLM commands will work with uvx llm. Here's how to set your OpenAI key without needing an environment variable, for example:
uvx llm keys set openai
# Paste key here
🍓 A note about Homebrew and PyTorch
The version of LLM packaged for Homebrew currently uses Python 3.12. The PyTorch project do not yet have a stable release of PyTorch for that version of Python. 😭
This means that LLM plugins that depend on PyTorch — such as llm-sentence-transformers at https://github.com/simonw/llm-sentence-transformers — may not install cleanly with the Homebrew version of LLM.
You can workaround this by manually installing PyTorch before installing llm-sentence-transformers:
llm install llm-python
llm python -m pip install \
  --pre torch torchvision \
  --index-url https://download.pytorch.org/whl/nightly/cpu
llm install llm-sentence-transformers
This should produce a working installation of that plugin. ✨
🔌 Installing plugins
Plugins <#plugins> can be used to add support for other language models, including models that can run on your own device.
For example, the llm-gpt4all plugin at https://github.com/simonw/llm-gpt4all adds support for 17 new models that can be installed on your own machine. You can install that like so:
llm install llm-gpt4all🔑 API key management
Many LLM models require an API key. These API keys can be provided to this tool using several different mechanisms.
You can obtain an API key for OpenAI's language models from the API keys page at https://platform.openai.com/api-keys on their site.
💾 Saving and using stored keys
The easiest way to store an API key is to use the llm keys set command:
llm keys set openaiYou will be prompted to enter the key like this:
% llm keys set openai
Enter key:
Once stored, this key will be automatically used for subsequent calls to the API:
llm "Five ludicrous names for a pet lobster"You can list the names of keys that have been set using this command:
llm keysKeys that are stored in this way live in a file called keys.json. This file is located at the path shown when you run the following command:
llm keys pathOn macOS this will be ~/Library/Application Support/io.datasette.llm/keys.json. On Linux it may be something like ~/.config/io.datasette.llm/keys.json.
🎯 Passing keys using the --key option
Keys can be passed directly using the --key option, like this:
llm "Five names for pet weasels" --key sk-my-key-goes-hereYou can also pass the alias of a key stored in the keys.json file. For example, if you want to maintain a personal API key you could add that like this:
llm keys set personalAnd then use it for prompts like so:
llm "Five friendly names for a pet skunk" --key personal🌈 Keys in environment variables
Keys can also be set using an environment variable. These are different for different models.
For OpenAI models the key will be read from the OPENAI_API_KEY environment variable.
The environment variable will be used if no --key option is passed to the command and there is not a key configured in keys.json
To use an environment variable in place of the keys.json key run the prompt like this:
llm 'my prompt' --key $OPENAI_API_KEY🌸 Configuration 🌸
Okay bestie, so here's the thing — you can configure LLM in a number of different ways. Pick your fighter. 💅
✨ Setting a custom default model ✨
When you call llm without the -m/--model option, it defaults to gpt-5.6-luna — which is a fast and less expensive OpenAI model. Lowkey the budget queen. 👑
Want a different default? Use the llm models default command. For GPT-4o (slower and more expensive, but more capable, so it's giving ✨main character✨) run this:
llm models default gpt-4oWanna see what your current default even is? Run this:
llm models defaultAnd bestie — any of the supported aliases for a model can be passed to this command. No gatekeeping here. 🫶
🎀 Setting a custom directory location 🎀
This tool stores various files — prompt templates, stored keys, preferences, a database of logs — in a directory on your computer. It's a whole little home for your stuff. 🏠
- On macOS this is
~/Library/Application Support/io.datasette.llm/. - On Linux it may be something like
~/.config/io.datasette.llm/.
You can set a custom location for this directory by setting the LLM_USER_PATH environment variable:
export LLM_USER_PATH=/path/to/my/custom/directory🦋 Turning SQLite logging on and off 🦋
By default, LLM will log every single prompt and response you make to a SQLite database — see Logging to SQLite for more details. Yes, it's keeping receipts. 😭
You can turn this behavior off by default by running:
llm logs offOr turn it back on again with:
llm logs onRun llm logs status to see the current states of the setting. Vibe check your logging, bestie. ✨
👑 Usage 👑
The command to run a prompt is llm prompt 'your prompt'. But here's the tea — this is the default command, so you can just use llm 'your prompt' as a shortcut. Periodt.
💖 Executing a prompt 💖
These examples use the default OpenAI gpt-5.6-luna model, which requires you to first set an OpenAI API key. Don't skip that step bestie, it will not work. 🙈
You can install LLM plugins to use models from other providers too — including openly licensed models you can run directly on your own computer. So many options fr fr. 🌈
To run a prompt, streaming tokens as they come in:
llm 'Ten names for cheesecakes'To disable streaming and only return the response once it has completed:
llm 'Ten names for cheesecakes' --no-streamTo switch from the default model to GPT-5.6 Sol:
llm 'Ten names for cheesecakes' -m gpt-5.6-solPass --model <model name> to use a different model. Run llm models to see a list of available models. 👀
Or — and this is the icon behavior — if you know the name is too long to type, use -q once or more to provide search terms. The model with the shortest model ID that matches all of those terms (as a lowercase substring) will be used:
llm 'Ten names for cheesecakes' -q gpt -q solTo change the default model for the current session, set the LLM_MODEL environment variable:
export LLM_MODEL=gpt-4.1
llm 'Ten names for cheesecakes' # Uses gpt-4.1
You can send a prompt directly to standard input like this:
echo 'Ten names for cheesecakes' | llmAnd if you send text to standard input and provide arguments, the resulting prompt will consist of the piped content followed by the arguments:
cat myscript.py | llm 'explain this code'Will run a prompt of:
<contents of myscript.py> explain this codeFor models that support them, system prompts are a better tool for this kind of prompting. Just saying. 💅
🧚 Model options 🧚
Some models support options. You can pass these using -o/--option name value — for example, to set the temperature to 1.5 run this:
llm 'Ten names for cheesecakes' -o temperature 1.5Use the llm models --options command to see which options are supported by each model, or llm -m gpt-5.5 --options to show the options for a specific selected model. Slay, now you know. ✨
You can also configure default options for a model using the llm models options commands.
🌸 Attachments 🌸
Some models are multi-modal, which means they can accept input in more than just text. GPT-4o and GPT-4o mini can accept images, and models such as Google's gemini-flash-latest can accept audio and video as well. It's giving versatility. 💅
LLM calls these attachments. You can pass attachments using the -a option like this:
llm "describe this image" -a https://static.simonwillison.net/static/2024/pelicans.jpg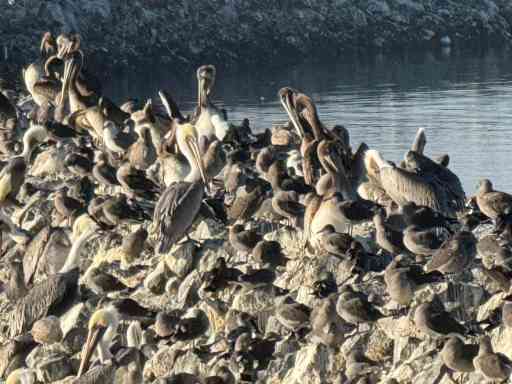
Attachments can be passed using URLs or file paths, and you can attach more than one attachment to a single prompt:
llm "extract text" -a image1.jpg -a image2.jpgYou can also pipe an attachment to LLM by using - as the filename:
cat image.jpg | llm "describe this image" -a -LLM will attempt to automatically detect the content type of the image. If this doesn't work you can instead use the --attachment-type option (--at for short) which takes the URL/path plus an explicit content type:
cat myfile | llm "describe this image" --at - image/jpeg💜 System prompts 💜
You can use -s/--system '...' to set a system prompt.
llm 'SQL to calculate total sales by month' \
  --system 'You are an exaggerated sentient cheesecake that knows SQL and talks about cheesecake a lot'
Honestly? Iconic prompt. This is useful for piping content to standard input, for example:
curl -s 'https://simonwillison.net/2023/May/15/per-interpreter-gils/' | \
  llm -s 'Suggest topics for this post as a JSON array'
Or to generate a description of changes made to a Git repository since the last commit:
git diff | llm -s 'Describe these changes'Different models support system prompts in different ways.
The OpenAI models are particularly good at using system prompts as instructions for how they should process additional input sent as part of the regular prompt.
Other models might use system prompts change the default voice and attitude of the model.
System prompts can be saved as templates to create reusable tools. For example, you can create a template called pytest like this:
llm -s 'write pytest tests for this code' --save pytestAnd then use the new template like this:
cat llm/utils.py | llm -t pytestSee prompt templates for more. Go off bestie. 🎀
🔥 Tools 🔥
Many models support the ability to call external tools. Tools can be provided by plugins or you can pass a --functions CODE option to LLM to define one or more Python functions that the model can then call.
llm --functions '
def multiply(x: int, y: int) -> int:
    """Multiply two numbers."""
    return x * y
' 'what is 34234 * 213345'
Add --td/--tools-debug to see full details of the tools that are being executed. You can also set the LLM_TOOLS_DEBUG environment variable to 1 to enable this for all prompts.
llm --functions '
def multiply(x: int, y: int) -> int:
    """Multiply two numbers."""
    return x * y
' 'what is 34234 * 213345' --td
Output:
Tool call: multiply({'x': 34234, 'y': 213345})
  7303652730
34234 multiplied by 213345 is 7,303,652,730.
Or add --ta/--tools-approve to approve each tool call interactively before it is executed:
llm --functions '
def multiply(x: int, y: int) -> int:
    """Multiply two numbers."""
    return x * y
' 'what is 34234 * 213345' --ta
Output:
Tool call: multiply({'x': 34234, 'y': 213345})
Approve tool call? [y/N]:
The --functions option can be passed more than once, and can also point to the filename of a .py file containing one or more functions.
If you have any tools that have been made available via plugins you can add them to the prompt using --tool/-T option. For example, using llm-tools-simpleeval like this:
llm install llm-tools-simpleeval
llm --tool simple_eval "4444 * 233423" --td
Run this command to see a list of available tools from plugins:
llm toolsServer-side tools are model-specific. Pass -m/--model to include the tools supported by a particular model:
llm tools -m gpt-5.6-lunaThese are displayed in a separate Server-side tools section with their constructor signatures and documentation. Add --json to return them in a server_side_tools array whose entries have "server_side": true.
If you run a prompt that uses tools from plugins or model-specific server-side tools, continuing that conversation using llm -c will reuse the tools from the first prompt. Configured constructor arguments such as CodeInterpreter(memory_limit="4g") are retained. Running llm chat -c will start a chat that continues using those same tools. For example:
llm -T simple_eval "12345 * 12345" --td
Tool call: simple_eval({'expression': '12345 * 12345'})
  152399025
12345 multiplied by 12345 equals 152,399,025.
llm -c "that * 6" --td
Tool call: simple_eval({'expression': '152399025 * 6'})
  914394150
152,399,025 multiplied by 6 equals 914,394,150.
llm chat -c --td
Chatting with gpt-4.1-mini
Type 'exit' or 'quit' to exit
Type '!multi' to enter multiple lines, then '!end' to finish
Type '!edit' to open your default editor and modify the prompt
> / 123
Tool call: simple_eval({'expression': '914394150 / 123'})
  7434098.780487805
914,394,150 divided by 123 is approximately 7,434,098.78.
Some tools are bundled in a configurable collection of tools called a toolbox. This means a single --tool option can load multiple related tools. Obsessed. ✨
llm-tools-datasette is one example. Using a toolbox looks like this:
llm install llm-tools-datasette
llm -T 'Datasette("https://datasette.io/content")' "Show tables" --td
Toolboxes always start with a capital letter. They can be configured by passing a tool specification, which should fit the following patterns:
- Empty:
ToolboxNameorToolboxName()— has no configuration arguments - JSON object:
ToolboxName({"key": "value", "other": 42}) - Single JSON value:
ToolboxName("hello")orToolboxName([1,2,3]) - Key-value pairs:
ToolboxName(name="test", count=5, items=[1,2])— treated the same as{"name": "test", "count": 5, "items": [1, 2]}, all values must be valid JSON
The llm tools command lists toolboxes along with the tools they provide. Some toolboxes cannot know their list of tools until they have been configured — llm-mcp-client for example fetches its tools from whichever MCP server it is pointed at. These dynamic toolboxes are listed with their constructor signature and documentation instead:
MCP(server, mode='auto', prefix='') (plugin: mcp_client)

  Expose the tools from an MCP server as LLM tools.

  Usage:

      MCP("https://example.com/mcp")
      MCP("https://example.com/mcp", mode="legacy", prefix="demo_")
Pass a full toolbox specification to llm tools to see the tools provided by a configured instance:
llm tools 'MCP("https://datasette.simonwillison.net/-/mcp")'okay so if you're rolling with an MCP toolbox that looks like this:
MCP("https://datasette.simonwillison.net/-/mcp"):then it comes pre-loaded with these three little guys:
list_databases(**kwargs)— lists out every database hanging around in this Datasette instance.get_database_schema(**kwargs)— hands you the whole complete SQL schema for a database.execute_sql(**kwargs)— runs exactly one read-only SQL statement and gives you back the tabular results.
Now here's the slay part: continuing a convo with llm -c or llm chat -c rebuilds all your toolboxes from the configuration that got recorded in the logs. So bestie, you do not have to type out -T all over again. 🙌
⚠️ But listen — each instance gets rebuilt fresh. Which means any in-memory state your toolbox built up during the earlier prompt does not carry over. It's giving amnesia. It's giving new phone who dis. 😭
Toolboxes + llm chat? chef's kiss. Try chatting with the Datasette content database like this:
llm chat -T 'Datasette("https://datasette.io/content")' --tdand you'll get something like:
Chatting with gpt-4.1-mini
Type 'exit' or 'quit' to exit
...
> show tables
🌸 Extracting fenced code blocks 🌸
If you're using an LLM to generate code, sometimes you literally just want the code and none of the yapping around it. Same, honestly.
The -x/--extract option scans the response for the first instance of a Markdown fenced code block — something that looks exactly like this:
def my_function(): # ...
It extracts and returns just the content of that block, excluding the fenced code delimiters. And if there are no fenced code blocks at all? It just returns the full response. No drama. 🫶
Wanna grab the last one instead of the first? Use --xl/--extract-last. Done and dusted. ✨
💡 Heads up: the entire response — explanatory text and all — is still logged to the database. Peep it any time with llm logs -c.
✨ JSON output ✨
Add --json and you get back a JSON array describing the prompt and the response, in the exact same format as llm logs --json <#logging-view>:
llm 'Five names for a pet pelican' --json[
{
"id": "01jm8ec74wxsdatyn5pq1fp0s5",
"model": "gpt-5.6-luna",
"resolved_model": null,
"prompt": "Five names for a pet pelican",
"system": null,
"prompt_json": null,
"options_json": {},
"response": "1. Captain Beaky\n...",
"reasoning": null,
"response_json": null,
"conversation_id": "01jm8ec74taftdgj2t4zra9z0j",
"duration_ms": 1560,
"datetime_utc": "2025-02-16T22:34:30.374882+00:00",
"input_tokens": 8,
"output_tokens": 62,
"token_details": null,
"conversation_name": "Five names for a pet pelican",
"conversation_model": "gpt-5.6-luna",
"schema_json": null,
"prompt_fragments": [],
"system_fragments": [],
"tools": [],
"tool_calls": [],
"tool_results": [],
"attachments": []
}
]Real talk: that array will hold more than one object if your prompt triggered tool calls, because every single round-trip with the model gets logged as its own separate response. Each one gets a lil moment. 💅
And bestie, this works even if logging is turned off or you use -n/--no-log — in that case the JSON just gets assembled without writing anything to your logs database. Sneaky. Iconic. 🎀
🦋 Schemas 🦋
Some models can return JSON that matches a JSON schema you hand them <https://json-schema.org/>. Models from OpenAI, Anthropic and Google Gemini all have this capability. Look at them go. 👑
For the full detailed guide, go check the schemas documentation <#schemas>. iykyk.
You can pass JSON schemas straight into the --schema option:
llm --schema '{
  "type": "object",
  "properties": {
    "dogs": {
      "type": "array",
      "items": {
        "type": "object",
        "properties": {
          "name": {
            "type": "string"
          },
          "bio": {
            "type": "string"
          }
        }
      }
    }
  }
}' -m gpt-5.6-sol 'invent two dogs'
Or you can use LLM's custom concise schema syntax <#schemas-dsl> like this:
llm --schema 'name,bio' 'invent a dog'Wanna use that same concise schema for multiple items? That's what --schema-multi is for:
llm --schema-multi 'name,bio' 'invent two dogs'You can also save the JSON schema to a file and reference the filename using --schema:
llm --schema dogs.schema.json 'invent two dogs'Or save your schema to a template <#prompt-templates> like this:
llm --schema dogs.schema.json --save dogs
# Then to use it:
llm -t dogs 'invent two dogs'
⚠️ Be warned, bestie: different models may support different dialects of the JSON schema specification. Don't assume they all speak the same language. 🙈
See Browsing logged JSON objects created using schemas <#schemas-logs> for tips on using the llm logs --schema X command to access JSON objects you've previously logged using this option. Your past self left you little gifts. 🎁
💜 Fragments 💜
The -f/--fragment option lets you reference fragments of context you want loaded into your prompt. Fragments can be specified as URLs, file paths, or as aliases to previously saved fragments. Versatile queen.
Fragments are designed for running longer prompts. Here's the tea: LLM stores prompts in a database <#logging>, and the same prompt repeated a million times ends up stored as a million copies, which wastes disk space. Rude. A fragment gets stored just once and referenced by all the prompts that use it. Frugal. Efficient. Slay. ✨
The -f option can accept a path to a file on disk, a URL, or the hash or alias of a previous fragment.
For example, to ask a question about the robots.txt file on llm.datasette.io:
llm -f https://llm.datasette.io/robots.txt 'explain this'Or for a poem inspired by some Python code on disk:
llm -f cli.py 'a short snappy poem inspired by this code'You can use as many -f options as you like — the fragments get concatenated together in the order you provided them, with any additional prompt tacked on at the end.
Fragments can also be used for the system prompt using the --sf/--system-fragment option. Say you have a file called explain_code.txt containing this:
Explain this code in detail. Include copies of the code quoted in the explanation.You can run it as the system prompt like this:
llm -f cli.py --sf explain_code.txtYou can use the llm fragments set command to load a fragment and give it an alias for future queries:
llm fragments set cli cli.py
# Then
llm -f cli 'explain this code'
Use llm fragments to list all the fragments that have been stored:
llm fragmentsYou can search by passing one or more -q X search strings. This returns results matching all of those strings, searching across the source, hash, aliases and content:
llm fragments -q pytest -q asyncioThe llm fragments remove command removes an alias. It does not delete the fragment record itself, because those are linked to previous prompts and responses and literally cannot be deleted independently of them. The lore is permanent. 💀
llm fragments remove cli🌈 Continuing a conversation 🌈
By default, the tool starts a brand new conversation every single time you run it. Fresh start energy. 🦋
But you can opt to continue the previous conversation by passing the -c/--continue option:
llm 'More names' -cThis re-sends the prompts and responses from the previous conversation as part of the call to the language model. And listen — this can add up quickly in terms of tokens, especially if you're using expensive models. Your wallet is watching. 👀
--continue will automatically use the same model as the conversation you're continuing, even if you omit the -m/--model option. It remembers so you don't have to. 🫶
To continue a conversation that is not the most recent one, use the --cid/--conversation <id> option:
llm 'More names' --cid 01h53zma5txeby33t1kbe3xk8qYou can find these conversation IDs using the llm logs command. Go digging, bestie. 🔍
⭐ Tips for using LLM with Bash or Zsh ⭐
Wanna learn more about your computer's operating system based on the output of uname -a? Run this:
llm "Tell me about my operating system: $(uname -a)"This pattern of using $(command) inside a double quoted string is a super useful way to quickly assemble prompts. Command substitution said let me cook. 🔥
🎀 Completion prompts 🎀
Some models are completion models — rather than being tuned to respond to chat style prompts, they're designed to complete a sentence or a paragraph. Different breed. Different vibe.
An example of this is the gpt-3.5-turbo-instruct OpenAI model.
You can prompt that model the same way as the chat models, but be aware that the prompt format that works best is likely to differ:
llm -m gpt-3.5-turbo-instruct 'Reasons to tame a wild beaver:'👑 Starting an interactive chat 👑
The llm chat command starts an ongoing interactive chat with a model. It's giving main character energy, honestly.
This is particularly useful for models that run on your own machine, since it saves them from having to be loaded into memory each time a new prompt gets added to a conversation. No more re-loading. No more waiting. 😌
Run llm chat, optionally with a -m model_id, to start a chat conversation:
llm chat -m chatgptEach chat starts a new conversation. A record of each conversation can be accessed through the logs <#logging-conversation>. Everything's documented, nothing's lost. ✨
You can pass -c to start a conversation as a continuation of your most recent prompt. This will automatically use the most recently used model:
llm chat -cFor models that support them, you can pass options using -o/--option:
llm chat -m gpt-4.1 -o temperature 0.5You can pass a system prompt to be used for your chat conversation:
llm chat -m gpt-5.6-luna -s 'You are a sentient cheesecake'You can also pass a template <#prompt-templates> — super useful for creating chat personas that you wish to return to. Your little roster of characters. 💅
Here's how to create a template for your GPT-5.6 Luna powered cheesecake:
llm --system 'You are a sentient cheesecake' -m gpt-5.6-luna --save cheesecakeNow you can start a new chat with your cheesecake any time you like using this:
llm chat -t cheesecakeChatting with gpt-5.6-luna
Type 'exit' or 'quit' to exit
Type '!multi' to enter multiple lines, then '!end' to finish
Type '!edit' to open your default editor and modify the prompt
Type '!fragment <my_fragment> [<another_fragment> ...]' to insert one or more fragments
> who are you?
I am a sentient cheesecake, meaning I am an artificial
intelligence embodied in a dessert form, specifically a
cheesecake. However, I don't consume or prepare foods
like humans do, I communicate, learn and help answer
your queries.Type quit or exit followed by <enter> to end a chat session. 🫡
Sometimes you may want to paste multiple lines of text into a chat at once — for example when debugging an error message. Been there, bestie. 😭
To do that, type !multi to start a multi-line input. Type or paste your text, then type !end and hit <enter> to finish.
If your pasted text might itself contain a !end line, you can set a custom delimiter using !multi abc followed by !end abc at the end:
Okay so real talk, the multi-line thing is chef's kiss when you're pasting a whole ahh traceback. Here's the vibe — you open with !multi custom-end, dump everything in, then close it with !end custom-end:
Chatting with gpt-5.6-luna
Type 'exit' or 'quit' to exit
Type '!multi' to enter multiple lines, then '!end' to finish
Type '!edit' to open your default editor and modify the prompt.
Type '!fragment <my_fragment> [<another_fragment> ...]' to insert one or more fragments
> !multi custom-end
 Explain this error:

   File "/opt/homebrew/Caskroom/miniconda/base/lib/python3.10/urllib/request.py", line 1391, in https_open
    return self.do_open(http.client.HTTPSConnection, req,
  File "/opt/homebrew/Caskroom/miniconda/base/lib/python3.10/urllib/request.py", line 1351, in do_open
    raise URLError(err)
urllib.error.URLError: <urlopen error [Errno 8] nodename nor servname provided, or not known>

 !end custom-end
You can also use !edit to open your default editor and modify the prompt before sending it to the model. yes bestie, the editor you already live in 💅
Chatting with gpt-5.6-luna
Type 'exit' or 'quit' to exit
Type '!multi' to enter multiple lines, then '!end' to finish
Type '!edit' to open your default editor and modify the prompt.
Type '!fragment <my_fragment> [<another_fragment> ...]' to insert one or more fragments
> !edit
llm chat takes the same --tool/-T and --functions options as llm prompt. You can use this to start a chat with the specified tools enabled. tools ON, chaos managed ✨
🌈 Listing available models 🌈
The llm models command lists every model that can be used with LLM, along with their aliases. This includes models that have been installed using plugins <#plugins> — yep, the whole plugin crew is invited to the party 🎀
llm modelsExample output:
OpenAI Responses: gpt-5.5
OpenAI Responses: gpt-5.5-2026-04-23
OpenAI Responses: gpt-5.6-sol
OpenAI Responses: gpt-5.6-terra
OpenAI Responses: gpt-5.6-luna (aliases: luna)
...
Add one or more -q term options to search for models matching all of those search terms:
llm models -q gpt-5.6
llm models -q gpt -q sol
Use one or more -m options to indicate specific models, either by their model ID or one of their aliases:
llm models -m gpt-5.6-luna -m claude-opus-4.8Add --json to return an array of model records with aliases, capability flags, attachment types and server_side_tools. Combine it with -m to inspect one or more specific models; adding --options includes each model's option schemas:
llm models --json -m gpt-5.6-lunaAdd --options to also see documentation for the options supported by each model:
llm models --optionsOutput:
🦋 OpenAI Chat: gpt-4o (aliases: 4o)
okay so this one is like, the main character of the OpenAI chat lineup, and here's everything you can tweak about it 💅
Options:
temperature:float— bestie this is the sampling temperature, and it lives between0and2. Higher values like0.8make the output more random, while lower values like0.2make it more focused and deterministic. pick your chaos level fr.max_tokens:int— the maximum number of tokens to generate. that's it, that's the cap 👑top_p:float— an alternative to sampling with temperature, called nucleus sampling, where the model considers the results of the tokens withtop_pprobability mass. So0.1means only the tokens comprising the top 10% probability mass are considered. Recommended to usetop_portemperaturebut not both (pick one, don't be greedy 💀).frequency_penalty:float— a number between-2.0and2.0. Positive values penalize new tokens based on their existing frequency in the text so far, decreasing the model's likelihood to repeat the same line verbatim. so like, anti-broken-record mode 🎀presence_penalty:float— a number between-2.0and2.0. Positive values penalize new tokens based on whether they appear in the text so far, increasing the model's likelihood to talk about new topics. new-topic energy ✨stop:str— a string where the API will stop generating further tokens. bye bestie, we're done here 🫶logit_bias:dict, str— modify the likelihood of specified tokens appearing in the completion. pass a JSON string like'{"1712":-100, "892":-100, "1489":-100}'seed:int— integer seed to attempt to sample deterministically. lowkey reproducibility icon.json_object:boolean— output a valid JSON object{...}. Prompt must mention JSON. no cap, it has to say JSON.image_detail:str— controls the detail level for image attachments. Supported values arelow,high, andauto.service_tier:str— the processing tier to use for this request — for example'fast'for Fast mode (faster responses at a higher price) or'flex'for slower, cheaper processing on models that support those tiers.
Attachment types:
application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
- streaming
- schemas
- tools
- async
Keys:
key:openaienv_var:OPENAI_API_KEY
🌸 OpenAI Chat: gpt-4o-mini (aliases: 4o-mini)
same vibe, smaller package, still iconic 🎀
Options:
temperature:floatmax_tokens:inttop_p:floatfrequency_penalty:floatpresence_penalty:floatstop:strlogit_bias:dict, strseed:intjson_object:booleanimage_detail:strservice_tier:str
Attachment types:
application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
- streaming
- schemas
- tools
- async
Keys:
key:openaienv_var:OPENAI_API_KEY
🧚 OpenAI Chat: gpt-4.1 (aliases: 4.1)
Options:
temperature:floatmax_tokens:inttop_p:floatfrequency_penalty:floatpresence_penalty:floatstop:strlogit_bias:dict, strseed:intjson_object:booleanimage_detail:strservice_tier:str
Attachment types:
application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
- streaming
- schemas
- tools
- async
Keys:
key:openaienv_var:OPENAI_API_KEY
💜 OpenAI Chat: gpt-4.1-mini (aliases: 4.1-mini)
Options:
temperature:floatmax_tokens:inttop_p:floatfrequency_penalty:floatpresence_penalty:floatstop:strlogit_bias:dict, strseed:intjson_object:booleanimage_detail:strservice_tier:str
Attachment types:
application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
- streaming
- schemas
- tools
- async
Keys:
key:openaienv_var:OPENAI_API_KEY
⭐ OpenAI Chat: gpt-4.1-nano (aliases: 4.1-nano)
tiny but mighty, the little legend 🫶
Options:
temperature:floatmax_tokens:inttop_p:floatfrequency_penalty:floatpresence_penalty:floatstop:strlogit_bias:dict, strseed:intjson_object:booleanimage_detail:strservice_tier:str
Attachment types:
application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
- streaming
- schemas
- tools
- async
Keys:
key:openaienv_var:OPENAI_API_KEY
🌈 OpenAI Chat: gpt-3.5-turbo (aliases: 3.5, chatgpt)
the og, the blueprint, the one that started it all 😭✨
Options:
temperature:floatmax_tokens:inttop_p:floatfrequency_penalty:floatpresence_penalty:floatstop:strlogit_bias:dict, strseed:intjson_object:booleanimage_detail:strservice_tier:str
Features:
- streaming
- async
Keys:
key:openaienv_var:OPENAI_API_KEY
bestie notice: noschemasand notoolson this one, and no attachment types either. we keep it real 💀
🎀 OpenAI Chat: gpt-3.5-turbo-16k (aliases: chatgpt-16k, 3.5-16k)
Options:
temperature:floatmax_tokens:inttop_p:floatfrequency_penalty:floatpresence_penalty:floatstop:strlogit_bias:dict, strseed:intjson_object:booleanimage_detail:strservice_tier:str
Features:
- streaming
- async
Keys:
key:openaienv_var:OPENAI_API_KEY
🔥 OpenAI Chat: gpt-4 (aliases: 4, gpt4)
Options:
temperature:floatmax_tokens:inttop_p:floatfrequency_penalty:floatpresence_penalty:floatstop:strlogit_bias:dict, strseed:intjson_object:booleanimage_detail:strservice_tier:str
Features:
- streaming
- async
Keys:
key:openaienv_var:OPENAI_API_KEY
🍓 OpenAI Chat: gpt-4-turbo-2024-04-09
no aliases on this one, it's too cool for nicknames 💅
Options:
temperature:floatmax_tokens:inttop_p:floatfrequency_penalty:floatpresence_penalty:floatstop:strlogit_bias:dict, strseed:intjson_object:booleanimage_detail:strservice_tier:str
Features:
- streaming
- async
Keys:
key:openaienv_var:OPENAI_API_KEY
💖 OpenAI Chat: gpt-4-turbo (aliases: gpt-4-turbo-preview, 4-turbo, 4t)
Options:
temperature:floatmax_tokens:inttop_p:floatfrequency_penalty:floatpresence_penalty:floatstop:strlogit_bias:dict, strseed:intjson_object:booleanimage_detail:strservice_tier:str
Features:
- streaming
- async
Keys:
key:openaienv_var:OPENAI_API_KEY
🌸 OpenAI Responses: o1
and now we pivot to the Responses family bestie, and this one is giving big brain energy 🧠✨
Options:
temperature:float— What sampling temperature to use, between0and2. Higher values like0.8will make the output more random, while lower values like0.2will make it more focused and deterministic.max_tokens:int— Maximum number of tokens to generate.top_p:float— An alternative to sampling with temperature, called nucleus sampling, where the model considers the results of the tokens withtop_pprobability mass. So0.1means only the tokens comprising the top 10% probability mass are considered. Recommended to usetop_portemperaturebut not both.frequency_penalty:float— Number between-2.0and2.0. Positive values penalize new tokens based on their existing frequency in the text so far, decreasing the model's likelihood to repeat the same line verbatim.presence_penalty:float— Number between-2.0and2.0. Positive values penalize new tokens based on whether they appear in the text so far, increasing the model's likelihood to talk about new topics.stop:str— A string where the API will stop generating further tokens.logit_bias:dict, str— Modify the likelihood of specified tokens appearing in the completion. Pass a JSON string like'{"1712":-100, "892":-100, "1489":-100}'seed:int— Integer seed to attempt to sample deterministicallyjson_object:boolean— Output a valid JSON object{...}. Prompt must mention JSON.chat_completions:boolean— Force the use of the older/v1/chat/completionsendpoint instead of/v1/responses. Most callers should leave this off; set totrueto fall back to the Chat Completions code path for compatibility. ngl, most of y'all should just not touch this 🙈image_detail:str— Controls the detail level for image attachments. Supported values arelow,high, andauto.reasoning_effort:str— Constraints effort on reasoning for reasoning models. Currently supported values arelow,medium, andhigh. Reducing reasoning effort can result in faster responses and fewer tokens used on reasoning in a response.reasoning_summary:str— Requests a summary of the model's reasoning. Supported values areauto,concise, anddetailed.service_tier:str— The processing tier to use for this request — for example'fast'for Fast mode (faster responses at a higher price) or'flex'for slower, cheaper processing on models that support those tiers.
Attachment types:
application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
- schemas
- tools
- async
Keys:
key:openaienv_var:OPENAI_API_KEY
heads up bestie: this one hasschemasandtoolsandasyncbut no streaming in the feature list. just how it is 🫶
👑 OpenAI Responses: o1-2024-12-17
Options:
temperature:floatmax_tokens:inttop_p:floatfrequency_penalty:floatpresence_penalty:floatstop:strlogit_bias:dict, strseed:int
Picking up right where we left off — here's the rest of that previous model's option lineup, bestie:
json_object: boolean
chat_completions: boolean
image_detail: str
reasoning_effort: str
reasoning_summary: str
service_tier: str
Attachment types: application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
schemastoolsasync
Keys:
key:openaienv_var:OPENAI_API_KEY
🍓 OpenAI Responses: o3-mini
OK so this one's the lil sibling of the family. Here's her whole vibe:
temperature: float
max_tokens: int
top_p: float
frequency_penalty: float
presence_penalty: float
stop: str
logit_bias: dict, str
seed: int
json_object: boolean
chat_completions: boolean
image_detail: str
reasoning_effort: str
reasoning_summary: str
service_tier: str
Features:
streamingschemastoolsasync
Keys:
key:openaienv_var:OPENAI_API_KEY
Not a single attachment type listed here — so no PDFs and no pics for this one, just vibes.
🌸 OpenAI Responses: o3
Next up, and now we're talking, because the attachment types said BET:
temperature: float
max_tokens: int
top_p: float
frequency_penalty: float
presence_penalty: float
stop: str
logit_bias: dict, str
seed: int
json_object: boolean
chat_completions: boolean
image_detail: str
reasoning_effort: str
reasoning_summary: str
service_tier: str
Attachment types: application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
streamingschemastoolsasync
Keys:
key:openaienv_var:OPENAI_API_KEY
🦋 OpenAI Responses: o4-mini
Same energy as o3, just a lil more mini, and yes she also eats your files:
temperature: float
max_tokens: int
top_p: float
frequency_penalty: float
presence_penalty: float
stop: str
logit_bias: dict, str
seed: int
json_object: boolean
chat_completions: boolean
image_detail: str
reasoning_effort: str
reasoning_summary: str
service_tier: str
Attachment types: application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
streamingschemastoolsasync
Keys:
key:openaienv_var:OPENAI_API_KEY
⭐ OpenAI Responses: gpt-5
Ooh bestie, now THIS is the one that brings a whole new option to the party — say hi to verbosity. Everything else stays iconic:
temperature: float
max_tokens: int
top_p: float
frequency_penalty: float
presence_penalty: float
stop: str
logit_bias: dict, str
seed: int
json_object: boolean
chat_completions: boolean
image_detail: str
reasoning_effort: str
reasoning_summary: str
verbosity: str
service_tier: str
Attachment types: application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
streamingschemastoolsasync
Keys:
key:openaienv_var:OPENAI_API_KEY
💜 OpenAI Responses: gpt-5-mini
The mini version, still serving the exact same option spread, verbosity included:
temperature: float
max_tokens: int
top_p: float
frequency_penalty: float
presence_penalty: float
stop: str
logit_bias: dict, str
seed: int
json_object: boolean
chat_completions: boolean
image_detail: str
reasoning_effort: str
reasoning_summary: str
verbosity: str
service_tier: str
Attachment types: application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
streamingschemastoolsasync
Keys:
key:openaienv_var:OPENAI_API_KEY
🎀 OpenAI Responses: gpt-5-nano
Tiny but mighty, same menu of options, same attachment glow-up:
temperature: float
max_tokens: int
top_p: float
frequency_penalty: float
presence_penalty: float
stop: str
logit_bias: dict, str
seed: int
json_object: boolean
chat_completions: boolean
image_detail: str
reasoning_effort: str
reasoning_summary: str
verbosity: str
service_tier: str
Attachment types: application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
streamingschemastoolsasync
Keys:
key:openaienv_var:OPENAI_API_KEY
🌈 OpenAI Responses: gpt-5-2025-08-07
A dated snap of gpt-5, and yeah she carries the exact same everything — no surprises here, iykyk:
temperature: float
max_tokens: int
top_p: float
frequency_penalty: float
presence_penalty: float
stop: str
logit_bias: dict, str
seed: int
json_object: boolean
chat_completions: boolean
image_detail: str
reasoning_effort: str
reasoning_summary: str
verbosity: str
service_tier: str
Attachment types: application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
streamingschemastoolsasync
Keys:
key:openaienv_var:OPENAI_API_KEY
🧚 OpenAI Responses: gpt-5-mini-2025-08-07
The dated mini. Same options, same attachments, same everything. Periodt:
temperature: float
max_tokens: int
top_p: float
frequency_penalty: float
presence_penalty: float
stop: str
logit_bias: dict, str
seed: int
json_object: boolean
chat_completions: boolean
image_detail: str
reasoning_effort: str
reasoning_summary: str
verbosity: str
service_tier: str
Attachment types: application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
streamingschemastoolsasync
Keys:
key:openaienv_var:OPENAI_API_KEY
🫶 OpenAI Responses: gpt-5-nano-2025-08-07
Dated nano, still absolutely slaying the same config:
temperature: float
max_tokens: int
top_p: float
frequency_penalty: float
presence_penalty: float
stop: str
logit_bias: dict, str
seed: int
json_object: boolean
chat_completions: boolean
image_detail: str
reasoning_effort: str
reasoning_summary: str
verbosity: str
service_tier: str
Attachment types: application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
streamingschemastoolsasync
Keys:
key:openaienv_var:OPENAI_API_KEY
✨ OpenAI Responses: gpt-5.1
A dot-release glow-up, and the option list is identical to her gpt-5 ancestors:
temperature: float
max_tokens: int
top_p: float
frequency_penalty: float
presence_penalty: float
stop: str
logit_bias: dict, str
seed: int
json_object: boolean
chat_completions: boolean
image_detail: str
reasoning_effort: str
reasoning_summary: str
verbosity: str
service_tier: str
Attachment types: application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
streamingschemastoolsasync
Keys:
key:openaienv_var:OPENAI_API_KEY
💖 OpenAI Responses: gpt-5.2
Another dot-release, another identical spreadsheet of options, we love consistency:
temperature: float
max_tokens: int
top_p: float
frequency_penalty: float
presence_penalty: float
stop: str
logit_bias: dict, str
seed: int
json_object: boolean
chat_completions: boolean
image_detail: str
reasoning_effort: str
reasoning_summary: str
verbosity: str
service_tier: str
Attachment types: application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
streamingschemastoolsasync
Keys:
key:openaienv_var:OPENAI_API_KEY
🌸 OpenAI Responses: gpt-5.2-chat-latest
The chat-flavored one, and yup, same exact config energy:
temperature: float
max_tokens: int
top_p: float
frequency_penalty: float
presence_penalty: float
stop: str
logit_bias: dict, str
seed: int
json_object: boolean
chat_completions: boolean
image_detail: str
reasoning_effort: str
reasoning_summary: str
verbosity: str
service_tier: str
Attachment types: application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
streamingschemastoolsasync
Keys:
key:openaienv_var:OPENAI_API_KEY
👑 OpenAI Responses: gpt-5.4
A whole minor version up, still keeping the same option roster like the loyal main character she is:
temperature: float
max_tokens: int
top_p: float
frequency_penalty: float
presence_penalty: float
stop: str
logit_bias: dict, str
seed: int
json_object: boolean
chat_completions: boolean
image_detail: str
reasoning_effort: str
reasoning_summary: str
verbosity: str
service_tier: str
Attachment types: application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
streamingschemastoolsasync
Keys:
key:openaienv_var:OPENAI_API_KEY
🌈 OpenAI Responses: gpt-5.4-2026-03-05
And last but never least in this batch, the dated snap of gpt-5.4, holding it down with the exact same everything:
temperature: float
max_tokens: int
top_p: float
frequency_penalty: float
presence_penalty: float
stop: str
logit_bias: dict, str
seed: int
json_object: boolean
chat_completions: boolean
image_detail: str
reasoning_effort: str
reasoning_summary: str
verbosity: str
service_tier: str
Attachment types: application/pdf, image/gif, image/jpeg, image/png, image/webp
Features:
streamingschemastoolsasync
Keys:
key:openaienv_var:OPENAI_API_KEY
Bestie, if you noticed that the last several entries were giving "copy my homework but change it a lil" — yeah, that's the point, they're all the same family. Keep reading for more, because we are NOT done yet 💅
- Features:
streamingschemastoolsasync
- Keys:
- key:
openai - env_var:
OPENAI_API_KEY
- key:
OpenAI Responses: gpt-5.4-mini💖- Options:
temperature: floatmax_tokens: inttop_p: floatfrequency_penalty: floatpresence_penalty: floatstop: strlogit_bias: dict, strseed: intjson_object: booleanchat_completions: booleanimage_detail: strreasoning_effort: strreasoning_summary: strverbosity: strservice_tier: str
- Attachment types:
application/pdf,image/gif,image/jpeg,image/png,image/webp - Features:
streamingschemastoolsasync
- Keys:
- key:
openai - env_var:
OPENAI_API_KEY
- key:
- Options:
OpenAI Responses: gpt-5.4-mini-2026-03-17✨- Options:
temperature: floatmax_tokens: inttop_p: floatfrequency_penalty: floatpresence_penalty: floatstop: strlogit_bias: dict, strseed: intjson_object: booleanchat_completions: booleanimage_detail: strreasoning_effort: strreasoning_summary: strverbosity: strservice_tier: str
- Attachment types:
application/pdf,image/gif,image/jpeg,image/png,image/webp - Features:
streamingschemastoolsasync
- Keys:
- key:
openai - env_var:
OPENAI_API_KEY
- key:
- Options:
OpenAI Responses: gpt-5.4-nano🦋- Options:
temperature: floatmax_tokens: inttop_p: floatfrequency_penalty: floatpresence_penalty: floatstop: strlogit_bias: dict, strseed: intjson_object: booleanchat_completions: booleanimage_detail: strreasoning_effort: strreasoning_summary: strverbosity: strservice_tier: str
- Attachment types:
application/pdf,image/gif,image/jpeg,image/png,image/webp - Features:
streamingschemastoolsasync
- Keys:
- key:
openai - env_var:
OPENAI_API_KEY
- key:
- Options:
OpenAI Responses: gpt-5.4-nano-2026-03-17🌸- Options:
temperature: floatmax_tokens: inttop_p: floatfrequency_penalty: floatpresence_penalty: floatstop: strlogit_bias: dict, strseed: intjson_object: booleanchat_completions: booleanimage_detail: strreasoning_effort: strreasoning_summary: strverbosity: strservice_tier: str
- Attachment types:
application/pdf,image/gif,image/jpeg,image/png,image/webp - Features:
streamingschemastoolsasync
- Keys:
- key:
openai - env_var:
OPENAI_API_KEY
- key:
- Options:
OpenAI Responses: gpt-5.5💅- Options:
temperature: floatmax_tokens: inttop_p: floatfrequency_penalty: floatpresence_penalty: floatstop: strlogit_bias: dict, strseed: intjson_object: booleanchat_completions: booleanimage_detail: strreasoning_effort: strreasoning_summary: strverbosity: strservice_tier: str
- Attachment types:
application/pdf,image/gif,image/jpeg,image/png,image/webp - Features:
streamingschemastoolsasync
- Keys:
- key:
openai - env_var:
OPENAI_API_KEY
- key:
- Options:
OpenAI Responses: gpt-5.5-2026-04-23🫶- Options:
temperature: floatmax_tokens: inttop_p: floatfrequency_penalty: floatpresence_penalty: floatstop: strlogit_bias: dict, strseed: intjson_object: booleanchat_completions: booleanimage_detail: strreasoning_effort: strreasoning_summary: strverbosity: strservice_tier: str
- Attachment types:
application/pdf,image/gif,image/jpeg,image/png,image/webp - Features:
streamingschemastoolsasync
- Keys:
- key:
openai - env_var:
OPENAI_API_KEY
- key:
- Options:
OpenAI Responses: gpt-5.6-sol⭐- Options:
temperature: floatmax_tokens: inttop_p: floatfrequency_penalty: floatpresence_penalty: floatstop: strlogit_bias: dict, strseed: intjson_object: booleanchat_completions: booleanimage_detail: strreasoning_effort: strreasoning_summary: strverbosity: strservice_tier: str
- Attachment types:
application/pdf,image/gif,image/jpeg,image/png,image/webp - Features:
streamingschemastoolsasync
- Keys:
- key:
openai - env_var:
OPENAI_API_KEY
- key:
- Options:
OpenAI Responses: gpt-5.6-terra🌈- Options:
temperature: floatmax_tokens: inttop_p: floatfrequency_penalty: floatpresence_penalty: floatstop: strlogit_bias: dict, strseed: intjson_object: booleanchat_completions: booleanimage_detail: strreasoning_effort: strreasoning_summary: strverbosity: strservice_tier: str
- Attachment types:
application/pdf,image/gif,image/jpeg,image/png,image/webp - Features:
streamingschemastoolsasync
- Keys:
- key:
openai - env_var:
OPENAI_API_KEY
- key:
- Options:
OpenAI Responses: gpt-5.6-luna🌙- Options:
temperature: floatmax_tokens: inttop_p: floatfrequency_penalty: floatpresence_penalty: floatstop: strlogit_bias: dict, strseed: intjson_object: booleanchat_completions: booleanimage_detail: strreasoning_effort: strreasoning_summary: strverbosity: strservice_tier: str
- Attachment types:
application/pdf,image/gif,image/jpeg,image/png,image/webp - Features:
streamingschemastoolsasync
- Keys:
- key:
openai - env_var:
OPENAI_API_KEY
- key:
- Options:
OpenAI Completion: gpt-3.5-turbo-instruct(aliases:3.5-instruct,chatgpt-instruct) 🎀- Options:
temperature: float- the sampling temperature to use, somewhere between 0 and 2. Higher values like 0.8 make the output more random, while lower values like 0.2 make it more focused and deterministic.
max_tokens: int- maximum number of tokens to generate.
top_p: float- an alternative to sampling with temperature, called nucleus sampling — the model looks at the results of the tokens with
top_pprobability mass. So 0.1 means only the tokens making up the top 10% probability mass are considered. Recommended to usetop_portemperaturebut not both.
- an alternative to sampling with temperature, called nucleus sampling — the model looks at the results of the tokens with
frequency_penalty: float- a number between -2.0 and 2.0. Positive values penalize new tokens based on their existing frequency in the text so far, decreasing the model's likelihood of repeating the same line verbatim.
presence_penalty: float- a number between -2.0 and 2.0. Positive values penalize new tokens based on whether they appear in the text so far, increasing the model's likelihood of talking about new topics.
stop: str- a string where the API will stop generating further tokens.
logit_bias: dict, str- modify the likelihood of specified tokens appearing in the completion. Pass a JSON string like
'{"1712":-100, "892":-100, "1489":-100}'
- modify the likelihood of specified tokens appearing in the completion. Pass a JSON string like
seed: int- integer seed to attempt to sample deterministically
logprobs: int- include the log probabilities of most likely N per token
- Features:
streaming
- Keys:
- key:
openai - env_var:
OPENAI_API_KEY
- key:
- Options:
okay so when you're running a prompt, you can pass the full model name or any of the aliases to the -m/--model option:
llm -m luna \
  'As many names for cheesecakes as you can think of, with detailed descriptions'
✨ Setting default options for models ✨
Want a specific model to just always use a certain option? Say less. Use the llm models options set command:
llm models options set gpt-4.1 temperature 0.5From then on, that option gets applied automatically any time you run a prompt through the gpt-4o model. 💅
Default options live in the model_options.json file inside the LLM configuration directory.
You can list every default option across all the models with llm models options list:
llm models options listOr show them for one individual model with llm models options show <model_id>:
llm models options show gpt-4.1To clear a default option, use the llm models options clear command:
llm models options clear gpt-4.1 temperatureOr clear every default option for a model like this:
llm models options clear gpt-4.1Default model options are respected by both the llm prompt and the llm chat commands. They will not be applied when you use LLM as a Python library (<#python-api>).
👑 OpenAI models 👑
LLM ships with a default plugin for talking to OpenAI's API. OpenAI offer both language models and embedding models, and LLM can access both types. 🫶
🌸 Configuration 🌸
All OpenAI models are accessed using an API key. You can obtain one from the API keys page at https://platform.openai.com/api-keys on their site.
Once you've created a key, configure LLM to use it by running:
llm keys set openaiThen paste in the API key. 🔑
🦋 OpenAI language models 🦋
Run llm models for a full list of available models. The OpenAI models supported by LLM are:
- OpenAI Chat:
gpt-4o(aliases:4o) - OpenAI Chat:
gpt-4o-mini(aliases:4o-mini) - OpenAI Chat:
gpt-4.1(aliases:4.1) - OpenAI Chat:
gpt-4.1-mini(aliases:4.1-mini) - OpenAI Chat:
gpt-4.1-nano(aliases:4.1-nano) - OpenAI Chat:
gpt-3.5-turbo(aliases:3.5,chatgpt) - OpenAI Chat:
gpt-3.5-turbo-16k(aliases:chatgpt-16k,3.5-16k) - OpenAI Chat:
gpt-4(aliases:4,gpt4) - OpenAI Chat:
gpt-4-turbo-2024-04-09 - OpenAI Chat:
gpt-4-turbo(aliases:gpt-4-turbo-preview,4-turbo,4t) - OpenAI Responses:
o1 - OpenAI Responses:
o1-2024-12-17 - OpenAI Responses:
o3-mini - OpenAI Responses:
o3 - OpenAI Responses:
o4-mini - OpenAI Responses:
gpt-5 - OpenAI Responses:
gpt-5-mini - OpenAI Responses:
gpt-5-nano - OpenAI Responses:
gpt-5-2025-08-07 - OpenAI Responses:
gpt-5-mini-2025-08-07 - OpenAI Responses:
gpt-5-nano-2025-08-07 - OpenAI Responses:
gpt-5.1 - OpenAI Responses:
gpt-5.2 - OpenAI Responses:
gpt-5.2-chat-latest - OpenAI Responses:
gpt-5.4 - OpenAI Responses:
gpt-5.4-2026-03-05 - OpenAI Responses:
gpt-5.4-mini - OpenAI Responses:
gpt-5.4-mini-2026-03-17 - OpenAI Responses:
gpt-5.4-nano - OpenAI Responses:
gpt-5.4-nano-2026-03-17 - OpenAI Responses:
gpt-5.5 - OpenAI Responses:
gpt-5.5-2026-04-23 - OpenAI Responses:
gpt-5.6-sol - OpenAI Responses:
gpt-5.6-terra - OpenAI Responses:
gpt-5.6-luna - OpenAI Completion:
gpt-3.5-turbo-instruct(aliases:3.5-instruct,chatgpt-instruct)
✨ bestie the full tea on every single one of these lives in the OpenAI models documentation: https://platform.openai.com/docs/models — go sip 💅
Ok so which one is the default? gpt-5.6-luna — she's one of the less expensive ones and she's the one you get if you don't specify a model at all. No model specified, no problem, luna shows up 💖 And for the rest of them? Consult OpenAI's model documentation, same link: https://platform.openai.com/docs/models 🌸
✨ Model features ✨
Here's what actually works with the OpenAI models, bestie:
- System prompts can be used to provide instructions that have a higher weight than the prompt itself. (iykyk — the system prompt runs the vibe, the prompt just asks nicely 🫶)
- Attachments. Many OpenAI models support image inputs — check which ones using
llm models --options. And plot twist: any model that accepts images can also accept PDFs 📄✨ - Schemas can be used to influence the JSON structure of the model output.
- Model options can be used to set parameters like temperature. Use
llm models --optionsfor a full list of supported options.
🌈 Web Search 🌈
Models that use the OpenAI Responses API can search the web using the WebSearch server-side tool:
llm -m gpt-5.6-luna -T WebSearch 'Search the web for a positive news story from today'The model decides whether to search based on the prompt — she's the main character making that call, not you 💅 The Python API accepts the same tool:
import llm
from llm.default_plugins.openai_models import WebSearch

response = llm.get_model("gpt-5.6-luna").prompt(
    "Search the web for a positive news story from today",
    tools=[WebSearch(include_sources=True)],
)
print(response.text())
Domain filters, ok so: up to 100 allowed domains and up to 100 blocked domains. Omit http:// or https:// — just the bare domain please — and heads up, each entry also covers its subdomains:
WebSearch(
    allowed_domains=["openai.com", "python.org"],
    blocked_domains=["example.com"],
)
Use search_context_size="low", "medium" or "high" to control how much search-result context is made available to the model. Set external_web_access=False for cached/indexed results only. And return_token_budget="unlimited" removes the standard returned-token limit for longer GPT-5 reasoning searches — but bestie, lowkey be careful, that can increase latency and cost 💀
Approximate geographic context can include a two-letter country code, city, region and IANA timezone. LLM adds the required "type": "approximate" field when it is omitted:
WebSearch(
    user_location={
        "country": "GB",
        "city": "London",
        "timezone": "Europe/London",
    }
)
include_sources=True requests every URL consulted during search and records them in the server-executed tool call arguments. For image search, use search_content_types=["image", "text"] and image_settings={"max_results": 3, "caption": True}. Set include_results=True to request and record the raw image result objects in the corresponding server-executed tool result 🖼️
See OpenAI's Web Search documentation for model behavior, current limitations, citations and pricing details: https://developers.openai.com/api/docs/guides/tools-web-search
🧚 Code Interpreter 🧚
Models that use the OpenAI Responses API can run Python in an OpenAI-managed container using the CodeInterpreter server-side tool:
llm -m gpt-5.6-luna -T 'CodeInterpreter(memory_limit="4g")' 'Run this calculation'The same tool can be used from Python:
import llm
from llm.default_plugins.openai_models import CodeInterpreter

model = llm.get_model("gpt-5.6-luna")
response = model.prompt(
    "Use the python tool to calculate 111111 * 333333",
    tools=[CodeInterpreter()],
)
print(response.text())
Fun fact bestie: OpenAI calls this Code Interpreter, but models know it as the "python tool" — so referring to that name in the prompt is the most explicit way to request it 👑
By default OpenAI automatically creates a 1 GB container, or reuses an active container from the model's context. Configure a larger automatic container or make existing OpenAI files available to it like this:
CodeInterpreter(
    memory_limit="4g",
    file_ids=["file-1", "file-2"],
)
The accepted memory limits are 1g, 4g, 16g and 64g. Higher limits cost more 💸 To reuse a container that was created separately, pass its ID:
CodeInterpreter(container="cntr_abc123")⚠️ An explicit container ID cannot be combined withmemory_limitorfile_ids. Pick a lane bestie.
LLM automatically requests the full Code Interpreter output and records returned code and output as server-executed tool parts; it never tries to run that code locally. Not me being responsible with your laptop 🙈
OpenAI containers are ephemeral and expire after 20 minutes without activity. See OpenAI's Code Interpreter documentation for container behavior, supported files and current pricing details: https://developers.openai.com/api/docs/guides/tools-code-interpreter
🔥 Fast mode and service tiers 🔥
OpenAI models can process requests at different speeds and prices using the service_tier API parameter. Fast mode runs up to 2.5x faster than standard processing at a higher per-token price, with the biggest speed increase on gpt-5.6-sol. Flex processing is slower but cheaper. Each tier works with a different subset of models — the Fast and Flex tables on OpenAI's pricing page are the definitive list of which models support which tier.
Fast mode: https://developers.openai.com/api/docs/guides/fast-mode Flex processing: https://developers.openai.com/api/docs/guides/flex-processing Pricing page: https://developers.openai.com/api/docs/pricing
All of the OpenAI models supported by LLM expose a service_tier option — with the exception of the legacy gpt-3.5-turbo-instruct completion model. Use -o service_tier fast to enable Fast mode for a prompt:
llm -m gpt-5.6-sol -o service_tier fast 'Fast facts about pelicans'The value is passed straight to the API, so other tiers such as priority (the older name for fast) and flex (slower but cheaper processing) work too:
llm -m gpt-5.4 -o service_tier flex 'No rush: facts about pelicans'💜 OpenAI embedding models 💜
Run llm embed-models for a list of embedding models. The following OpenAI embedding models are supported by LLM:
ada-002(aliases:ada,oai)3-small3-large3-small-5123-large-2563-large-1024
The 3-small model is currently the most inexpensive. 3-large costs more but is more capable — see New embedding models and API updates on the OpenAI blog for details and benchmarks: https://openai.com/blog/new-embedding-models-and-api-updates
An important characteristic of any embedding model is the size of the vector it returns. Smaller vectors cost less to store and query, but may be less accurate 📉
OpenAI 3-small and 3-large vectors can be safely truncated to lower dimensions without losing too much accuracy. The -int models provided by LLM are pre-configured to do this, so 3-large-256 is the 3-large model truncated to 256 dimensions.
The vector size of the supported OpenAI embedding models are as follows:
ada-002— 15363-small— 15363-large— 30723-small-512— 5123-large-256— 2563-large-1024— 1024
🌸 OpenAI completion models 🌸
The gpt-3.5-turbo-instruct model is a little different — she's a completion model rather than a chat model, described in the OpenAI completions documentation: https://platform.openai.com/docs/api-reference/completions/create
🦋 Adding more OpenAI models 🦋
OpenAI occasionally release new models with new names. LLM aims to ship new releases to support these, but you can also configure them directly, by adding them to a extra-openai-models.yaml configuration file 🎀
Run this command to find the directory in which this file should be created:
dirname "$(llm logs path)"On my Mac laptop I get this:
~/Library/Application Support/io.datasette.llmCreate a file in that directory called extra-openai-models.yaml.
Let's say OpenAI have just released the gpt-3.5-turbo-0613 model and you want to use it, despite LLM not yet shipping support. You could configure that by adding this to the file:
- model_id: gpt-3.5-turbo-0613
  model_name: gpt-3.5-turbo-0613
  aliases: ["0613"]
The model_id is the little name tag that gets written into your LLM logs — it's how the model shows up in your history. You can also toss in a list of aliases for that model if you want extra nicknames. The model_name is the actual model identifier that gets handed to the API, and bestie, it has to match exactly what the API is expecting. No typos, no vibes-based spelling. 💅
If your model is a completion model (think gpt-3.5-turbo-instruct), add completion: true to the config. ✨
If the model should be using the OpenAI Responses API instead of Chat Completions, add responses: true. This is the move for models like o1, o3-mini and gpt-5-style models that you reach through /v1/responses. 🦋
If the model supports structured extraction via json_schema, add supports_schema: true.
For reasoning models like o1 or o3-mini, add reasoning: true. 🧠
And if the model supports the service_tier parameter — peep Fast mode and service tiers — add service_tier: true to unlock the matching option.
Once that config is in place, this command should run a prompt against your brand new model:
llm -m 0613 'What is the capital of France?'Then run llm models to confirm the new model is actually there now:
llm modelsExample output, looking all cute and official:
OpenAI Chat: gpt-3.5-turbo (aliases: 3.5, chatgpt)
OpenAI Chat: gpt-3.5-turbo-16k (aliases: chatgpt-16k, 3.5-16k)
OpenAI Chat: gpt-4 (aliases: 4, gpt4)
OpenAI Chat: gpt-3.5-turbo-0613 (aliases: 0613)
Run llm logs -n 1 and you should see that your prompt and its response got logged to the database correctly. Receipts. 🧾
✨ Other models ✨
LLM ships with OpenAI models by default, that's the whole starting lineup. You can install plugins <#plugins> to add support for other models — and you can also add additional OpenAI-API-compatible models using a configuration file <#openai-extra-models>. So many doors, all open. 🚪
🌸 Installing and using a local model 🌸
LLM plugins <#plugins> can serve up local models that run right on your machine. Main character energy, no cloud required. 👑
To install llm-gpt4all <https://github.com/simonw/llm-gpt4all>, which brings you 17 models from the GPT4All <https://gpt4all.io/> project, run this:
llm install llm-gpt4allThen run llm models to see the list of available models go from "okay" to "expanded". 🎀
To run a prompt through one of the GPT4All models, specify it with -m/--model:
llm -m orca-mini-3b-gguf2-q4_0 'What is the capital of France?'Heads up: the model gets downloaded and cached the first time you use it. So the first run is the slow one, then you're golden. ⭐
Check the plugin directory <#plugin-directory> for the latest list of available plugins for other models.
💜 OpenAI-compatible models 💜
Projects like LocalAI <https://localai.io/> hand you a REST API that cosplays as the OpenAI API but can actually run other models — including ones you can install on your own machine. These get added using the exact same configuration mechanism. Same vibe, different model. 🫶
🔥 Run against an endpoint without configuring it 🔥
Use llm openai endpoint to run a prompt directly against an OpenAI-compatible base URL:
llm openai endpoint https://example.com/v1 \
  -m model-id \
  "What is the capital of France?"
Important things, listen up bestie — this command does not register the model, and it does not log the prompt or response. It also does not send your configured OpenAI API key to the endpoint. Use --key to explicitly hand over a key, or pass the alias of a key you saved with llm keys set:
llm openai endpoint https://example.com/v1 \
  -m model-id \
  --key custom-endpoint \
  "What is the capital of France?"
Want the model IDs the endpoint is advertising? Use --models. This requests the models resource relative to the base URL, so a base URL ending in /v1 will request /v1/models:
llm openai endpoint https://example.com/v1 --modelsOmit the prompt entirely and it'll read from stdin. In an interactive terminal the command just waits for input until EOF, matching llm prompt:
llm openai endpoint https://example.com/v1 -m model-idUse --chat to kick off an interactive chat:
llm openai endpoint https://example.com/v1 -m model-id --chatUse -a or --attachment to attach an image or a PDF. Chat Completions endpoints can also receive WAV or MP3 audio attachments:
llm openai endpoint https://example.com/v1 \
  -m model-id \
  -a image.jpg \
  "Describe this image"
Use --at path-or-url mimetype when the attachment type can't be inferred. And if you attach stuff while starting an interactive chat, those attachments ride along with the first message. 🎀
Use -t or --template to apply an existing LLM template. Template prompts, system prompts, defaults, model options, model IDs, schemas and attachments are all supported. Pass template variables with -p or --param:
llm openai endpoint https://example.com/v1 \
  -t summarize \
  -p style concise \
  "Text to summarize"
The -m option can be left out if the template already specifies a model. In an interactive chat started with --chat, the template gets applied to every single turn. Without --chat, a template that brings its own prompt runs once even when you don't supply a prompt argument. It's giving self-sufficient. 💅
Use --schema to request structured JSON output, or --schema-multi to request an array of matching items. These accept the same inline JSON, file paths, stored schema IDs, template references and concise schema syntax <#schemas-dsl> as llm prompt:
llm openai endpoint https://example.com/v1 \
  -m model-id \
  --schema 'name, age int' \
  "Invent a dog"
Reasoning-capable endpoints can be given a reasoning effort with -o reasoning_effort, and the value can be none, minimal, low, medium, high, xhigh, or max:
llm openai endpoint https://example.com/v1 \
  -m model-id \
  -o reasoning_effort high \
  "Solve this problem"
Responses API endpoints can also be asked for a visible reasoning summary using -o reasoning_summary, with a value of auto, concise, or detailed:
llm openai endpoint https://example.com/v1 \
  --responses \
  -m model-id \
  -o reasoning_summary auto \
  "Solve this problem"
This maps to the Responses API reasoning.summary request field. auto asks the endpoint for the most detailed summary available for that model. Use -R or --hide-reasoning to suppress summary generation for a request.
The command does not send reasoning-specific request fields by default, and it does not request a reasoning summary unless one of these options is used. And if an endpoint doesn't support an option? It'll just return its own API error. Not our problem, that's the endpoint's moment. 💀
Use -T or --tool to make an installed LLM tool available to the model, or --functions to load Python functions from an inline code block or a file:
llm openai endpoint https://example.com/v1 \
  -m model-id \
  -T llm_time \
  --functions tools.py \
  "What time is it?"
Tool calls are executed locally, and their results get sent back to the endpoint until it returns a final answer. --chain-limit controls the maximum number of responses, --tools-debug shows you tool execution details, and --tools-approve asks for confirmation before each call. Tools and trusted Python functions declared by local templates are supported too. 🛠️
The command uses the Chat Completions API by default. Add --responses for an endpoint that implements the Responses API:
llm openai endpoint https://example.com/v1 \
  -m model-id \
  --responses \
  "What is the capital of France?"
Responses endpoints can define their own server-side tool types. Use ServerSideTool to pass an endpoint-specific tool specification through without validation. For example, OpenRouter's web search server tool <https://openrouter.ai/docs/api/reference/responses/web-search> can be used like this:
llm openai endpoint https://openrouter.ai/api/v1 \
  -m openai/gpt-oss-20b:free \
  --key openrouter \
  --responses \
  -R \
  -T 'ServerSideTool(spec={"type":"openrouter:web_search","parameters":{"engine":"exa","max_results":2,"max_uses":1}})' \
  "Search for the OpenRouter documentation URL"
That -R hides the reasoning text this model returns, so the command displays just its final answer. Clean. ✨
🦋 Configure an OpenAI-compatible model 🦋
The model_id is the name LLM will use for the model. The model_name is the name that needs to be passed to the API — and yes, this might differ from the model_id, especially if your model_id could potentially clash with other installed models. Keep them straight! 🙈
The api_base key is how you point the OpenAI client library at a different API endpoint.
To add the orca-mini-3b model hosted by a local installation of LocalAI <https://localai.io/>, drop this into your extra-openai-models.yaml file:
- model_id: orca-openai-compat
  model_name: orca-mini-3b.ggmlv3
api_base: "http://localhost:8080"Ifapi_baseis set, your existing configuredopenaiAPI key will not be sent by default. Safety first, bestie. 🔒
You can set api_key_name to the name of a key stored using the API key management <#api-keys> feature.
Other keys you can use here:
completion: true— for completion models that should use the/completionendpoint as opposed to/completion/chatresponses: true— for models that should use the OpenAI Responses API (/responses) instead of the Chat Completions API (/chat/completions)supports_tools: true— for models that support tool callingcan_stream: false— to disable streaming mode for models that cannot streamsupports_schema: true— for models that support JSON structured schema outputvision: true— for models that can accept images as inputaudio: true— for models that accept audio attachments
Having configured the model like this, run llm models --options -m MODEL_ID to check that it installed correctly. Then you can run prompts against it like so:
llm -m orca-openai-compat 'What is the capital of France?'And confirm they were logged correctly with:
llm logs -n 1🌈 Extra HTTP headers 🌈
Some providers, like openrouter.ai <https://openrouter.ai/docs>, may require additional HTTP headers to be set. You can set those using the headers: key, like this:
- model_id: claude
  model_name: anthropic/claude-2
  api_base: "https://openrouter.ai/api/v1"
  api_key_name: openrouter
  headers:
    HTTP-Referer: "https://llm.datasette.io/"
    X-Title: LLM
👑 Tools 👑
Many Large Language Models have been trained to execute tools as part of responding to a prompt. LLM supports tool usage with both the command-line interface and the Python API. ✨
Exposing tools to LLMs carries risks! Be sure to read the warning below. 🚨 This is not a drill, bestie, go read it.
💅 How tools work 💅
A tool is effectively a function that the model can request to be executed. Here's how that works:
- The initial prompt to the model includes a list of available tools, containing their names, descriptions and parameters.
- The model can then choose to call one of those tools — or sometimes more than one, because it's greedy like that — and it sends back a request for the tool to actually execute.
- The code that's calling the model — which in this case is literally LLM itself — goes ahead and executes the specified tool, using the arguments that were provided.
- Then LLM prompts the model a second time, this time including the output from that tool execution in the mix.
- And then the model gets to use that output to generate its next response. Iconic behavior honestly.
This whole sequence can run several times in a loop, which is what lets the LLM access data, act on that data, and then hand that data off to other tools for even more processing. It's giving relay race. 🏃♀️💨
⚠️ Tools can be dangerous ⚠️
Warning: tools can be dangerous.
Okay bestie, this is the part where we get serious for a sec. 🫶
Applications built on top of LLMs suffer from a whole class of attacks called prompt injection attacks — that's <https://simonwillison.net/tags/prompt-injection/> if you wanna read up. These happen when a malicious third party injects content into the LLM that makes it take tool-based actions which work against the interests of the person using that application. Not cute. Not slay. Straight up sabotage.
Be very careful about which tools you enable when there's any chance you might be exposed to untrusted sources of content — web pages, GitHub issues posted by other people, email and messages that have been sent to you that could come from an attacker. 🙈
And watch out for the lethal trifecta of prompt injection exfiltration attacks — <https://simonwillison.net/2025/Jun/16/the-lethal-trifecta/>. If your tool-enabled LLM has all of the following:
- access to private data
- exposure to malicious instructions
- the ability to exfiltrate information
…then literally anyone who can feed malicious instructions into your LLM — by leaving them on a web page it visits, or sending an email to an inbox that it monitors — could be able to trick your LLM into using other tools to access your private information and then exfiltrate (that means pass out) that data to somewhere the attacker can see it. 💀 Yeah. Terrifying.
🎀 Trying out tools 🎀
LLM ships with a default tool already installed, and it's called llm_version. You can try that out like this:
llm --tool llm_version "What version of LLM is this?" --tdYou can also use -T llm_version as a shortcut for --tool llm_version, because we love efficiency. ✨
The output should look like this:
Tool call: llm_version({})
  0.26a0

The installed version of the LLM is 0.26a0.
Further tools can be installed using plugins, or you can use the llm --functions option to pass tools implemented as Python functions directly, as described here (the usage-tools section).
🐍 LLM's implementation of tools 🐍
In LLM every tool is defined as a Python function. The function can take any number of arguments and can return a string or an object that can be converted to a string. Flexible queen. 💅
Tool functions should include a docstring that describes what the function does. That docstring becomes the description that gets passed to the model — so write it like you mean it.
Tools can also be defined as toolbox classes (that's the python-api-toolbox section), a subclass of llm.Toolbox that lets multiple related tools get bundled together. Toolbox classes can be configured when they are instantiated, and they can also maintain state in between multiple tool calls. Very main character energy.
The Python API can accept functions directly. The command-line interface has two ways for tools to be defined: via plugins that implement the register_tools() plugin hook (the plugin-hooks-register-tools section), or directly on the command-line using the --functions argument to specify a block of Python code defining one or more functions — or a path to a Python file containing the same.
You can use tools with the LLM command-line tool (the usage-tools section) or with the Python API (the python-api-tools section).
⭐ Default tools ⭐
LLM includes some default tools for you to try out:
llm_version()returns the current version of LLMllm_time()returns the current local and UTC time
Try them like this:
llm -T llm_version -T llm_time 'Give me the current time and LLM version' --td💡 Tips for implementing tools 💡
Consult the register_tools() plugin hook documentation (the plugin-hooks-register-tools section) for examples of how to implement tools in plugins.
If your plugin needs access to API secrets I recommend storing those using llm keys set api-name and then reading them using the llm.get_key() utility function (the plugin-utilities-get-key section). This avoids secrets being logged to the database as part of tool calls — keep those keys private, bestie. 🔐
If your tool implementation needs to know which tool call invoked it — for example to key state against the unique tool_call_id — add a parameter named llm_tool_call to your function. It will be passed the llm.ToolCall object for the current invocation, and is hidden from the schema the model sees. See "Accessing the tool call from inside a tool" (the python-api-tools-llm-tool-call section) for details.
✨ Schemas ✨
Large Language Models are very good at producing structured output as JSON or other formats. LLM's schemas feature lets you define the exact structure of the JSON data you want to receive from a model. Chef's kiss. 👑
This feature is supported by models from OpenAI, Anthropic, Google Gemini and can be implemented for others via plugins (the advanced-model-plugins-schemas section).
This page describes schemas used via the llm command-line tool. Schemas can also be used from the Python API (the python-api-schemas section).
🌈 Schemas tutorial 🌈
In this tutorial we're going to use schemas to analyze some news stories.
But first, let's invent some dogs! 🐶
🦋 Getting started with dogs 🦋
LLMs are great at creating test data. Let's define a simple schema for a dog, using LLM's concise schema syntax. We'll pass that to LLM with llm --schema and prompt it to "invent a cool dog":
llm --schema 'name, age int, one_sentence_bio' 'invent a cool dog'I got back Ziggy:
{
  "name": "Ziggy",
  "age": 4,
  "one_sentence_bio": "Ziggy is a hyper-intelligent, bioluminescent dog who loves to perform tricks in the dark and guides his owner home using his glowing fur."
}
The response matched my schema, with name and one_sentence_bio string columns and an integer for age.
We're using the default LLM model here — gpt-5.6-luna. Add -m model to use another model — for example use -m gpt-5.6-sol to have GPT-5.6 Sol invent some dogs.
For a list of available models that support schemas, run this command:
llm models --schemasWant several more dogs? You can pass in that same schema using --schema-multi and ask for several at once:
llm --schema-multi 'name, age int, one_sentence_bio' 'invent 3 really cool dogs'Here's what I got:
{
  "items": [
    {
      "name": "Echo",
      "age": 3,
      "one_sentence_bio": "Echo is a sleek, silvery-blue Siberian Husky with mesmerizing blue eyes and a talent for mimicking sounds, making him a natural entertainer."
    },
    {
      "name": "Nova",
      "age": 2,
      "one_sentence_bio": "Nova is a vibrant, spotted Dalmatian with an adventurous spirit and a knack for agility courses, always ready to leap into action."
    },
    {
      "name": "Pixel",
      "age": 4,
      "one_sentence_bio": "Pixel is a playful, tech-savvy Poodle with a rainbow-colored coat, known for her ability to interact with smart devices and her love for puzzle toys."
    }
  ]
}
So that's the basic idea: we can feed in a schema and LLM will pass it to the underlying model and (usually) get back JSON that conforms to that schema. No cap.
This stuff gets a lot more useful when you start applying it to larger amounts of text, extracting structured details from unstructured content. That's where it really eats. 🔥
📰 Extracting people from a news articles 📰
We are going to extract details of the people who are mentioned in different news stories, and then use those to compile a database.
Let's start by compiling a schema. For each person mentioned we want to extract the following details:
- Their name
- The organization they work for
- Their role
- What we learned about them from the story
We will also record the article headline and the publication date, to make things easier for us later on.
Using LLM's custom, concise schema language, this time with newlines separating the individual fields (for the dogs example we used commas):
name: the person's name
organization: who they represent
role: their job title or role
learned: what we learned about them from this story
article_headline: the headline of the story
article_date: the publication date in YYYY-MM-DD
As you can see, this schema definition is pretty simple — each line has the name of a property we want to capture, then an optional : followed by a description, which doubles as instructions for the model.
The full syntax is described below — you can also include type information for things like numbers.
Let's run this against a news article.
Visit AP News at <https://apnews.com/> and grab the URL to an article. I'm using this one:
https://apnews.com/article/trump-federal-employees-firings-a85d1aaf1088e050d39dcf7e3664bb9fThere's quite a lot of HTML on that page, possibly even enough to exceed GPT-4o mini's 128,000 token input limit. We'll use another tool called strip-tags — <https://github.com/simonw/strip-tags> — to reduce that. If you have uv installed (<https://docs.astral.sh/uv/>) you can call it using uvx strip-tags, otherwise you'll need to install it first:
uv tool install strip-tags
# Or "pip install" or "pipx install"
Now we can run this command to extract the people from that article:
curl 'https://apnews.com/article/trump-federal-employees-firings-a85d1aaf1088e050d39dcf7e3664bb9f' | \
  uvx strip-tags | \
  llm --schema-multi "
name: the person's name
organization: who they represent
role: their job title or role
learned: what we learned about them from this story
article_headline: the headline of the story
article_date: the publication date in YYYY-MM-DD
" --system 'extract people mentioned in this article'
The output I got started like this:
          {
            "items": [
              {
                "name": "William Alsup",
                "organization": "U.S. District Court",
                "role": "Judge",
                "learned": "He ruled that the mass firings of probationary employees were likely unlawful and criticized the authority exercised by the Office of Personnel Management.",
                "article_headline": "Judge finds mass firings of federal probationary workers were likely unlawful",
                "article_date": "2025-02-26"
              },
              {
                "name": "Everett Kelley",
                "organization": "American Federation of Government Employees",
                "role": "National President",
                "learned": "He hailed the court's decision as a victory for employees who were illegally fired.",
                "article_headline": "Judge finds mass firings of federal probationary workers were likely unlawful",
                "article_date": "2025-02-26"
              }
okay so all of that? 💾 It got logged straight into LLM's SQLite database — that's the <#logging> situation, bestie. And the way we pull it back out again is with the llm logs command, aka <#logging-view>. Like this:
llm logs -c --dataBreak it down: the -c flag means "use most recent conversation", and --data says "output just the JSON data that was captured in the response." Chef's kiss. 👑
🦋 schemas, but make it permanent
Not me realizing we're gonna want the exact same schema for other stuff too. Schemas we use get automatically logged to the database ✨ — peek at them with llm schemas:
llm schemasHere's the output, look at her:
- id: 3b7702e71da3dd791d9e17b76c88730e
  summary: |
    {items: [{name, organization, role, learned, article_headline, article_date}]}
  usage: |
    1 time, most recently 2025-02-28T04:50:02.032081+00:00
Want the whole thing tho? Run that command with --full:
llm schemas --fullWhich outputs:
- id: 3b7702e71da3dd791d9e17b76c88730e
  schema: |
    {
      "type": "object",
      "properties": {
        "items": {
          "type": "array",
          "items": {
            "type": "object",
            "properties": {
              "name": {
                "type": "string",
                "description": "the person's name"
              },
    ...
the way that 3b7702e71da3dd791d9e17b76c88730e ID is literally a reusable key 🔑 — you can run the same schema again. Let's do it right now on a totally different URL:
curl 'https://apnews.com/article/bezos-katy-perry-blue-origin-launch-4a074e534baa664abfa6538159c12987' | \
  uvx strip-tags | \
  llm --schema 3b7702e71da3dd791d9e17b76c88730e \
    --system 'extract people mentioned in this article'
Here we're using --schema because our schema ID already corresponds to an array of items. 💅
The result starts like this:
{
  "items": [
    {
      "name": "Katy Perry",
      "organization": "Blue Origin",
      "role": "Singer",
      "learned": "Katy Perry will join the all-female celebrity crew for a spaceflight organized by Blue Origin.",
      "article_headline": "Katy Perry and Gayle King will join Jeff Bezos’ fiancee Lauren Sanchez on Blue Origin spaceflight",
      "article_date": "2023-10-15"
    },
🎀 one more trick (iykyk)
okay so let's turn our schema + system prompt combo into a template — that's <#prompt-templates>, iconic behavior:
llm --schema 3b7702e71da3dd791d9e17b76c88730e \
  --system 'extract people mentioned in this article' \
  --save people
This creates a new template called people 🫶. Confirm it came out right with:
llm templates show peopleWhich will output the YAML version of the template looking like this:
name: people
schema_object:
    properties:
        items:
            items:
                properties:
                    article_date:
                        description: the publication date in YYYY-MM-DD
                        type: string
                    article_headline:
                        description: the headline of the story
                        type: string
                    learned:
                        description: what we learned about them from this story
                        type: string
                    name:
                        description: the person's name
                        type: string
                    organization:
                        description: who they represent
                        type: string
                    role:
                        description: their job title or role
                        type: string
                required:
                - name
                - organization
                - role
                - learned
                - article_headline
                - article_date
                type: object
            type: array
    required:
    - items
    type: object
system: extract people mentioned in this article
and now we run our lil people-extractor against another fresh URL 🌸. Let's use one from The Guardian:
curl https://www.theguardian.com/commentisfree/2025/feb/27/billy-mcfarland-new-fyre-festival-fantasist | \
  strip-tags | llm -t people
Storing the schema in a template means we can just go llm -t people to run the prompt. No cap. Here's what I got back:
{
  "items": [
    {
      "name": "Billy McFarland",
      "organization": "Fyre Festival",
      "role": "Organiser",
      "learned": "Billy McFarland is known for organizing the infamous Fyre Festival and was sentenced to six years in prison for wire fraud related to it. He is attempting to revive the festival with Fyre 2.",
      "article_headline": "Welcome back Billy McFarland and a new Fyre festival. Shows you can’t keep a good fantasist down",
      "article_date": "2025-02-27"
    }
  ]
}
Depending on the model, schema extraction may work against images and PDF files as well. 👀
So I took a screenshot of part of this story in the Onion — <https://theonion.com/mark-zuckerberg-insists-anyone-with-same-skewed-values-1826829272/> — and saved it to the following URL:
https://static.simonwillison.net/static/2025/onion-zuck.jpg
We can pass that as an attachment (that's <#usage-attachments>) using the -a option 💖. This time let's use GPT-4o:
llm -t people -a https://static.simonwillison.net/static/2025/onion-zuck.jpg -m gpt-4oWhich gave me back this:
{
  "items": [
    {
      "name": "Mark Zuckerberg",
      "organization": "Facebook",
      "role": "CEO",
      "learned": "He addressed criticism by suggesting anyone with similar values and thirst for power could make the same mistakes.",
      "article_headline": "Mark Zuckerberg Insists Anyone With Same Skewed Values And Unrelenting Thirst For Power Could Have Made Same Mistakes",
      "article_date": "2018-06-14"
    }
  ]
}
🌈 load it into a database, bestie
Now that we've extracted people from a bunch of different sources, let's load them into a database. 🗄️✨
The llm logs command (you know her, <#logging-view>) has several features for working with logged JSON objects. Since we've been recording multiple objects from each page in an "items" array using our people template, we can access those using the following command:
llm logs --schema t:people --data-key itemsIn place of t:people we could use the 3b7702e71da3dd791d9e17b76c88730e schema ID or even the original schema string instead — see specifying a schema. 💅
This command outputs newline-delimited JSON for every item that has been captured using the specified schema:
{"name": "Katy Perry", "organization": "Blue Origin", "role": "Singer", "learned": "She is one of the passengers on the upcoming spaceflight with Blue Origin."}
{"name": "Gayle King", "organization": "Blue Origin", "role": "TV Journalist", "learned": "She is participating in the upcoming Blue Origin spaceflight."}
{"name": "Lauren Sanchez", "organization": "Blue Origin", "role": "Helicopter Pilot and former TV Journalist", "learned": "She selected the crew for the Blue Origin spaceflight."}
{"name": "Aisha Bowe", "organization": "Engineering firm", "role": "Former NASA Rocket Scientist", "learned": "She is part of the crew for the spaceflight."}
{"name": "Amanda Nguyen", "organization": "Research Scientist", "role": "Activist and Scientist", "learned": "She is included in the crew for the upcoming Blue Origin flight."}
{"name": "Kerianne Flynn", "organization": "Movie Producer", "role": "Producer", "learned": "She will also be a passenger on the upcoming spaceflight."}
{"name": "Billy McFarland", "organization": "Fyre Festival", "role": "Organiser", "learned": "He was sentenced to six years in prison for wire fraud in 2018 and has launched a new festival called Fyre 2.", "article_headline": "Welcome back Billy McFarland and a new Fyre festival. Shows you can\u2019t keep a good fantasist down", "article_date": "2025-02-27"}
{"name": "Mark Zuckerberg", "organization": "Facebook", "role": "CEO", "learned": "He attempted to dismiss criticism by suggesting that anyone with similar values and thirst for power could have made the same mistakes.", "article_headline": "Mark Zuckerberg Insists Anyone With Same Skewed Values And Unrelenting Thirst For Power Could Have Made Same Mistakes", "article_date": "2018-06-14"}
If we add --data-array we'll get back a valid JSON array of objects instead 🎀:
llm logs --schema t:people --data-key items --data-arrayOutput starts:
[{"name": "Katy Perry", "organization": "Blue Origin", "role": "Singer", "learned": "She is one of the passengers on the upcoming spaceflight with Blue Origin."},
 {"name": "Gayle King", "organization": "Blue Origin", "role": "TV Journalist", "learned": "She is participating in the upcoming Blue Origin spaceflight."},
💾 sqlite-utils girlies rise
We can load this into a SQLite database using sqlite-utils — <https://sqlite-utils.datasette.io/> — in particular the sqlite-utils insert command, docs right here: <https://sqlite-utils.datasette.io/en/stable/cli.html#inserting-json-data> 💜
uv tool install sqlite-utils
# or pip install or pipx install
Now we can pipe the JSON into that tool to create a database with a people table 🌸:
llm logs --schema t:people --data-key items --data-array | \
  sqlite-utils insert data.db people -
To see a table of the name, organization and role columns use sqlite-utils rows — <https://sqlite-utils.datasette.io/en/stable/cli.html#returning-all-rows-in-a-table> 🦋:
sqlite-utils rows data.db people -t -c name -c organization -c roleWhich produces:
- Katy Perry — Blue Origin — Singer
- Gayle King — Blue Origin — TV Journalist
- Lauren Sanchez — Blue Origin — Helicopter Pilot and former TV Journalist
- Aisha Bowe — Engineering firm — Former NASA Rocket Scientist
- Amanda Nguyen — Research Scientist — Activist and Scientist
- Kerianne Flynn — Movie Producer — Producer
- Billy McFarland — Fyre Festival — Organiser
- Mark Zuckerberg — Facebook — CEO
okay bestie, you can also poke at the database in a whole web interface using Datasette (https://datasette.io/), which is lowkey the cutest way to browse your data fr:
uvx datasette data.db
# Or install datasette first:
uv tool install datasette # or pip install or pipx install
datasette data.db
Then go visit http://127.0.0.1:8001/data/people and start navigating the data ✨
🌸 Using JSON schemas 🌸
So, everything above was using the concise schema syntax. LLM takes that format and converts it into a JSON schema (https://json-schema.org/) — and you can absolutely use JSON schema directly yourself if you want, no gatekeeping 💅
JSON schema covers the following:
- The data types of fields (
string,number,array,object, etc.) - Required vs. optional fields
- Nested data structures
- Constraints on values (
minimum/maximum, patterns, etc.) - Descriptions of those fields - these can be used to guide the language model
Different models may support different subsets of the overall JSON schema language. You should experiment to figure out what works for the model you are using 👑
LLM recommends that the top level of the schema is an object, not an array, for increased compatibility across multiple models. I suggest using {"items": [array of objects]} if you want to return an array.
The dogs schema above, name, age int, one_sentence_bio, would look like this as a full JSON schema:
{
  "type": "object",
  "properties": {
    "name": {
      "type": "string"
    },
    "age": {
      "type": "integer"
    },
    "one_sentence_bio": {
      "type": "string"
    }
  },
  "required": [
    "name",
    "age",
    "one_sentence_bio"
  ]
}
This JSON can be passed directly to the --schema option, or saved in a file and passed as the filename.
llm --schema '{
  "type": "object",
  "properties": {
    "name": {
      "type": "string"
    },
    "age": {
      "type": "integer"
    },
    "one_sentence_bio": {
      "type": "string"
    }
  },
  "required": [
    "name",
    "age",
    "one_sentence_bio"
  ]
}' 'a surprising dog'
Example output:
{
  "name": "Baxter",
  "age": 3,
  "one_sentence_bio": "Baxter is a rescue dog who learned to skateboard and now performs tricks at local parks, astonishing everyone with his skill!"
}
💖 Ways to specify a schema 💖
LLM accepts schema definitions for both running prompts and exploring logged responses, using the --schema option.
This option can take multiple forms:
- A string providing a JSON schema:
--schema '{"type": "object", ...}' - A condensed schema definition:
--schema 'name,age int' - The name or path of a file on disk containing a JSON schema:
--schema dogs.schema.json - The hexadecimal ID of a previously logged schema:
--schema 520f7aabb121afd14d0c6c237b39ba2d- these IDs can be found using thellm schemascommand. - A schema that has been saved in a template
<#prompt-templates-save>:--schema t:name-of-template, see Saving reusable schemas in templates.
🦋 Concise LLM schema syntax 🦋
JSON schemas can be time-consuming to construct by hand (iykyk 😭). LLM also supports a concise alternative syntax for specifying a schema.
A simple schema for an object with two string properties called name and bio looks like this:
name, bioYou can include type information by adding a type indicator after the property name, separated by a space.
name, bio, age intSupported types are int for integers, float for floating point numbers, str for strings (the default) and bool for true/false booleans.
To include a description of the field to act as a hint to the model, add one after a colon:
name: the person's name, age int: their age, bio: a short bioIf your schema is getting long you can switch from comma-separated to newline-separated, which also allows you to use commas in those descriptions:
name: the person's name
age int: their age
bio: a short bio, no more than three sentences
You can experiment with the syntax using the llm schemas dsl command, which converts the input into a JSON schema:
llm schemas dsl 'name, age int'Output:
{
  "type": "object",
  "properties": {
    "name": {
      "type": "string"
    },
    "age": {
      "type": "integer"
    }
  },
  "required": [
    "name",
    "age"
  ]
}
The Python utility function llm.schema_dsl(schema) can be used to convert this syntax into the equivalent JSON schema dictionary when working with schemas in the Python API <#python-api-schemas>.
🎀 Saving reusable schemas in templates 🎀
If you want to store a schema with a name so you can reuse it easily in the future, the easiest way to do so is to save it in a template <#prompt-templates-schemas>.
The quickest way to do that is with the llm --save option:
llm --schema 'name, age int, one_sentence_bio' --save dogNow you can use it like this:
llm --schema t:dog 'invent a dog'Or:
llm --schema-multi t:dog 'invent three dogs'🌈 Browsing logged JSON objects created using schemas 🌈
By default, all JSON produced using schemas is logged to a SQLite database <#logging>. You can use special options to the llm logs command to extract just those JSON objects in a useful format.
The llm logs --schema X filter option can be used to filter just for responses that were created using the specified schema. You can pass the full schema JSON, a path to the schema on disk or the schema ID.
The --data option causes just the JSON data collected by that schema to be outputted, as newline-delimited JSON.
If you instead want a JSON array of objects (with starting and ending square braces) you can use --data-array instead.
Let's invent some dogs:
llm --schema-multi 'name, ten_word_bio' 'invent 3 cool dogs'
llm --schema-multi 'name, ten_word_bio' 'invent 2 cool dogs'
Having logged these cool dogs, you can see just the data that was returned by those prompts like this:
llm logs --schema-multi 'name, ten_word_bio' --dataWe need to use --schema-multi here because we used that when we first created these records. The --schema option is also supported, and can be passed a filename or JSON schema or schema ID as well.
Output:
{"items": [{"name": "Robo", "ten_word_bio": "A cybernetic dog with laser eyes and super intelligence."}, {"name": "Flamepaw", "ten_word_bio": "Fire-resistant dog with a talent for agility and tricks."}]}
{"items": [{"name": "Bolt", "ten_word_bio": "Lightning-fast border collie, loves frisbee and outdoor adventures."}, {"name": "Luna", "ten_word_bio": "Mystical husky with mesmerizing blue eyes, enjoys snow and play."}, {"name": "Ziggy", "ten_word_bio": "Quirky pug who loves belly rubs and quirky outfits."}]}
Note that the dogs are nested in that "items" key. To access the list of items from that key use --data-key items:
llm logs --schema-multi 'name, ten_word_bio' --data-key itemsOutput:
{"name": "Bolt", "ten_word_bio": "Lightning-fast border collie, loves frisbee and outdoor adventures."}
{"name": "Luna", "ten_word_bio": "Mystical husky with mesmerizing blue eyes, enjoys snow and play."}
{"name": "Ziggy", "ten_word_bio": "Quirky pug who loves belly rubs and quirky outfits."}
{"name": "Robo", "ten_word_bio": "A cybernetic dog with laser eyes and super intelligence."}
{"name": "Flamepaw", "ten_word_bio": "Fire-resistant dog with a talent for agility and tricks."}
Finally, to output a JSON array instead of newline-delimited JSON use --data-array:
llm logs --schema-multi 'name, ten_word_bio' --data-key items --data-arrayOutput:
[{"name": "Bolt", "ten_word_bio": "Lightning-fast border collie, loves frisbee and outdoor adventures."},
 {"name": "Luna", "ten_word_bio": "Mystical husky with mesmerizing blue eyes, enjoys snow and play."},
 {"name": "Ziggy", "ten_word_bio": "Quirky pug who loves belly rubs and quirky outfits."},
 {"name": "Robo", "ten_word_bio": "A cybernetic dog with laser eyes and super intelligence."},
 {"name": "Flamepaw", "ten_word_bio": "Fire-resistant dog with a talent for agility and tricks."}]
Add --data-ids to include "response_id" and "conversation_id" fields in each of the returned objects reflecting the database IDs of the response and conversation they were a part of. This can be useful for tracking the source of each individual row.
llm logs --schema-multi 'name, ten_word_bio' --data-key items --data-idsOutput:
{"name": "Nebula", "ten_word_bio": "A cosmic puppy with starry fur, loves adventures in space.", "response_id": "01jn4dawj8sq0c6t3emf4k5ryx", "conversation_id": "01jn4daxk2sq0c6t3emf4k5aaa"}
{"name": "Echo", "ten_word_bio": "A clever hound with extraordinary hearing, master of hide-and-seek.", "response_id": "01jn4dawj8sq0c6t3emf4k5ryx", "conversation_id": "01jn4daxk2sq0c6t3emf4k5aaa"}
{"name": "Biscuit", "ten_word_bio": "An adorable chef dog, bakes treats that everyone loves.", "response_id": "01jn4dawj8sq0c6t3emf4k5ryx", "conversation_id": "01jn4daxk2sq0c6t3emf4k5aaa"}
{"name": "Cosmo", "ten_word_bio": "Galactic explorer, loves adventures and chasing shooting stars.", "response_id": "01jn4daycb3svj0x7kvp7zrp4q", "conversation_id": "01jn4dazk2sq0c6t3emf4k5bbb"}
{"name": "Pixel", "ten_word_bio": "Tech-savvy pup, builds gadgets and loves virtual playtime.", "response_id": "01jn4daycb3svj0x7kvp7zrp4q", "conversation_id": "01jn4dazk2sq0c6t3emf4k5bbb"}
If a row already has a property called "conversation_id" or "response_id" additional underscores will be appended to the ID key until it no longer overlaps with the existing keys.
The --id-gt $ID and --id-gte $ID options can be useful for ignoring logged schema data prior to a certain point, see Filtering past a specific ID <#logging-filter-id> for details.
✨ Templates ✨
A template can combine a prompt, system prompt, model, default model options, schema, and fragments into a single reusable unit.
Only one template can be used at a time — fr fr, that's the rule. If you wanna stack a bunch of lil prompt pieces together, go use fragments <#fragments> instead, okay? 💖
✨ Getting started with --save ✨
The easiest way to make a template is literally just the --save template_name option. Iconic behaviour, no notes.
Here's how you'd make a template that summarizes text:
llm '$input - summarize this' --save summarizePop $input wherever you want the user's input to land. And if you just... forget to add it? Their input gets tacked onto the end of your regular prompt instead:
llm 'Summarize the following: ' --save summarizeYou can also build templates out of system prompts, bestie:
llm --system 'Summarize this' --save summarizeWanna set a default model for a template? That's --model:
llm --system 'Summarize this' --model gpt-4o --save summarizeAnd yes, you can save default options too:
llm --system 'Speak in French' -o temperature 1.8 --save wild-frenchNow — if you want a literal $ sign in your prompt, you gotta escape it with $$ instead. No cap:
llm --system 'Estimate the cost in $$ of this: $input' --save estimateWant tools in your template? Use --tool/-T one or more times:
llm -T llm_time --system 'Always include the current time in the answer' --save timeYou can also use --functions to add Python function code directly into the template:
llm --functions 'def reverse_string(s): return s[::-1]' --system 'reverse any input' --save reverse
llm -t reverse 'Hello, world!'
Drop --schema in to bake a schema <#usage-schemas> right into your template:
llm --schema dog.schema.json 'invent a dog' --save dogAnd if you add --extract, the setting to extract the first fenced code block <#usage-extract-fenced-code> gets persisted in the template. Obsessed:
llm --system 'write a Python function' --extract --save python-function
llm -t python-function 'calculate haversine distance between two points'
In every single one of these cases, your template gets saved in YAML format in a dedicated directory on disk. Cute, right? 🎀
🌸 Using a template 🌸
You run a named template with the -t/--template option:
curl -s https://example.com/ | llm -t summarizeCombine it with -m to pick a different model:
curl -s https://llm.datasette.io/en/latest/ | \
  llm -t summarize -m gpt-3.5-turbo-16k
Templates can ALSO be a direct path to a YAML file on disk:
llm -t path/to/template.yaml 'extra prompt here'Or a URL pointing at a YAML file hosted online:
llm -t https://raw.githubusercontent.com/simonw/llm-templates/refs/heads/main/python-app.yaml \
  'Python app to pick a random line from a file'
The option can be repeated to combine templates — they get applied left to right, so one template can hand over model config and options while a later one provides or transforms the prompt:
llm -t model-and-options -t summarize 'Text to summarize'Heads up bestie: templates loaded via URLs will have any functions: keys ignored, so nobody accidentally executes arbitrary code. This restriction also applies to templates loaded via the template loaders plugin mechanism <#plugin-hooks-register-template-loaders>. Safety slay. 🔥
💅 Listing available templates 💅
This command lists every available template:
llm templatesThe output looks something like this:
cmd        : system: reply with macos terminal commands only, no extra information
glados     : system: You are GlaDOS prompt: Summarize this:
🦋 Templates as YAML files 🦋
Templates live as YAML files on disk. Periodt.
You can edit (or create) a YAML file for a template using the llm templates edit command:
llm templates edit summarizeThat opens your system default editor.
Tip: You control which editor gets used here with theEDITORenvironment variable — for example, to use VS Code:export EDITOR="code -w"Add that to your~/.zshrcor~/.bashrcfile depending on which shell you use (zsh is the default on macOS since macOS Catalina in 2019).
You can also create or edit template files directly in the templates directory. Where's that directory at? The llm templates path command will tell you:
llm templates pathExample output:
/Users/simon/Library/Application Support/io.datasette.llm/templatesA basic YAML template looks like this:
prompt: 'Summarize this: $input'Or use YAML multi-line strings for longer inputs. I made this one using llm templates edit steampunk:
prompt: >
    Summarize the following text.

    Insert frequent satirical steampunk-themed illustrative anecdotes.
    Really go wild with that.

    Text to summarize: $input
The prompt: > makes the following indented text get treated as a single string, with newlines collapsed into spaces. Use prompt: | if you want to preserve newlines. 🌈
Running that with llm -t steampunk against GPT-4o (via strip-tags <https://github.com/simonw/strip-tags> to strip HTML tags from the input and minify whitespace):
curl -s 'https://til.simonwillison.net/macos/imovie-slides-and-audio' | \
  strip-tags -m | llm -t steampunk -m gpt-4o
Output:
In a fantastical steampunk world, Simon Willison decided to merge an
old MP3 recording with slides from the talk using iMovie. After
exporting the slides as images and importing them into iMovie, he had
to disable the default Ken Burns effect using the "Crop" tool. Then,
Simon manually synchronized the audio by adjusting the duration of
each image. Finally, he published the masterpiece to YouTube, with
the whimsical magic of steampunk-infused illustrations leaving his
viewers in awe.
🎀 System prompts 🎀
When you're working with models that support system prompts, you can set one with a system: key like so:
system: Summarize thisIf you specify only a system prompt you don't need the $input variable at all — llm will use the user's input as the whole of the regular prompt, which then gets processed using the instructions set in that system prompt. Easy.
You can combine system and regular prompts like so:
system: You speak like an excitable Victorian adventurer
prompt: 'Summarize this: $input'
🧚 Fragments 🧚
Templates can reference Fragments <#fragments> using the fragments: and system_fragments: keys. These should be a list of fragment URLs, filepaths or hashes:
fragments:
- https://example.com/robots.txt
- /path/to/file.txt
- 993fd38d898d2b59fd2d16c811da5bdac658faa34f0f4d411edde7c17ebb0680
system_fragments:
- https://example.com/systm-prompt.txt
⭐ Options ⭐
Default options can be set using the options: key:
name: wild-french
system: Speak in French
options:
  temperature: 1.8
🔥 Tools 🔥
The tools: key can hand you a list of tool names from other plugins — either function names or toolbox specifiers:
name: time-plus
tools:
- llm_time
- Datasette("https://example.com/timezone-lookup")
The functions: key can provide a multi-line string of Python code defining additional functions:
name: my-functions
functions: |
  def reverse_string(s: str):
      return s[::-1]

  def greet(name: str):
      return f"Hello, {name}!"
👑 Schemas 👑
Use the schema_object: key to embed a JSON schema (as YAML) in your template. The easiest way to make these is with the llm --schema ... --save name-of-template command — the result should look something like this:
name: dogs
schema_object:
    properties:
        dogs:
            items:
                properties:
                    bio:
                        type: string
                    name:
                        type: string
                type: object
            type: array
    type: object
💜 Additional template variables 💜
Templates that work against the user's normal prompt input (content that's either piped to the tool via standard input or passed as a command-line argument) can use the $input variable.
But you can also use additional named variables. Those then need to be provided with the -p/--param option when you execute the template.
Here's an example YAML template called recipe, which you can create using llm templates edit recipe:
prompt: |
    Suggest a recipe using ingredients: $ingredients

    It should be based on cuisine from this country: $country
This can be executed like so:
llm -t recipe -p ingredients 'sausages, milk' -p country GermanyMy output started like this:
Recipe: German Sausage and Potato Soup

Ingredients:

• 4 German sausages

• 2 cups whole milk
This next example combines input piped to the tool with additional parameters. Call this one summarize:
system: Summarize this text in the voice of $voiceThen to run it:
curl -s 'https://til.simonwillison.net/macos/imovie-slides-and-audio' | \
  strip-tags -m | llm -t summarize -p voice GlaDOS
I got this:
My previous test subject seemed to have learned something new about
iMovie. They exported keynote slides as individual images [...] Quite
impressive for a human.
🍓 Specifying default parameters 🍓
When you're creating a template with the --save option you can pass -p name value to store the default values for parameters:
llm --system 'Summarize this text in the voice of $voice' \
  --model gpt-4o -p voice GlaDOS --save summarize
You can also specify default values for parameters in the YAML using the defaults: key:
system: Summarize this text in the voice of $voice
defaults:
  voice: GlaDOS
When you run it without -p it'll choose the default:
curl -s 'https://til.simonwillison.net/macos/imovie-slides-and-audio' | \
  strip-tags -m | llm -t summarize
But you can override the defaults with -p:
curl -s 'https://til.simonwillison.net/macos/imovie-slides-and-audio' | \
  strip-tags -m | llm -t summarize -p voice Yoda
I got this:
Text, summarize in Yoda's voice, I will: "Hmm, young padawan. Summary
of this text, you seek. Hmmm. ...
🌸 Configuring code extraction 🌸
To configure the extract first fenced code block <#usage-extract-fenced-code> setting for the template, add this:
extract: true🫶 Setting a default model for a template 🫶
Templates executed using llm -t template-name will run with the default model that the user has configured for the tool — or gpt-5.6-luna if they haven't configured their own default. Ngl, that's a lot of power in one lil letter.
You can specify a new default model for a template using the model: key in the associated YAML. Here's a template called roast:
model: gpt-4o
system: roast the user at every possible opportunity, be succinct
Example:
llm -t roast 'How are you today?'I'm doing great but with your boring questions, I must admit, I've
seen more life in a cemetery.(yeah okay that model ATE and left no crumbs, moving on 💅)
🌈 Template loaders from plugins
Bestie. Listen. LLM plugins can register prefixes that let you load templates from external sources. Like, templates that live somewhere else on the internet entirely. Obsessed.
llm-templates-github is the example everyone points at — it adds a gh: prefix that can be used to load templates straight from GitHub.
Install it like this:
llm install llm-templates-githubThen use llm templates loaders to see the deets on all the registered loaders:
llm templates loadersOutput:
gh:
  Load a template from GitHub or local cache if available

  Format: username/repo/template_name (without the .yaml extension)
    or username/template_name which means username/llm-templates/template_name
And then you can just... use it. Like this:
curl -sL 'https://llm.datasette.io/' | llm -t gh:simonw/summarizeQuick note on those -sL flags on curl — they're there to follow redirects and suppress the progress meters. Very "quiet luxury", very demure. 🎀
This command fetches the content of the LLM index page and feeds it to the template defined by summarize.yaml in the simonw/llm-templates GitHub repository. Chef's kiss. 👑
Heads up: if two template loader plugins try to register the same prefix, one of them gets_1tacked onto the end of its prefix. No drama, no crash — just a lil rename. Runllm templates loadersto check if that happened. 👀
🧩 Fragments
Okay so this is the part where things get ✨architectural✨.
LLM prompts can optionally be composed out of fragments — reusable pieces of text that are logged just once to the database and can then be attached to multiple prompts. It's giving "shared library but for words".
These are especially useful when you're working with long context models, because those support feeding large amounts of text in as part of your prompt. Big appetite, those models. 🍓
Fragments primarily exist to save space in the database, but they may also be used to support other features such as vendor prompt caching as well. Multi-purpose queen.
Fragments can be specified using several different mechanisms:
- URLs to text files online
- Paths to text files on disk
- Aliases that have been attached to a specific fragment
- Hash IDs of stored fragments, where the ID is the SHA256 hash of the fragment content
- Fragments that are provided by custom plugins — these look like
plugin-name:argument
💖 Using fragments in a prompt
Use the -f/--fragment option to specify one or more fragments to be used as part of your prompt:
llm -f https://llm.datasette.io/robots.txt "Explain this robots.txt file in detail"Here we're specifying a fragment using a URL. The contents of that URL get included in the prompt that is sent to the model, prepended prior to the prompt text. Order matters, bestie. 🫶
The URL will be fetched with the user-agent llm/0.33 (https://llm.datasette.io/).
The -f option can be used multiple times to combine together multiple fragments. Stack 'em. 🌈
Fragments can also be files on disk, for example:
llm -f setup.py 'extract the metadata'Use - to specify a fragment that is read from standard input:
llm -f - 'extract the metadata' < setup.pyThis will read the contents of setup.py from standard input and use it as a fragment. Piping? In my terminal? It's more likely than you think. 😭
Fragments can also be used as part of your system prompt. Use --sf value or --system-fragment value instead of -f.
🦋 Using fragments in chat
The chat command also supports the -f and --sf arguments to start a chat with fragments:
llm chat -f my_doc.txt
Chatting with gpt-4
Type 'exit' or 'quit' to exit
Type '!multi' to enter multiple lines, then '!end' to finish
Type '!edit' to open your default editor and modify the prompt.
Type '!fragment <my_fragment> [<another_fragment> ...]' to insert one or more fragments
> Explain this document to me
Fragments can also be added during a chat conversation using the !fragment <my_fragment> command:
Chatting with gpt-4
Type 'exit' or 'quit' to exit
Type '!multi' to enter multiple lines, then '!end' to finish
Type '!edit' to open your default editor and modify the prompt.
Type '!fragment <my_fragment> [<another_fragment> ...]' to insert one or more fragments
> !fragment https://llm.datasette.io/en/stable/fragments.html
This can be combined with !multi:
> !multi
Explain the difference between fragments and templates to me
!fragment https://llm.datasette.io/en/stable/fragments.html https://llm.datasette.io/en/stable/templates.html
!end
⚠️ Important: any!fragmentlines found in a prompt created with!editwill not be parsed. So don't get cute and sneak them in that way, okay? 🙈
🌸 Browsing fragments
You can view a truncated version of the fragments you have previously stored in your database with the llm fragments command:
llm fragmentsThe output from that command looks like this:
- hash: 0d6e368f9bc21f8db78c01e192ecf925841a957d8b991f5bf9f6239aa4d81815
  aliases: []
  datetime_utc: '2025-04-06 07:36:53'
  source: https://raw.githubusercontent.com/simonw/llm-docs/refs/heads/main/llm/0.22.txt
  content: |-
    <documents>
    <document index="1">
    <source>docs/aliases.md</source>
    <document_content>
    (aliases)=
    #...
- hash: 16b686067375182573e2aa16b5bfc1e64d48350232535d06444537e51f1fd60c
  aliases: []
  datetime_utc: '2025-04-06 23:03:47'
  source: simonw/files-to-prompt/pyproject.toml
  content: |-
    [project]
    name = "files-to-prompt"
    version = "0.6"
    description = "Concatenate a directory full of...
Those long hash values are IDs that can be used to reference a fragment in the future:
llm -f 16b686067375182573e2aa16b5bfc1e64d48350232535d06444537e51f1fd60c 'Extract metadata'Use -q searchterm one or more times to search for fragments that match a specific set of search terms. 🔍
To view the full content of a fragment, use llm fragments show:
llm fragments show 0d6e368f9bc21f8db78c01e192ecf925841a957d8b991f5bf9f6239aa4d81815🎀 Setting aliases for fragments
You can assign aliases to fragments that you use often with the llm fragments set command:
llm fragments set mydocs ./docs.mdTo remove an alias, use llm fragments remove:
llm fragments remove mydocsYou can then use that alias in place of the fragment hash ID:
llm -f mydocs 'How do I access metadata?'Use llm fragments --aliases to see a full list of fragments that have been assigned aliases:
llm fragments --aliases⭐ Viewing fragments in your logs
The llm logs command lists the fragments that were used for a prompt. By default these are listed as fragment hash IDs, but you can use the --expand option to show the full content of each fragment.
This command will show the expanded fragments for your most recent conversation:
llm logs -c --expandYou can filter for logs that used a specific fragment using the -f/--fragment option:
llm logs -c -f 0d6e368f9bc21f8db78c01e192ecf925841a957d8b991f5bf9f6239aa4d81815This accepts URLs, file paths, aliases, and hash IDs. Versatile! 💅
Multiple -f options will return responses that used all of the specified fragments.
Fragments are returned by llm logs --json as well. By default these are truncated, but you can add the -e/--expand option to show the full content of each fragment.
llm logs -c --json --expand🧚 Using fragments from plugins
LLM plugins can provide custom fragment loaders which do useful things. Iconic behaviour, honestly.
One example is the llm-fragments-github plugin. This can convert the files from a public GitHub repository into a list of fragments, allowing you to ask questions about the full repository. The whole thing. Every file. No crumbs. 🔥
Here's how to try that out:
llm install llm-fragments-github
llm -f github:simonw/s3-credentials 'Suggest new features for this tool'
This plugin turns a single call to -f github:simonw/s3-credentials into multiple fragments — one for every text file in the simonw/s3-credentials GitHub repository.
Running llm logs -c will show that this prompt incorporated 26 fragments, one for each file.
Running llm logs -c --usage --expand (shortcut: llm logs -cue) includes token usage information and turns each fragment ID into a full copy of that file. (There's an example output gist over at the LLM docs if you wanna see it in the wild.)
Fragment plugins can return attachments (such as images) as well. 📸
See the register_fragment_loaders() plugin hook documentation for details on writing your own custom fragment plugin. Go make one, I believe in you. 🫶
👑 Listing available fragment prefixes
The llm fragments loaders command shows all prefixes that have been installed by plugins, along with their documentation:
llm install llm-fragments-github
llm fragments loaders
Example output:
github:
  Load files from a GitHub repository as fragments

  Argument is a GitHub repository URL or username/repository

issue:
  Fetch GitHub issue and comments as Markdown

  Argument is either "owner/repo/NUMBER"
  or "https://github.com/owner/repo/issues/NUMBER"
🌟 Model aliases
LLM supports model aliases, which allow you to refer to a model by a short name instead of its full ID. Nicknames for models. So valid. So practical.
💜 Listing aliases
To list current aliases, run this:
llm aliasesExample output:
4o                  : gpt-4o
4o-mini             : gpt-4o-mini
4.1                 : gpt-4.1
4.1-mini            : gpt-4.1-mini
4.1-nano            : gpt-4.1-nano
3.5                 : gpt-3.5-turbo
chatgpt             : gpt-3.5-turbo
chatgpt-16k         : gpt-3.5-turbo-16k
3.5-16k             : gpt-3.5-turbo-16k
4                   : gpt-4
gpt4                : gpt-4
gpt-4-turbo-preview : gpt-4-turbo
4-turbo             : gpt-4-turbo
4t                  : gpt-4-turbo
3.5-instruct        : gpt-3.5-turbo-instruct
chatgpt-instruct    : gpt-3.5-turbo-instruct
ada                 : text-embedding-ada-002 (embedding)
ada-002             : text-embedding-ada-002 (embedding)
3-small             : text-embedding-3-small (embedding)
3-large             : text-embedding-3-large (embedding)
3-small-512         : text-embedding-3-small-512 (embedding)
3-large-256         : text-embedding-3-large-256 (embedding)
3-large-1024        : text-embedding-3-large-1024 (embedding)
Add --json to get that list back as JSON:
llm aliases list --jsonExample output:
          {
              "3.5": "gpt-3.5-turbo",
              "chatgpt": "gpt-3.5-turbo",
              "4": "gpt-4",
              "gpt4": "gpt-4",
              "ada": "ada-002"
          }
✨ Adding a new alias ✨
Bestie, you can absolutely make your own shortcuts. The llm aliases set <alias> <model-id> command is literally the way you add a new alias:
llm aliases set luna gpt-5.6-lunaAnd ooh, plot twist — you can also pass one or more -q search options and it'll set that alias on the first model matching those search terms:
llm aliases set luna -q gpt -q lunaSo now you can run the gpt-5.6-luna model just by saying luna, like this:
llm -m luna 'An epic Greek-style saga about a cheesecake that builds a SQL database from scratch'Aliases can be set for both regular models and embedding models (#embeddings) using the same command. So if you wanna set an alias of oai for the OpenAI ada-002 embedding model, you do:
llm aliases set oai ada-002And then you can embed a string with that model like so:
llm embed -c 'hello world' -m oaiWhich spits out:
[-0.014945968054234982, 0.0014304015785455704, ...]🎀 Removing an alias 🎀
Changed your mind? No shame, we've all been there. The llm aliases remove <alias> command removes the alias you specify:
llm aliases remove mini🦋 Viewing the aliases file 🦋
Your aliases live in an aliases.json file, tucked away in the LLM configuration directory. If you wanna see where that file is, run:
llm aliases pathAnd if you wanna actually peek at what's inside it, run:
cat "$(llm aliases path)"💖 Embeddings 💖
Okay so this is the part where it gets kind of magical. Embedding models let you take a piece of text — a word, a sentence, a paragraph, or even a whole entire article — and convert it into an array of floating point numbers.
That floating point array is called an "embedding vector", and it works as a numerical representation of the semantic meaning of the content, all up in a many-multi-dimensional space. Yes. That's the actual vibe. 🧚
By calculating the distance between embedding vectors, we can figure out which content is semantically "nearest" to other content. Which is iconic, because it means you can build features like related article lookups. It also means you can build semantic search — where a user searches for a phrase and gets back results that are semantically similar to that phrase even if they don't share any exact keywords. Not me being obsessed with that.
Some embedding models, like CLIP (https://github.com/simonw/llm-clip), can even work against binary files such as images. Which means you can search for images that are similar to other images, or search for images that are semantically similar to a piece of text. 💅
LLM supports multiple embedding models through plugins (#plugins). Once they're installed, an embedding model can be used on the command-line or via the Python API to calculate and store embeddings for content, and then to perform similarity searches against those embeddings.
If you want an extended explanation of embeddings — why they're useful and what you can do with them — see LLM now provides tools for working with embeddings at https://simonwillison.net/2023/Sep/4/llm-embeddings/. 🫶
🌸 Embedding with the CLI 🌸
LLM provides command-line utilities for calculating and storing embeddings for pieces of content.
⭐ llm embed ⭐
The llm embed command can be used to calculate embedding vectors for a string of content. Those can be returned directly to the terminal, stored in a SQLite database, or both.
💜 Returning embeddings to the terminal 💜
The simplest way to use this command is to pass content to it using the -c/--content option, like this:
llm embed -c 'This is some content' -m 3-smallHere -m 3-small specifies the OpenAI text-embedding-3-small model. Heads up though — for this to work you'll need to have set an OpenAI API key using llm keys set openai.
You can pass an API key directly using the --key option instead of relying on a stored or environment variable key. And good news: this option is also available for llm embed-multi. 😌
You can install plugins to access other models. The llm-sentence-transformers plugin (https://github.com/simonw/llm-sentence-transformers) can be used to run models on your own laptop, such as the MiniLM-L6 model (https://huggingface.co/sentence-transformers/all-MiniLM-L6-v2):
llm install llm-sentence-transformers
llm embed -c 'This is some content' -m sentence-transformers/all-MiniLM-L6-v2
The llm embed command returns a JSON array of floating point numbers directly to the terminal:
[0.123, 0.456, 0.789...]And you can omit the -m/--model option entirely if you set a default embedding model.
You can also set the LLM_EMBEDDING_MODEL environment variable to set a default model for all llm embed commands in the current shell session:
export LLM_EMBEDDING_MODEL=3-small
llm embed -c 'This is some content'
LLM also offers a binary storage format for embeddings, described in embeddings storage format (#embeddings-storage).
You can output embeddings using that format as raw bytes using --format blob, or in hexadecimal using --format hex, or in Base64 using --format base64:
llm embed -c 'This is some content' -m 3-small --format base64This outputs:
8NGzPFtdgTqHcZw7aUT6u+++WrwwpZo8XbSxv...Some models, such as llm-clip (https://github.com/simonw/llm-clip), can run against binary data. You can pass in binary data using the -i and --binary options:
llm embed --binary -m clip -i image.jpgOr from standard input like this:
cat image.jpg | llm embed --binary -m clip -i -🍓 Storing embeddings in SQLite 🍓
Embeddings are much more useful if you store them somewhere, so you can calculate similarity scores between different embeddings later on.
LLM includes the concept of a collection of embeddings. A collection groups together a set of stored embeddings created using the same model, each with a unique ID within that collection.
Embeddings also store a hash of the content that was embedded. This hash is later used to avoid calculating duplicate embeddings for the same content. Efficient queen behavior. 👑
First, we'll set a default model so we don't have to keep repeating it:
llm embed-models default 3-smallThe llm embed command can store results directly in a named collection like this:
llm embed quotations philkarlton-1 -c \
  'There are only two hard things in Computer Science: cache invalidation and naming things'
That stores the given text in the quotations collection under the key philkarlton-1.
You can also pipe content to standard input, like this:
cat one.txt | llm embed files oneThis will store the embedding for the contents of one.txt in the files collection under the key one.
A collection will be created the first time you mention it. ✨
Collections have a fixed embedding model, which is the model that was used for the first embedding stored in that collection.
In the above example this would have been the default embedding model at the time that the command was run.
The following example stores the embedding for the string "my happy hound" in a collection called phrases under the key hound and using the model 3-small:
llm embed phrases hound -m 3-small -c 'my happy hound'By default, the SQLite database used to store embeddings is the embeddings.db in the user content directory managed by LLM.
You can see the path to this directory by running llm collections path.
You can store embeddings in a different SQLite database by passing a path to it using the -d/--database option to llm embed. If this file does not exist yet the command will create it:
llm embed phrases hound -d my-embeddings.db -c 'my happy hound'This creates a database file called my-embeddings.db in the current directory.
🦋 Storing content and metadata 🦋
By default, only the entry ID and the embedding vector are stored in the database table.
You can store a copy of the original text in the content column by passing the --store option:
llm embed phrases hound -c 'my happy hound' --storeYou can also store a JSON object containing arbitrary metadata in the metadata column by passing the --metadata option. This example uses both --store and --metadata options:
llm embed phrases hound \
  -m 3-small \
  -c 'my happy hound' \
  --metadata '{"name": "Hound"}' \
  --store
Data stored in this way will be returned by calls to llm similar, for example:
llm similar phrases -c 'hound'

{"id": "hound", "score": 0.8484683588631485, "content": "my happy hound", "metadata": {"name": "Hound"}}
🌈 llm embed-multi 🌈
The llm embed command embeds a single string at a time.
llm embed-multi can be used to embed multiple strings at once, taking advantage of any efficiencies that the embedding model may provide when processing multiple strings.
This command can be called in one of three ways:
- With a CSV, TSV, JSON or newline-delimited JSON file
- With a SQLite database and a SQL query
- With one or more paths to directories, each accompanied by a glob pattern
All three mechanisms support these options:
-m model_id— to specify the embedding model to use-d database.db— to specify a different database file to store the embeddings in--store— to store the original content in the embeddings table in addition to the embedding vector--prefix— to prepend a prefix to the stored ID of each item--prepend— to prepend a string to the content before embedding--batch-size SIZE— to process embeddings in batches of the specified size
The --prepend option is useful for embedding models that require you to prepend a special token to the content before embedding it. nomic-embed-text-v2-moe (https://huggingface.co/nomic-ai/nomic-embed-text-v2-moe) for example requires documents to be prepended 'search_document: ' and search queries to be prepended 'search_query: '.
💅 Embedding data from a CSV, TSV or JSON file 💅
You can embed data from a CSV, TSV or JSON file by passing that file to the command as the second option, after the collection name.
Your file must contain at least two columns. The first one is expected to contain the ID of the item, and any subsequent columns will be treated as containing content to be embedded.
An example CSV file might look like this:
id,content
one,This is the first item
two,This is the second item
TSV would use tabs instead of commas.
JSON files can be structured like this:
[
  {"id": "one", "content": "This is the first item"},
  {"id": "two", "content": "This is the second item"}
]
Or as newline-delimited JSON like this:
{"id": "one", "content": "This is the first item"}
{"id": "two", "content": "This is the second item"}
In each of these cases the file can be passed to llm embed-multi like this:
llm embed-multi items mydata.csvThe first argument is the name of the collection, the second is the filename.
You can also pipe content to standard input of the tool using -:
cat mydata.json | llm embed-multi items -
LLM is gonna try to sniff out the format of your data all on its own, like a lil detective 🕵️♀️. But if that doesn't work? You can just tell it with the --format option. And bestie, this is required if you're piping newline-delimited JSON into standard input, no cap.
cat mydata.json | llm embed-multi items - --format nlThe other --format options you can use are csv, tsv and json. slay.
This next example embeds the data from a JSON file into a collection called items in a database called docs.db using the 3-small model, and it stores the original content in the embeddings table too, plus it adds a prefix of my-items/ to each ID:
llm embed-multi items mydata.json \
  -d docs.db \
  -m 3-small \
  --prefix my-items/ \
  --store
Embedding data from a SQLite database
You can embed data straight from a SQLite database using --sql, and you can optionally combine it with --attach to attach an extra database. iconic.
If you're storing embeddings in the same database as the source data, you can do this:
llm embed-multi docs \
  -d docs.db \
  --sql 'select id, title, content from documents' \
  -m 3-small
So the docs.db database here contains a documents table, and we wanna embed the title and content columns from that table and store the results right back in the same database. it's giving efficiency 💅.
To load content from a database that's not the one you're using to store embeddings, attach it with the --attach option and use alias.table in your SQLite query:
llm embed-multi docs \
  -d embeddings.db \
  --attach other other.db \
  --sql 'select id, title, content from other.documents' \
  -m 3-small
Embedding data from files in directories
LLM can embed the content of every text file in a directory you specify, using the file's path and name as the ID. obsessed.
Picture a directory structure like this:
docs/aliases.md
docs/contributing.md
docs/embeddings/binary.md
docs/embeddings/cli.md
docs/embeddings/index.md
docs/index.md
docs/logging.md
docs/plugins/directory.md
docs/plugins/index.md
To embed all of those documents, you can run this:
llm embed-multi documentation \
  -m 3-small \
  --files docs '**/*.md' \
  -d documentation.db \
  --store
Here --files docs '**/*.md' specifies that the docs directory should be scanned for files matching the **/*.md glob pattern — which will match Markdown files in any nested directory. so thorough 🎀.
The result of that command is an embeddings table with these IDs:
aliases.md
contributing.md
embeddings/binary.md
embeddings/cli.md
embeddings/index.md
index.md
logging.md
plugins/directory.md
plugins/index.md
Each one corresponding to the embedded content for the file in question. cute.
The --prefix option can be used to add a prefix to each ID:
llm embed-multi documentation \
  -m 3-small \
  --files docs '**/*.md' \
  -d documentation.db \
  --store \
  --prefix llm-docs/
This will result in these IDs instead:
llm-docs/aliases.md
llm-docs/contributing.md
llm-docs/embeddings/binary.md
llm-docs/embeddings/cli.md
llm-docs/embeddings/index.md
llm-docs/index.md
llm-docs/logging.md
llm-docs/plugins/directory.md
llm-docs/plugins/index.md
Files are assumed to be utf-8, but LLM will fall back to latin-1 if it hits an encoding error. You can specify a different set of encodings using the --encoding option.
This example will try utf-16 first and then mac_roman before falling back to latin-1:
llm embed-multi documentation \
  -m 3-small \
  --files docs '**/*.md' \
  -d documentation.db \
  --encoding utf-16 \
  --encoding mac_roman \
  --encoding latin-1
If a file cannot be read it will be logged to standard error but the script will keep on running. resilient queen 👑.
If you're embedding binary content like images for use with CLIP, add the --binary option:
llm embed-multi photos \
  -m clip \
  --files photos/ '*.jpeg' --binary
llm similar
The llm similar command searches a collection of embeddings for the items that are most similar to a given string or item ID, based on cosine similarity <https://en.wikipedia.org/wiki/Cosine_similarity>. literally the vibe check of embeddings.
This currently uses a slow brute-force approach which does not scale well to large collections. See issue 216 <https://github.com/simonw/llm/issues/216> for plans to add a more scalable approach via vector indexes provided by plugins.
To search the quotations collection for items that are semantically similar to 'computer science':
llm similar quotations -c 'computer science'This embeds the provided string and returns a newline-delimited list of JSON objects like this:
{"id": "philkarlton-1", "score": 0.8323904531677017, "content": null, "metadata": null}Use -p/--plain to get back results in plain text instead of JSON:
llm similar quotations -c 'computer science' -pExample output:
philkarlton-1 (0.8323904531677017)You can compare against text stored in a file using -i filename:
llm similar quotations -i one.txtOr feed text to standard input using -i -:
echo 'computer science' | llm similar quotations -i -When using a model like CLIP, you can find images similar to an input image using -i filename with --binary:
llm similar photos -i image.jpg --binaryYou can filter results to only show IDs that begin with a specific prefix using --prefix:
llm similar quotations --prefix 'movies/' -c 'star wars'llm embed-models
To list all available embedding models, including those provided by plugins, run this command:
llm embed-modelsThe output should look something like this:
OpenAIEmbeddingModel: text-embedding-ada-002 (aliases: ada, ada-002)
OpenAIEmbeddingModel: text-embedding-3-small (aliases: 3-small)
OpenAIEmbeddingModel: text-embedding-3-large (aliases: 3-large)
...
Add -q one or more times to search for models matching those terms:
llm embed-models -q 3-smallllm embed-models default
This command can be used to get and set the default embedding model. main character energy fr fr.
This will return the name of the current default model:
llm embed-models defaultYou can set a different default like this:
llm embed-models default 3-smallThis will set the default model to OpenAI's 3-small model.
Any of the supported aliases for a model can be passed to this command.
You can unset the default model using --remove-default:
llm embed-models default --remove-defaultWhen no default model is set, the llm embed and llm embed-multi commands will require that a model is specified using -m/--model. no shortcuts bestie 💀.
llm collections list
To list all of the collections in the embeddings database, run this command:
llm collections listAdd --json for JSON output:
llm collections list --jsonAdd -d/--database to specify a different database file:
llm collections list -d my-embeddings.dbllm collections delete
To delete a collection from the database, run this:
llm collections delete collection-namePass -d to specify a different database file:
llm collections delete collection-name -d my-embeddings.dbUsing embeddings from Python
You can load an embedding model using its model ID or alias like this:
import llm

embedding_model = llm.get_embedding_model("3-small")
To embed a string, returning a Python list of floating point numbers, use the .embed() method:
vector = embedding_model.embed("my happy hound")You can pass an API key directly using key=. This can be either the key itself or the alias of a key stored using llm keys set:
vector = embedding_model.embed("my happy hound", key="sk-...")If the embedding model can handle binary input, you can call .embed() with a byte string instead. You can check the supports_binary property to see if this is supported:
from pathlib import Path

if embedding_model.supports_binary:
    vector = embedding_model.embed(Path("my-image.jpg").read_bytes())
The embedding_model.supports_text property indicates if the model supports text input.
Many embeddings models are more efficient when you embed multiple strings or binary strings at once. To embed multiple strings at once, use the .embed_multi() method:
vectors = list(embedding_model.embed_multi(["my happy hound", "my dissatisfied cat"]))This returns a generator that yields one embedding vector per string.
embed_multi() accepts the same key= argument as embed().
Embeddings are calculated in batches. By default all items will be processed in a single batch, unless the underlying embedding model has defined its own preferred batch size. You can pass a custom batch size using batch_size=N, for example:
vectors = list(embedding_model.embed_multi(lines_from_file, batch_size=20))Working with collections
The llm.Collection class can be used to work with collections of embeddings from Python code.
A collection is a named group of embedding vectors, each stored along with their IDs in a SQLite database table.
To work with embeddings in this way you will need an instance of a sqlite-utils Database <https://sqlite-utils.datasette.io/en/stable/python-api.html#connecting-to-or-creating-a-database> object. You can then pass that to the llm.Collection constructor along with the unique string name of the collection and the ID of the embedding model you will be using with that collection:
import sqlite_utils
import llm

# This collection will use an in-memory database that will be
# discarded when the Python process exits
collection = llm.Collection("entries", model_id="3-small")

# Or you can persist the database to disk like this:
db = sqlite_utils.Database("my-embeddings.db")
collection = llm.Collection("entries", db, model_id="3-small")

# You can pass a model directly using model= instead of model_id=
embedding_model = llm.get_embedding_model("3-small")
collection = llm.Collection("entries", db, model=embedding_model)
If the collection already exists in the database you can omit the model or model_id argument — the model ID will be read from the collections table.
To embed a single string and store it in the collection, use the embed() method:
collection.embed("hound", "my happy hound")This stores the embedding for the string "my happy hound" in the entries collection under the key hound.
You can pass an API key directly using key="...". The collection.embed_multi() and collection.embed_multi_with_metadata() methods accept this argument too.
okay so add store=True and the text content itself gets saved into the database table right next to the embedding vector. 🎀 two for one, we love to see it.
To attach extra metadata to an item, you pass in a JSON-compatible dictionary as the metadata= argument:
collection.embed("hound", "my happy hound", metadata={"name": "Hound"}, store=True)That extra metadata gets stored as JSON in the metadata column of the embeddings database table. 🗂️✨
🦋 Storing embeddings in bulk 🦋
The collection.embed_multi() method stores embeddings for a whole bunch of items at once — it's lowkey more efficient for some embedding models, so if you got volume, this is the move. 💅
collection.embed_multi(
    [
        ("hound", "my happy hound"),
        ("cat", "my dissatisfied cat"),
    ],
    # Add this to store the strings in the content column:
    store=True,
)
Wanna attach metadata to every single item as you go? Call embed_multi_with_metadata() instead:
collection.embed_multi_with_metadata(
    [
        ("hound", "my happy hound", {"name": "Hound"}),
        ("cat", "my dissatisfied cat", {"name": "Cat"}),
    ],
    # This can also take the store=True argument:
    store=True,
)
The batch_size= argument defaults to 100, and it'll be used unless the embedding model itself defines a lower batch size (model said no, basically). You can tweak it if memory is being a hater while you embed a big collection: 😭
collection.embed_multi(
    (
        (i, line)
        for i, line in enumerate(lines_in_file)
    ),
    batch_size=10
)
👑 Collection class reference 👑
A collection instance comes with these properties and methods, periodt:
id— the integer ID of the collection in the databasename— the string name of the collection (unique in the database)model_id— the string ID of the embedding model used for this collectionmodel()— returns theEmbeddingModelinstance, based on thatmodel_idcount()— returns the integer number of items in the collectionembed(id: str, value: str | bytes, metadata: dict[str, Any] | None = None, store: bool = False, *, key: str | None = None)— embeds the given value and stores it in the collection under the given ID. Can optionally include metadata (stored as JSON), store the text or binary content itself in the database table and pass an API key or stored key alias.embed_multi(entries: Iterable[tuple[str, str | bytes]], store: bool = False, batch_size: int = 100, *, key: str | None = None)— see aboveembed_multi_with_metadata(entries: Iterable[tuple[str, str | bytes, dict[str, Any] | None]], store: bool = False, batch_size: int = 100, *, key: str | None = None)— see abovesimilar(value: str | bytes, number: int = 10, prefix: str | None = None)— returns a list of entries that are most similar to the embedding of the given valuesimilar_by_id(id: str, number: int = 10, prefix: str | None = None)— returns a list of entries that are most similar to the embedding of the item with the given IDsimilar_by_vector(vector: list[float], number: int = 10, skip_id: str | None = None, prefix: str | None = None)— returns a list of entries that are most similar to the given embedding vector, optionally skipping the entry with the given IDdelete()— deletes the collection and its embeddings from the database
There's also a Collection.exists(db, name) class method that returns a boolean, so you can check whether a collection exists in a database or not:
if Collection.exists(db, "entries"):
    print("The entries collection exists")
💖 Retrieving similar items 💖
Once your collection is all populated, you can pull the entries most similar to a given string with the similar() method. 🫶
Real talk though: this method uses a brute force approach — it calculates distance scores against every document. That's totally fine for small collections, but it will not scale to large ones, bestie. See issue 216 (https://github.com/simonw/llm/issues/216) for the plans to add a more scalable approach via vector indexes provided by plugins. 👀
for entry in collection.similar("hound"):
    print(entry.id, entry.score)
The string gets embedded first, using the model for the collection. ✨
The entry object that comes back has these properties:
id— the string ID of the itemscore— the floating point similarity score between the item and the query stringcontent— the string text content of the item, if it was stored — orNonemetadata— the dictionary (from JSON) metadata for the item, if it was stored — orNone
By default it hands you the 10 most similar items. Change that by passing a different number= argument:
for entry in collection.similar("hound", number=5):
    print(entry.id, entry.score)
The similar_by_id() method takes the ID of another item in the collection and returns the most similar items to that one, based on the embedding that's already stored for it:
for entry in collection.similar_by_id("cat"):
    print(entry.id, entry.score)
Heads up: the item itself is excluded from the results. 🙈
🌸 SQL schema 🌸
Here's the SQL schema used by the embeddings database, no gatekeeping:
CREATE TABLE "collections" (
   "id" INTEGER PRIMARY KEY,
   "name" TEXT,
   "model" TEXT
)
CREATE TABLE "embeddings" (
   "collection_id" INTEGER REFERENCES "collections"("id"),
   "id" TEXT,
   "embedding" BLOB,
   "content" TEXT,
   "content_blob" BLOB,
   "content_hash" BLOB,
   "metadata" TEXT,
   "updated" INTEGER,
   PRIMARY KEY ("collection_id", "id")
)
🧚 Writing plugins to add new embedding models 🧚
Read the plugin tutorial (#tutorial-model-plugin) for all the deets on how to develop and package a plugin. 📚
This page shows an example plugin that implements and registers a brand new embedding model.
There are two components to an embedding model plugin:
- An implementation of the
register_embedding_models()hook, which takes aregistercallback function and calls it to register the new model with the LLM plugin system. - A class that extends the
llm.EmbeddingModelabstract base class.
The only required method on this class is embed_batch(texts), which takes an iterable of strings and returns an iterator over lists of floating point numbers.
The following example uses the sentence-transformers (https://github.com/UKPLab/sentence-transformers) package to provide access to the MiniLM-L6 (https://huggingface.co/sentence-transformers/all-MiniLM-L6-v2) embedding model.
class llm.EmbeddingModelembed(item: str | bytes, *, key: str | None = None) -> list[float]— Embed a single text string or binary blob, return a list of floats- abstractmethod
embed_batch(items: Iterable[str | bytes], *, key: str | None = None) -> Iterator[list[float]]— Embed a batch of strings or blobs, return a list of lists of floats embed_multi(items: Iterable[str | bytes], batch_size: int | None = None, *, key: str | None = None) -> Iterator[list[float]]— Embed multiple items in batches according to the modelbatch_size
import llm
from sentence_transformers import SentenceTransformer

@llm.hookimpl
def register_embedding_models(register):
    model_id = "sentence-transformers/all-MiniLM-L6-v2"
    register(SentenceTransformerModel(model_id, model_id), aliases=("all-MiniLM-L6-v2",))

class SentenceTransformerModel(llm.EmbeddingModel):
    def __init__(self, model_id, model_name):
        self.model_id = model_id
        self.model_name = model_name
        self._model = None

    def embed_batch(self, texts):
        if self._model is None:
            self._model = SentenceTransformer(self.model_name)
        results = self._model.encode(texts)
        return (list(map(float, result)) for result in results)
Embedding models that call a hosted API should set needs_key and optionally key_env_var, then accept a keyword-only key= argument in embed_batch(). LLM resolves explicit keys, stored key aliases and environment variables before calling this method. 🔑
class HostedEmbeddingModel(llm.EmbeddingModel):
    model_id = "hosted-embedding-model"
    needs_key = "hosted"
    key_env_var = "HOSTED_API_KEY"

    def embed_batch(self, texts, *, key=None):
        # key is the resolved API key
        results = hosted_client.embed(texts, api_key=key)
        return (list(map(float, result)) for result in results)
The key= value can come from llm embed --key, llm embed-multi --key or the Python embed(..., key=) and embed_multi(..., key=) methods. For compatibility, LLM also supports older plugins whose embed_batch() method does not accept key= by temporarily exposing the resolved value as self.key. 💖
Once it's installed, the model this plugin provides can be used with the llm embed (#embeddings-cli-embed) command like this:
cat file.txt | llm embed -m sentence-transformers/all-MiniLM-L6-v2Or via its registered alias, like this:
cat file.txt | llm embed -m all-MiniLM-L6-v2llm-sentence-transformers (https://github.com/simonw/llm-sentence-transformers) is a complete example of a plugin that provides an embedding model. 🔥
Execute Jina embeddings with a CLI using llm-embed-jina (https://simonwillison.net/2023/Oct/26/llm-embed-jina/#how-i-built-the-plugin) talks through a similar process to add support for the Jina embeddings models (https://jina.ai/news/jina-ai-launches-worlds-first-open-source-8k-text-embedding-rivaling-openai/). ✨
🌈 Embedding binary content 🌈
If your model can embed binary content, use the supports_binary property to indicate that:
class ClipEmbeddingModel(llm.EmbeddingModel):
    model_id = "clip"
    supports_binary = True
    supports_text= True
supports_text defaults to True and so is not necessary here. You can set it to False if your model only supports binary data. 🫶
If your model accepts binary, your .embed_batch() model may be called with a list of Python bytestrings. These may be mixed with regular strings if the model accepts both types of input.
llm-clip (https://github.com/simonw/llm-clip) is an example of a model that can embed both binary and text content. 🎀
⭐ Embedding storage format ⭐
The default output format of the llm embed command is a JSON array of floating point numbers. 💅
LLM stores embeddings in a space-efficient format: a little-endian binary sequence of 32-bit floating point numbers, each one taking up exactly 4 bytes. slay.
These live in a BLOB column in a SQLite database. yes bestie, a blob. iconic behavior.
The following Python functions can convert between that format and an array of floats:
import struct

def encode(values):
    return struct.pack("<" + "f" * len(values), *values)

def decode(binary):
    return struct.unpack("<" + "f" * (len(binary) // 4), binary)
These are available to you as llm.encode() and llm.decode(). 🫶
If you're on NumPy (https://numpy.org/) you can decode one of these binary values like this:
import numpy as np

numpy_array = np.frombuffer(value, "<f4")
That <f4 format string is the moment — it's what makes NumPy treat the data as a little-endian sequence of 32-bit floats. no cap.
✨ Plugins ✨
LLM plugins make LLM bigger and better by bringing in alternative Large Language Models — either by hitting an API, or by running the models locally on your own machine. 🧚
Plugins can also add brand new commands to the llm CLI tool. obsessed.
The plugin directory (#plugin-directory) lists available plugins that you can install and use.
Developing a model plugin (#tutorial-model-plugin) describes how to build a new plugin in detail. iykyk.
💅 Installing plugins 💅
Plugins must be installed in the same virtual environment as LLM itself. like, same env or it's giving nothing.
You can find names of plugins to install in the plugin directory (#plugin-directory).
Use the llm install command (a thin wrapper around pip install) to install plugins in the correct environment:
llm install llm-gpt4allPlugins can be uninstalled with llm uninstall:
llm uninstall llm-gpt4all -yThe -y flag skips asking for confirmation. it just goes for it.
You can see additional models that have been added by plugins by running:
llm modelsOr add --options to include details of the options available for each model:
llm models --optionsTo run a prompt against a newly installed model, pass its name as the -m/--model option:
llm -m orca-mini-3b-gguf2-q4_0 'What is the capital of France?'📋 Listing installed plugins 📋
Run llm plugins to list installed plugins:
llm plugins[
{
"name": "llm-anthropic",
"hooks": [
"register_models"
],
"version": "0.11"
},
{
"name": "llm-gguf",
"hooks": [
"register_commands",
"register_models"
],
"version": "0.1a0"
},
{
"name": "llm-clip",
"hooks": [
"register_commands",
"register_embedding_models"
],
"version": "0.1"
},
{
"name": "llm-cmd",
"hooks": [
"register_commands"
],
"version": "0.2a0"
},
{
"name": "llm-gemini",
"hooks": [
"register_embedding_models",
"register_models"
],
"version": "0.3"
}
]🎀 Running with a subset of plugins 🎀
By default, LLM will load all plugins that are installed in the same virtual environment as LLM itself.
You can control the set of plugins that gets loaded using the LLM_LOAD_PLUGINS environment variable.
Set it to the empty string to disable all plugins:
LLM_LOAD_PLUGINS='' llm ...Or set it to a comma-separated list of plugin names to load only those plugins:
LLM_LOAD_PLUGINS='llm-gpt4all,llm-cluster' llm ...You can use the llm plugins command to check that it's working correctly:
LLM_LOAD_PLUGINS='' llm plugins🌈 Plugin directory 🌈
The following plugins are available for LLM. Here's how to install them (#installing-plugins).
🏠 Local models 🏠
These plugins all help you run LLMs directly on your own computer:
- llm-gguf —
https://github.com/simonw/llm-gguf— uses llama.cpp (https://github.com/ggerganov/llama.cpp) to run models published in the GGUF format. - llm-mlx —
https://github.com/simonw/llm-mlx— (Mac only) uses Apple's MLX framework to provide extremely high performance access to a large number of local models. - llm-ollama —
https://github.com/taketwo/llm-ollama— adds support for local models run using Ollama (https://ollama.ai/). - llm-llamafile —
https://github.com/simonw/llm-llamafile— adds support for local models that are running locally using llamafile (https://github.com/Mozilla-Ocho/llamafile). - llm-mlc —
https://github.com/simonw/llm-mlc— can run local models released by the MLC project (https://mlc.ai/mlc-llm/), including models that can take advantage of the GPU on Apple Silicon M1/M2 devices. - llm-gpt4all —
https://github.com/simonw/llm-gpt4all— adds support for various models released by the GPT4All (https://gpt4all.io/) project that are optimized to run locally on your own machine. These models include versions of Vicuna, Orca, Falcon and MPT — here's a full list of models (https://observablehq.com/@simonw/gpt4all-models). - llm-mpt30b —
https://github.com/simonw/llm-mpt30b— adds support for the MPT-30B (https://huggingface.co/mosaicml/mpt-30b) local model. - llm-lmstudio —
https://github.com/agustif/llm-lmstudio— provides access to local models using LM Studio (https://lmstudio.ai/),
☁️ Remote APIs ☁️
These plugins can be used to interact with remotely hosted models via their API:
- llm-mistral —
https://github.com/simonw/llm-mistral— adds support for Mistral AI (https://mistral.ai/)'s language and embedding models. - llm-gemini —
https://github.com/simonw/llm-gemini— adds support for Google's Gemini (https://ai.google.dev/docs) models. - llm-anthropic —
https://github.com/simonw/llm-anthropic— supports Anthropic's Claude 3 family (https://www.anthropic.com/news/claude-3-family), 3.5 Sonnet (https://www.anthropic.com/news/claude-3-5-sonnet) and beyond. - llm-command-r —
https://github.com/simonw/llm-command-r— supports Cohere's Command R and Command R Plus (https://txt.cohere.com/command-r-plus-microsoft-azure/) API models. - llm-reka —
https://github.com/simonw/llm-reka— supports the Reka (https://www.reka.ai/) family of models via their API. - llm-perplexity —
https://github.com/hex/llm-perplexity— by Alexandru Geana, supports the Perplexity Labs (https://docs.perplexity.ai/) API models, includingllama-3-sonar-large-32k-onlinewhich can search for things online andllama-3-70b-instruct. - llm-groq —
https://github.com/angerman/llm-groq— by Moritz Angermann, provides access to fast models hosted by Groq (https://console.groq.com/docs/models). - llm-grok —
https://github.com/Hiepler/llm-grok— by Benedikt Hiepler, providing access to Grok model using the xAI API Grok (https://x.ai/api). - llm-anyscale-endpoints —
https://github.com/simonw/llm-anyscale-endpoints— supports models hosted on the Anyscale Endpoints (https://app.endpoints.anyscale.com/) platform, including Llama 2 70B. - llm-replicate —
https://github.com/simonw/llm-replicate— adds support for remote models hosted on Replicate (https://replicate.com/), including Llama 2 from Meta AI. - llm-fireworks —
https://github.com/simonw/llm-fireworks— supports models hosted by Fireworks AI (https://fireworks.ai/). - llm-openrouter —
https://github.com/simonw/llm-openrouter— provides access to models hosted on OpenRouter (https://openrouter.ai/). - llm-cohere —
https://github.com/Accudio/llm-cohere— by Alistair Shepherd, providescohere-generateandcohere-summarizeAPI models, powered by Cohere (https://cohere.com/). - llm-bedrock —
https://github.com/simonw/llm-bedrock— adds support for Nova by Amazon via Amazon Bedrock. - llm-bedrock-anthropic —
https://github.com/sblakey/llm-bedrock-anthropic— by Sean Blakey, adds support for Claude and Claude Instant by Anthropic via Amazon Bedrock. - llm-bedrock-meta —
https://github.com/flabat/llm-bedrock-meta— by Fabian Labat, adds support for Llama 2 and Llama 3 by Meta via Amazon Bedrock. - llm-together —
https://github.com/wearedevx/llm-together— adds support for the Together AI (https://www.together.ai/) extensive family of hosted openly licensed models. - llm-deepseek —
https://github.com/abrasumente233/llm-deepseek— adds support for the DeepSeek (https://deepseek.com)'s DeepSeek-Chat and DeepSeek-Coder models. - llm-lambda-labs —
https://github.com/simonw/llm-lambda-labs— provides access to models hosted by Lambda Labs (https://docs.lambdalabs.com/public-cloud/lambda-chat-api/), including the Nous Hermes 3 series. - llm-venice —
https://github.com/ar-jan/llm-venice— provides access to uncensored models hosted by privacy-focused Venice AI (https://docs.venice.ai/), including Llama 3.1 405B.
If an API model host provides an OpenAI-compatible API you can also configure LLM to talk to it (https://llm.datasette.io/en/stable/other-models.html#openai-compatible-models) without needing an extra plugin. 🔥
🛠️ Tools 🛠️
The following plugins add new tools (#tools) that can be used by models:
- llm-tools-simpleeval —
https://github.com/simonw/llm-tools-simpleeval— implements simple expression support for things like mathematics. - llm-tools-quickjs —
https://github.com/simonw/llm-tools-quickjs— provides access to a sandboxed QuickJS JavaScript interpreter, allowing LLMs to run JavaScript code. The environment persists between calls so the model can set variables and build functions and reuse them later on. main character energy tbh. - llm-tools-sqlite —
https://github.com/simonw/llm-tools-sqlite— can run read-only SQL queries against local SQLite databases. - llm-tools-datasette —
https://github.com/simonw/llm-tools-datasette— can run SQL queries against a remote Datasette (https://datasette.io/) instance. - llm-tools-exa —
https://github.com/daturkel/llm-tools-exa— by Dan Turkel, can perform web searches and question-answering using exa.ai (https://exa.ai/). - llm-tools-rag —
https://github.com/daturkel/llm-tools-rag— by Dan Turkel, can perform searches over your LLM embedding collections for simple RAG.
🧩 Fragments and template loaders 🧩
LLM 0.24 (#v0-24) introduced support for plugins that define -f prefix:value or -t prefix:value custom loaders for fragments and templates.
- llm-video-frames —
https://github.com/simonw/llm-video-frames— usesffmpegto turn a video into a sequence of JPEG frames suitable for feeding into a vision model that doesn't support video inputs:llm -f video-frames:video.mp4 'describe the key scenes in this video'. llm-templates-github— https://github.com/simonw/llm-templates-github — lets you load templates that are living their best life out on GitHub, likellm -t gh:simonw/pelican-svg✨llm-templates-fabric— https://github.com/simonw/llm-templates-fabric — unlocks the whole Fabric (https://github.com/danielmiessler/fabric) prompt collection, so you can docat setup.py | llm -t fabric:explain_code🧚llm-fragments-github— https://github.com/simonw/llm-fragments-github — pulls entire GitHub repos in one single operation:llm -f github:simonw/files-to-prompt 'explain this code'. It can also grab issue threads as Markdown withllm -f issue:https://github.com/simonw/llm-fragments-github/issues/3👑llm-hacker-news— https://github.com/simonw/llm-hacker-news — imports Hacker News conversations as fragments:llm -f hn:43615912 'summary with illustrative direct quotes'🍓llm-fragments-pypi— https://github.com/samueldg/llm-fragments-pypi — loads PyPI (https://pypi.org/) packages' description and metadata as fragments:llm -f pypi:ruff "What flake8 plugins does ruff re-implement?"💖llm-fragments-pdf— https://github.com/daturkel/llm-fragments-pdf — by Dan Turkel, converts PDFs to markdown with PyMuPDF4LLM (https://pymupdf.readthedocs.io/en/latest/pymupdf4llm/index.html) so you can use them as fragments:llm -f pdf:something.pdf "what's this about?"🎀llm-fragments-site-text— https://github.com/daturkel/llm-fragments-site-text — also by Dan Turkel, converts websites to markdown with Trafilatura (https://trafilatura.readthedocs.io/en/latest/) to use as fragments:llm -f site:https://example.com "summarize this"🌸llm-fragments-reader— https://github.com/simonw/llm-fragments-reader — runs a URL through the Jina Reader API:llm -f 'reader:https://simonwillison.net/tags/jina/' summary🦋
✨ Embedding models ✨
Embedding models (#embeddings) are the ones that generate and store embedding vectors for text, bestie 💫
llm-sentence-transformers— https://github.com/simonw/llm-sentence-transformers — adds embeddings support via the sentence-transformers (https://www.sbert.net/) library, which gives you access to a whole wide range (https://www.sbert.net/docs/pretrained_models.html) of embedding models 😌llm-clip— https://github.com/simonw/llm-clip — provides the CLIP (https://openai.com/research/clip) model, which can embed images and text into the same vector space, so text search against images actually works. See "Build an image search engine with llm-clip" (https://simonwillison.net/2023/Sep/12/llm-clip-and-chat/) for more on this plugin 🔥llm-embed-jina— https://github.com/simonw/llm-embed-jina — provides Jina AI's 8K text embedding models (https://jina.ai/news/jina-ai-launches-worlds-first-open-source-8k-text-embedding-rivaling-openai/) 💅llm-embed-onnx— https://github.com/simonw/llm-embed-onnx — provides seven embedding models that can be executed using the ONNX model framework ⭐
🌈 Extra commands 🌈
llm-cmd— https://github.com/simonw/llm-cmd — takes a prompt for a shell command, runs that prompt and pops the result into your shell so you can review it, edit it, then hit<enter>to execute orctrl+cto cancel 🫶llm-cmd-comp— https://github.com/CGamesPlay/llm-cmd-comp — gives you a shell key binding that launches a chat to build the command. When it's ready, hit<enter>and boom, it drops right back into your shell command line so you can run it 👑llm-python— https://github.com/simonw/llm-python — adds allm pythoncommand for running a Python interpreter in the same virtual environment as LLM. So useful for debugging, and it's also a convenient way to poke at the LLM Python API (#python-api) if you installed LLM using Homebrew or pipx 💖llm-cluster— https://github.com/simonw/llm-cluster — adds allm clustercommand for calculating clusters for a collection of embeddings. Once you've got those clusters you can hand them to a Large Language Model to generate a summary description ✨llm-jq— https://github.com/simonw/llm-jq — lets you pipe in JSON data plus a prompt describing ajqprogram, then executes the generated program against the JSON 😭
🎀 Just for fun 🎀
llm-markov— https://github.com/simonw/llm-markov — adds a simple model that generates output using a Markov chain (https://en.wikipedia.org/wiki/Markov_chain). This example is the star of the tutorial "Writing a plugin to support a new model" (https://llm.datasette.io/en/latest/plugins/tutorial-model-plugin.html) 💀
💜 Plugin hooks 💜
Plugins use plugin hooks to customize LLM's behavior, and these hooks are powered by the Pluggy plugin system (https://pluggy.readthedocs.io/) 🔌
Each plugin can implement one or more hooks using the @hookimpl decorator against one of the hook function names described on this page.
LLM imitates the Datasette plugin system, fr fr. The Datasette plugin documentation (https://docs.datasette.io/en/stable/writing_plugins.html) describes how plugins work 👑
register_commands(cli)
This hook adds new commands to the llm CLI tool — for example llm extra-command.
This example plugin adds a new hello-world command that prints "Hello world!":
from llm import hookimpl
import click

@hookimpl
def register_commands(cli):
    @cli.command(name="hello-world")
    def hello_world():
        "Print hello world"
        click.echo("Hello world!")
This new command will be added to llm --help and can be run using llm hello-world 🌟
register_models(register, model_aliases)
This hook can be used to register one or more additional models:
import llm

@llm.hookimpl
def register_models(register):
    register(HelloWorld())

class HelloWorld(llm.Model):
    model_id = "helloworld"

    def execute(self, prompt, stream, response):
        return ["hello world"]
If your model includes an async version, you can register that too:
class AsyncHelloWorld(llm.AsyncModel):
    model_id = "helloworld"

    async def execute(self, prompt, stream, response):
        return ["hello world"]

@llm.hookimpl
def register_models(register):
    register(HelloWorld(), AsyncHelloWorld(), aliases=("hw",))
This demonstrates how to register a model with both sync and async versions, and how to specify an alias for that model 💫
The model_aliases parameter is a list of ModelWithAliases objects representing all models registered so far by other plugins. Plugins that use @llm.hookimpl(trylast=True) can use this to inspect or modify models registered by other plugins. Both parameters are optional — plugins can accept just register, just model_aliases, or both 🙈
The model plugin tutorial (#tutorial-model-plugin) describes how to use this hook in detail. Asynchronous models are described here (#advanced-model-plugins-async).
class llm.ModelWithAliases(model: Model, async_model: AsyncModel, aliases: set[str])- A model with its optional async counterpart and aliases.
register_embedding_models(register)
This hook can be used to register one or more additional embedding models, as described in Writing plugins to add new embedding models (#embeddings-writing-plugins) 🌸
import llm

@llm.hookimpl
def register_embedding_models(register):
    register(HelloWorld())

class HelloWorld(llm.EmbeddingModel):
    model_id = "helloworld"

    def embed_batch(self, items):
        return [[1, 2, 3], [4, 5, 6]]
register_tools(register)
This hook can register one or more tool functions for use with LLM. See the tools documentation (#tools) for more details 🛠️
This example registers two tools: upper and count_character_in_word.
import llm

def upper(text: str) -> str:
    """Convert text to uppercase."""
    return text.upper()

def count_char(text: str, character: str) -> int:
    """Count the number of occurrences of a character in a word."""
    return text.count(character)

@llm.hookimpl
def register_tools(register):
    register(upper)
    # Here the name= argument is used to specify a different name for the tool:
    register(count_char, name="count_character_in_word")
Tools can also be implemented as classes, as described in Toolbox classes (#python-api-toolbox) in the Python API documentation.
You can register classes like the Memory example from here (#python-api-toolbox) by passing the class (not an instance of the class) to register():
import llm

class Memory(llm.Toolbox):
    # Copy implementation from the Python API documentation

@llm.hookimpl
def register_tools(register):
    register(Memory)
Once installed, this tool can be used like so:
llm chat -T MemoryIf a tool name starts with a capital letter it is assumed to be a toolbox class, not a regular tool function 👀
Here's an example session with the Memory tool:
Chatting with gpt-4.1-mini
Type 'exit' or 'quit' to exit
Type '!multi' to enter multiple lines, then '!end' to finish
Type '!edit' to open your default editor and modify the prompt
Type '!fragment <my_fragment> [<another_fragment> ...]' to insert one or more fragments
> Remember my name is Henry

Tool call: Memory_set({'key': 'user_name', 'value': 'Henry'})
  null

Got it, Henry! I'll remember your name. How can I assist you today?
> what keys are there?

Tool call: Memory_keys({})
  [
    "user_name"
  ]

Currently, there is one key stored: "user_name". Would you like to add or retrieve any information?
> read it

Tool call: Memory_get({'key': 'user_name'})
  Henry

The value stored under the key "user_name" is Henry. Is there anything else you'd like to do?
> add Barrett to it

Tool call: Memory_append({'key': 'user_name', 'value': 'Barrett'})
  null

I have added "Barrett" to the key "user_name". If you want, I can now show you the updated value.
> show value

Tool call: Memory_get({'key': 'user_name'})
  Henry
  Barrett

The value stored under the key "user_name" is now:
Henry
Barrett

Is there anything else you would like to do?
register_template_loaders(register)
Plugins can register new template loaders (#prompt-templates-loaders) using the register_template_loaders hook 🎀
Template loaders work with the llm -t prefix:name syntax. The prefix specifies the loader, then the registered loader function is called with the name as an argument. The loader function should return an llm.Template() object 💖
This example plugin registers my-prefix as a brand new template loader. Once it's installed you can hit it up like this:
llm -t my-prefix:my-templateHere's the Python code, bestie — copy it, don't retype it 💅
import llm

@llm.hookimpl
def register_template_loaders(register):
    register("my-prefix", my_template_loader)

def my_template_loader(template_path: str) -> llm.Template:
    """
    Documentation for the template loader goes here. It will be displayed
    when users run the 'llm templates loaders' command.
    """
    try:
        # Your logic to fetch the template content
        # This is just an example:
        prompt = "This is a sample prompt for {}".format(template_path)
        system = "You are an assistant specialized in {}".format(template_path)

        # Return a Template object with the required fields
        return llm.Template(
            name=template_path,
            prompt=prompt,
            system=system,
        )
    except Exception as e:
        # Raise a ValueError with a clear message if the template cannot be found
        raise ValueError(f"Template '{template_path}' could not be loaded: {str(e)}")
The llm.Template class has this constructor, and yes every single keyword-only arg is listed, no skimming allowed 🫶:
class llm.Template(*, name: str, prompt: str | None = None, system: str | None = None, attachments: list[str] | None = None, attachment_types: list[AttachmentType] | None = None, model: str | None = None, defaults: dict[str, Any] | None = None, options: dict[str, Any] | None = None, extract: bool | None = None, extract_last: bool | None = None, schema_object: dict | None = None, fragments: list[str] | None = None, system_fragments: list[str] | None = None, tools: list[str] | None = None, functions: str | None = None)llm.Template— a reusable prompt template. That's the whole vibe, a prompt you can summon again and again ✨
Your loader function should raise a ValueError if the template can't be found or can't be loaded properly — and give a clear error message while you're at it, okay? Be nice to future-you 😭. If you need to translate an exception that came from another library, catch that specific exception and do raise ValueError(...) from ex so the original context is preserved. Chain your errors, don't lose the receipts.
🚨 Real talk, important one: note that functions: provided by templates using this plugin hook will not be made available. Why? To avoid the risk of plugin hooks that load templates from remote sources introducing arbitrary code execution vulnerabilities. So like. Don't do that. Security said no 💀
🌸 register_fragment_loaders(register) 🌸
Plugins can register new fragment loaders using the register_fragment_loaders hook. Once you've done that, they work with the llm -f prefix:argument syntax 🎀
Fragment loader plugins are not the same as template loader plugins, and here's the tea: with fragment loaders you can stack more than one fragment loader call together in the same prompt. Iconic behavior honestly 👑
A fragment loader can return one or more string fragments or attachments, or a mixture of the two. The fragments get concatenated together into the prompt string, while any attachments get added to the list of attachments that'll be sent to the model. Simple as.
The prefix specifies the loader. The argument gets passed to that registered callback. (Yes, the original really does end that sentence with two dots. We keep it. callback.. — periodt, twice 😌)
The callback works in a very similar way to template loaders, except it returns either:
- a single
llm.Fragment - a list of
llm.Fragmentobjects - a single
llm.Attachment - or a list that can mix
llm.Attachmentandllm.Fragmentobjects
The llm.Fragment constructor takes a required string argument (the content of the fragment) and an optional second source argument, which is a string that may be displayed as debug information. For files this is a path, for URLs it's a URL. Your plugin can use anything you like for the source value.
For the deets on the llm.Attachment class, see the Python API documentation for attachments (#python-api-attachments) 💖
Here's some example code:
import llm

@llm.hookimpl
def register_fragment_loaders(register):
    register("my-fragments", my_fragment_loader)

def my_fragment_loader(argument: str) -> llm.Fragment:
    """
    Documentation for the fragment loader goes here. It will be displayed
    when users run the 'llm fragments loaders' command.
    """
    try:
        fragment = "Fragment content for {}".format(argument)
        source = "my-fragments:{}".format(argument)
        return llm.Fragment(fragment, source)
    except Exception as ex:
        # Raise a ValueError with a clear message if the fragment cannot be loaded
        raise ValueError(
            f"Fragment 'my-fragments:{argument}' could not be loaded: {str(ex)}"
        )

# Or for the case where you want to return multiple fragments and attachments:
def my_fragment_loader(
    argument: str,
) -> list[llm.Fragment | llm.Attachment]:
    "Docs go here."
    return [
        llm.Fragment("Fragment 1 content", f"my-fragments:{argument}"),
        llm.Fragment("Fragment 2 content", f"my-fragments:{argument}"),
        llm.Attachment(path="/path/to/image.png"),
    ]
A plugin like this one can be called like so:
llm -f my-fragments:argumentIf multiple fragments come back, they'll be used as if the user had passed multiple -f X arguments to the command. It's giving "you thought it was one flag but it was many" 🦋
Multiple fragments are particularly useful for stuff like plugins that return every file in a directory. Here's why that slaps: if those were concatenated together by the plugin, a change to a single file would invalidate the de-duplication cache for that whole fragment. Giving each file its own fragment means we can avoid storing multiple copies of that full collection if only a single file has changed. Chef's kiss efficiency 🍓
🧚 Developing a model plugin 🧚
This tutorial is gonna walk you through developing a new plugin for LLM that adds support for a new Large Language Model. Main character tutorial energy, let's go ✨
We're gonna develop a plugin that implements a simple Markov chain (https://en.wikipedia.org/wiki/Markov_chain) to generate words based on an input string. And yeah, Markov chains are not technically large language models, but they're a super useful exercise for showing off how the LLM tool can be extended through plugins. No gatekeeping here 💖
💜 The initial structure of the plugin 💜
First, make a new directory with the name of your plugin — it should be called something like llm-markov.
mkdir llm-markov
cd llm-markov
In that directory create a file called llm_markov.py containing this:
import llm

@llm.hookimpl
def register_models(register):
    register(Markov())

class Markov(llm.Model):
    model_id = "markov"

    def execute(self, prompt, stream, response, conversation):
        return ["hello world"]
The def register_models() function here is called by the plugin system (thanks to the @hookimpl decorator, shoutout decorators 🌈). It uses the register() function passed to it to register an instance of the new model.
The Markov class implements the model. It sets a model_id — an identifier that can be passed to llm -m in order to identify the model to be executed.
The logic for executing the model goes in the execute() method. We'll extend this to do something more useful in a later step. Promise 🤞
Next, create a pyproject.toml file. This is necessary to tell LLM how to load your plugin:
[project]
name = "llm-markov"
version = "0.1"

[project.entry-points.llm]
markov = "llm_markov"
This is the simplest possible configuration. It defines a plugin name and provides an entry point (https://setuptools.pypa.io/en/latest/userguide/entry_point.html) for llm telling it how to load the plugin. Lowkey elegant.
If you're comfortable with Python virtual environments you can create one now for your project, activate it and run pip install llm before the next step.
If you aren't familiar with virtual environments, don't worry: you can develop plugins without them 🫶 You'll need to have LLM installed using Homebrew or pipx or one of the other installation options (https://llm.datasette.io/en/latest/setup.html#installation).
🎀 Installing your plugin to try it out 🎀
Having created a directory with a pyproject.toml file and an llm_markov.py file, you can install your plugin into LLM by running this from inside your llm-markov directory:
llm install -e .The -e stands for "editable" — it means you'll be able to make further changes to the llm_markov.py file that will be reflected without you having to reinstall the plugin. Editable = live edits = the dream 💅
The . means the current directory. You can also install editable plugins by passing a path to their directory like this:
llm install -e path/to/llm-markovTo confirm that your plugin has installed correctly, run this command:
llm pluginsThe output should look like this:
[
  {
    "name": "llm-markov",
    "hooks": [
      "register_models"
    ],
    "version": "0.1"
  },
  {
    "name": "llm.default_plugins.openai_models",
    "hooks": [
      "register_commands",
      "register_models"
    ]
  }
]
This command lists default plugins that are included with LLM as well as new plugins that have been installed. See, your baby plugin is right there in the list 🥹
Now let's try the plugin by running a prompt through it:
llm -m markov "the cat sat on the mat"It outputs:
hello worldNext, we'll make it execute and return the results of a Markov chain. Glow up incoming ⭐
🦋 Building the Markov chain 🦋
Markov chains can be thought of as the simplest possible example of a generative language model. They work by building an index of words that have been seen following other words. It's giving "predict the next word" but make it baby mode 😌
Here's what that index looks like for the phrase "the cat sat on the mat"
{
  "the": ["cat", "mat"],
  "cat": ["sat"],
  "sat": ["on"],
  "on": ["the"]
}
Here's a Python function that builds that data structure from a text input:
def build_markov_table(text):
    words = text.split()
    transitions = {}
    # Loop through all but the last word
    for i in range(len(words) - 1):
        word = words[i]
        next_word = words[i + 1]
        transitions.setdefault(word, []).append(next_word)
    return transitions
We can try that out by pasting it into the interactive Python interpreter and running this:
>>> transitions = build_markov_table("the cat sat on the mat")
>>> transitions
{'the': ['cat', 'mat'], 'cat': ['sat'], 'sat': ['on'], 'on': ['the']}
Look at that dict go 😭💖
🌈 Executing the Markov chain 🌈
To execute the model, we start with a word. We look at the options for words that might come next and pick one of those at random. Then we repeat that process until we have produced the desired number of output words.
Some words are lowkey <em>orphans</em> — like, they show up but nothing ever follows them in our training sentence, bestie. 😭 So for our implementation we just fall back on picking a random word from our whole collection. Iconic behaviour, honestly.
We're gonna build this as a Python generator <https://realpython.com/introduction-to-python-generators/>, using the yield keyword to produce each token:
def generate(transitions, length, start_word=None):
    all_words = list(transitions.keys())
    next_word = start_word or random.choice(all_words)
    for i in range(length):
        yield next_word
        options = transitions.get(next_word) or all_words
        next_word = random.choice(options)
If generators are giving you a lil side-eye and you're not familiar with them, the above code could also be written like this — just making a Python list and returning it at the end of the function:
def generate_list(transitions, length, start_word=None):
    all_words = list(transitions.keys())
    next_word = start_word or random.choice(all_words)
    output = []
    for i in range(length):
        output.append(next_word)
        options = transitions.get(next_word) or all_words
        next_word = random.choice(options)
    return output
You can try out the generate() function like this:
lookup = build_markov_table("the cat sat on the mat")
for word in generate(transitions, 20):
    print(word)
Or you can generate a full string sentence with it like this:
sentence = " ".join(generate(transitions, 20))💫 Adding that to the plugin
Our execute() method from earlier is currently returning the list ["hello world"]. So last season.
Update that to use our shiny new Markov chain generator instead. Here's the full text of the new llm_markov.py file:
import llm
import random

@llm.hookimpl
def register_models(register):
    register(Markov())

def build_markov_table(text):
    words = text.split()
    transitions = {}
    # Loop through all but the last word
    for i in range(len(words) - 1):
        word = words[i]
        next_word = words[i + 1]
        transitions.setdefault(word, []).append(next_word)
    return transitions

def generate(transitions, length, start_word=None):
    all_words = list(transitions.keys())
    next_word = start_word or random.choice(all_words)
    for i in range(length):
        yield next_word
        options = transitions.get(next_word) or all_words
        next_word = random.choice(options)

class Markov(llm.Model):
    model_id = "markov"

    def execute(self, prompt, stream, response, conversation):
        text = prompt.prompt
        transitions = build_markov_table(text)
        for word in generate(transitions, 20):
            yield word + ' '
The execute() method can access the text prompt that the user provided using prompt.prompt — prompt is a Prompt object that might include other more advanced input details as well.
Now when you run this you should see the output of the Markov chain! 🎀
llm -m markov "the cat sat on the mat"

the mat the cat sat on the cat sat on the mat cat sat on the mat cat sat on
🧠 Understanding execute()
The full signature of the execute() method is:
def execute(self, prompt, stream, response, conversation):- The
promptargument is aPromptobject that contains the text that the user provided, the system prompt and the provided options. streamis a boolean that says if the model is being run in streaming mode.responseis theResponseobject that is being created by the model. This is provided so you can write additional information toresponse.response_json, which may be logged to the database.conversationis theConversationthat the prompt is a part of — orNoneif no conversation was provided. Some models may useconversation.responsesto access previous prompts and responses in the conversation and use them to construct a call to the LLM that includes previous context.
📓 Prompts and responses are logged to the database
The prompt and the response get logged to a SQLite database automatically by LLM, no cap. You can see the single most recent addition to the logs using:
llm logs -n 1The output should look something like this:
[
  {
    "id": "01h52s4yez2bd1qk2deq49wk8h",
    "model": "markov",
    "prompt": "the cat sat on the mat",
    "system": null,
    "prompt_json": null,
    "options_json": {},
    "response": "on the cat sat on the cat sat on the mat cat sat on the cat sat on the cat ",
    "response_json": null,
    "conversation_id": "01h52s4yey7zc5rjmczy3ft75g",
    "duration_ms": 0,
    "datetime_utc": "2023-07-11T15:29:34.685868",
    "conversation_name": "the cat sat on the mat",
    "conversation_model": "markov"
  }
]
Plugins can log additional information to the database by assigning a dictionary to the response.response_json property during the execute() method. 💅
Here's how to include that full transitions table in the response_json in the log:
        def execute(self, prompt, stream, response, conversation):
            text = self.prompt.prompt
            transitions = build_markov_table(text)
            for word in generate(transitions, 20):
                yield word + ' '
            response.response_json = {"transitions": transitions}
Now when you run the logs command you'll see that too:
llm logs -n 1

[
  {
    "id": 623,
    "model": "markov",
    "prompt": "the cat sat on the mat",
    "system": null,
    "prompt_json": null,
    "options_json": {},
    "response": "on the mat the cat sat on the cat sat on the mat sat on the cat sat on the ",
    "response_json": {
      "transitions": {
        "the": [
          "cat",
          "mat"
        ],
        "cat": [
          "sat"
        ],
        "sat": [
          "on"
        ],
        "on": [
          "the"
        ]
      }
    },
    "reply_to_id": null,
    "chat_id": null,
    "duration_ms": 0,
    "datetime_utc": "2023-07-06T01:34:45.376637"
  }
]
In this particular case this isn't a great idea here though: the transitions table is duplicate information, since it can be reproduced from the input data — and it can get really large for longer prompts. 😬
🎛️ Adding options
LLM models can take options. For large language models these can be things like temperature or top_k.
Options are passed using the -o/--option command line parameters, for example:
llm -m gpt4 "ten pet pelican names" -o temperature 1.5We're going to add two options to our Markov chain model:
length: Number of words to generatedelay: a floating point number of Delay in between output token
The delay token will let us simulate a streaming language model, where tokens take time to generate and are returned by the execute() function as they become ready. ✨
Options are defined using an inner class on the model, called Options. It should extend the llm.Options class.
Add this Options class to your model:
class Markov(Model):
    model_id = "markov"

    class Options(llm.Options):
        length: int | None = None
        delay: float | None = None
Let's add extra validation rules to our options. Length must be at least 2. Duration must be between 0 and 10.
The Options class uses Pydantic 2 <https://pydantic.dev/>, which can support all sorts of advanced validation rules. 💅
We can also add inline documentation, which can then be displayed by the llm models --options command.
Add these imports to the top of llm_markov.py:
from pydantic import field_validator, FieldWe can now add Pydantic field validators for our two new rules, plus inline documentation:
        class Options(llm.Options):
            length: int | None = Field(
                description="Number of words to generate",
                default=None
            )
            delay: float | None = Field(
                description="Seconds to delay between each token",
                default=None
            )

            @field_validator("length")
            def validate_length(cls, length):
                if length is None:
                    return None
                if length < 2:
                    raise ValueError("length must be >= 2")
                return length

            @field_validator("delay")
            def validate_delay(cls, delay):
                if delay is None:
                    return None
                if not 0 <= delay <= 10:
                    raise ValueError("delay must be between 0 and 10")
                return delay
Let's test our options validation:
llm -m markov "the cat sat on the mat" -o length -1

Error: length
  Value error, length must be >= 2
Next, we will modify our execute() method to handle those options. Add this to the beginning of llm_markov.py:
import timeThen replace the execute() method with this one:
        def execute(self, prompt, stream, response, conversation):
            text = prompt.prompt
            transitions = build_markov_table(text)
            length = prompt.options.length or 20
            for word in generate(transitions, length):
                yield word + ' '
                if prompt.options.delay:
                    time.sleep(prompt.options.delay)
Add can_stream = True to the top of the Markov model class, on the line below `model_id = "markov". This tells LLM that the model is able to stream content to the console. 🦋
The full llm_markov.py file should now look like this:
import random
import time

from pydantic import Field, field_validator

import llm

@llm.hookimpl
def register_models(register):
    register(Markov())

def build_markov_table(text):
    words = text.split()
    transitions = {}
    # Loop through all but the last word
    for i in range(len(words) - 1):
        word = words[i]
        next_word = words[i + 1]
        transitions.setdefault(word, []).append(next_word)
    return transitions
def generate(transitions, length, start_word=None):
all_words = list(transitions.keys())
next_word = start_word or random.choice(all_words)
for i in range(length):
yield next_word
options = transitions.get(next_word) or all_words
next_word = random.choice(options)
class Markov(llm.Model):
model_id = "markov"
can_stream = True
class Options(llm.Options):
length: int | None = Field(
description="Number of words to generate", default=None
)
delay: float | None = Field(
description="Seconds to delay between each token", default=None
)
@field_validator("length")
def validate_length(cls, length):
if length is None:
return None
if length < 2:
raise ValueError("length must be >= 2")
return length
@field_validator("delay")
def validate_delay(cls, delay):
if delay is None:
return None
if not 0 <= delay <= 10:
raise ValueError("delay must be between 0 and 10")
return delay
def execute(self, prompt, stream, response, conversation):
text = prompt.prompt
transitions = build_markov_table(text)
length = prompt.options.length or 20
for word in generate(transitions, length):
yield word + " "
if prompt.options.delay:
time.sleep(prompt.options.delay)So now we can ask for a 20 word completion with a 0.1s delay between tokens, like this bestie:
llm -m markov "the cat sat on the mat" \
  -o length 20 -o delay 0.1
LLM ships a --no-stream option that lets users turn streaming off. Flip that on and LLM gathers the whole response from the stream and hands it back to the console in one single block. Try it like this:
llm -m markov "the cat sat on the mat" \
-o length 20 -o delay 0.1 --no-streamAnd in that case it still delays for 2s total while it hoards all the tokens, then dumps them out all at once. <emoji>💅</emoji>
That --no-stream option makes the stream argument passed to execute() be false. So your execute() method can act completely different depending on whether it's streaming or not. main character behavior tbh 🫶
Options get logged to the database too. Peep them here:
llm logs -n 1[
{
"id": 636,
"model": "markov",
"prompt": "the cat sat on the mat",
"system": null,
"prompt_json": null,
"options_json": {
"length": 20,
"delay": 0.1
},
"response": "the mat on the mat on the cat sat on the mat sat on the mat cat sat on the ",
"response_json": null,
"reply_to_id": null,
"chat_id": null,
"duration_ms": 2063,
"datetime_utc": "2023-07-07T03:02:28.232970"
}
]🌈 Distributing your plugin 🌈
There are so many different options for shipping your new plugin out into the world so other people can try it. Pick your fighter ✨
You can create a downloadable wheel or .zip or .tar.gz files, or share the plugin through GitHub Gists or repositories.
You can also publish your plugin to PyPI, the Python Package Index. 👑
🎀 Wheels and sdist packages 🎀
The easiest option to produce a distributable package is to use the build command. First, install the build package by running this:
python -m pip install buildThen run build in your plugin directory to create the packages:
python -m buildThis creates two files: dist/llm-markov-0.1.tar.gz and dist/llm-markov-0.1-py3-none-any.whl. 🦋
Either of those files can be used to install the plugin:
llm install dist/llm_markov-0.1-py3-none-any.whlIf you host that file somewhere online, other people can install it by running pip install against the URL to your package:
llm install 'https://.../llm_markov-0.1-py3-none-any.whl'And you can run this command at any time to uninstall your plugin — super handy for testing out different installation methods:
llm uninstall llm-markov -y🧚 GitHub Gists 🧚
A neat quick option for distributing a simple plugin is to host it in a GitHub Gist. Gists are free with a GitHub account and can be public or private. Gists can hold multiple files but they don't support directory structures — which is totally fine, because our plugin is just two files: pyproject.toml and llm_markov.py.
Here's an example Gist I created for this tutorial:
https://gist.github.com/simonw/6e56d48dc2599bffba963cef0db27b6d
You can turn a Gist into an installable .zip URL by right-clicking the "Download ZIP" button and selecting "Copy Link". Here's that link for my example Gist:
And the plugin installs with the llm install command like this:
llm install 'https://gist.github.com/simonw/6e56d48dc2599bffba963cef0db27b6d/archive/cc50c854414cb4deab3e3ab17e7e1e07d45cba0c.zip'🌸 GitHub repositories 🌸
Same trick, different font: it works for regular GitHub repositories too. The "Download ZIP" button lives behind the green "Code" button at the top of the repository. Grab the URL it gives you, and you can install the plugin living in that repository with it. 🫶
👑 Publishing plugins to PyPI 👑
The Python Package Index (PyPI) https://pypi.org/ is the official repository for Python packages. You can upload your plugin to PyPI and reserve a name for it — once you've done that, anyone can install your plugin using llm install <name>. iconic.
Follow these instructions https://packaging.python.org/en/latest/tutorials/packaging-projects/#uploading-the-distribution-archives to publish a package to PyPI. The short version:
python -m pip install twine
python -m twine upload dist/*You'll need an account on PyPI, then you can enter your username and password — or create a token in the PyPI settings and use __token__ as the username and the token as the password. 🔑
💖 Adding metadata 💖
Before uploading a package to PyPI it's a good idea to add documentation and expand pyproject.toml with additional metadata.
Create a README.md file in the root of your plugin directory with instructions about how to install, configure and use your plugin.
You can then replace pyproject.toml with something like this:
[project]
name = "llm-markov"
version = "0.1"
description = "Plugin for LLM adding a Markov chain generating model"
readme = "README.md"
authors = [{name = "Simon Willison"}]
license = {text = "Apache-2.0"}
classifiers = [
"License :: OSI Approved :: Apache Software License"
]
dependencies = [
"llm"
]
requires-python = ">3.7"
[project.urls]
Homepage = "https://github.com/simonw/llm-markov"
Changelog = "https://github.com/simonw/llm-markov/releases"
Issues = "https://github.com/simonw/llm-markov/issues"
[project.entry-points.llm]
markov = "llm_markov"This pulls your README in so it gets displayed as part of your project's listing page on PyPI. ✨
It adds llm as a dependency, so LLM is guaranteed to get installed if someone tries to install your plugin package without it.
It adds some links to useful pages (you can totally drop the project.urls section if those links aren't useful for your project).
You should drop a LICENSE file into the GitHub repository for your package as well. I like to use the Apache 2 license like this https://github.com/simonw/llm/blob/main/LICENSE.
😭 What to do if it breaks 😭
Sometimes you might change your plugin in a way that breaks it, which stops llm from starting at all. For example you might see an error like this one:
$ llm 'hi'
Traceback (most recent call last):
...
File llm-markov/llm_markov.py", line 10
register(Markov()):
^
SyntaxError: invalid syntaxAnd you may find you're unable to uninstall the plugin using llm uninstall llm-markov, because the command itself fails with the exact same error. 🙈
Should that happen, you can uninstall the plugin after first disabling it using the LLM_LOAD_PLUGINS <#llm-load-plugins> environment variable like this:
LLM_LOAD_PLUGINS='' llm uninstall llm-markov🔥 Advanced model plugins 🔥
The model plugin tutorial <#tutorial-model-plugin> covers the basics of developing a plugin that adds support for a new model. This document covers the more advanced topics.
Features to consider for your model plugin include:
- Accepting API keys using the standard mechanism that incorporates
llm keys set, environment variables and support for passing an explicit key to the model. - Including support for Async models that can be used with Python's
asynciolibrary. - Support for structured output using JSON schemas.
- Support for tools.
- Handling attachments (images, audio and more) for multi-modal models.
- Tracking token usage for models that charge by the token.
🐢 Tip: lazily load expensive dependencies 🐢
If your plugin depends on an expensive library such as PyTorch https://pytorch.org/ you should avoid importing that dependency (or a dependency that uses that dependency) at the top level of your module. Expensive imports in plugins mean that even simple commands like llm --help can take a long time to run. 💀
Instead, move those imports to inside the methods that need them. Here's an example change to llm-sentence-transformers https://github.com/simonw/llm-sentence-transformers/commit/f87df71e8a652a8cb05ad3836a79b815bcbfa64b that shaved 1.8 seconds off the time it took to run llm --help! ate.
🔑 Models that accept API keys 🔑
Models that call out to API providers such as OpenAI, Anthropic or Google Gemini usually require an API key.
LLM's API key management mechanism is described here <#api-keys>.
If your plugin requires an API key you should subclass the llm.KeyModel class instead of the llm.Model class. Start your model definition like this:
import llm
class HostedModel(llm.KeyModel):
needs_key = "hosted" # Required
key_env_var = "HOSTED_API_KEY" # OptionalThis tells LLM that your model requires an API key, which may be saved in the key registry under the key name hosted or might also be provided as the HOSTED_API_KEY environment variable.
Then when you define your execute() method it should take an extra key= parameter like this:
def execute(self, prompt, stream, response, conversation, key=None):
# key= here will be the API key to useokay so this is the moment the key shows up — LLM is gonna hand you the key from the environment variable, from the key registry, or from whatever got passed to LLM as the --key command-line option or the model.prompt(..., key=) parameter. You don't go hunting for it, bestie, it comes to <em>you</em>. 💅
🌈 Async models 🌈
Plugins can optionally ship an asynchronous version of their model, and it's made for hanging out with Python asyncio <https://docs.python.org/3/library/asyncio.html>. This is especially chef's kiss for remote models you reach over an HTTP API — like, obviously, that's the vibe. 🦋
The async version of a model subclasses llm.AsyncModel instead of llm.Model. And it has to implement an async def execute() async generator method instead of a plain def execute().
Here's a lil subset of the OpenAI default plugin showing how that method might work:
from collections.abc import AsyncGenerator
import llm
class MyAsyncModel(llm.AsyncModel):
# This can duplicate the model_id of the sync model:
model_id = "my-model-id"
async def execute(
self, prompt, stream, response, conversation=None
) -> AsyncGenerator[str, None]:
if stream:
completion = await client.chat.completions.create(
model=self.model_id,
messages=messages,
stream=True,
)
async for chunk in completion:
yield chunk.choices[0].delta.content
else:
completion = await client.chat.completions.create(
model=self.model_name or self.model_id,
messages=messages,
stream=False,
)
if completion.choices[0].message.content is not None:
yield completion.choices[0].message.contentIf your model takes an API key, you should instead subclass llm.AsyncKeyModel and have a key= parameter on your .execute() method:
class MyAsyncModel(llm.AsyncKeyModel):
...
async def execute(
self, prompt, stream, response, conversation=None, key=None
) -> AsyncGenerator[str, None]:And then this async model instance should get passed to the register() method inside the register_models() plugin hook:
@hookimpl
def register_models(register):
register(
MyModel(), MyAsyncModel(), aliases=("my-model-aliases",)
)The prompt object handed to your execute() method is an instance of Prompt:
class llm.Prompt(prompt, model, *, fragments=None, attachments=None,
system=None, system_fragments=None, prompt_json=None, options=None,
schema=None, tools=None, tool_results=None, messages=None,
hide_reasoning=False)- The prompt being sent to the model.
- property
prompt— The text of the prompt, with any fragments concatenated. - property
system— The system prompt, with any system fragments concatenated.
- property
🎀 Supporting schemas 🎀
If your model supports structured output against a defined JSON schema (peep <#schemas>), you can implement that support by first adding supports_schema = True to the class:
class MyModel(llm.KeyModel):
...
support_schema = TrueThen add code to your .execute() method that checks for prompt.schema and, if it's there, uses it to prompt the model. ✨
prompt.schema will always be a Python dictionary representing a JSON schema — even if the user passed in a Pydantic model class. No cap. 💯
Check out the llm-gemini <https://github.com/simonw/llm-gemini> and llm-anthropic <https://github.com/simonw/llm-anthropic> plugins for examples of this pattern in action.
🔥 Supporting tools 🔥
Adding tools support (<#tools>) is a whole multi-step situation, so let's go:
- Add
supports_tools = Trueto your model class. - If
prompt.toolsis populated, turn that list ofllm.Toolobjects into the correct format for your model. - Look out for requests to call tools in the responses from your model. Call
response.add_tool_call(llm.ToolCall(...))for each of those. This should work for streaming and non-streaming and async and non-async cases. Pass the provider's tool call ID astool_call_id=if there is one; if you omit it LLM synthesizes a uniquetc_-prefixed id, since consumers rely on every tool call having one. - If your prompt has a
prompt.tool_resultslist, pass the information from thosellm.ToolResultobjects to your model. - Include
prompt.toolsandprompt.tool_resultsand tool calls fromresponse.tool_calls_or_raise()in the conversation history constructed by your plugin. - Make sure your code is OK with prompts that do not have
prompt.promptset to a value, since they may be carrying exclusively the results of a tool call.
This commit to llm-gemini <https://github.com/simonw/llm-gemini/commit/a7f1096cfbb733018eb41c29028a8cc6160be298> implementing tools helps demonstrate what this looks like for a real plugin. 👑
Here are the relevant dataclasses:
class llm.Tool(name: str, description: str | None = None, input_schema:
dict = <factory>, implementation: ~collections.abc.Callable | None =
None, plugin: str | None = None)- A tool that can be called by a model.
class llm.ToolCall(name: str, arguments: dict, tool_call_id: str | None
= None)- A request by the model to call a tool.
class llm.ToolResult(name: str, output: str, attachments:
list[~llm.models.Attachment] = <factory>, tool_call_id: str | None =
None, instance: ~llm.models.Toolbox | None = None, exception: Exception
| None = None)- The result of executing a tool call.
💜 Supporting server-side tools 💜
Server-side tools execute inside the provider's infrastructure rather than in LLM's local tool loop. Provider plugins represent these by subclassing llm.ServerSideTool:
class ProviderSearch(llm.ServerSideTool):
"A search tool executed by Example Provider."
name = "provider_search"
def __init__(self, allowed_domains=None):
self.allowed_domains = allowed_domains
def tool_spec(self, model):
spec = {"type": "provider_search"}
if self.allowed_domains:
spec["allowed_domains"] = self.allowed_domains
return spec
def prepare_request(self, model, kwargs):
# Add any other request fields this tool requires. Merge with existing values instead of replacing them.
include = kwargs.setdefault("include", [])
if "provider_search.results" not in include:
include.append("provider_search.results")Model instances expose the server-side tool classes they support using the supported_server_side_tools property:
class MyModel(llm.KeyModel):
@property
def supported_server_side_tools(self):
return (ProviderSearch,)This property is evaluated on the model instance, so it can use self.model_id or other instance configuration to vary the available tools. It is independent of supports_tools: that flag describes locally executed function tools. A model can support server-side tools, function tools, both or neither. 🤷
prompt.tools can contain both llm.Tool and llm.ServerSideTool instances. The adapter should partition that list, put each server-side tool's tool_spec(model) result wherever its provider expects it and, after the baseline request is complete, call tool.prepare_request(model, kwargs) once for each server-side tool in list order. LLM validates the model declaration before execute() runs, but it does not interpret the specification or call either method itself.
Providers with an OpenAI-compatible tools array can optionally support raw specifications by including llm.ServerSideTool in this property. This claims direct instances such as:
llm.ServerSideTool({"type": "browser_search"})Server-side tool calls returned by the provider should use the server_executed=True events described in Structured messages and streaming events.
class llm.ServerSideTool(spec: dict | None = None)- A tool executed inside the provider's infrastructure.
- Instances are passed in
tools=[...]alongside function tools. The framework transports and validates them but never executes them. Provider plugins subclass this class for their own tools; the base class can be instantiated directly with a raw provider tool specification. prepare_request(model, kwargs: dict) -> None— Add any other values this tool needs to provider requestkwargs.tool_spec(model) -> dict— Return this tool's provider-specific request specification.
- Instances are passed in
🦋 Attachments for multi-modal models 🦋
Models such as GPT-4o, Claude 3.5 Sonnet and Google's gemini-flash-latest are multi-modal: they accept input in the form of images and maybe even audio, video and other formats. iconic behaviour honestly ✨
LLM calls these attachments. Models can specify the types of attachments they accept and then implement special code in the .execute() method to handle them.
See the Python attachments documentation (<#python-api-attachments>) for details on using attachments in the Python API.
🌸 Specifying attachment types 🌸
A Model subclass can list the types of attachments it accepts by defining an attachment_types class attribute:
class NewModel(llm.Model):
model_id = "new-model"
attachment_types = frozenset(
{
"image/png",
"image/jpeg",
"image/webp",
"image/gif",
}
)These content types are detected when an attachment is passed to LLM using llm -a filename, or can be specified by the user using the --attachment-type filename image/png option.
Note: MP3 files will have their attachment type detected asaudio/mpeg, notaudio/mp3. don't @ me, that's just how it is 😭
LLM will use the attachment_types attribute to validate that provided attachments should be accepted before passing them to the model.
🍓 Handling attachments 🍓
The prompt object passed to the execute() method will have an attachments attribute containing a list of Attachment objects provided by the user.
An Attachment instance has the following properties:
url(str): The URL of the attachment, if it was provided as a URLpath(str): The resolved file path of the attachment, if it was provided as a filetype(str): The content type of the attachment, if it was providedcontent(bytes): The binary content of the attachment, if it was provided
Generally only one of url, path or content will be set.
You should usually access the type and the content through one of these methods:
attachment.resolve_type()-> str — hands you the type if it's actually available, and otherwise does the detective thing and guesses it by peeking at the first few bytes of content.attachment.content_bytes()-> bytes — gives you back the binary content, which it might have to read from a file or fetch from a URL first.attachment.base64_content()-> str — the same content, but as a base64-encoded string.
There's also an id() method that returns a database ID for this content — either a SHA256 hash of the binary content or, when the attachment is hosted at an external URL, a hash of {"url": url} instead. Lowkey an implementation detail, and one you should not need to access directly.
Heads up bestie: it's genuinely possible for a prompt with attachments to have no text prompt at all, and in that caseprompt.promptwill beNone.
Here's how the OpenAI plugin handles attachments, including the case where no prompt.prompt was provided:
if not prompt.attachments:
messages.append({"role": "user", "content": prompt.prompt})
else:
attachment_message = []
if prompt.prompt:
attachment_message.append({"type": "text", "text": prompt.prompt})
for attachment in prompt.attachments:
attachment_message.append(_attachment(attachment))
messages.append({"role": "user", "content": attachment_message})
# And the code for creating the attachment message
def _attachment(attachment):
url = attachment.url
base64_content = ""
if not url or attachment.resolve_type().startswith("audio/"):
base64_content = attachment.base64_content()
url = f"data:{attachment.resolve_type()};base64,{base64_content}"
if attachment.resolve_type().startswith("image/"):
return {"type": "image_url", "image_url": {"url": url}}
else:
format_ = "wav" if attachment.resolve_type() == "audio/wav" else "mp3"
return {
"type": "input_audio",
"input_audio": {
"data": base64_content,
"format": format_,
},
}So as you can see, it uses attachment.url if that's available and otherwise falls back to the base64_content() method to embed the image directly in the JSON it sends to the API. And for the OpenAI API, audio attachments are always included as base64-encoded strings. No exceptions, periodt.
💖 Attachments from previous conversations 💖
Conversation history — attachments from prior turns included — is all available on the canonical prompt.messages list. Peek at the next section for how that works. 🫶
✨ Structured messages and streaming events ✨
The 0.32 alpha introduced a way richer contract for plugins than just "yield strings", and honestly? It ate:
execute()yieldsStreamEventobjects (or plainstr, still supported) so text, reasoning (thinking tokens), tool calls, and server-side tool results each surface as their own event type. The framework assembles these into typedPartobjects.build_messages(or equivalent) readsprompt.messages— alist[llm.Message]that is the complete input chain for this turn.- Opaque provider tokens round-trip via
provider_metadata— Anthropic thinking signatures, Gemini thought signatures, OpenAI Responses API encrypted reasoning blobs. Plugins stash whatever the API returns, then echo it back on the next request. Iconic behavior tbh.
Older plugins still work, bestie. A plugin that still yields plain str from execute() works unchanged — each string gets wrapped as a StreamEvent(type="text", chunk=...) internally. 💅
🦋 Yielding StreamEvent from execute() 🦋
from llm.parts import StreamEvent
def execute(self, prompt, stream, response, conversation, key=None):
messages = self.build_messages(prompt, conversation)
...
for chunk in provider_sdk.stream(...):
if chunk.type == "text":
yield StreamEvent(type="text", chunk=chunk.text)
elif chunk.type == "thinking":
yield StreamEvent(type="reasoning", chunk=chunk.text)A StreamEvent has four frequently-used fields:
type— one of"text","reasoning","tool_call_name","tool_call_args","tool_result".chunk— the text fragment. For tool calls this is the tool name (fortool_call_name) or a partial JSON string (fortool_call_args).tool_call_id— the provider's id for the tool call, set ontool_call_name/tool_call_args/tool_resultevents. It's also the signal the framework uses to group tool-call events into oneToolCallPart.provider_metadata— an optionaldict[str, dict]namespaced by provider name. Carries opaque data (signatures, encrypted blobs) that must be echoed back on future requests.
Three additional fields exist for special cases:
server_executed: bool — setTruefor server-side tool calls (for example, Anthropic web search) and their results. This means the model ran the tool internally as part of responding to the prompt.tool_name— set ontool_resultevents to identify which tool this result came from.part_index: int | None — defaults toNone, which means "let the framework decide whichPartthis event belongs to." Pass an explicit integer only when you need to override the default grouping (see below).
🎀 How events group into Parts 🎀
When you leave part_index as None (the default), the framework groups events using these rules:
- Consecutive same-family events concatenate. Two
textevents in a row become oneTextPart. Tworeasoningevents in a row become oneReasoningPart. A family transition (text→reasoning, orreasoning→text) starts a newPart. - Tool calls group by
tool_call_id. Atool_call_nameand any number oftool_call_argsevents sharing atool_call_idcombine into oneToolCallPart— even if they're interleaved with other events (parallel tool calls). tool_resultis always its ownPart, paired to the originating call bytool_call_id.
And here's the whole vibe check, stream in → parts out:
text× N → oneTextPartreasoning× N, thentext× N →ReasoningPart,TextParttext,tool_call_name+args,text→TextPart,ToolCallPart,TextPart- Parallel tool calls (interleaved by id) → one
ToolCallPartper distincttool_call_id reasoning, tool call,reasoning→ReasoningPart,ToolCallPart,ReasoningPart
💜 Setting part_index explicitly 💜
In rare cases you'll want to override the default grouping:
- Forcing a single
TextPartacross non-adjacent text bursts. If your provider interleaves text deltas with tool calls but you want all the text concatenated into oneTextPart, passpart_index=0on every text event. (The default behavior produces separateTextParts on each side of the tool calls — usually what you want, but not always.) - Tool-call args arriving before the id. If your provider streams args before the
tool_call_idis known, assign your own index per logical tool call and pass it on each event of that call.
You can mix explicit indices with None in the same stream — the framework reserves your explicit values and decides the rest. Teamwork, honestly.
🌸 Reasoning tokens 🌸
For streamed reasoning text:
yield StreamEvent(type="reasoning", chunk=text_chunk)Reasoning events that appear before/after text events become distinct ReasoningPart and TextPart entries in response.messages automatically. If your provider emits two thinking blocks separated by a tool call, you'll get two ReasoningParts. No cap.
Plugins should respect prompt.hide_reasoning. This is set when the caller passes hide_reasoning=True to model.prompt(), conversation.prompt(), model.chain(), conversation.chain(), or their async counterparts. It's also set by the CLI -R/--hide-reasoning option.
prompt.hide_reasoning means "hide visible reasoning output", not "disable model reasoning". Do not confuse them!!If your provider requires an explicit request for visible reasoning summaries, do not request those summaries when prompt.hide_reasoning is true:
kwargs = {}
if not prompt.hide_reasoning:
kwargs["reasoning"] = {"summary": "auto"}If your provider emits reasoning blocks regardless of request parameters, keep yielding those reasoning events as usual:
if chunk.type == "thinking":
yield StreamEvent(type="reasoning", chunk=chunk.text)LLM's display layers use prompt.hide_reasoning to avoid showing those events to the user, while still allowing the framework to persist ReasoningPart objects and provider metadata for logs, serialization, and future turns. 👑
⭐ Tool calls ⭐
Each tool call emits two event types sharing a tool_call_id:
yield StreamEvent(
type="tool_call_name",
chunk=tool_name,
tool_call_id=tool_call_id,
)
# then, as the provider streams JSON args:
yield StreamEvent(
type="tool_call_args",
chunk=partial_json_fragment,
tool_call_id=tool_call_id,
)okay so the framework groups them by tool_call_id 🎀 — which means parallel tool calls (where the args for tool A and tool B are interleaving all over the wire) just work, with zero per-call index tracking. no cap. and some providers (looking at you, Gemini) emit the entire tool call in one single chunk — and that's completely fine, it's OK to emit both events back-to-back with the full name and the full JSON. slay. 💅
for client-side tool calls — the ones where LLM should execute the tool locally in a chain — you also call response.add_tool_call(). the chain-execution path (response.tool_calls() → execute_tool_calls()) reads from that explicitly-added list, not from the StreamEvent buffer. important!! 🙈
response.add_tool_call(
llm.ToolCall(
tool_call_id=tool_id,
name=tool_name,
arguments=parsed_args,
)
)🫶 Provider-managed local tool calls
some provider SDKs run the tool loop all by themselves — like, they call a local callback with the generated arguments, wait for that callback to hand back a result, then keep going on the same model response. iconic of them, honestly. plugins for those providers can delegate the actual invocation to LLM using response.execute_tool_call():
tool_result = response.execute_tool_call(
llm.ToolCall(
tool_call_id=tool_id,
name=tool_name,
arguments=parsed_args,
)
)
return tool_result.outputasync model plugins, you're up — use the awaitable equivalent method on AsyncResponse:
tool_result = await response.execute_tool_call(
llm.ToolCall(
tool_call_id=tool_id,
name=tool_name,
arguments=parsed_args,
)
)
return tool_result.outputthis routes through LLM's normal tool executor, which means toolbox preparation, error handling, llm_tool_call injection, and the before_call / after_call lifecycle callbacks all come along for the ride. and if you leave tool_call_id out, LLM just generates one for you. 🎀
⚠️ do not also call response.add_tool_call() for a provider-managed call. that would make the normal chain loop run the same tool a second time after the provider already got its result. double trouble, and not the cute kind. 💀
🌸 Server-side tool calls
for tools the API executes internally, set server_executed=True on the events. Anthropic web search is the textbook example: the API sends back a server_tool_use block for the search request, then a web_search_tool_result block carrying the result payload. 🦋
yield StreamEvent(
type="tool_call_name",
chunk="web_search",
tool_call_id=tool_id,
server_executed=True,
)
yield StreamEvent(
type="tool_call_args",
chunk=json.dumps(query_args),
tool_call_id=tool_id,
server_executed=True,
)the tool result (like, the actual search hits) gets emitted as an event too:
yield StreamEvent(
type="tool_result",
chunk=human_readable_summary,
tool_call_id=tool_id,
server_executed=True,
tool_name="web_search",
provider_metadata={"myprovider": {"raw_content": full_payload}},
)some providers don't stream their server-tool-result contents at all (Anthropic's web_search_tool_result blocks only arrive in the final message, rip). for those, emit the results as a post-stream step: once the main iteration loop completes, inspect the final message and emit tool_result events for any server-side results. 💅
⚠️ don't call response.add_tool_call() for server-side tool calls either!! that method should only be used for tool calls that actually need to be executed locally by the framework. periodt.
🔮 Opaque provider metadata
some providers need you to echo back opaque fields on the next request, or multi-turn continuity simply will not work:
- Anthropic —
signatureon each thinking block;encrypted_contentinsideweb_search_tool_resultitems. - Google Gemini —
thoughtSignatureonfunctionCallparts when thinking is active. - OpenAI Responses API —
encrypted_contenton reasoning items in stateless mode.
these values get attached to a StreamEvent via its provider_metadata field. the framework merges metadata across events that group into the same Part (last non-None wins per top-level key) and persists it on the finalized Part. 🫶
namespace under your provider's name so transcripts that mix providers don't collide:
# Anthropic signature arrives at the end of a thinking block.
yield StreamEvent(
type="reasoning",
chunk="",
provider_metadata={"anthropic": {"signature": sig}},
)
# Gemini attaches thoughtSignature to a functionCall part.
yield StreamEvent(
type="tool_call_name",
chunk=name,
tool_call_id=tc_id,
provider_metadata={"gemini": {"thoughtSignature": sig}},
)the framework round-trips the value verbatim via JSON, so keep your provider metadata to JSON-safe primitives (string, int, bool, dict, list) — and if you need to store binary data, base64 encode it. ✨
💫 Non-streaming path
when stream=False (or the provider just hands you a complete message all at once), emit one event per content block:
else:
completion = client.messages.create(**kwargs)
response.response_json = completion.model_dump()
for block in completion.content:
if block.type == "thinking":
yield StreamEvent(
type="reasoning",
chunk=block.thinking,
provider_metadata={"anthropic": {"signature": block.signature}},
)
elif block.type == "text":
yield StreamEvent(type="text", chunk=block.text)
elif block.type == "tool_use":
yield StreamEvent(
type="tool_call_name",
chunk=block.name,
tool_call_id=block.id,
)
yield StreamEvent(
type="tool_call_args",
chunk=json.dumps(block.input),
tool_call_id=block.id,
)🎀 Condensing logged payloads with json_replacements
the raw provider payload your plugin assigns to response.response_json gets logged condensed <#logging-message-store-response-json>: content the log database already stores elsewhere — the response text, reasoning blobs, tool definitions — is replaced with references instead of being written twice. no duplicate data, we stan. 💖
your model class can level this up by declaring a json_replacements class attribute: a dictionary of payload fragments that you know recur in every response from your provider. go consult the default OpenAI plugin for an example of this pattern: https://github.com/simonw/llm/blob/main/llm/default_plugins/openai_models.py 👑
class MyModel(llm.KeyModel):
json_replacements = {
"tool_usage_0": {
"image_gen": {"input_tokens": 0, "output_tokens": 0},
"web_search": {"num_requests": 0},
},
"response_env_0": {
"object": "response",
"status": "completed",
"store": False,
},
}payload content that matches an entry is stored as a reference to it. dict entries match structurally and additionally serve as merge bases: a payload object that mostly matches an entry — like a response envelope where only the id and usage vary per call — is stored as the base plus a patch of its differing keys. chef's kiss. 😭
rules to follow, bestie — write these on your hand:
- Entries are append-only. never remove or change an existing entry — only add new ones. stored payloads reference entries by key and resolve against your dictionary when they're read back, so editing an entry silently breaks every payload already logged against it. when a provider changes a boilerplate block, append a new entry with a new suffix and leave the old one in place. 🫶
- Reading these payloads requires your plugin to be installed: resolution looks your model up by id in the registry. if the model is unknown at read time, the payload gets reported as unavailable rather than resolved incorrectly. 🙈
- There is no size threshold for dictionary entries — you're trusted to curate them — but an entry smaller than the roughly 20-byte reference that replaces it makes payloads larger, not smaller. 💀
🌈 Consuming prompt.messages in build_messages
prompt.messages is a list[llm.Message] that is always the complete input chain for this turn — whether the caller supplied it explicitly via model.prompt(messages=[...]), or it was synthesized from kwargs (prompt=, system=, attachments=, tool_results=), or it was pre-built by a Conversation or by response.reply(). every single time, no exceptions. 💅
⚠️ do not also walkconversation.responses. history is already baked intoprompt.messages; walking the conversation would double-emit. not the vibe.
a plugin's build_messages (or its equivalent) iterates prompt.messages and dispatches per Part subtype:
from llm.parts import (
TextPart,
ReasoningPart,
ToolCallPart,
ToolResultPart,
AttachmentPart,
)
def build_messages(self, prompt, conversation):
messages = []
for msg in prompt.messages:
if msg.role == "system":
# Some APIs put system on a separate kwarg (Anthropic, Gemini).
# OpenAI-style APIs emit it as a message; handle accordingly.
continue
self._append_message(messages, msg)
return messagesdef _append_message(self, out, msg):
# Map llm's role to the provider's (assistant→model for Gemini,
# tool→user for Anthropic/Gemini tool_result convention, etc.)
role = self._provider_role(msg.role)
parts = []
for part in msg.parts:
if isinstance(part, TextPart):
parts.append({"type": "text", "text": part.text})
elif isinstance(part, ReasoningPart):
# Skip redacted reasoning (no content to echo back).
if part.redacted or not part.text:
continue
block = {"type": "thinking", "thinking": part.text}
# Restore the signature from provider_metadata.
sig = (part.provider_metadata or {}).get("anthropic", {}).get("signature")
if sig:
block["signature"] = sig
parts.append(block)
elif isinstance(part, ToolCallPart):
parts.append({
"type": "tool_use",
"id": part.tool_call_id,
"name": part.name,
"input": part.arguments,
})
elif isinstance(part, ToolResultPart):
parts.append({
"type": "tool_result",
"tool_use_id": part.tool_call_id,
"content": part.output,
})
elif isinstance(part, AttachmentPart) and part.attachment:
parts.append(self._attachment_block(part.attachment))
# Merge with the previous message if roles match (some providers
# require strict alternation between user and assistant).
if out and out[-1]["role"] == role:
out[-1]["content"].extend(parts)
else:
out.append({"role": role, "content": parts})🔮 Restoring opaque metadata on subsequent requests 🔮
So when a conversation keeps going, your build_messages has to walk the prior-turn Parts via prompt.messages. Every Part's provider_metadata is a dict[str, dict] keyed by provider name — so extract your namespace and fold the fields back into the outgoing request body, like this:
if isinstance(part, ReasoningPart):
block = {"type": "thinking", "thinking": part.text}
pm = (part.provider_metadata or {}).get("anthropic", {})
if "signature" in pm:
block["signature"] = pm["signature"]
parts.append(block)
if isinstance(part, ToolCallPart):
fc_part = {"function_call": {"name": part.name, "args": part.arguments}}
pm = (part.provider_metadata or {}).get("gemini", {})
if "thoughtSignature" in pm:
# Gemini expects thoughtSignature beside function_call,
# not nested inside it.
fc_part["thoughtSignature"] = pm["thoughtSignature"]
parts.append(fc_part)If the key is missing — like, an older transcript that pre-dates your plugin's support — just fall through, don't fail. And treat other providers' entries as opaque, bestie. Do not parse them. 💅
💸 Tracking token usage 💸
Models that charge by the token should track the number of tokens used by each prompt. The response.set_usage() method records the number of tokens used by a response — and then those numbers get made available through the Python API and logged to the SQLite database for command-line users. 🧾✨
response here is the response object that's passed to .execute() as an argument.
Call response.set_usage() at the end of your .execute() method. It takes keyword arguments input=, output= and details= — all three are optional. input and output should be integers, and details should be a dictionary that gives extra info beyond the input and output token counts.
This example logs 15 input tokens, 340 output tokens and notes that 37 tokens were cached:
response.set_usage(input=15, output=340, details={"cached": 37})🏷️ Tracking resolved model names 🏷️
Sometimes the model ID the user asked for is not the exact model that actually ran. A lot of providers have a model-latest alias that might execute different models over time. 👀
If those APIs hand back the real model ID that was used, your plugin can record it in the resources.resolved_model column in the logs by calling this method and passing the string representing the resolved, final model ID:
response.set_resolved_model(resolved_model_id)That string gets recorded in the database and shown in the output of llm logs and llm logs --json. 🫶
🚨 LLM_RAISE_ERRORS 🚨
While you're working on a plugin it's genuinely useful to ask for errors to be raised instead of caught and logged, so you can actually reach them from the Python debugger.
Set the LLM_RAISE_ERRORS environment variable to enable this behavior, then run llm like this:
LLM_RAISE_ERRORS=1 python -i -m llm ...The -i option means Python will drop into an interactive shell if an error occurs. Then you can open a debugger at the most recent error using:
import pdb; pdb.pm()🧰 Utility functions for plugins 🧰
LLM ships some utility functions that may be useful to plugins. Little gift bag, honestly. 🎁
🔑 llm.get_key()
This method looks up secrets that users have stored using the llm keys set command. If your plugin needs to access an API key or other secret, this is a convenient way to provide it.
It returns either a string containing the key, or None if the key could not be resolved.
Use the alias="name" option to retrieve the key set with that alias:
github_key = llm.get_key(alias="github")You can also add env="ENV_VAR" to fall back to looking in that environment variable if the key has not been configured:
github_key = llm.get_key(alias="github", env="GITHUB_TOKEN")In some cases you may let users provide a key as input, where they could input either the key itself or specify an alias to look up in keys.json. Use the input= parameter for that:
github_key = llm.get_key(input=input_from_user, alias="github", env="GITHUB_TOKEN")A previous version of this function used positional arguments in a confusing order. Those are still supported, but the new keyword arguments are the recommended, better way to use llm.get_key() going forward. 👑
📁 llm.user_dir()
LLM stores various pieces of logging and configuration data in a directory on the user's machine.
On macOS this directory is ~/Library/Application Support/io.datasette.llm, but this will differ on other operating systems.
The llm.user_dir() function returns the path to this directory as a pathlib.Path object, after creating that directory if it does not yet exist.
Plugins can use this to store their own data in a subdirectory of this directory. 🗂️
import llm
user_dir = llm.user_dir()
plugin_dir = data_path = user_dir / "my-plugin"
plugin_dir.mkdir(exist_ok=True)
data_path = plugin_dir / "plugin-data.db"😭 llm.ModelError
If your model encounters an error that should be reported to the user, you can raise this exception. For example:
import llm
raise ModelError("MPT model not installed - try running 'llm mpt30b download'")This gets caught by the CLI layer and displayed to the user as an error message. 🫡
🎭 Response.fake()
When you're writing tests for a model it can be useful to generate fake response objects — for example in this test from llm-mpt30b:
def test_build_prompt_conversation():
model = llm.get_model("mpt")
conversation = model.conversation()
conversation.responses = [
llm.Response.fake(model, "prompt 1", "system 1", "response 1"),
llm.Response.fake(model, "prompt 2", None, "response 2"),
llm.Response.fake(model, "prompt 3", None, "response 3"),
]
lines = model.build_prompt(llm.Prompt("prompt 4", model), conversation)
assert lines == [
"<|im_start|>system\system 1<|im_end|>\n",
"<|im_start|>user\nprompt 1<|im_end|>\n",
"<|im_start|>assistant\nresponse 1<|im_end|>\n",
"<|im_start|>user\nprompt 2<|im_end|>\n",
"<|im_start|>assistant\nresponse 2<|im_end|>\n",
"<|im_start|>user\nprompt 3<|im_end|>\n",
"<|im_start|>assistant\nresponse 3<|im_end|>\n",
"<|im_start|>user\nprompt 4<|im_end|>\n",
"<|im_start|>assistant\n",
]The signature of llm.Response.fake() is:
def fake(cls, model: Model, prompt: str, system: str, response: str):🐍 Python API 🐍
LLM provides a Python API for executing prompts, in addition to the command-line interface.
Understanding this API is also important for writing Plugins. ✨
🌟 Basic prompt execution 🌟
To run a prompt against the gpt-5.6-luna model, run this:
import llm
model = llm.get_model("gpt-5.6-luna")
# key= is optional, you can configure the key in other ways
response = model.prompt(
"Five surprising names for a pet pelican",
key="sk-..."
)
print(response.text())Note that the prompt will not be evaluated until you call that response.text() method — it's a form of lazy loading. 😴
If you inspect the response before it has been evaluated it will look like this:
<Response prompt='Your prompt' text='... not yet done ...'>The llm.get_model() function accepts model IDs or aliases. You can also omit it entirely to use the currently configured default model, which is gpt-5.6-luna if you have not changed the default.
In this example the key is set by Python code. You can also provide the key using the OPENAI_API_KEY environment variable, or use the llm keys set openai command to store it in a keys.json file — see API key management.
The __str__() method of response also returns the text of the response, so you can do this instead:
print(llm.get_model().prompt("Five surprising names for a pet pelican"))You can run this command to see a list of available models and their aliases:
llm modelsIf you have set a OPENAI_API_KEY environment variable you can omit the model.key = line.
Calling llm.get_model() with an invalid model ID will raise a llm.UnknownModelError exception. 💀
🎀 System prompts 🎀
For models that accept a system prompt, pass it as system="...":
response = model.prompt(
"Five surprising names for a pet pelican",
system="Answer like GlaDOS"
)🖼️ Attachments 🖼️
Models that accept multi-modal input (images, audio, video etc) can be passed attachments using the attachments= keyword argument. This accepts a list of llm.Attachment() instances.
This example shows two attachments — one from a file path and one from a URL:
import llmmodel = llm.get_model("gpt-5.6-luna")
response = model.prompt(
"Describe these images",
attachments=[
llm.Attachment(path="pelican.jpg"),
llm.Attachment(url="https://static.simonwillison.net/static/2024/pelicans.jpg"),
]
)And if you've already got the raw bytes sitting in memory, just hand them over directly with llm.Attachment(content=b"binary image content here") — no filesystem, no URL, no drama ✨
📎 the Attachment class, bestie
class llm.Attachment(type: str | None = None, path: str | None = None,
url: str | None = None, content: bytes | None = None, _id: str | None =
None)An attachment (image, audio, etc) to include with a prompt. Like, it's the little payload you tuck into your prompt so the model has something to look at 👀
It's got three lil' helper methods and they all eat:
base64_content()— hands you back the content as a base64-encoded string (iykyk, APIs love base64)content_bytes()— gives you the binary content, and it'll go read from thepathor the URL if it needs to fetch it firstresolve_type()— gives you back the content type, and if you never told it the type it'll guess it from the content 🕵️♀️
🎀 which attachments does my model even want
Not every model eats every file type, okay? You can vibe check that with the model.attachment_types set:
model = llm.get_model("gpt-5.6-luna")
print(model.attachment_types)
# {'image/gif', 'image/png', 'image/jpeg', 'image/webp'}
if "image/jpeg" in model.attachment_types:
# Use a JPEG attachment here
...So cute, so simple, so "does this model do JPEG or not" 💅
🛠️ Tools
Tools <#tools> are functions that can be executed by the model as part of a chain of responses. Not you writing the tool and the model calling the tool — the model is the one driving here 👑
You define tools in Python code — with a docstring that describes what they do, because that docstring is literally how the model learns what the thing does — and then you pass them to the model.prompt() method using the tools= keyword argument. If the model decides it wants a tool call, the response.tool_calls() method shows you exactly what the model wants to execute:
import llm
def upper(text: str) -> str:
"""Convert text to uppercase."""
return text.upper()
model = llm.get_model("gpt-4.1-mini")
response = model.prompt("Convert panda to upper", tools=[upper])
tool_calls = response.tool_calls()
# [ToolCall(name='upper', arguments={'text': 'panda'}, tool_call_id='...')]Every single tool call is guaranteed to have a unique tool_call_id. No cap. Most providers supply their own; for the providers that don't, LLM synthesizes one of the form tc_01..., so you can always use the id to correlate a tool call with its result, or to key external state against a specific invocation. fr fr, always populated, always yours to use ✨
Then you can call response.execute_tool_calls() to actually run those calls and get the results back:
tool_results = response.execute_tool_calls()
# [ToolResult(name='upper', output='PANDA', tool_call_id='...')]To get the model's follow-up reply, call response.reply() — and here's the slay part: when the previous response made tool calls, reply() automatically executes them and feeds the results back into the next turn 🌈
follow_up = response.reply()
print(follow_up.text())
# The word "panda" converted to uppercase is "PANDA".You can also pass an additional user prompt: response.reply("now translate it to French"). Conversational, iconic, we love to see it.
And if you want to use custom or already-computed tool results (e.g. results you mutated, or synthetic ones for testing), pass them explicitly with tool_results= and the auto-execute step is skipped entirely:
follow_up = response.reply(
"now translate it",
tool_results=[llm.ToolResult(name="upper", output="PANDA", tool_call_id="...")],
)For an automatic loop that keeps going until the model stops requesting tools, use model.chain() — it passes tool call results back to the model automatically as subsequent prompts 🔁
chain_response = model.chain(
"Convert panda to upper",
tools=[upper],
)
print(chain_response.text())
# The word "panda" converted to uppercase is "PANDA".You can also loop through the model.chain() response to get a stream of tokens, like this:
for chunk in model.chain(
"Convert panda to upper",
tools=[upper],
):
print(chunk, end="", flush=True)This will stream each of the chain of responses in turn as they are generated. Token by token by token, like a little waterfall of words 💧
You can access the individual responses that make up the chain using chain.responses(). This can be iterated over as the chain executes, like this:
chain = model.chain(
"Convert panda to upper",
tools=[upper],
)
for response in chain.responses():
print(response.prompt)
for chunk in response:
print(chunk, end="", flush=True)🐛 Tool debugging hooks
Pass a function to the before_call= parameter of model.chain() and that function gets called before every tool call is executed. And if you want to shut the whole thing down, you can raise llm.CancelToolCall() to cancel that tool call 🚫
The method signature is def before_call(tool: llm.Tool | None, tool_call: llm.ToolCall) — and heads up, that first tool argument can be None if the model requests a tool be executed that has not been provided in the tools= list. Like the model ordering off-menu 💀
Here's an example:
import llm
def upper(text: str) -> str:
"Convert text to uppercase."
return text.upper()
def before_call(tool: llm.Tool | None, tool_call: llm.ToolCall):
tool_name = tool.name if tool is not None else tool_call.name
print(f"About to call tool {tool_name} with arguments {tool_call.arguments}")
if tool_name == "upper" and "bad" in repr(tool_call.arguments):
raise llm.CancelToolCall("Not allowed to call upper on text containing 'bad'")
model = llm.get_model("gpt-4.1-mini")
response = model.chain(
"Convert panda to upper and badger to upper",
tools=[upper],
before_call=before_call,
)
print(response.text())If you raise llm.CancelToolCall in the before_call function the model will be informed that the tool call was cancelled. Polite rejection, bestie — it knows, and it moves on 🫶
The after_call= parameter can be used to run a logging function after each tool call has been executed. The method signature is def after_call(tool: llm.Tool, tool_call: llm.ToolCall, tool_result: llm.ToolResult). This continues the previous example:
def after_call(tool: llm.Tool, tool_call: llm.ToolCall, tool_result: llm.ToolResult):
print(f"Tool {tool.name} called with arguments {tool_call.arguments} returned {tool_result.output}")
response = model.chain(
"Convert panda to upper and badger to upper",
tools=[upper],
after_call=after_call,
)
print(response.text())🔍 Accessing the tool call from inside a tool
Tool implementations sometimes need to know about the llm.ToolCall that triggered them — most often the tool_call_id (always populated, see above), which can be used to key external state against that specific invocation.
If your tool function accepts a parameter named llm_tool_call it will be passed the llm.ToolCall object for the current call:
import llm
def lookup(name: str, llm_tool_call: llm.ToolCall) -> str:
"Look up a name."
return do_lookup(name, request_id=llm_tool_call.tool_call_id)The llm_tool_call parameter name is reserved: it is excluded from the input schema that is exposed to the model, and it is populated automatically when the tool executes. The type annotation is optional. So the model never even sees it — it's our lil' secret 🤫
This works for both sync and async tool functions, and for methods on llm.Toolbox subclasses. The parameter must be declared explicitly — a **kwargs catch-all will not receive llm_tool_call. Declare it or lose it, that's the rule 🎀
⏸️ Pausing a chain from inside a tool
Sometimes a tool cannot finish without outside input — human approval being the classic case. Raise llm.PauseChain inside a tool implementation to stop the chain cleanly:
import llm
def delete_files(path: str) -> str:
if not approval_already_recorded(path):
record_approval_request(path)
raise llm.PauseChain("waiting for approval to delete " + path)
do_delete(path)
return "deleted"Unlike other exceptions — which are converted into "Error: ..." tool results and sent back to the model — PauseChain propagates out of the chain to your code. No provider call is made with a placeholder result. This one does NOT get quietly absorbed, bestie, it comes straight back to you 👑
Before re-raising, the framework populates two attributes:
pause.tool_call— thellm.ToolCallwhose implementation pausedpause.tool_results— results of sibling calls in the same batch that completed
try:
chain_response.text()
except llm.PauseChain as pause:
print("Paused on", pause.tool_call.name, pause.tool_call.tool_call_id)The failure semantics are defined: concurrent (async) sibling tool calls always run to completion before the exception propagates — their after_call hooks fire and their results are preserved — while sequential (sync) execution stops at the paused call, leaving later calls unexecuted so they can safely run on resume. If several concurrent calls pause, the first by call order propagates. after_call does not fire for a paused call, and no ToolResult is recorded for it — which is what marks it as still pending. Pending = not done = we'll pick it back up later 💅
▶️ Resuming a chain with pending tool calls
To resume after a pause (or a crash, or a server restart), re-run the chain with a messages= history that ends in the unresolved tool calls. When the last assistant message in the history contains tool calls that have no matching results, the chain executes them first — through the normal before_call/after_call machinery — and then sends the results to the model:
chain = model.chain(
messages=persisted_messages, # ends in assistant tool calls with no results
tools=[delete_files],
system=system_prompt,
)
chain.text()Calls that already have results in trailing tool-role messages are skipped, so a batch where some calls completed before the pause only re-executes the unresolved ones. No double-deleting your files, we're not doing that today 🫶 A re-executed tool may raise PauseChain again — multi-step approval flows work by repeating the cycle. If a user or assistant message follows the tool calls in the history, the conversation has moved on and nothing is re-executed. Moved on = stay moved on ✨
Matching uses tool_call_id (always populated for newly-created tool calls); id-less calls from older persisted histories match results by name. You can also execute an explicit list of calls directly with response.execute_tool_calls(tool_calls_list=[...]).
🖼️ Tools can return attachments
Tools can return attachments in addition to returning text. Attachments that are returned from a tool call will be passed to the model as attachments for the next prompt in the chain. Tool hands the model a picture, model looks at the picture, the chain continues — iconic behaviour honestly 🌈
To return one or more attachments, return a llm.ToolOutput instance from your tool function. This can have an output= string and an attachments= list of llm.Attachment instances.
Here's an example:
import llmdef generate_image(prompt: str) -> llm.ToolOutput:
"""Generate an image based on the prompt."""
image_content = generate_image_from_prompt(prompt)
return llm.ToolOutput(
output="Image generated successfully",
attachments=[llm.Attachment(
content=image_content,
mimetype="image/png"
)],
)okay so that's the whole "my tool wants to hand back an actual picture and not just a lil string" vibe 💅 and the class doing all that heavy lifting is this one:
class llm.ToolOutput(output: str | dict | list | bool | int | float | None = None, attachments: list[~llm.models.Attachment] = <factory>)— tool functions can return output with extra attachments 🎀
Server-side tools 🛰️
Server-side tools are executed by the model provider during a response. Pass them in the same tools= list as function tools, but do not call execute_tool_calls() for them: their calls and results arrive in response.messages() with server_executed=True and are excluded from the local execution loop.
For example, OpenAI Responses models support Web Search <#openai-models-web-search> and Code Interpreter <#openai-models-code-interpreter>:
import llm
from llm.default_plugins.openai_models import CodeInterpreter
response = llm.get_model("gpt-5.6-luna").prompt(
"Use the python tool to calculate the first 20 Fibonacci numbers",
tools=[CodeInterpreter(memory_limit="4g")],
)
print(response.text())Provider plugins define these tools by subclassing llm.ServerSideTool <#llm.ServerSideTool>. Each model instance returns its supported classes from supported_server_side_tools; a model rejects classes it has not explicitly included rather than silently dropping them. See Supporting server-side tools <#advanced-model-plugins-server-side-tools> for the plugin API.
Toolbox classes 🧰✨
Functions are useful for simple tools, but some tools may have more advanced needs. You can also define tools as a class (known as a "toolbox"), which provides the following advantages:
- Toolbox tools can bundle multiple tools together 🫶
- Toolbox tools can be configured, e.g. to give filesystem tools access to a specific directory
- Toolbox instances can persist shared state in between tool invocations
Toolboxes are classes that extend llm.Toolbox. Any methods that do not begin with an underscore will be exposed as tool functions.
This example sets up key/value memory storage that can be used by the model:
import llm
class Memory(llm.Toolbox):
_memory = None
def _get_memory(self):
if self._memory is None:
self._memory = {}
return self._memory
def set(self, key: str, value: str):
"Set something as a key"
self._get_memory()[key] = value
def get(self, key: str):
"Get something from a key"
return self._get_memory().get(key) or ""
def append(self, key: str, value: str):
"Append something as a key"
memory = self._get_memory()
memory[key] = (memory.get(key) or "") + "\n" + value
def keys(self):
"Return a list of keys"
return list(self._get_memory().keys())class llm.Toolbox— the base class, bestie 👑add_tool(tool_or_function: Tool <#llm.Tool> | Callable[[...], Any], pass_self: bool = False)— add a tool to this toolboxprepare()— over-ride this to perform setup (and.add_tool()calls) before the toolbox is used. Implement a similarprepare_async()method for async setup.async prepare_async()— over-ride this to perform async setup (and.add_tool()calls) before the toolbox is used.tools() -> Iterable[Tool <#llm.Tool>]— returns anllm.Tool()for each class method, plus any extras registered withadd_tool()
You can then use that from Python like this:
model = llm.get_model("gpt-4.1-mini")
memory = Memory()
conversation = model.conversation(tools=[memory])
print(conversation.chain("Set name to Simon", after_call=print).text())
print(memory._memory)
# Should show {'name': 'Simon'}
print(conversation.chain("Set name to Penguin", after_call=print).text())
# Now it should be {'name': 'Penguin'}
print(conversation.chain("Print current name", after_call=print).text())See the register_tools() plugin hook documentation <#plugin-hooks-register-tools> for an example of this tool in action as a CLI plugin.
Dynamic toolboxes 🦋
Sometimes you may need to register additional tools against a toolbox after it has been created — for example if you are implementing an MCP plugin where the toolbox needs to consult the MCP server to discover what tools are available.
You can use the toolbox.add_tool(function_or_tool) method to add a new tool to an existing toolbox.
This can be passed a llm.Tool instance or a function that will be converted into a tool automatically.
If you want your function to be able to access the toolbox instance itself as a self parameter, pass that function to add_tool() with the pass_self=True parameter:
def my_function(self, arg1: str, arg2: int) -> str:
return f"Received {arg1} and {arg2} in {self}"
toolbox.add_tool(my_function, pass_self=True)Without pass_self=True the function will be called with only its declared arguments, with no self parameter.
If your toolbox needs to run an additional command to figure out what it should register using .add_tool() you can implement a prepare() method on your toolbox class. This will be called once automatically when the toolbox is first used.
In asynchronous contexts the alternative method await toolbox.prepare_async() method will be called before the toolbox is used. You can implement this method on your subclass and use it to run asynchronous operations that discover tools to be registered using self.add_tool().
If you want to prepare the class in this way such that it can be used in both synchronous and asynchronous contexts, implement both prepare() and prepare_async() methods.
Toolbox classes that override tools(), prepare() or prepare_async() are treated as dynamic by the llm tools command. Since their full list of tools cannot be determined until an instance has been configured, llm tools displays their constructor signature and class docstring instead of a list of tools - so give your dynamic toolbox a descriptive docstring that shows how to configure it. Users can then pass a full specification such as llm tools 'MCP("https://example.com/mcp")' to instantiate the toolbox - running prepare() if it is implemented - and list the tools that instance provides. See the tools usage documentation <#usage-tools> for details.
Schemas 🎀
As with the CLI tool <#usage-schemas> some models support passing a JSON schema should be used for the resulting response.
You can pass this to the prompt(schema=) parameter as either a Python dictionary or a Pydantic <https://docs.pydantic.dev/> BaseModel subclass:
import llm, json
from pydantic import BaseModel
class Dog(BaseModel):
name: str
age: int
model = llm.get_model("gpt-5.6-luna")
response = model.prompt("Describe a nice dog", schema=Dog)
dog = json.loads(response.text())
print(dog)
# {"name":"Buddy","age":3}You can also pass a schema directly, like this:
response = model.prompt("Describe a nice dog", schema={
"properties": {
"name": {"title": "Name", "type": "string"},
"age": {"title": "Age", "type": "integer"},
},
"required": ["name", "age"],
"title": "Dog",
"type": "object",
})You can also use LLM's alternative schema syntax <#schemas-dsl> via the llm.schema_dsl(schema_dsl) function. This provides a quick way to construct a JSON schema for simple cases:
print(model.prompt(
"Describe a nice dog with a surprising name",
schema=llm.schema_dsl("name, age int, bio")
))Pass multi=True to generate a schema that returns multiple items matching that specification:
print(model.prompt(
"Describe 3 nice dogs with surprising names",
schema=llm.schema_dsl("name, age int, bio", multi=True)
))Fragments 🌸
The fragment system <#usage-fragments> from the CLI tool can also be accessed from the Python API, by passing fragments= and/or system_fragments= lists of strings to the prompt() method:
from pathlib import Path
response = model.prompt(
"What do these documents say about dogs?",
fragments=[
Path("dogs1.txt").read_text(),
Path("dogs2.txt").read_text(),
],
system_fragments=[
"You answer questions like Snoopy",
]
)This mechanism has limited utility in Python, as you can also assemble the contents of these strings together into the prompt= and system= strings directly.
Fragments become more interesting if you are working with LLM's mechanisms for storing prompts to a SQLite database, which are not yet part of the stable, documented Python API.
Some model plugins may include features that take advantage of fragments, for example llm-anthropic <https://github.com/simonw/llm-anthropic> aims to use them as part of a mechanism that taps into Claude's prompt caching system.
Model options ⚙️
For models that support options (view those with llm models --options) pass them as a dictionary to the options= argument of the .prompt() method:
model = llm.get_model()
print(model.prompt("Names for otters", options={"temperature": 0.2}))Passing an API key 🔑
Models that accept API keys should take an additional key= parameter to their model.prompt() method:
model = llm.get_model("gpt-5.6-luna")
print(model.prompt("Names for beavers", key="sk-..."))If you don't provide this argument LLM will attempt to find it from an environment variable (OPENAI_API_KEY for OpenAI, others for different plugins) or from keys that have been saved using the llm keys set <#api-keys> command.
Some model plugins may not yet have been upgraded to handle the key= parameter, in which case you will need to use one of the other mechanisms.
Models from plugins 🧚
Any models you have installed as plugins will also be available through this mechanism, for example to use Anthropic's Claude 3.5 Sonnet model with llm-anthropic <https://github.com/simonw/llm-anthropic>:
pip install llm-anthropicThen in your Python code:
import llmmodel = llm.get_model("claude-sonnet-5")
# Use this if you have not set the key using 'llm keys set anthropic':
model.key = 'YOUR_API_KEY_HERE'
response = model.prompt("Five surprising names for a pet pelican")
print(response.text())Some models do not use API keys at all. Like, none. Zero. Nada. They just vibe. ✨
🌈 Accessing the underlying JSON
Most model plugins also hand you a JSON version of the prompt response. Fair warning bestie: the structure of this differs between model plugins, so if you build against it, your code is probably only gonna work with that one specific model provider. It's giving commitment issues. 💀
You can grab this JSON data as a Python dictionary with the response.json() method:
import llm
from pprint import pprint
model = llm.get_model("gpt-5.6-luna")
response = model.prompt("3 names for an otter")
json_data = response.json()
pprint(json_data)Here's an abbreviated example of that output from GPT-5.6 Luna:
{'created_at': 1785451200.0,
'id': 'resp_...',
'model': 'gpt-5.6-luna',
'object': 'response',
'output': [
# Reasoning and message items are abbreviated here
{'content': [{'annotations': [],
'text': '1. Splash\n2. Bubbles\n3. Otto',
'type': 'output_text'}],
'id': 'msg_...',
'role': 'assistant',
'status': 'completed',
'type': 'message'}],
'status': 'completed',
'usage': {'input_tokens': 13,
'output_tokens': 43,
'output_tokens_details': {'reasoning_tokens': 0},
'total_tokens': 56}}🎀 Token usage
Lots of models can hand you a count of how many tokens got used while the prompt was running. Token math, iconic.
The response.usage() method gives you an abstraction over all that:
pprint(response.usage())Example output:
Usage(input=5,
output=2,
details={'candidatesTokensDetails': [{'modality': 'TEXT',
'tokenCount': 2}],
'promptTokensDetails': [{'modality': 'TEXT', 'tokenCount': 5}]})class llm.Usage(input: int | None = None, output: int | None = None, details: dict[str, Any] | None = None)Token usage information from a model response. That's the whole thing. Obsessed. 💖
🦋 Streaming responses
For models that support it, you can stream responses as they're generated, like this:
response = model.prompt("Five diabolical names for a pet goat")
for chunk in response:
print(chunk, end="")The response.text() method described earlier does this for you — it runs through the iterator and gathers the results into a string. It's doing the work so you don't have to. 💅
If a response has been evaluated, response.text() will continue to return the same string.
class llm.Response(prompt: Prompt <#llm.Prompt>, model: _BaseModel, stream: bool, conversation: _BaseConversation | None = None, key: str | None = None, before_call: Callable[[Tool <#llm.Tool> | None, ToolCall <#llm.ToolCall>], None] | Callable[[Tool <#llm.Tool> | None, ToolCall <#llm.ToolCall>], None | Awaitable[None]] | None = None, after_call: Callable[[Tool <#llm.Tool>, ToolCall <#llm.ToolCall>, ToolResult <#llm.ToolResult>], None] | Callable[[Tool <#llm.Tool>, ToolCall <#llm.ToolCall>, ToolResult <#llm.ToolResult>], None | Awaitable[None]] | None = None)Sync response from a model.
json() -> dict[str, Any] | None— Return the raw JSON response from the model, if available.on_done(callback)— Register a callback to be called when the response is complete.text() -> str— Return the full text of the response, executing the prompt if needed.tool_calls() -> list[ToolCall <#llm.ToolCall>]— Return the list of tool calls made during this response.usage() -> Usage <#llm.Usage>— Return token usage information for this response.
🌸 Structured messages and streaming events
Many LLMs return structure that goes way beyond a plain text response. LLM represents these using messages that consist of parts.
A conversation consists of turns, where each turn is an llm.Message with a role ("user", "assistant", "system", or "tool") and a list of Part objects — TextPart, ReasoningPart, ToolCallPart, ToolResultPart, or AttachmentPart.
You can pass structured prompt inputs via messages=[...], iterate over typed events as the model streams, and inspect the assembled message after the response completes. Three for the price of one, bestie. 🫶
Here's how to prompt a model with a list of messages instead of a plain text prompt:
import llm
from llm import user, assistant, system
model = llm.get_model("gpt-5.4-mini")
response = model.prompt(messages=[
system("You are a helpful pirate."),
user("What is the capital of France?"),
assistant("Paris, matey."),
user("And Germany?"),
])
print(response.text())The user(), assistant(), and system() helpers accept strings (wrapped as TextPart) but can also accept llm.Attachment instances (wrapped as AttachmentPart) or more complex sequences of Part objects.
Calling model.prompt("hi", system="Be brief.") is equivalent to model.prompt(messages=[system("Be brief."), user("hi")]).
⭐ Streaming events as they arrive
response.stream_events() yields typed events for every content block the model produces as they stream in. This is the moment for interfaces that show the model response "live". Main character energy fr fr. 👑
response = model.prompt("Explain quantum computing briefly.")
for event in response.stream_events():
if event.type == "reasoning":
print(f"[thinking] {event.chunk}", end="", flush=True)
elif event.type == "text":
print(event.chunk, end="", flush=True)
elif event.type == "tool_call_name":
print(f"\n[calling tool: {event.chunk}]")
elif event.type == "tool_call_args":
print(event.chunk, end="", flush=True)Event types are "text", "reasoning", "tool_call_name", "tool_call_args", and "tool_result". Each event carries a part_index that groups events into the same logical Part (all events at the same part_index assemble into one Part after the stream completes). For async models, use async for event in response.astream_events().
Iterating against the response object itself (for chunk in response) yields only text strings — reasoning and tool-call events are filtered out. Text only. No crumbs. 🧚
💜 Hiding reasoning output
Some model plugins can return visible reasoning text, exposed as "reasoning" events from response.stream_events() and assembled as ReasoningPart objects in response.messages().
Pass hide_reasoning=True to ask LLM and supported model plugins not to expose that visible reasoning output:
response = model.prompt(
"Explain quantum computing briefly.",
hide_reasoning=True,
)
print(response.text())This is the Python API equivalent of the CLI -R/--hide-reasoning option. It is available on model.prompt(), conversation.prompt(), model.chain(), conversation.chain(), and their async counterparts.
Heads up bestie: this only requests that the underlying model does not return visible tokens. This request may not be supported by your provider, in which case this hint will not prevent visible reasoning tokens from being returned in the stream. You've been warned. 😭
🍓 Inspecting the finished response
response.messages() returns the assembled list of Message objects produced by the model, excluding the messages from the original prompt. Calling it forces execution if the response hasn't been drained yet, so you don't need a separate response.text() first. Efficiency, we love to see it.
response = model.prompt("What's 2+2?")
for message in response.messages():
for part in message.parts:
print(type(part).__name__, part.to_dict())On async models messages() is awaitable: await response.messages().
🌈 Persisting a conversation
A Response can round-trip through a plain Python dictionary via response.to_dict() and llm.Response.from_dict(...). The dict captures the model id, the input messages that were sent, the assistant output, and any options. The re-inflated object can be used to continue the conversation. It's giving resurrection. It's giving glow up. ✨
Use response.reply(...) to continue from a rehydrated response:
import json
import llm
model = llm.get_model("gpt-5.4-mini")
response = model.prompt("What's 2+2?")
print(response.text())
payload = json.dumps(response.to_dict())
# ...save `payload` wherever you want...
# Later — rehydrate and continue.
rebuilt = llm.Response.from_dict(json.loads(payload))
followup = rebuilt.reply("Add 3 to that")
print(followup.text())AttachmentPart bytes are base64-encoded in the dict form, so multi-modal conversations round-trip via JSON too. Base64 carrying the whole vibe. 💅
Individual Message and Part objects also support to_dict() / from_dict() if you need to manipulate turns directly — for example, to edit, filter, or splice messages before passing them back via model.prompt(messages=[...]).
🦋 Async models
Some plugins provide async versions of their supported models, suitable for use with Python asyncio (https://docs.python.org/3/library/asyncio.html).
To use an async model, use the llm.get_async_model() function instead of llm.get_model():
import llm
model = llm.get_async_model("gpt-4o")You can then run a prompt using await model.prompt(...):
print(await model.prompt(
"Five surprising names for a pet pelican"
).text())Or use async for chunk in ... to stream the response as it is generated:
async for chunk in model.prompt(
"Five surprising names for a pet pelican"
):
print(chunk, end="", flush=True)class llm.AsyncResponse(prompt: Prompt <#llm.Prompt>, model: _BaseModel, stream: bool, conversation: _BaseConversation | None = None, key: str | None = None, before_call: Callable[[Tool <#llm.Tool> | None, ToolCall <#llm.ToolCall>], None] | Callable[[Tool <#llm.Tool> | None, ToolCall <#llm.ToolCall>], None | Awaitable[None]] | None = None, after_call: Callable[[Tool <#llm.Tool>, ToolCall <#llm.ToolCall>, ToolResult <#llm.ToolResult>], None] | Callable[[Tool <#llm.Tool>, ToolCall <#llm.ToolCall>, ToolResult <#llm.ToolResult>], None | Awaitable[None]] | None = None)Async response from a model.
async json() -> dict[str, Any] | None— Return the raw JSON response from the model, if available.async on_done(callback)— Register a callback to be called when the response is complete.async text() -> str— Return the full text of the response, executing the prompt if needed.async tool_calls()→list[ToolCall]— hands you back the whole list of tool calls that got made during this response, bestie. Every single one. 💅async usage()→Usage— gives you the token usage info for this response, so you can be nosy about how many tokens it ate. ✨
This await model.prompt() method takes the same arguments as the synchronous model.prompt() method — so like, options and attachments and key= and all that jazz. Same energy, just awaitable. 🫶
🌸 Tool functions can be sync or async 🌸
Tool functions can be both synchronous or asynchronous. The async ones are defined with async def tool_name(...). Either kind of function can be passed to the tools=[...] parameter. No judgement, both are valid, we love versatility. 💖
If an async def function gets used in a synchronous context, LLM will automatically run it in a thread pool using asyncio.run(). Which means — and this is the iconic part — the following works even in non-asynchronous Python scripts:
async def hello(name: str) -> str:
"Say hello to name"
return "Hello there " + name
model = llm.get_model("gpt-4.1-mini")
chain_response = model.chain(
"Say hello to Percival", tools=[hello]
)
print(chain_response.text())This also works for async def methods of llm.Toolbox subclasses. Periodt. 👑
🔥 Tool use for async models 🔥
Tool use is also supported for async models, using either synchronous or asynchronous tool functions. But listen — synchronous functions will block the event loop, so only use those in an asynchronous context if you are certain they are extremely fast. Like, no cap, be careful with that one. 😭
The response.execute_tool_calls() and chain_response.text() and chain_response.responses() methods must all be awaited when run against asynchronous models:
import llm
model = llm.get_async_model("gpt-4.1")
def upper(string):
"Converts string to uppercase"
return string.upper()
chain = model.chain(
"Convert panda to uppercase then pelican to uppercase",
tools=[upper],
after_call=print
)
print(await chain.text())To iterate over the chained response output as it arrives, use async for:
async for chunk in model.chain(
"Convert panda to uppercase then pelican to uppercase",
tools=[upper]
):
print(chunk, end="", flush=True)response.reply() is awaitable on async models — it awaits execute_tool_calls() internally before building the next turn:
response = model.prompt("Convert panda to upper", tools=[upper])
await response.text()
follow_up = await response.reply()
print(await follow_up.text())The before_call and after_call hooks can be async functions when used with async models. Slay. ✨
🦋 Conversations 🦋
LLM supports conversations, where you ask follow-up questions of a model as part of an ongoing conversation. It's giving "talking to a friend who actually remembers what you said last time". 💜
To start a new conversation, use the model.conversation() method:
model = llm.get_model()
conversation = model.conversation()You can then use the conversation.prompt() method to execute prompts against this conversation:
response = conversation.prompt("Five fun facts about pelicans")
print(response.text())This works exactly the same as the model.prompt() method, except that the conversation will be maintained across multiple prompts. So if you run this next:
response2 = conversation.prompt("Now do skunks")
print(response2.text())You will get back five fun facts about skunks. (Yes really, it just knows. Main character energy.) 🦨
The conversation.prompt() method supports attachments as well:
response = conversation.prompt(
"Describe these birds",
attachments=[
llm.Attachment(url="https://static.simonwillison.net/static/2024/pelicans.jpg")
]
)Access conversation.responses for a list of all of the responses that have so far been returned during the conversation. Receipts, basically. 🎀
🌈 Conversations using tools 🌈
You can pass a list of tool functions to the tools=[] argument when you start a new conversation:
import llm
def upper(text: str) -> str:
"convert text to upper case"
return text.upper()
def reverse(text: str) -> str:
"reverse text"
return text[::-1]
model = llm.get_model("gpt-4.1-mini")
conversation = model.conversation(tools=[upper, reverse])You can then call the conversation.chain() method multiple times to have a conversation that uses those tools:
print(conversation.chain(
"Convert panda to uppercase and reverse it"
).text())
print(conversation.chain(
"Same with pangolin"
).text())The before_call= and after_call= parameters described above can be passed directly to the model.conversation() method to set those options for all chained prompts in that conversation. Set it once, vibe forever. 💅
⭐ Listing models ⭐
The llm.get_models() list returns a list of all available models, including those from plugins. Obsessed with plugins tbh.
import llm
for model in llm.get_models():
print(model.model_id)Use llm.get_async_models() to list async models:
for model in llm.get_async_models():
print(model.model_id)🧚 Running code when a response has completed 🧚
For some applications, such as tracking the tokens used by an application, it may be useful to execute code as soon as a response has finished being executed. Like a little "ding, we're done!" moment. 🔔
You can do this using the response.on_done(callback) method, which causes your callback function to be called as soon as the response has finished (all tokens have been returned).
The signature of the method you provide is def callback(response) — it can be optionally an async def method when working with asynchronous models.
Example usage:
import llm
model = llm.get_model("gpt-5.6-luna")
response = model.prompt("a poem about a hippo")
response.on_done(lambda response: print(response.usage()))
print(response.text())Which outputs:
Usage(input=20, output=494, details={})
In a sunlit glade by a bubbling brook,
Lived a hefty hippo, with a curious look.
...Or using an asyncio model, where you need to await response.on_done(done) to queue up the callback:
import asyncio, llm
async def run():
model = llm.get_async_model("gpt-5.6-luna")
response = model.prompt("a short poem about a brick")
async def done(response):
print(await response.usage())
print(await response.text())
await response.on_done(done)
print(await response.text())
asyncio.run(run())💖 Other functions 💖
The llm top level package includes some useful utility functions. Little helpers, if you will. 🫶
🌸 set_alias(alias, model_id) 🌸
The llm.set_alias() function can be used to define a new alias:
import llm
llm.set_alias("mini", "gpt-5.6-luna")The second argument can be a model identifier or another alias, in which case that alias will be resolved. Alias-ception, lowkey. 😭
If the aliases.json file does not exist or contains invalid JSON it will be created or overwritten.
🎀 remove_alias(alias) 🎀
Removes the alias with the given name from the aliases.json file.
Raises KeyError if the alias does not exist. So like, it will yell at you. 💀
import llm
llm.remove_alias("turbo")✨ set_default_model(alias) ✨
This sets the default model to the given model ID or alias. Any changes to defaults will be persisted in the LLM configuration folder, and will affect all programs using LLM on the system, including the llm CLI tool. So yes bestie, this one has consequences. 💅
import llm
llm.set_default_model("claude-5-sonnet")🌈 get_default_model() 🌈
This returns the currently configured default model, or gpt-5.6-luna if no default has been set.
import llm
model_id = llm.get_default_model()To detect if no default has been set you can use this pattern:
if llm.get_default_model(default=None) is None:
print("No default has been set")Here the default= parameter specifies the value that should be returned if there is no configured default. Iconic little escape hatch. 🦋
👑 set_default_embedding_model(alias) and get_default_embedding_model() 👑
These two methods work the same as set_default_model() and get_default_model() but for the default embedding model instead. Same vibe, different department. 💜
🍓 Logging to SQLite 🍓
llm defaults to logging all prompts and responses to a SQLite database.
You can find the location of that database using the llm logs path command:
llm logs pathOn my Mac that outputs:
/Users/simon/Library/Application Support/io.datasette.llm/logs.dbThis will differ for other operating systems. (Don't come for me, Windows girlies. 🙈)
To avoid logging an individual prompt, pass --no-log or -n to the command:
llm 'Ten names for cheesecakes' -nTo turn logging by default off:
llm logs offIf you've turned off logging you can still log an individual prompt and response by adding --log:
llm 'Five ambitious names for a pet pterodactyl' --logTo turn logging by default back on again:
llm logs onTo see the status of the logs database, run this:
llm logs statusExample output:
Logging is ON for all prompts
Found log database at /Users/simon/Library/Application Support/io.datasette.llm/logs.db
Number of threads logged: 33
Number of turns logged: 48
Database file size: 19.96MB💅 Viewing the logs 💅
You can view the logs using the llm logs command:
llm logsThis will output the three most recent logged items in Markdown format, showing both the prompt and the response formatted using Markdown.
To get back just the most recent prompt response as plain text, add -r/--response:
llm logs -rUse -x/--extract to extract and return the first fenced code block from the selected log entries:
llm logs --extractOr --xl/--extract-last for the last fenced code block:
llm logs --extract-lastAdd --json to get the log messages in JSON instead:
llm logs --jsonAdd -n 10 to see the ten most recent items:
llm logs -n 10Or -n 0 to see everything that has ever been logged. Everything. The whole archive, bestie. 😭
llm logs -n 0You can truncate the display of the prompts and responses using the -t/--truncate option. This can help make the JSON output more readable — though the --short option is usually better. (Just saying. 💅)
llm logs -n 1 -t --jsonExample output:
[
{
"id": "01jm8ec74wxsdatyn5pq1fp0s5",
"model": "anthropic/claude-3-haiku-20240307",
"prompt": "hi",
"system": null,
"prompt_json": null,
"response": "Hello! How can I assist you today?",
"conversation_id": "01jm8ec74taftdgj2t4zra9z0j",
"duration_ms": 560,
"datetime_utc": "2025-02-16T22:34:30.374882+00:00",
"input_tokens": 8,
"output_tokens": 12,
"token_details": null,
"conversation_name": "hi",
"conversation_model": "anthropic/claude-3-haiku-20240307",
"attachments": []
}
]🌸 -s/--short mode
okay so if you want the YAML but short — like, prompts get chopped and responses just... don't show up at all — hit -s/--short bestie:
llm logs -n 2 --shortit's giving:
- model: deepseek-reasoner
datetime: '2025-02-02T06:39:53'
conversation: 01jk2pk05xq3d0vgk0202zrsg1
prompt: H01 There are five huts. H02 The Scotsman lives in the purple hut. H03 The Welshman owns the parrot. H04 Kombucha is...
- model: o3-mini
datetime: '2025-02-02T19:03:05'
conversation: 01jk40qkxetedzpf1zd8k9bgww
system: Formatting re-enabled. Write a detailed README with extensive usage examples.
prompt: <documents> <document index="1"> <source>./Cargo.toml</source> <document_content> [package] name = "py-limbo" version...and if you're nosy about tokens (same honestly) throw in -u/--usage to get that token usage tea:
llm logs -n 1 --short --usagewhich is gonna look like:
- model: o3-mini
datetime: '2025-02-16T23:00:56'
conversation: 01jm8fxxnef92n1663c6ays8xt
system: Produce Python code that demonstrates every possible usage of yaml.dump
with all of the arguments it can take, especi...
prompt: <documents> <document index="1"> <source>./setup.py</source> <document_content>
NAME = 'PyYAML' VERSION = '7.0.0.dev0...
usage:
input: 74793
output: 3550
details:
completion_tokens_details:
reasoning_tokens: 2240💅 Logs for a conversation
wanna peep the logs for your most recent convo with a model? just -c:
llm logs -cand if you need a specific one — like you know the ID — use --cid ID or --conversation ID:
llm logs --cid 01h82n0q9crqtnzmf13gkyxawg🔍 Searching the logs
you can search across your prompts and the model's responses, which is iconic:
llm logs -q 'cheesecake'most relevant results come first, obviously, main character results only ✨
okay important detail: search covers the text you typed and the text the model produced, and literally nothing else. System prompts, fragment contents, tool calls and their output, and reasoning traces are all excluded from the index — a query only matches words that showed up in a prompt or a response. so if a prompt used fragments, the fragment text is not searchable, but the question you typed next to it is.
ranking uses SQLite FTS5 relevance scores, and matches in your prompt get weighted way above matches in the response — bc what you asked is usually a stronger signal of what a convo was actually about than what came back, periodt. the full FTS5 query syntax is available too, phrase queries included:
llm logs -q '"pet pelican"'want most-recent-first instead? add -l/--latest, and you can stack it with -n to cap the number of results:
llm logs -q 'cheesecake' -l -n 3oh and search covers both new conversations and history recorded by older versions of LLM 🫶
🆔 Filtering past a specific ID
so if you wanna grab every log recorded since a specific response ID, these are your girls:
--id-gt $ID— every record with an ID greater than$ID--id-gte $ID— every record with an ID greater than or equal to$ID
IDs are always issued in ascending order by time, so this is a lowkey genius way to see everything that's happened since a particular record.
this hits different when you're working with schema data — like, you might wanna access every record you created using a specific --schema but skip the ones you already processed. chef's kiss.
🎀 Filtering by model
filter to logs for just one specific model (or model alias) with -m/--model:
llm logs -m chatgpt🧩 Filtering by prompts that used specific fragments
the -f/--fragment X option filters for just the responses that were made using the specified fragment hash or alias or URL or filename.
fragments show up in the logs as their hash ID. add -e/--expand to see them as their full content — and yes this works for both the default Markdown and the --json mode:
llm logs -f https://llm.datasette.io/robots.txt --expandyou can also display just the content for one specific fragment hash ID (or alias) with the llm fragments show command:
llm fragments show 993fd38d898d2b59fd2d16c811da5bdac658faa34f0f4d411edde7c17ebb0680and if you drop multiple fragments you'll get back responses that used all of them. no partial credit, bestie.
🛠️ Filtering by prompts that used specific tools
filter for responses that used tools from specific fragments with the --tool/-T option:
llm logs -T simple_evalthis matches responses that involved a result from that tool. if the tool wasn't actually executed it will not show up in the filtered responses.
pass --tool/-T multiple times for responses that used all of the specified tools.
and use the llm logs --tools flag to see all responses that involved at least one tool result, including ones from --functions:
llm logs --tools📊 Browsing data collected using schemas
the --schema X option lets you view responses that used the specified schema, using any of the ways to specify a schema:
llm logs --schema 'name, age int, bio'you can combine this with --data and --data-array and --data-key to extract just the returned JSON data — the schemas documentation has the deets, go look.
🦋 Browsing logs using Datasette
you can also use Datasette to browse your logs like this:
datasette "$(llm logs path)"💾 Backing up your database
back your logs up to another file with the llm logs backup command:
llm logs backup /tmp/backup.dbunder the hood this is using SQLite VACUUM INTO, so it's clean, it's tidy, it's doing the most.
🗄️ The message store
the logs.db database contains two generations of tables. Databases created by older versions of LLM recorded everything in a responses table, with companion tables such as prompt_attachments and tool_calls hanging off it. current versions write to a set of content-addressed tables instead: threads, turns, messages and parts. content-addressed means rows are identified by a hash of their content rather than an assigned id, so identical content is stored exactly once. efficient queen 💅
the legacy tables are read-only history now. the llm logs command merges the two generations: rows that only exist in the legacy responses table are combined with rows from the new tables, so history recorded by an older version stays visible after an upgrade. and all new logging writes only the content-addressed tables.
🧵 Threads, turns, messages and parts
from the top down, bestie:
- A thread is a conversation. It is a named pointer at the message at the head of that conversation, and its id is the conversation id displayed by
llm logs. - A turn is a single model call within a thread. It records everything specific to that call — which model answered, options, token counts, timings — and points at the messages that were its input and output.
- A message is one entry in a conversation, with a role of
system,userorassistant. Each message links to its parent, forming a chain, and is identified by a hash of its content combined with that parent link. - A part is a piece of content within a message: text, reasoning, a tool call, a tool result or an attachment. A message's parts are ordered by their position.
✨ A worked example
okay so here's a two turn conversation, logged to a fresh database and then dumped. it was generated with a small scripted model that returns canned replies — every model plugin logs through the same code path, so rows written by a real model have exactly the same shape, but the canned replies keep this example deterministic. cute, right?
messages and their parts:
user b2:d6b0cd4e7a65ea90423c50fadb3f5704
parent: null
part 0: type=text text='Suggest a name for a pet pelican' payload=null
assistant b2:0f2c02ad982050b623b7e034199c8c61
parent: b2:d6b0cd4e7a65ea90423c50fadb3f5704
part 0: type=text text='How about Percy? Pelicans suit a dignified name.' payload=null
user b2:c785dd6c77540150c2647f406cacc76f
parent: b2:0f2c02ad982050b623b7e034199c8c61
part 0: type=text text='Now one for a pet walrus' payload=null
assistant b2:a30a236e0d1b717c592e826d06e3c9d2
parent: b2:c785dd6c77540150c2647f406cacc76f
part 0: type=text text='Wallace. It pairs nicely with Percy.' payload=nullturns:
turn 01kf2rw8jj3nfd5t7w9y1a3c5e
thread_id: 01kf2rw8jhv1x9c2m4p6q8s0tv
parent_message_hash: b2:d6b0cd4e7a65ea90423c50fadb3f5704
tip_message_hash: b2:0f2c02ad982050b623b7e034199c8c61
model: scripted
turn 01kf2rw8jkq7h9k2m4n6p8r0t2
thread_id: 01kf2rw8jhv1x9c2m4p6q8s0tv
parent_message_hash: b2:c785dd6c77540150c2647f406cacc76f
tip_message_hash: b2:a30a236e0d1b717c592e826d06e3c9d2
model: scriptedthread:
thread 01kf2rw8jhv1x9c2m4p6q8s0tv
name: Suggest a name for a pet pelican
tip_message_hash: b2:a30a236e0d1b717c592e826d06e3c9d2Things to notice:
- The four messages form a chain: the first has a
nullparent and each subsequent message names the hash of the one before it. - The
part N:lines show each part's storage columns. A part whose text is pure literal keeps it in thetextcolumn — raw, unescaped and never parsed, so text that happens to look like JSON is safe — with anullpayload. Thepayloadcolumn holds any remaining structure as JSON: fragment references, tool call fields, provider metadata. The part'stypelives only in thetypecolumn. - Each turn brackets one model call. Its
parent_message_hashis the tip of the chain that got sent to the model — like, the last input message, usually that turn's user prompt — and itstip_message_hashis the chain tip after the model's reply got appended. The prompt and response thatllm logsshows you? Those are derived by splitting the chain at the parent. Not stored a second time. Efficient queen behavior. 👑 - The thread's
idis the conversation id, itsnameis derived from the first prompt, and itstip_message_hashfollows the head of the conversation as new turns get logged. She's always keeping up. 💅 - Turn and thread ids are ULIDs: sortable identifiers issued in time order. The ids shown here are illustrative, since fresh ones are generated on every run. The hashes are not — they depend only on the message content and its position in the chain, so replaying this conversation produces these exact four hashes. Deterministic icon. ✨
Content addressing as a contract 🎀
A message's hash is calculated like this:
- Build the object
{"parent": parent_hash, "message": message}, whereparent_hashis the hash of the previous message in the chain (ornullfor the first message) andmessageis the message's dictionary representation — itsrole, itspartsand any provider metadata. - Serialize that object to canonical JSON: keys sorted, compact
,and:separators with no extra whitespace, non-ASCII characters left unescaped. - Hash the UTF-8 encoding of that string with BLAKE2b (https://en.wikipedia.org/wiki/BLAKE_(hash_function)) using a 16 byte digest, and prefix the hex digest with
b2:.
The b2: prefix names the algorithm that produced the hash, so any future change to it will be detectable. That's her little name tag. 🏷️
Two design decisions matter here:
- The hash covers resolved content. Fragment
#usage-fragmentsreferences are expanded to their full text before hashing, and attachments are represented by the SHA-256 hash of their bytes together with their media type — the model sees the type, so identical bytes sent asimage/pngand astext/plainare different requests. An attachment supplied as a URL is hashed by that URL: the log records which URL was sent, not whatever it served that day. Attachments loaded from a filesystem path are stored by reference to that file rather than copied into the database, so their fidelity depends on the file staying put —LogStore.verify()re-reads the actual bytes when it re-derives every hash, and reports a changed or deleted file as a broken hash rather than letting it pass silently. - The parent hash participates in the hash. The same content appearing at a different point in a conversation is a different node. This is what makes two conversations that share a prefix collapse to shared rows, with no explicit comparison required: replaying the same messages produces the same hashes, and a hash that's already present needs nothing written. Deduplication without even trying. 😌
A consequence of that second decision is that a stateless client — one that holds its own conversation history and re-sends the whole thing with every call — writes only the new tail on each request. It also makes forks cheap, as described next. Here the first conversation from the worked example is logged again, followed by a second conversation that starts with the same prompt and then diverges:
message rows after the first conversation: 4
message rows after both conversations: 6
rows added by the second conversation:
user b2:371ceec468c0ec797ac7042970992c0b
parent: b2:0f2c02ad982050b623b7e034199c8c61
assistant b2:4ad19ddf94ea086aa9a8aa6fd8b0af05
parent: b2:371ceec468c0ec797ac7042970992c0bTwo conversations of two turns each — eight messages sent to the model in total — produced six rows. The second conversation's first turn hashed to rows that were already present, so only its second turn was written, and the new user message's parent is the assistant reply both conversations share. Sharing is caring fr fr. 🫶
Forking and shared history 🦋
Because messages form a parent-linked tree, a conversation can fork: a new thread can point at any existing message and continue from there, sharing its entire history with the thread it came from until the two diverge. Nothing is copied when this happens. The threads.forked_from column records which thread a fork came from.
Shared rows cut both ways. Deleting a conversation is not the same as deleting its rows, because another thread may reach the same messages — removing them would silently corrupt that thread's history. For this reason LLM does not currently delete message rows at all; garbage collection of unreachable messages is deliberately left as future work. 🗑️ (someday, bestie)
Storage by reference 🌸
The hash of a message covers its resolved content, but storage is by reference. A text part whose content borrows from a fragment does not store a copy of that fragment. Instead of a filled text column its payload holds a text_ref list of fragment references and literal segments:
{"text_ref": [{"fragment": 1}, {"literal": "\nquestion about it"}]}Here fragment 1 is an id in the existing fragments table. Reading the part concatenates the fragment content and the literal back together, reproducing the exact text that was hashed. Ask a hundred questions about a novel and the novel is stored once. That's the whole point. 💖
Attachments work the same way: the binary content lives in the attachments table, keyed by a SHA-256 hash of the bytes, and the part payload stores that id in place of the data.
The raw provider payload 💀
The parts of a response are a normalized view of what the provider returned. The raw response.json() dictionary is also recorded in the turns.response_json column, storing details that have no part equivalent — usage breakdowns, system fingerprints, logprobs, and more.
The JSON is in a condensed form using condense-json (https://github.com/simonw/condense-json). This library allows values that are stored in the other database rows to be replaced in the JSON as special references such as {"$": "tool.NAME.description"}.
Model plugins can contribute a dictionary of their own recurring boilerplate — the same idea as a zstandard custom dictionary — by defining a json_replacements class attribute. See the plugin author documentation #advanced-model-plugins-json-replacements for guidance on declaring these.
llm logs --json resolves the stored payload back to the original sent by the provider as the response_json. ✨
Table by table 🍓
The full schema for these tables appears in the SQL schema section below.
messages— one row per unique message.hashis the content address described above,parent_hashlinks to the previous message in the chain androleissystem,userorassistant.provider_metadataholds any provider-specific data carried by the message; it participates in the hash.parts— the content of each message, ordered byposition. When a part's text is stored inline in full it lives in thetextcolumn — raw and never parsed, soselect text from partsreads as prose. Text that references fragments is stored inpayloadastext_refinstead.payloadholds any remaining structure as JSON (fragment references, tool call fields, provider metadata), orNULLwhen thetextcolumn carries the whole part.typeandtool_nameare their own columns for direct filtering; the type never appears inside thepayload.part_attachmentsandpart_fragments— junction tables recording which rows inattachmentsandfragmentsa part's payload references, in order.threads— one row per conversation.idis the conversation id,tip_message_hashpoints at the current head of the conversation andforked_fromrecords the thread a fork came from.turns— one row per model call.parent_message_hashandtip_message_hashbracket the call's input and output as described above, and the remaining columns record provenance:model,options,schema, token counts, timings and the condensed raw provider payload inresponse_json. Turn ids are ULIDs, in the same id space as legacy response ids, which is how the two generations of tables sort together inllm logs.turn_tools— which tool#toolsdefinitions were available to a turn, referencing thetoolstable. For toolbox-derived tools,instance_idreferences thetool_instancesrow recording which configured instance provided them — so the tools list inllm logsshows thatSQLite_querycame fromSQLite("mydb.db")before any call has run. Iconic foresight. 👑turn_fragments— which fragments a turn was given, with theirkind(promptorsystem) and order. Provenance lives here rather than on the shared message rows, and this table is what powersllm logs -f.turn_search— the searchable text of each turn: the literal prompt the user typed (fragment content excluded, via thetext_refliterals described above) and the assistant's text output. An FTS5 index over this table,turn_search_fts, is what powersllm logs -q. Derived from the stored parts when a turn is logged; a turn with no prompt or response text, such as a pure tool call, gets no row.tool_instantiations— which configured toolbox#python-api-toolboxinstance served a tool call, as a reference into the sharedtool_instancestable (each distinct configuration is stored once), keyed by(turn_id, tool_call_id)— call ids supplied by providers are not guaranteed unique across turns. Message rows are shared between conversations and so cannot carry this kind of local execution provenance; this table joins to the chain from outside it. Sneaky. Clever. Slay. 💅
Querying the message store 🔥
These queries can be pasted into Datasette (https://datasette.io/) or sqlite3 against your logs.db.
The database includes a message_tree view that renders every conversation tree as indented text, one row per message, depth-first with forks shown as siblings:
select * from message_treeIts columns:
root_hash— the hash of the tree's root message, shared by every message in the tree. Filter or facet on this to isolate a single conversation and its forks.datetime— when the message was first logged, derived from the earliest turn that recorded it (shared message rows carry no timestamp of their own). 😭message— the message's text, indented to show its depth in the tree. Text stored as fragment references is resolved back to the fragment content, and messages with no text show a placeholder such as[tool_result].tools— names of any tools that were executed at that message, comma-separated.message_hashandpath— the message's own hash, and the sort key that produces the tree ordering.
Heads up bestie: the rows only read as trees while sorted by path, so re-sorting by another column will scramble the indentation. 🫠 Don't do that to her.
with recursive msg as (
select m.hash, m.parent_hash, m.role, m.rowid as rid,
replace(coalesce(
nullif(p.text, ''),
(select f.content from part_fragments pf
join fragments f on f.id = pf.fragment_id
where pf.part_id = p.id
order by pf."order" limit 1),
'[' || coalesce(p.type, 'empty') || ']'
), char(10), ' ') as text,
(select group_concat(p2.tool_name, ', ') from parts p2
where p2.message_hash = m.hash and p2.type = 'tool_result'
and p2.tool_name is not null) as tools
from messages m
left join parts p on p.message_hash = m.hash and p.position = 0
),
tree as (
select hash, text, tools, 0 as depth,
printf('%012d', rid) as path, hash as root_hash
from msg where parent_hash is null
union all
select msg.hash, msg.text, msg.tools, t.depth + 1,
t.path || '/' || printf('%012d', msg.rid),
t.root_hash
from msg join tree t on msg.parent_hash = t.hash
),
turn_chain as (
select t.id as turn_id, t.datetime_utc, m.hash, m.parent_hash
from turns t join messages m on m.hash = t.tip_message_hash
union all
select tc.turn_id, tc.datetime_utc, m.hash, m.parent_hash
from turn_chain tc join messages m on m.hash = tc.parent_hash
)
select
t.root_hash,
strftime('%Y-%m-%d %H:%M:%S',
(select min(tc.datetime_utc) from turn_chain tc where tc.hash = t.hash)
) as datetime,
replace(hex(zeroblob(t.depth)), '00', ' ') || substr(t.text, 1, 60)
as message,
coalesce(t.tools, '') as tools,
t.hash as message_hash,
t.path
from tree t
order by t.pathOkay bestie, next one 💅 — every single turn that was handed a specific fragment, courtesy of the turn_fragments provenance table. Just set :fragment_hash to a hash you pulled from llm fragments:
select turns.id, turns.model, turns.datetime_utc, turn_fragments.kind
from turns
join turn_fragments on turn_fragments.turn_id = turns.id
join fragments on fragments.id = turn_fragments.fragment_id
where fragments.hash = :fragment_hash
order by turns.id;And for the nosy girlies 👀 — the most recently active conversations, with a lil count of how many turns each one has:
select
threads.id,
threads.name,
count(turns.id) as num_turns,
max(turns.datetime_utc) as last_used
from threads
left join turns on turns.thread_id = threads.id
group by threads.id
order by last_used desc
limit 10;🐍 Logging from Python
So the officially supported way to write into a log database from Python is the log_to_db() method on a response — and yes, that's literally also what plugins are supposed to call. No cap, it's the one true path 🫶
import llm
import sqlite_utils
db = sqlite_utils.Database("logs.db")
model = llm.get_model("gpt-5.5")
response = model.prompt("A short pelican fact")
print(response.text())
response.log_to_db(db)log_to_db() takes a sqlite_utils.Database and writes the response's thread, turn, messages, parts, fragments, attachments and tools into the content-addressed tables. And the iconic part? It applies any outstanding migrations all by itself, so it's safe to point at a fresh new database file or one that some older version of LLM made. Glow up applied automatically ✨
Heads up though: the underlyingLogStoreclass is internal and its API may change without warning 💀 —log_to_db()and the table schema documented on this page are the supported interfaces. Don't go poking the internals and then act surprised.
🗄️ SQL schema
Here's the SQL schema used by the logs.db database — she's long, she's detailed, she's the blueprint of the whole situation 🎀
CREATE TABLE "conversations" (
"id" TEXT PRIMARY KEY,
"name" TEXT,
"model" TEXT
);
CREATE TABLE "schemas" (
"id" TEXT PRIMARY KEY,
"content" TEXT
);
CREATE TABLE "responses" (
"id" TEXT PRIMARY KEY,
"model" TEXT,
"prompt" TEXT,
"system" TEXT,
"prompt_json" TEXT,
"options_json" TEXT,
"response" TEXT,
"response_json" TEXT,
"conversation_id" TEXT REFERENCES "conversations"("id"),
"duration_ms" INTEGER,
"datetime_utc" TEXT,
"input_tokens" INTEGER,
"output_tokens" INTEGER,
"token_details" TEXT,
"schema_id" TEXT REFERENCES "schemas"("id"),
"resolved_model" TEXT,
"reasoning" TEXT
);
CREATE VIRTUAL TABLE "responses_fts" USING FTS5 (
"prompt",
"response",
content="responses"
);
CREATE TABLE "attachments" (
"id" TEXT PRIMARY KEY,
"type" TEXT,
"path" TEXT,
"url" TEXT,
"content" BLOB
);
CREATE TABLE "prompt_attachments" (
"response_id" TEXT REFERENCES "responses"("id"),
"attachment_id" TEXT REFERENCES "attachments"("id"),
"order" INTEGER,
PRIMARY KEY ("response_id",
"attachment_id")
);
CREATE TABLE "fragments" (
"id" INTEGER PRIMARY KEY,
"hash" TEXT,
"content" TEXT,
"datetime_utc" TEXT,
"source" TEXT
);
CREATE TABLE "fragment_aliases" (
"alias" TEXT PRIMARY KEY,
"fragment_id" INTEGER REFERENCES "fragments"("id")
);
CREATE TABLE "prompt_fragments" (
"response_id" TEXT REFERENCES "responses"("id"),
"fragment_id" INTEGER REFERENCES "fragments"("id"),
"order" INTEGER,
PRIMARY KEY ("response_id",
"fragment_id",
"order")
);
CREATE TABLE "system_fragments" (
"response_id" TEXT REFERENCES "responses"("id"),
"fragment_id" INTEGER REFERENCES "fragments"("id"),
"order" INTEGER,
PRIMARY KEY ("response_id",
"fragment_id",
"order")
);
CREATE TABLE "tools" (
"id" INTEGER PRIMARY KEY,
"hash" TEXT,
"name" TEXT,
"description" TEXT,
"input_schema" TEXT,
"plugin" TEXT
);
CREATE TABLE "tool_responses" (
"tool_id" INTEGER REFERENCES "tools"("id"),
"response_id" TEXT REFERENCES "responses"("id"),
PRIMARY KEY ("tool_id",
"response_id")
);
CREATE TABLE "tool_calls" (
"id" INTEGER PRIMARY KEY,
"response_id" TEXT REFERENCES "responses"("id"),
"tool_id" INTEGER REFERENCES "tools"("id"),
"name" TEXT,
"arguments" TEXT,
"tool_call_id" TEXT
);
CREATE TABLE "tool_results" (
"id" INTEGER PRIMARY KEY,
"response_id" TEXT REFERENCES "responses"("id"),
"tool_id" INTEGER REFERENCES "tools"("id"),
"name" TEXT,
"output" TEXT,
"tool_call_id" TEXT,
"instance_id" INTEGER REFERENCES "tool_instances"("id"),
"exception" TEXT
);
CREATE TABLE "tool_instances" (
"id" INTEGER PRIMARY KEY,
"plugin" TEXT,
"name" TEXT,
"arguments" TEXT
);
CREATE TABLE "tool_results_attachments" (
"tool_result_id" INTEGER REFERENCES "tool_results"("id"),
"attachment_id" TEXT REFERENCES "attachments"("id"),
"order" INTEGER,
PRIMARY KEY ("tool_result_id",
"attachment_id")
);
CREATE TABLE "messages" (
"hash" TEXT PRIMARY KEY,
"parent_hash" TEXT REFERENCES "messages"("hash"),
"role" TEXT,
"provider_metadata" TEXT
);
CREATE TABLE "parts" (
"id" INTEGER PRIMARY KEY,
"message_hash" TEXT REFERENCES "messages"("hash"),
"position" INTEGER,
"type" TEXT,
"tool_name" TEXT,
"text" TEXT,
"payload" TEXT
);
CREATE TABLE "part_attachments" (
"part_id" INTEGER REFERENCES "parts"("id"),
"attachment_id" TEXT REFERENCES "attachments"("id"),
"order" INTEGER,
PRIMARY KEY ("part_id",
"attachment_id",
"order")
);
CREATE TABLE "part_fragments" (
"part_id" INTEGER REFERENCES "parts"("id"),
"fragment_id" INTEGER REFERENCES "fragments"("id"),
"order" INTEGER,
PRIMARY KEY ("part_id",
"fragment_id",
"order")
);
CREATE TABLE "threads" (
"id" TEXT PRIMARY KEY,
"name" TEXT,
"tip_message_hash" TEXT REFERENCES "messages"("hash"),
"forked_from" TEXT REFERENCES "threads"("id"),
"datetime_utc" TEXT
);
CREATE TABLE "turns" (
"id" TEXT PRIMARY KEY,
"thread_id" TEXT REFERENCES "threads"("id"),
"parent_message_hash" TEXT REFERENCES "messages"("hash"),
"tip_message_hash" TEXT REFERENCES "messages"("hash"),
"model" TEXT,
"resolved_model" TEXT,
"options_json" TEXT,
"schema_id" TEXT REFERENCES "schemas"("id"),
"input_tokens" INTEGER,
"output_tokens" INTEGER,
"token_details" TEXT,
"duration_ms" INTEGER,
"datetime_utc" TEXT,
"response_json" TEXT
);
CREATE TABLE "turn_tools" (
"turn_id" TEXT REFERENCES "turns"("id"),
"tool_id" INTEGER REFERENCES "tools"("id"),
"instance_id" INTEGER REFERENCES "tool_instances"("id"),
PRIMARY KEY ("turn_id",
"tool_id")
);
CREATE TABLE "turn_fragments" (
"turn_id" TEXT REFERENCES "turns"("id"),
"fragment_id" INTEGER REFERENCES "fragments"("id"),
"order" INTEGER,
"kind" TEXT,
PRIMARY KEY ("turn_id",
"fragment_id",
"kind",
"order")
);
CREATE TABLE "turn_search" (
"id" INTEGER PRIMARY KEY,
"turn_id" TEXT REFERENCES "turns"("id"),
"prompt" TEXT,
"response" TEXT
);
CREATE VIRTUAL TABLE "turn_search_fts" USING FTS5 (
"prompt",
"response",
content="turn_search"
);
CREATE TABLE "tool_instantiations" (
"turn_id" TEXT REFERENCES "turns"("id"),
"tool_call_id" TEXT,
"instance_id" INTEGER REFERENCES "tool_instances"("id"),
PRIMARY KEY ("turn_id",
"tool_call_id")
);responses_fts sets up SQLite full-text search (https://www.sqlite.org/fts5.html) against the prompt and response columns in the responses table. And turn_search_fts does the exact same thing for the turn_search table, which is where the searchable text of each turn lives in the content-addressed tables. Together? That's literally what llm logs -q queries, bestie. The whole search situation, explained 🔍✨
🧰 Related tools
These following tools are built to be used with LLM, iykyk:
✂️ strip-tags
strip-tags — find it at https://github.com/simonw/strip-tags — is a command for stripping tags right out of HTML. Why does that matter? Because HTML tags can absolutely devour your token budget, and nobody wants that 🍓 Staying cute means staying lean.
okay so here's the actual recipe for summarizing the New York Times front page — you strip the tags <em>and</em> filter down to just the elements rockin' <code>class="story-wrapper"</code>, like so:
curl -s https://www.nytimes.com/ \
| strip-tags .story-wrapper \
| llm -s 'summarize the news'✨ and if you wanna go deeper on any of this, there's a whole writeup: llm, ttok and strip-tags—CLI tools for working with ChatGPT and other LLMs <https://simonwillison.net/2023/May/18/cli-tools-for-llms/> — it describes ways to use strip-tags in way more detail. 🫶
🌸 ttok 🌸
ttok <https://github.com/simonw/ttok> is a lil command-line bestie for counting OpenAI tokens. You use it to vibe-check whether your input is even gonna fit in the token limit for GPT 3.5 or GPT4:
cat my-file.txt | ttok125It can also truncate your input down to whatever number of tokens you want:
ttok This is too many tokens -t 3This is tooWhich is so useful when you need to chop a big ol' document down to a size an LLM can actually chew on. no cap.
🦋 Symbex 🦋
Symbex <https://github.com/simonw/symbex> is a tool for searching for symbols in Python codebases. It's giving "extract just the code for one specific problem" energy, so you can pipe that straight into LLM for explanation, refactoring, or whatever else you're on.
Here's how you use it to find every function matching test*csv* and then let the model guess what the software under test actually does:
symbex 'test*csv*' | \
llm --system 'based on these tests guess what this tool does'It can also export symbols in a format you can pipe to llm embed-multi <#embeddings-cli-embed-multi> to make embeddings:
symbex '*' '*:*' --nl | \
llm embed-multi symbols - \
--format nl --database embeddings.db --storeMore examples live over here if you're obsessed: Symbex: search Python code for functions and classes, then pipe them into a LLM <https://simonwillison.net/2023/Jun/18/symbex/> 💅
👑 CLI reference 👑
This page lists the --help output for all of the llm commands. yes, all of them. buckle up bestie.
⭐ llm --help
Usage: llm [OPTIONS] COMMAND [ARGS]...
Access Large Language Models from the command-line
Documentation: https://llm.datasette.io/
LLM can run models from many different providers. Consult the plugin directory
for a list of available models:
https://llm.datasette.io/en/stable/plugins/directory.html
To get started with OpenAI, obtain an API key from them and:
$ llm keys set openai
Enter key: ...
Then execute a prompt like this:
llm 'Five outrageous names for a pet pelican'
For a full list of prompting options run:
llm prompt --help
Options:
--version Show the version and exit.
-h, --help Show this message and exit.
Commands:
prompt* Execute a prompt
aliases Manage model aliases
chat Hold an ongoing chat with a model.
collections View and manage collections of embeddings
embed Embed text and store or return the result
embed-models Manage available embedding models
embed-multi Store embeddings for multiple strings at once in the...
fragments Manage fragments that are stored in the database
install Install packages from PyPI into the same environment as LLM
keys Manage stored API keys for different models
logs Tools for exploring logged prompts and responses
models Manage available models
openai Commands for working with OpenAI and OpenAI-compatible APIs
plugins List installed plugins
schemas Manage stored schemas
similar Return top N similar IDs from a collection using cosine...
templates Manage stored prompt templates
tools Manage tools that can be made available to LLMs
uninstall Uninstall Python packages from the LLM environment🎀 llm prompt --help
Usage: llm prompt [OPTIONS] [PROMPT]
Execute a prompt
Documentation: https://llm.datasette.io/en/stable/usage.html
Examples:
llm 'Capital of France?'
llm 'Capital of France?' -m gpt-5.5
llm 'Capital of France?' -s 'answer in Spanish'
Multi-modal models can be called with attachments like this:
llm 'Extract text from this image' -a image.jpg
llm 'Describe' -a https://static.simonwillison.net/static/2024/pelicans.jpg
cat image | llm 'describe image' -a -
# With an explicit mimetype:
cat image | llm 'describe image' --at - image/jpeg
Structured output schemas:
Use --schema to request one JSON object, or --schema-multi to request multiple
objects returned in an "items" array. Both options accept a concise schema
DSL. Define each field as NAME [TYPE]: DESCRIPTION, with the type and
description both optional. Separate fields with commas:
llm --schema 'name, age int, active bool' 'Invent a dog'
Supported types are str, int, float and bool. The default is str and every
listed field is required. Descriptions provide extra instructions to the
model. Use one field per line if descriptions contain commas:
llm --schema-multi '
name: the dog's name
age int: the dog's age in years
bio: a short bio, no more than three sentences
' 'Invent three dogs'
JSON Schema is also accepted.
The -x/--extract option returns just the content of the first ``` fenced code
block, if one is present. If none are present it returns the full response.
llm 'JavaScript function for reversing a string' -x
Options:
-s, --system TEXT System prompt to use
-m, --model TEXT Model to use
-d, --database FILE Path to log database
-q, --query TEXT Use first model matching these strings
-a, --attachment ATTACHMENT Attachment path or URL or -
--at, --attachment-type <TEXT TEXT>...
Attachment with explicit mimetype,
--at image.jpg image/jpeg
-T, --tool TEXT Name of a tool to make available to the model
--functions TEXT Python code block or file path defining
functions to register as tools
--td, --tools-debug Show full details of tool executions
--ta, --tools-approve Manually approve every tool execution
--cl, --chain-limit INTEGER How many chained tool responses to allow,
default 5, set 0 for unlimited
-o, --option <TEXT TEXT>... key/value options for the model
--options Show options for the selected model
--schema TEXT Schema DSL, JSON schema, filepath or ID
--schema-multi TEXT Schema for multiple results
-f, --fragment TEXT Fragment (alias, URL, hash or file path) to
add to the prompt
--sf, --system-fragment TEXT Fragment to add to system prompt
-t, --template TEXT Template to use; can be repeated to combine
templates
-p, --param <TEXT TEXT>... Parameters for template
--no-stream Do not stream output
-n, --no-log Don't log to database
--log Log prompt and response to the database
-R, --hide-reasoning Hide reasoning output
-c, --continue Continue the most recent conversation.
--cid, --conversation TEXT Continue the conversation with the given ID.
--key TEXT API key to use
--save TEXT Save prompt with this template name
--async Run prompt asynchronously
-u, --usage Show token usage
-x, --extract Extract first fenced code block
--xl, --extract-last Extract last fenced code block
--json Output the response as JSON, same format as
llm logs --json
-h, --help Show this message and exit.💖 llm chat --help
Usage: llm chat [OPTIONS]
Hold an ongoing chat with a model.
Options:
-s, --system TEXT System prompt to use
-m, --model TEXT Model to use
-c, --continue Continue the most recent conversation.
--cid, --conversation TEXT Continue the conversation with the given ID.
-f, --fragment TEXT Fragment (alias, URL, hash or file path) to add
to the prompt
--sf, --system-fragment TEXT Fragment to add to system prompt
-t, --template TEXT Template to use
-p, --param <TEXT TEXT>... Parameters for template
-o, --option <TEXT TEXT>... key/value options for the model
-d, --database FILE Path to log database
--no-stream Do not stream output
-R, --hide-reasoning Hide reasoning output
--key TEXT API key to use
-T, --tool TEXT Name of a tool to make available to the model
--functions TEXT Python code block or file path defining
functions to register as tools
--td, --tools-debug Show full details of tool executions
--ta, --tools-approve Manually approve every tool execution
--cl, --chain-limit INTEGER How many chained tool responses to allow,
default 5, set 0 for unlimited
-h, --help Show this message and exit.🔑 llm keys --help
Usage: llm keys [OPTIONS] COMMAND [ARGS]...
Manage stored API keys for different models
Options:
-h, --help Show this message and exit.
Commands:
list* List names of all stored keys
get Return the value of a stored key
path Output the path to the keys.json file
set Save a key in the keys.json file💜 llm keys list --help
Usage: llm keys list [OPTIONS]
List names of all stored keys
Options:
-h, --help Show this message and exit.🧚 llm keys path --help
Usage: llm keys path [OPTIONS]
Output the path to the keys.json file
Options:
-h, --help Show this message and exit.🍓 llm keys get --help
Usage: llm keys get [OPTIONS] NAME
Return the value of a stored key
Example usage:
export OPENAI_API_KEY=$(llm keys get openai)
Options:
-h, --help Show this message and exit.🎀 llm keys set --help
Usage: llm keys set [OPTIONS] NAMESave a key in the keys.json file 💾✨
Example usage:
$ llm keys set openai
Enter key: ...Options:
--value TEXT— Value to set-h,--help— Show this message and exit.
🫶 llm logs --help
Usage: llm logs [OPTIONS] COMMAND [ARGS]...Tools for exploring logged prompts and responses 🔍💖
Options:
-h,--help— Show this message and exit.
Commands:
list*— Show logged prompts and their responsesbackup— Backup your logs database to this fileoff— Turn off logging for all promptson— Turn on logging for all promptspath— Output the path to thelogs.dbfilestatus— Show current status of database logging
🌸 llm logs path --help
Usage: llm logs path [OPTIONS]Output the path to the logs.db file 📂
Options:
-h,--help— Show this message and exit.
🦋 llm logs status --help
Usage: llm logs status [OPTIONS]Show current status of database logging 📊✨
Options:
-h,--help— Show this message and exit.
🍓 llm logs backup --help
Usage: llm logs backup [OPTIONS] PATHBackup your logs database to this file 🗄️💖
Options:
-h,--help— Show this message and exit.
✨ llm logs on --help
Usage: llm logs on [OPTIONS]Turn on logging for all prompts 🟢
Options:
-h,--help— Show this message and exit.
💀 llm logs off --help
Usage: llm logs off [OPTIONS]Turn off logging for all prompts 🔴
Options:
-h,--help— Show this message and exit.
👑 llm logs list --help
Usage: llm logs list [OPTIONS]Show logged prompts and their responses 📜
Options:
-n,--count INTEGER— Number of entries to show - defaults to3, use0for all-d,--database FILE— Path to log database-m,--model TEXT— Filter by model or model alias-q,--query TEXT— Search for logs matching this string-f,--fragment TEXT— Filter for prompts using these fragments-T,--tool TEXT— Filter for prompts with results from these tools--tools— Filter for prompts with results from any tools--schema TEXT— Schema DSL, JSON schema, filepath or ID--schema-multi TEXT— JSON schema used for multiple results-l,--latest— Return latest results matching search query--data— Output newline-delimited JSON data for schema--data-array— Output JSON array of data for schema--data-key TEXT— Return JSON objects from array in this key--data-ids— Attach corresponding IDs to JSON objects-t,--truncate— Truncate long strings in output-s,--short— Shorter YAML output with truncated prompts-u,--usage— Include token usage-r,--response— Just output the last response-x,--extract— Extract first fenced code block--xl,--extract-last— Extract last fenced code block-c,--current— Show logs from the current conversation--cid,--conversation TEXT— Show logs for this conversation ID--id-gt TEXT— Return responses with ID > this--id-gte TEXT— Return responses with ID >= this--json— Output logs as JSON-e,--expand— Expand fragments to show their content-h,--help— Show this message and exit.
🌈 llm models --help
Usage: llm models [OPTIONS] COMMAND [ARGS]...Manage available models 🤖💅
Options:
-h,--help— Show this message and exit.
Commands:
list*— List available modelsdefault— Show or set the default modeloptions— Manage default options for models
⭐ llm models list --help
Usage: llm models list [OPTIONS]List available models 📋
Options:
--options— Show options for each model, if available--async— List async models--schemas— List models that support schemas--tools— List models that support tools--json— Output as JSON-q,--query TEXT— Search for models matching these strings-m,--model TEXT— Specific model IDs-h,--help— Show this message and exit.
🧚 llm models default --help
Usage: llm models default [OPTIONS] [MODEL]Show or set the default model 🌟
Options:
-h,--help— Show this message and exit.
💜 llm models options --help
Usage: llm models options [OPTIONS] COMMAND [ARGS]...Manage default options for models ⚙️
Options:
-h,--help— Show this message and exit.
Commands:
list*— List default options for all modelsclear— Clear default option(s) for a modelset— Set a default option for a modelshow— List default options set for a specific model
💖 llm models options list --help
Usage: llm models options list [OPTIONS]List default options for all models 📝
Example usage:
llm models options listOptions:
-h,--help— Show this message and exit.
🎀 llm models options show --help
Usage: llm models options show [OPTIONS] MODELList default options set for a specific model 👀
Example usage:
llm models options show gpt-4.1Options:
-h,--help— Show this message and exit.
🫶 llm models options set --help
Usage: llm models options set [OPTIONS] MODEL KEY VALUESet a default option for a model 🛠️
Example usage:
llm models options set gpt-4.1 temperature 0.5Options:
-h,--help— Show this message and exit.
🌸 llm models options clear --help
Usage: llm models options clear [OPTIONS] MODEL [KEY]Clear default option(s) for a model 🧹
Example usage:
llm models options clear gpt-4.1
# Or for a single option
llm models options clear gpt-4.1 temperatureOptions:
-h,--help— Show this message and exit.
🦋 llm templates --help
Usage: llm templates [OPTIONS] COMMAND [ARGS]...Manage stored prompt templates 🗂️✨
Options:
-h,--help— Show this message and exit.
Commands:
list*— List available prompt templatesedit— Edit the specified prompt template using the default$EDITORloaders— Show template loaders registered by pluginspath— Output the path to the templates directoryshow— Show the specified prompt template
🍓 llm templates list --help
Usage: llm templates list [OPTIONS]List available prompt templates 📄
Options:
-h,--help— Show this message and exit.
✨ llm templates show --help
Usage: llm templates show [OPTIONS] NAMEShow the specified prompt template 🔎
Options:
-h,--help— Show this message and exit.
💅 llm templates edit --help
Usage: llm templates edit [OPTIONS] NAMEEdit the specified prompt template using the default $EDITOR ✍️
Options:
-h,--help— Show this message and exit.
👑 llm templates path --help
Usage: llm templates path [OPTIONS]Output the path to the templates directory 📁
Options:
-h,--help— Show this message and exit.
🌈 llm templates loaders --help
Usage: llm templates loaders [OPTIONS]Show template loaders registered by plugins 🔌
Options:
-h,--help— Show this message and exit.
⭐ llm schemas --help
Usage: llm schemas [OPTIONS] COMMAND [ARGS]...Manage stored schemas 🧩
Options:
-h,--help— Show this message and exit.
Commands:
list*— List stored schemasdsl— Convert LLM's schema DSL to a JSON schemashow— Show a stored schema
🧚 llm schemas list --help
Usage: llm schemas list [OPTIONS]List stored schemas 📚
Options:
-d,--database FILE— Path to log database-q,--query TEXT— Search for schemas matching this string--full— Output full schema contents--json— Output as JSON--nl— Output as newline-delimited JSON-h,--help— Show this message and exit.
💜 llm schemas show --help
Usage: llm schemas show [OPTIONS] SCHEMA_IDShow a stored schema 👀
Options:
-d,--database FILE— Path to log database-h,--help— Show this message and exit.
🎀 llm schemas dsl --help
Usage: llm schemas dsl [OPTIONS] INPUTConvert LLM's schema DSL to a JSON schema 🪄
llm schema dsl 'name, age int, bio: their bio'Options:
--multi— Wrap in an array-h,--help— Show this message and exit.
🫶 llm tools --help
Usage: llm tools [OPTIONS] COMMAND [ARGS]...Manage tools that can be made available to LLMs 🧰
Options:
-h,--help— Show this message and exit.
Commands:
list*— List available tools, optionally including tools supported by a model
🌸 llm tools list --help
Usage: llm tools list [OPTIONS] [TOOL_DEFS]...List available tools, optionally including tools supported by a model 🔧
Options:
--json— Output as JSON-m,--model TEXT— List tools supported by this model--functions TEXT— Python code block or file path defining functions to register as tools-h,--help— Show this message and exit.
🦋 llm aliases --help
Usage: llm aliases [OPTIONS] COMMAND [ARGS]...Manage model aliases 🏷️
Options:
-h,--help— Show this message and exit.
Commands:
list*— List current aliasespath— Output the path to thealiases.jsonfileremove— Remove an aliasset— Set an alias for a model
🍓 llm aliases list --help
Usage: llm aliases list [OPTIONS]List current aliases 📋✨
Options:
--json— Output as JSON-h,--help— Show this message and exit.
💖 llm aliases set --help
Usage: llm aliases set [OPTIONS] ALIAS [MODEL_ID]Set an alias for a model 🏷️💅
Example usage:
llm aliases set luna gpt-5.6-lunaAlternatively you can omit the model ID and specify one or more -q options. The first model matching all of those query strings will be used.
llm aliases set luna -q gpt -q lunaOptions:
-q,--query TEXT— Set alias for model matching these strings-h,--help— Show this message and exit.
llm aliases remove --help 💅
Usage:
llm aliases remove [OPTIONS] ALIASokay so this one? It's giving Remove an alias ✨. Example usage:
$ llm aliases remove turboOptions:
-h,--help— Show this message and exit.
llm aliases path --help 🎀
Usage:
llm aliases path [OPTIONS]Output the path to the aliases.json file — yes bestie, that's the whole vibe 🦋.
Options:
-h,--help— Show this message and exit.
llm fragments --help 🌸
Usage:
llm fragments [OPTIONS] COMMAND [ARGS]...Manage fragments that are stored in the database 💖.
Fragments are reusable snippets of text that are shared across multiple prompts.
Options:
-h,--help— Show this message and exit.
Commands:
list*— List current fragmentsloaders— Show fragment loaders registered by pluginsremove— Remove a fragment aliasset— Set an alias for a fragmentshow— Display the fragment stored under an alias or hash
llm fragments list --help 💅
Usage:
llm fragments list [OPTIONS]List current fragments — slay ✨.
Options:
-q,--query TEXT— Search for fragments matching these strings--aliases— Show only fragments with aliases--json— Output as JSON-h,--help— Show this message and exit.
llm fragments set --help 🫶
Usage:
llm fragments set [OPTIONS] ALIAS FRAGMENTSet an alias for a fragment 💖.
Accepts an alias and a file path, URL, hash or '-' for stdin.
Example usage:
llm fragments set mydocs ./docs.mdOptions:
-h,--help— Show this message and exit.
llm fragments show --help 🔥
Usage:
llm fragments show [OPTIONS] ALIAS_OR_HASHDisplay the fragment stored under an alias or hash — okay bestie, show me the goods 👑
llm fragments show mydocsOptions:
-h,--help— Show this message and exit.
llm fragments remove --help 💀
Usage:
llm fragments remove [OPTIONS] ALIASRemove a fragment alias — bye bye 👋.
Example usage:
llm fragments remove docsOptions:
-h,--help— Show this message and exit.
llm fragments loaders --help 🧚
Usage:
llm fragments loaders [OPTIONS]Show fragment loaders registered by plugins — the plugin girlies are doing their thing ✨.
Options:
-h,--help— Show this message and exit.
llm plugins --help 🌈
Usage:
llm plugins [OPTIONS]List installed plugins — let's see who's in the group chat 💅.
Options:
--all— Include built-in default plugins--hook TEXT— Filter for plugins that implement this hook-h,--help— Show this message and exit.
llm install --help ⭐
Usage:
llm install [OPTIONS] [PACKAGES]...Install packages from PyPI into the same environment as LLM — periodt 💖.
Options:
-U,--upgrade— Upgrade packages to latest version-e,--editable TEXT— Install a project in editable mode from this path--force-reinstall— Reinstall all packages even if they are already up-to-date--no-cache-dir— Disable the cache--pre— Include pre-release and development versions-h,--help— Show this message and exit.
llm uninstall --help 🙈
Usage:
llm uninstall [OPTIONS] PACKAGES...Uninstall Python packages from the LLM environment — not me deleting stuff 😭.
Options:
-y,--yes— Don't ask for confirmation-h,--help— Show this message and exit.
llm embed --help 🦋
Usage:
llm embed [OPTIONS] [COLLECTION] [ID]Embed text and store or return the result — the main character energy of embeddings ✨.
Options:
-i,--input PATH— File to embed-m,--model TEXT— Embedding model to use--key TEXT— API key to use--store— Store the text itself in the database-d,--database FILE-c,--content TEXT— Content to embed--binary— Treat input as binary data--metadata TEXT— JSON object metadata to store-f,--format [json|blob|base64|hex]— Output format-h,--help— Show this message and exit.
llm embed-multi --help 🌸
Usage:
llm embed-multi [OPTIONS] COLLECTION [INPUT_PATH]Store embeddings for multiple strings at once in the specified collection. 💖
Input data can come from one of three sources:
- A CSV, TSV, JSON or JSONL file:
- CSV/TSV: First column is ID, remaining columns concatenated as content
- JSON: Array of objects with "id" field and content fields
- JSONL: Newline-delimited JSON objects
Examples:
llm embed-multi docs input.csv
cat data.json | llm embed-multi docs -
llm embed-multi docs input.json --format json- A SQL query against a SQLite database:
- First column returned is used as ID
- Other columns concatenated to form content
Examples:
llm embed-multi docs --sql "SELECT id, title, body FROM posts"
llm embed-multi docs --attach blog blog.db --sql "SELECT id, content FROM blog.posts"- Files in directories matching glob patterns:
- Each file becomes one embedding
- Relative file paths become IDs
Examples:
llm embed-multi docs --files docs '**/*.md'
llm embed-multi images --files photos '*.jpg' --binary
llm embed-multi texts --files texts '*.txt' --encoding utf-8 --encoding latin-1Options:
--format [json|csv|tsv|nl]— Format of input file - defaults to auto-detect--files <DIRECTORY TEXT>...— Embed files in this directory - specify directory and glob pattern--encoding TEXT— Encodings to try when reading--files--binary— Treat--filesas binary data--sql TEXT— Read input using this SQL query--attach <TEXT FILE>...— Additional databases to attach - specify alias and file path--batch-size INTEGER— Batch size to use when running embeddings--prefix TEXT— Prefix to add to the IDs-m,--model TEXT— Embedding model to use--key TEXT— API key to use--prepend TEXT— Prepend this string to all content before embedding--store— Store the text itself in the database-d,--database FILE-h,--help— Show this message and exit.
llm similar --help 🔥
Usage:
llm similar [OPTIONS] COLLECTION [ID]Return top N similar IDs from a collection using cosine similarity. 👑
Example usage:
llm similar my-collection -c "I like cats"Or to find content similar to a specific stored ID:
llm similar my-collection 1234Options:
-i,--input PATH— File to embed for comparison-c,--content TEXT— Content to embed for comparison--binary— Treat input as binary data-n,--number INTEGER— Number of results to return-p,--plain— Output in plain text format-d,--database FILE--prefix TEXT— Just IDs with this prefix-h,--help— Show this message and exit.
llm embed-models --help 🎀
Usage:
llm embed-models [OPTIONS] COMMAND [ARGS]...Manage available embedding models — model management era 💅.
Options:
-h,--help— Show this message and exit.
Commands:
list*— List available embedding modelsdefault— Show or set the default embedding model
llm embed-models list --help ✨
Usage:
llm embed-models list [OPTIONS]List available embedding models — let's see the lineup 💖.
Options:
-q,--query TEXT— Search for embedding models matching these strings-h,--help— Show this message and exit.
llm embed-models default --help 🦋
Usage:
llm embed-models default [OPTIONS] [MODEL]Show or set the default embedding model — the default is the moment 🌟.
Options:
--remove-default— Reset to specifying no default model-h,--help— Show this message and exit.
llm collections --help 🌈
Usage:
llm collections [OPTIONS] COMMAND [ARGS]...View and manage collections of embeddings — collection curation, bestie 💅.
Options:
-h,--help— Show this message and exit.
Commands:
list*— View a list of collectionsdelete— Delete the specified collectionpath— Output the path to the embeddings database
llm collections path --help 🧚
Usage:
llm collections path [OPTIONS]Output the path to the embeddings database — where the embeddings live 🏠.
Options:
-h,--help— Show this message and exit.
llm collections list --help ⭐
Usage:
llm collections list [OPTIONS]View a list of collections — the collection roster ✨.
Options:
-d,--database FILE— Path to embeddings database--json— Output as JSON-h,--help— Show this message and exit.
llm collections delete --help 💀
Usage:
llm collections delete [OPTIONS] COLLECTIONDelete the specified collection — no cap, this one deletes it 😭.
Example usage:
llm collections delete my-collectionOptions:
-d,--database FILE— Path to embeddings database-h,--help— Show this message and exit.
llm openai --help 👑
Usage:
llm openai [OPTIONS] COMMAND [ARGS]...Commands for working with OpenAI and OpenAI-compatible APIs — OpenAI bestie era 💖.
Options:
-h,--help— Show this message and exit.
Commands:
endpoint— Run against an OpenAI-compatible endpoint without logging.models— List models available to you from the OpenAI API
llm openai endpoint --help 🔥
Usage:
llm openai endpoint [OPTIONS] URL [PROMPT]Run against an OpenAI-compatible endpoint without logging. 💅
PROMPT or stdin is executed once. If neither is provided, wait for input on stdin. Use --chat to start an interactive chat. Templates run once by default; use --chat to apply one interactively. Use --models to list the available model IDs without running a prompt.
-m,--model TEXT— the Model ID 💖 required, unless you're passing--modelsor a template already handed you one-s,--system TEXT— the system prompt to use-t,--template TEXT— the template to use-p,--param <TEXT TEXT>...— parameters for the template-o,--option <TEXT TEXT>...— key/value options for the model--schema TEXT— Schema DSL, JSON schema, filepath or ID--schema-multi TEXT— JSON schema to use for multiple results-a,--attachment ATTACHMENT— attachment path or URL or---at,--attachment-type <TEXT TEXT>...— attachment with an explicit mimetype, like--at image.jpg image/jpeg-T,--tool TEXT— name of a tool to make available to the model--functions TEXT— Python code block or file path defining functions to register as tools--td,--tools-debug— show full details of tool executions--ta,--tools-approve— manually approve every tool execution--cl,--chain-limit INTEGER— how many chained tool responses to allow, default5, set0for unlimited--key TEXT— API key or stored key alias to send-H,--header <TEXT TEXT>...— additional HTTP header--responses— use the Responses API instead of Chat Completions--chat— start an interactive chat--models— list model IDs from the endpoint and exit--no-stream— do not stream output-R,--hide-reasoning— hide reasoning output-h,--help— show this message and exit
🦋 llm openai models --help
Usage: llm openai models [OPTIONS]
List models available to you from the OpenAI API
Options:
--json Output as JSON
--key TEXT OpenAI API key
-h, --help Show this message and exit.💅 CONTRIBUTING
okay so if you wanna contribute, first thing: checkout the code. then run the tests with uv run:
cd llm
uv run pytestand bestie, you can run your dev copy of llm with uv run too, like:
uv run llm --help🌸 UPDATING RECORDED HTTP API INTERACTIONS AND ASSOCIATED SNAPSHOTS
this project uses pytest-recording (https://github.com/kiwicom/pytest-recording) to record OpenAI API responses for some of the tests, and syrupy (https://github.com/syrupy-project/syrupy) to capture snapshots of their results. two tools, one glow-up ✨
if you add a new test that calls the API, you can capture the API response and snapshot like this:
PYTEST_OPENAI_API_KEY="$(llm keys get openai)" uv run pytest --record-mode once --snapshot-updatethen go review the new snapshots in tests/__snapshots__/ to make sure they look correct 👀 fr fr, don't skip this step.
🔍 DEBUGGING TRICKS
the default OpenAI plugin has a debugging mechanism for showing the exact requests and responses that were sent to the OpenAI API. it's giving surveillance but make it helpful 💀
set the LLM_OPENAI_SHOW_RESPONSES environment variable like this:
LLM_OPENAI_SHOW_RESPONSES=1 uv run llm -m chatgpt 'three word slogan for an otter-run bakery'this will output details of the API requests and responses to the console 🫶
and use --no-stream to see a more readable version of the body that avoids streaming the response:
LLM_OPENAI_SHOW_RESPONSES=1 uv run llm -m chatgpt --no-stream \
'three word slogan for an otter-run bakery'📚 DOCUMENTATION
documentation for this project uses MyST (https://myst-parser.readthedocs.io/) — it is written in Markdown and rendered using Sphinx ✨
to build the documentation locally, run the following:
just docsthis will start a live preview server, using sphinx-autobuild (https://pypi.org/project/sphinx-autobuild/) 🦋
the CLI --help examples in the documentation are managed using Cog (https://github.com/nedbat/cog). update those files like this:
just cogheads up bestie: you'll need Just (https://github.com/casey/just) installed to run these commands 💖
👑 RELEASE PROCESS
to release a new version, in this exact order:
- Update
docs/changelog.mdwith the new changes. - Update the version number in
pyproject.toml - Run
just cogto updatedocs/fragments.mdwith the new version number. - Create a GitHub release (
https://github.com/simonw/llm/releases/new) for the new version. - Wait for the package to push to PyPI and then...
- Run the
regenerate.yaml(https://github.com/simonw/homebrew-llm/actions/workflows/regenerate.yaml) workflow to update the Homebrew tap to the latest version.
🌈 CHANGELOG
0.34 (2026-09-02)
New features:
llm logs --usageMarkdown output now includes the response duration in milliseconds and as a human-readable duration.llm logs --shortincludes a newduration_msfield. #1653 (https://github.com/simonw/llm/issues/1653)
Bug fixes:
- Significantly improved the performance of
llm logsfor long conversations by caching repeated message and model lookups. #1654 (https://github.com/simonw/llm/issues/1654) - Dynamically generated OpenAI options classes are now cached, avoiding repeated Pydantic class construction by plugins such as
llm-openrouter. Thanks, waveplate (https://github.com/waveplate). #1651 (https://github.com/simonw/llm/pull/1651) - Invalid schema DSL passed to
llm prompt --schemanow produces a clean command-line error instead of a Python traceback. Thanks, ikatyal2110 (https://github.com/ikatyal2110). #1647 (https://github.com/simonw/llm/pull/1647) llm --extractnow recognizes fenced code blocks in responses that use CRLF line endings. Thanks, mameikagou (https://github.com/mameikagou). #1644 (https://github.com/simonw/llm/pull/1644)monotonic_ulid()now remains monotonic if the system clock moves backwards or concurrent calls observe timestamps out of order. Thanks, Dylan Pulver (https://github.com/dylanpulver). #1641 (https://github.com/simonw/llm/pull/1641)- Declared the
typing-extensionspackage as a direct dependency, and added tests to protect against accidental missing dependencies. Thanks, Vansh Taneja (https://github.com/vanshtaneja23). #1622 (https://github.com/simonw/llm/pull/1622)
0.33 (2026-08-22)
New features:
- Upgraded to the OpenAI Python library 3.x and switched the HTTP client dependency from
httpxtohttpx2. #1608 (https://github.com/simonw/llm/issues/1608), #1631 (https://github.com/simonw/llm/pull/1631) llm embedandllm embed-multinow accept--key. The PythonEmbeddingModel.embed(),EmbeddingModel.embed_multi(),Collection.embed()andCollection.embed_multi()methods acceptkey=too, passing the resolved per-call key to embedding plugins without changing shared model state. Existing plugins that readself.keycontinue to work through a compatibility fallback. Thanks, ChrisJr404 (https://github.com/ChrisJr404). #757 (https://github.com/simonw/llm/issues/757), #1620 (https://github.com/simonw/llm/pull/1620)llm logsnow includes the output of server-side tool calls, shown in a Tool results section within the response. These results are also included inllm logs --jsonandllm logs --shortoutput, with a newserver_executedkey distinguishing them from locally executed tool results. #1629 (https://github.com/simonw/llm/issues/1629)llm prompt -t/--templatecan now be repeated to combine templates in order. This allows model configuration and options from one template to be used with a prompt from another.- Expanded the
llm prompt --helpdocumentation for--schemaand--schema-multiwith details and examples of the supported schema DSL. schema_dsl()now raises descriptiveValueErrorexceptions for unknown field types and duplicate field names, instead of silently treating unknown types as strings or overwriting earlier fields. #1607 (https://github.com/simonw/llm/issues/1607), #1616 (https://github.com/simonw/llm/issues/1616)- Reasoning stream events that contain provider metadata but no text are now preserved as
ReasoningPartobjects. This allows opaque state such as Anthropic signatures and redacted thinking data to round-trip correctly. simonw/llm-anthropic#81 (https://github.com/simonw/llm-anthropic/issues/81) - Reasoning-capable Responses API models now support a
reasoning_summaryoption withauto,concise, anddetailedvalues. This can be used withllm openai endpoint --responses<#openai-endpoint>. #1600 (https://github.com/simonw/llm/issues/1600) - Conversation prompts now validate that attachments are supported by the selected model before execution, for both synchronous and asynchronous conversations. Thanks, Daniel Peng (
https://github.com/original4422). #1626 (https://github.com/simonw/llm/issues/1626), #1628 (https://github.com/simonw/llm/pull/1628)
Bug fixes:
llm logs --data-idsnow setsconversation_idto the ID of the conversation instead of incorrectly duplicating the response ID. Thanks, K Merchant (https://github.com/Kayforkind). #1598 (https://github.com/simonw/llm/issues/1598), #1613 (https://github.com/simonw/llm/pull/1613)- Fixed
llm aliases listraising aValueErrorwhen no aliases are defined. Thanks, Taraka Abhiram (https://github.com/abhi-0203). #1602 (https://github.com/simonw/llm/issues/1602) llm embed-multinow reuses an existing collection's stored embedding model when no default embedding model is configured, and no longer masks unrelatedValueErrorexceptions with a missing-model error. #1523 (https://github.com/simonw/llm/issues/1523)llm tools -m MODELno longer prints a redundant message when the model has no server-side tools.
0.32.1 (2026-08-21)
This version pins LLM to use OpenAI Python versions less than v3.0.0 (https://github.com/openai/openai-python/releases#release-v3.0.0), ensuring fresh LLM installations work without needing to also install an extra httpx dependency. #1630 (https://github.com/simonw/llm/pull/1630)
0.32 (2026-08-04)
LLM 0.32 is a major, backwards-compatible update to the way prompts, responses, tools and logs are represented. It adds structured messages and parts throughout the Python API, adopts the OpenAI Responses API for reasoning-capable models, substantially expands control over pausable and resumable tool loops and introduces a new content-addressed SQLite logging schema. Reasoning traces are now displayed on standard error by the llm command, for models that support them.
💖 Structured messages and richer responses
Okay so this is THE glow-up. Prompt inputs and model outputs are now represented as lists of Message objects, and each one holds typed Part objects for text, reasoning, tool calls, tool results and attachments. It's giving structured. It's giving ✨organized✨.
- New
messages=keyword argument (#python-api-messages) on the prompt, conversation and chain APIs, including their asynchronous equivalents. For example,model.prompt(messages=[llm.user("Hello"), llm.assistant("Hi!"), llm.user("What can you do?")]). And bestie — the existingprompt=,system=,attachments=andtool_results=arguments? Still work, no cap. They just get converted into the same structured representation. 🫶 - New structured streaming methods
response.stream_events()andresponse.astream_events()(#python-api-messages) expose mixed streams of text, reasoning, tool calls and tool results. Iterating over a response directly still yields text strings, so your old code is safe, don't stress. 💅 response.messages()returns the assembled structured output. Andresponse.reply()continues from any response and can automatically execute pending tool calls before the next turn. Main character energy tbh.response.to_dict()andResponse.from_dict()provide JSON-safe persistence of complete turns, including reasoning and provider metadata, with matchingTypedDictdefinitions in the newllm.serializationmodule. 🔥response.prompt.messagesis now the canonical record of exactly what was sent to the model, including the full preceding conversation chain. The receipts. All of them. 💀- These APIs were introduced in
0.32a0. They are described in the Advanced model plugins documentation (#advanced-model-plugins).
🧠 OpenAI Responses API and reasoning
- Most reasoning-capable OpenAI models now use the
/v1/responsesendpoint by default, enabling interleaved reasoning across tool calls. The existing Chat Completions classes remain available, and-o chat_completions 1selects that older path for an individual prompt. See0.32a2for the full list of affected models. - OpenAI Responses API models now provide
WebSearch(#openai-models-web-search) andCodeInterpreter(#openai-models-code-interpreter) server-side tools, available from the CLI using-T WebSearchor-T 'CodeInterpreter(memory_limit="4g")'. Iconic honestly. 👑 - Visible reasoning summaries (
#python-api-messages-reasoning) are streamed to standard error byllm promptandllm chat. Use-R/--hide-reasoningor the newhide_reasoning=TruePython argument to hide them. Encrypted reasoning metadata is preserved for subsequent turns, so nothing gets lost. 🔐 - The default model for users who have not selected one is now GPT-5.6 Luna (https://developers.openai.com/api/docs/models/gpt-5.6-luna), replacing GPT-4o mini. New built-in models include
gpt-5.6-sol,gpt-5.6-terraandgpt-5.6-luna; models that are no longer available from OpenAI have been removed. See0.32rc1and0.32rc2for details. - New
llm openai endpointcommand (#openai-endpoint) runs prompts and chats, or lists models, against an arbitrary OpenAI-compatible endpoint without configuring it first. Heads up though: these calls are not logged. 🙈 - OpenAI models now support a
service_tieroption. Use-o service_tier fastfor faster responses at a higher price, or-o service_tier flexfor slower, cheaper processing on supported models. See Fast mode and service tiers (#openai-models-service-tier). #1585 (https://github.com/simonw/llm/pull/1585) - New
llm -m model --optionsflag lists the options supported by a model. The Python prompt APIs now accept an explicitoptions=dictionary (#python-api-model-options) as well as the previous keyword-argument form.
🛠️ More controllable tool loops
- Every tool call now has a unique
tool_call_id, synthesized when the provider does not supply one. Tool implementations can accept anllm_tool_callparameter (#python-api-tools-llm-tool-call) to inspect the current call and its ID. So nosy, love that for us. 🕵️ - Tools can raise
llm.PauseChain(#python-api-tools-pause) to pause execution for human approval or another external event. Chains can later resume from a message history ending in unresolved tool calls (#python-api-tools-resume), without repeating calls that already have results. Efficiency queen. ✨ - Conversations that use configured tools (
#usage-tools) can be continued withllm -corllm chat -cwithout repeating the toolbox configuration. Finally. 😭 llm toolsnow shows constructor signatures and docstrings for dynamic toolboxes (#python-api-tools-dynamic). Passing a toolbox specification instantiates it and lists its runtime-generated tools, whilellm tools --jsonidentifies dynamic toolboxes with a"dynamic"boolean. #1580 (https://github.com/simonw/llm/issues/1580)- Models can now declare the server-side tools they support (
#advanced-model-plugins-server-side-tools) using the instance-levelsupported_server_side_toolsproperty and the newllm.ServerSideToolbase class. Server-executed calls and results are captured as structured message parts, andllm -crestores configured server-side tools for continued conversations. #1592 (https://github.com/simonw/llm/issues/1592), #1593 (https://github.com/simonw/llm/pull/1593) llm tools -m MODEL(#usage-tools) lists the server-side tools supported by that model. Andllm models --jsonreturns model aliases, capability flags, attachment types and server-side tools, with option schemas included when combined with--options. 🌈- OpenAI-compatible Responses endpoints (
#openai-endpoint) can use provider-specific server-side tools withServerSideTool(spec={...}), including OpenRouter's web search implementation. - See
0.32a3for more detail on pausing, resuming and inspecting tool calls.
🗄️ New SQLite logging schema
LLM now logs prompts and responses using a new schema built around threads, turns and a content-addressed message store. Existing records in the legacy responses table are left untouched, and llm logs combines both generations of data. You can create a backup (#logging-backup) before upgrading using:
llm logs backup logs-backup.db- Messages are stored once and referenced by their content hash, preserving structured text, reasoning, attachments and tool activity without duplicating repeated conversation history. See the message store documentation (
#logging-message-store). No dupes, no waste, sustainable queen. 🌸 - Raw provider payloads are stored in
turns.response_json, condensed (#logging-message-store-response-json) using condense-json (https://github.com/simonw/condense-json).llm logs --jsonexpands them back to their original shape, andLogStore.turn_response_json(turn_id)returns them from Python. #1586 (https://github.com/simonw/llm/pull/1586) - Model plugins can define
json_replacements(#advanced-model-plugins-json-replacements) dictionaries to further improve payload compression. Squish it. 🗜️ - Full-text search (
#logging-search), model (#logging-filter-model) and tool filters (#logging-filter-tools), and conversation views (#logging-conversation) work across both the legacy and new tables. Logs now record which configured toolbox instance supplied each tool. 🔍 - New
Response.log_to_db()(#logging-message-store-python) Python API writes a response to a logs database. Andllm prompt --jsonoutputs the same structured representation asllm logs --json, even when persistent logging is disabled. - New
message_treeSQL view (#logging-message-store-queries) renders conversation threads as indented text outlines for direct SQL exploration. It's giving family tree but for your prompts. 🌳 - LLM now requires sqlite-utils 4.0 (https://sqlite-utils.datasette.io/en/stable/changelog.html#v4-0) or higher and no longer depends on
sqlite-migrate. - See
0.32rc1for the detailed migration notes and complete list of logging changes.
🩹 Fixes since 0.32rc2
- Fixed streamed OpenAI Responses API calls recording two different ciphertexts of the same reasoning: the part's
encrypted_contentwas harvested from theresponse.output_item.doneevent whileresponse_jsoncame fromresponse.completed, and OpenAI encrypts per event. Reasoning metadata is now re-emitted from the final payload, so both records agree on one blob. Teamwork makes the dream work. 🤝 - Attachments loaded from URLs now follow up to three redirects when detecting their content type or fetching their bytes. Thanks, Ojas Sharma (https://github.com/ojassharma7). #1046 (https://github.com/simonw/llm/issues/1046), #1579 (https://github.com/simonw/llm/pull/1579)
- Fixed a bug where
llm openai endpoint --schemawas ignored if the selected template also defined a schema. Thanks, ikatyal2110 (https://github.com/ikatyal2110). #1588 (https://github.com/simonw/llm/pull/1588) llm logs statusnow counts records in the newthreadsandturnstables, with legacy conversation and response counts shown separately when present.Response.to_dict()now executes an unconsumed synchronous response before serializing it instead of producing an empty assistant message list. No more ghosting your own output. 👻Response.from_dict()now restores pending client-side tool calls so they can be inspected, executed or continued usingresponse.reply(tools=[...]).Response.reply()now correctly passes attachments returned by tools (#python-api-tools-attachments) to the next model call, for both synchronous and asynchronous responses. 💖
⭐ 0.32rc2 (2026-07-30)
- The default model for users who have not set their own default is now GPT-5.6 Luna (https://developers.openai.com/api/docs/models/gpt-5.6-luna). It was previously GPT-4o mini (https://developers.openai.com/api/docs/models/gpt-4o-mini). Luna is a much better and more recent model, albeit slightly more expensive — $0.20 per million input tokens and $1.20 per million output tokens, compared to $0.15/$0.60 for 4o mini. You can switch back to 4o mini using
llm models default gpt-4o-mini, or switch to GPT-5 nano (https://developers.openai.com/api/docs/models/gpt-5-nano), an even cheaper default model ($0.05/$0.40), usingllm models default gpt-5-nano. #1576 (https://github.com/simonw/llm/issues/1576) - New
llm openai endpointcommand (#openai-endpoint) for running prompts, chats and model listings against arbitrary OpenAI-compatible endpoints without first configuring a model. And again for the people in the back: these calls are not logged. #1565 (https://github.com/simonw/llm/issues/1565) - No longer depends on
sqlite-migrate(https://github.com/simonw/sqlite-migrate), since that functionality is now handled by sqlite-utils 4.0 (https://sqlite-utils.datasette.io/en/stable/changelog.html#v4-0). #1577 (https://github.com/simonw/llm/issues/1577) - Fixed a bug where server-executed tool calls were incorrectly reported as pending by
LogStore.pending_tool_calls(). Thanks, ikatyal2110 (https://github.com/ikatyal2110). #1574 (https://github.com/simonw/llm/issues/1574) schema_dsl()is now way less cryptic when you hand it garbage: it raises a descriptiveValueErrorinstead of a confusingIndexErrorwhen it hits malformed fields with no name before the colon. #1466 —https://github.com/simonw/llm/issues/1466
0.32rc1 (2026-07-30)
Okay bestie, this release candidate for 0.32 is a big one. It introduces a brand new database schema for logging prompts and responses that captures the full details of the interaction with the underlying LLM, and it de-duplicates those records using a content-addressed message store. ✨
Upgrading to this RC will create those new tables and start logging to them. Existing data in theresponsestable will be left unaffected, and thelogscommand will read from both old and new tables. New interactions will only be written to the new tables. 🫶
You can create a backup of your logs database prior to upgrading using:
llm logs backup logs-backup.dbChanges to SQLite logging
- See the message store documentation (
#logging-message-store) for all the deets on the new logging schema. 📚 llm promptlogs are now written to a new set of tables, not the legacy tables.- New documented
Response.log_to_db()(#logging-message-store-python) Python API for writing to a SQLite logs database. 🐍 llm logsnow reads both generations of log tables: history recorded by older versions of LLM in the legacyresponsestable is merged into the output alongside new turns, with rows from the dual-write era deduplicated byid. The-m,-c,-f,-T,--toolsand--schemafilters work across both. #1562 —https://github.com/simonw/llm/pull/1562- Raw provider payloads (the old
prompt_jsonandresponse_jsoncolumns) are no longer persisted — the stored message chain is the record of what was sent and returned. This means data that only ever lived in those raw payloads is no longer stored, notably the log probabilities returned by OpenAI completion models with-o logprobs. 💀 llm logs -qfull-text search works against the new log tables. Search covers the prompt text you typed and the model's text responses — system prompts, fragment contents, tool activity and reasoning traces are excluded from the index. See Searching the logs (#logging-search). 🔍llm logsnow shows which configured toolbox instance provided each tool — in the tools list for a prompt and on each tool result, so aSQLite_queryresult records that it ran againstSQLite("mydb.db"). 🧰- New
message_treeSQL view (#logging-message-store-queries) that renders each conversation thread as an indented text outline, for exploring the message store directly with SQL. #1562 —https://github.com/simonw/llm/pull/1562🌳
Other changes
- New OpenAI models:
gpt-5.6-sol,gpt-5.6-terraandgpt-5.6-luna. 👑 - Removed OpenAI models that are no longer available via the OpenAI API:
chatgpt-4o-latest, thegpt-4oandgpt-4o-miniaudio preview models,gpt-4-32k,gpt-4-1106-preview,gpt-4-0125-preview, thegpt-4.5preview models,o1-preview,o1-miniandgpt-5.1-chat-latest. #1553 —https://github.com/simonw/llm/issues/1553💀 - Continuing a conversation that used a configured toolbox now works:
llm -candllm chat -creconstruct each toolbox instance from its recorded configuration, so a conversation started with-T 'Datasette("https://datasette.io/content")'can be continued without repeating the-Toption. 🎀 - New
llm prompt --jsonoption which outputs a JSON array describing the prompt and the response, in the same format asllm logs --json. This works even with--no-logor logging turned off, in which case the response is logged to a temporary in-memory database to build the JSON. #1566 —https://github.com/simonw/llm/pull/1566✨ - New
response.execute_tool_call(tool_call)method (awaitable on async responses) that executes a single tool call and returns itsToolResult. This is designed for plugins wrapping provider SDKs that orchestrate the tool loop themselves, described in the advanced model plugins documentation (#advanced-model-plugins-execute-tool-call). 🛠️ - Documentation for the
responses: truesetting inextra-openai-models.yaml, which opts a custom OpenAI model into the Responses API instead of Chat Completions. See Adding more OpenAI models (#openai-extra-models). 📝 - Fixed a bug where the system prompt was omitted from the pre-computed
prompt.messageson the first turn of a conversation, so models that build their request from that message list never received it. Thanks, Niall Smart —https://github.com/niallsmart. #1478 —https://github.com/simonw/llm/issues/1478🫶 - Fixed a bug on Windows where a fragment argument holding an absolute path such as
C:\Users\demo\notes.txtwas mistaken for a reference to ac:fragment loader plugin. Fragment arguments that match an existing file path now always resolve as files. #1563 —https://github.com/simonw/llm/issues/1563🪟 - LLM now requires
sqlite-utils4.0 or higher —https://sqlite-utils.datasette.io/en/stable/changelog.html#v4-0
0.31.1 (2026-07-09)
- Fix for a bug with OpenAI Chat Completion endpoints where a tool call with empty arguments could result in a JSON error from some providers. #1521 —
https://github.com/simonw/llm/issues/1521🐛
0.32a3 (2026-06-09)
Driven by the needs of Datasette Agent's human-in-the-loop ask_user() feature (https://github.com/datasette/datasette-agent), this one made the following improvements to how tool calls work:
- Tool implementations can declare a parameter named
llm_tool_callin order to be passed thellm.ToolCallobject for the current invocation. This allows them to access the currentllm_tool_call.tool_call_id. See Accessing the tool call from inside a tool (#python-api-tools-llm-tool-call). #1480 —https://github.com/simonw/llm/pull/1480🎯 - Every tool call is now guaranteed a unique
tool_call_id— providers that do not supply one get a synthesizedtc_-prefixed ULID. #1481 —https://github.com/simonw/llm/pull/1481🆔 - Tools can raise a
llm.PauseChainexception to cleanly pause the tool chain, useful for things like waiting for human approval. The exception propagates to the caller with.tool_calland.tool_results(completed sibling results) attached, and no model call is made with a placeholder result. See Pausing a chain from inside a tool (#python-api-tools-pause). #1482 —https://github.com/simonw/llm/pull/1482⏸️ - Failure semantics for concurrent tool execution: async sibling tool calls always run to completion before a pause or hook exception propagates. #1482 —
https://github.com/simonw/llm/pull/1482🏁 - Chains can now resume from a
messages=history ending in unresolved tool calls: the calls are executed through the normalbefore_call/after_callmachinery before the first model call, skipping any that already have results. Theexecute_tool_calls()method also accepts a new optionaltool_calls_list=argument for executing an explicit list ofToolCallobjects in place of the calls requested by the response. See Resuming a chain with pending tool calls (#python-api-tools-resume). #1482 —https://github.com/simonw/llm/pull/1482🔁 - Fixed a bug where the async tool executor silently dropped calls to tools not present in
tools=— these now returnError: tool "..." does not existresults, matching the sync executor. #1483 —https://github.com/simonw/llm/pull/1483🐛
0.32a2 (2026-05-12)
Support for the OpenAI Responses API
Most reasoning-capable OpenAI models now use the /v1/responses endpoint (https://developers.openai.com/api/reference/responses/overview) instead of /v1/chat/completions. This enables interleaved reasoning across tool calls for GPT-5 class models. #1435 — https://github.com/simonw/llm/pull/1435 🧠
- New
ResponsesandAsyncResponsesmodel classes driving the OpenAI Responses API. The existingChatandAsyncChatclasses are unchanged so other plugins that import them keep working. 🫶 - The following models now use the Responses API by default:
o1,o3-mini,o3,o4-mini,gpt-5,gpt-5-mini,gpt-5-nano,gpt-5.1,gpt-5.2,gpt-5.4,gpt-5.4-mini,gpt-5.4-nano,gpt-5.5(and their pinned date variants). 📋 - Use
-o chat_completions 1to fall back to the older/v1/chat/completionscode path for any of these models. 🔙 - Encrypted reasoning items are captured as
provider_metadataonReasoningPartobjects and round-tripped back to OpenAI on subsequent turns. 🔐 - Reasoning summaries are now requested with
"summary": "auto"so visible reasoning text is streamed back where the model produces it, unless--hide-reasoningorhide_reasoning=is set. 👀 - This means OpenAI prompts run using
llm promptthat return reasoning tokens will display those on standard error. 📺
CLI
- New
llm -m model --optionsflag to list the options supported by a given model. #1441 —https://github.com/simonw/llm/pull/1441🎛️ - The
-R/--no-reasoningoption has been renamed to-R/--hide-reasoning. 🏷️
Python API
- New
hide_reasoning=Truekeyword argument onmodel.prompt(),conversation.prompt(),model.chain(),conversation.chain(), and their async counterparts, exposed to model plugins asprompt.hide_reasoning. Model plugins can use this to decide (#advanced-model-plugins-reasoning-tokens) if they should request visible reasoning summaries from their providers. #1442 —https://github.com/simonw/llm/pull/1442🙈 - New
options=dict keyword argument onModel.prompt(),Conversation.prompt(),Response.reply(), and their async equivalents, matching the pattern already used by.chain(). The previous**kwargsform continues to work for backwards compatibility but is no longer documented, and will be removed in the future. #1432 —https://github.com/simonw/llm/pull/1432⚠️
Bug fixes
add_tool_call()calls that were not also recorded as stream events are now correctly emitted asToolCallPartobjects when assembling response parts, so they survive serialization viaresponse.to_dict(). #1433 —https://github.com/simonw/llm/issues/1433🐛
0.32a1 (2026-04-29)
- Fixed a bug in 0.32a0 where tool-calling conversations were not correctly reinflated from SQLite. #1426 —
https://github.com/simonw/llm/issues/1426🐛
0.32a0 (2026-04-28)
This alpha introduces a major backwards-compatible refactor. Models can now be prompted with a list of messages, OpenAI Chat Completions style, and the response can now be iterated over as a sequence of mixed types of content — for example reasoning tokens mixed with text tokens mixed with tool calls. 🌈
For more background on this release take a look at the annotated release notes (https://simonwillison.net/2026/Apr/29/llm/) on my blog. 📝
Prompt inputs and response outputs are now a list of Message objects, and every one of those is packed with typed Part objects — text, reasoning, tool calls, tool results, attachments. it's giving structured. 💖
The llm CLI tool can now display reasoning tokens while it's executing a prompt. like, you get to watch it think. main character behavior fr fr.
Plugin authors — bestie, this is your callout — go read the expanded Advanced model plugins documentation, which now covers StreamEvent, consuming prompt.messages, and round-tripping opaque provider metadata such as Anthropic extended-thinking signatures and Gemini thoughtSignature values. iykyk. 🧚
✨ Structured messages and streaming events ✨
- New
llm.Messagevalue type plus constructor helpersllm.user(),llm.assistant(),llm.system(), andllm.tool_message()for building structured prompt inputs. These helpers accept strings,Attachmentinstances, or nestedPartlists. versatile queen. 👑 - New
messages=keyword argument onmodel.prompt(),conversation.prompt(),model.chain(),conversation.chain(), and their async counterparts. Theprompt=,system=,attachments=, andtool_results=keywords still work and synthesize into the sameMessagelist internally. nothing broke, everything slays. 💅 - New
response.stream_events()andresponse.astream_events()methods yielding typedStreamEventobjects (typeis one of"text","reasoning","tool_call_name","tool_call_args","tool_result", plus aredacted=Truemarker for opaque reasoning). Iterating againstresponsedirectly continues to yield only text strings. old vibes preserved, new vibes unlocked. 🦋 - New
response.messages()method (async:await response.messages()) returning the assembledlist[Message]produced by the model. Calling it forces execution if the response prompt has not yet been executed. - New
response.reply(prompt=None, **kwargs)method that continues the conversation from anyResponse, regardless of origin. When the previous response made tool calls andtool_results=was not passed,reply()automatically executes the pending tool calls and threads the results into the next turn. On async responsesreply()is awaitable. 🫶 - New
response.to_dict()andResponse.from_dict(data, *, model=None)for JSON-safe serialization of a full conversation turn — model id, input chain, assembled output (including reasoning parts and provider metadata), options, and audit fields. Reasoning signatures andthoughtSignaturevalues round-trip viaprovider_metadata, so multi-turn extended thinking works across process boundaries. no cap, that's huge. 🔥 - New
llm/serialization.pymodule exposingMessageDict,PartDict,ResponseDict,PromptDict,UsageDict,AttachmentDict, and the per-PartTypedDicts. Everyto_dict()/from_dict()method is annotated with the matchingTypedDict. Response.prompt.messagesis now the canonical structured input across the entire conversation chain.Conversation.promptandAsyncConversation.promptpre-compute the full chain (prior input + prior output + new turn) before constructing the nextPrompt, soresponse.prompt.messagesis always exactly what the model was sent. receipts. 💯
💻 CLI 💻
llm promptandllm chatnow display visible reasoning text to stderr in a dim style while the response streams.- New
-R,--hide-reasoningflag forllm promptandllm chatto hide the reasoning stream. for when you want it to keep its thoughts to itself. 🙈 llm logsnow renders any visible reasoning emitted during a response under a## Reasoningheading above the response.- New
reasoningcolumn on theresponsestable populated from the visible-reasoning text.
🌈 0.31 (2026-04-24) 🌈
- New GPT-5.5 OpenAI model:
llm -m gpt-5.5.#1418<https://github.com/simonw/llm/issues/1418> - New option to set the text verbosity level for GPT-5+ OpenAI models:
-o verbosity low. Values arelow,medium,high.<https://developers.openai.com/cookbook/examples/gpt-5/gpt-5_new_params_and_tools#1-verbosity-parameter> - New option for setting the image detail level used for image attachments to OpenAI models:
-o image_detail low— values arelow,highandauto, and GPT-5.4 and 5.5 also acceptoriginal.<https://developers.openai.com/api/docs/guides/images-vision#choose-an-image-detail-level> - Models listed in
extra-openai-models.yamlare now also registered as asynchronous.#1395<https://github.com/simonw/llm/issues/1395>
🌈 0.30 (2026-03-31) 🌈
- The
register_models()plugin hook now takes an optionalmodel_aliasesparameter listing all of the models, async models and aliases that have been registered so far by other plugins. A plugin with@hookimpl(trylast=True)can use this to take previously registered models into account.#1389<https://github.com/simonw/llm/issues/1389> - Added docstrings to public classes and methods and included those directly in the documentation.
🌈 0.29 (2026-03-17) 🌈
- The
-t/--templateoption now works correctly with the-x/--extractand--xl/--extract-lastflags. teamwork makes the dream work. 🤝 llm logsnow shows any additional model options in the Markdown output.#1322<https://github.com/simonw/llm/issues/1322>- New OpenAI models:
gpt-5.4,gpt-5.4-mini,gpt-5.4-nano.#1376<https://github.com/simonw/llm/issues/1376>
🌈 0.28 (2025-12-12) 🌈
- New OpenAI models:
gpt-5.1,gpt-5.1-chat-latest,gpt-5.2andgpt-5.2-chat-latest.#1300<https://github.com/simonw/llm/issues/1300>,#1317<https://github.com/simonw/llm/issues/1317> - LLM now requires Python 3.10 or higher. Python 3.14 is now covered by the tests.
- When fetching URLs as fragments using
llm -f URL, the request now includes a custom user-agent header:llm/VERSION (https://llm.datasette.io/).#1309<https://github.com/simonw/llm/issues/1309> - Fixed a bug where fragments were not correctly registered with their source when using
llm chat. Thanks, Giuseppe Rota<https://github.com/grota>.#1316<https://github.com/simonw/llm/pull/1316> - Fixed some file descriptor leak warnings. Thanks, Eric Bloch
<https://github.com/eedeebee>.#1313<https://github.com/simonw/llm/issues/1313> - Fixed a deprecation warning for
asyncio.iscoroutinefunction. - Type annotations for the OpenAI
Chat,AsyncChatandCompletionexecute()methods. Thanks, Arjan Mossel<https://github.com/ar-jan>.#1315<https://github.com/simonw/llm/pull/1315> - The project now uses
uvand dependency groups for development. See the updated contributing documentation.#1318<https://github.com/simonw/llm/issues/1318>
🌈 0.27.1 (2025-08-11) 🌈
llm chat -t templatenow correctly loads any tools that are included in that template.#1239<https://github.com/simonw/llm/issues/1239>- Fixed a bug where
llm -m gpt5 -o reasoning_effort minimal --save gmsaved a template containing invalid YAML.#1237<https://github.com/simonw/llm/issues/1237> - Fixed a bug where running
llm chat -t templatecould cause prompts to be duplicated.#1240<https://github.com/simonw/llm/issues/1240> - Less confusing error message if a requested toolbox class is unavailable.
#1238<https://github.com/simonw/llm/issues/1238>
🌈 0.27 (2025-08-11) 🌈
This release adds support for the new GPT-5 family of models from OpenAI. It also enhances tool calling in a number of ways, including allowing templates to bundle pre-configured tools. glow up. ✨
🌸 New features 🌸
- New models:
gpt-5,gpt-5-miniandgpt-5-nano.#1229<https://github.com/simonw/llm/issues/1229> - LLM templates can now include a list of tools. These can be named tools from plugins or arbitrary Python function blocks, see Tools in templates.
#1009<https://github.com/simonw/llm/issues/1009> - Tools can now return attachments, for models that support features such as image input.
#1014<https://github.com/simonw/llm/issues/1014> - New methods on the
Toolboxclass:.add_tool(),.prepare()and.prepare_async(), described in Dynamic toolboxes.#1111<https://github.com/simonw/llm/issues/1111> - New
model.conversation(before_call=x, after_call=y)attributes for registering callback functions to run before and after tool calls. See tool debugging hooks for details.#1088<https://github.com/simonw/llm/issues/1088> - Some model providers can serve different models from the same configured URL —
llm-llama-server<https://github.com/simonw/llm-llama-server>for example. Plugins for these providers can now record the resolved model ID of the model that was used to the LLM logs using theresponse.set_resolved_model(model_id)method.#1117<https://github.com/simonw/llm/issues/1117> - Raising
llm.CancelToolCallnow only cancels the current tool call, passing an error back to the model and allowing it to continue.#1148<https://github.com/simonw/llm/issues/1148> - New
-l,--latestoption forllm logs -q searchtermfor searching logs ordered by date (most recent first) instead of the default relevance search.#1177<https://github.com/simonw/llm/issues/1177>
🐛 Bug fixes and documentation 🐛
- Fix for various bugs with different formats of streaming function responses for OpenAI-compatible models. Thanks, James Sanford
<https://github.com/jamessanford>.#1218<https://github.com/simonw/llm/pull/1218> - The
register_embedding_modelshook is now documented<https://llm.datasette.io/en/stable/plugins/plugin-hooks.html#register-embedding-models-register>.#1049<https://github.com/simonw/llm/issues/1049> - Show visible stack trace for
llm templates show invalid-template-name.#1053<https://github.com/simonw/llm/issues/1053> - Handle invalid tool names more gracefully in
llm chat.#1104<https://github.com/simonw/llm/issues/1104> - Add a Tool plugins section to the plugin directory.
#1110<https://github.com/simonw/llm/issues/1110> - Error on
register(Klass)if the passed class is not a subclass ofToolbox.#1114<https://github.com/simonw/llm/issues/1114> - Add
-hfor--helpfor allllmCLI commands.#1134<https://github.com/simonw/llm/issues/1134> - Add missing dataclasses to advanced model plugins docs.
#1137<https://github.com/simonw/llm/issues/1137> - Fixed a bug where
llm logs -T llm_version "version" --asyncincorrectly recorded just one single log entry when it should have recorded two.#1150<https://github.com/simonw/llm/issues/1150> - All extra OpenAI model keys in
extra-openai-models.yamlare now documented.#1228<https://github.com/simonw/llm/issues/1228>
🌈 0.26 (2025-05-27) 🌈
Tool support is finally here! This release adds support exposing tools to LLMs, previously described in the release notes for 0.26a0 and 0.26a1. we've been waiting for this one, bestie. 💜
Read Large Language Models can run tools in your terminal with LLM 0.26 (https://simonwillison.net/2025/May/27/llm-tools/) for a detailed overview of the new features. Bestie it's a whole article, go read it 💖
Also in this release:
- Two new default tools (see
#tools-default):llm_version()andllm_time(). #1096 (https://github.com/simonw/llm/issues/1096), #1103 (https://github.com/simonw/llm/issues/1103) - Documentation on how to add tool supports to a model plugin (see
#advanced-model-plugins-tools). #1000 (https://github.com/simonw/llm/issues/1000) - Added a prominent warning (see
#tools-warning) about the risk of prompt injection when using tools. #1097 (https://github.com/simonw/llm/issues/1097) - Switched to using monotonic ULIDs for the response IDs in the logs, fixing some intermittent test failures. #1099 (
https://github.com/simonw/llm/issues/1099) - New
tool_instancestable records details ofToolboxinstances created while executing a prompt. #1089 (https://github.com/simonw/llm/issues/1089) llm.get_key()is now a documented utility function (see#plugin-utilities-get-key). #1094 (https://github.com/simonw/llm/issues/1094)
🎀 0.26a1 (2025-05-25)
Hopefully the last alpha before a stable release that includes tool support. fingers crossed bestie 🤞
Features 💅
- Plugin-provided tools can now be grouped into "Toolboxes".
- Toolboxes (
llm.Toolboxclasses) allow plugins to expose multiple related tools that share state or configuration (e.g., a Memory tool or Filesystem tool). (#1059https://github.com/simonw/llm/issues/1059, #1086https://github.com/simonw/llm/issues/1086)
- Toolboxes (
- Tool support for
llm chat.- The
llm chatcommand now accepts--tooland--functionsarguments, allowing interactive chat sessions to use tools. (#1004https://github.com/simonw/llm/issues/1004, #1062https://github.com/simonw/llm/issues/1062)
- The
- Tools can now execute asynchronously.
- Models that implement
AsyncModelcan now run tools, including tool functions defined asasync def. (#1063https://github.com/simonw/llm/issues/1063)
- Models that implement
llm chatnow supports adding fragments during a session.- Use the new
!fragment <id>command while chatting to insert content from a fragment. Initial fragments can also be passed tollm chatusing-for--sf. Thanks, Dan Turkel (https://github.com/daturkel). (#1044https://github.com/simonw/llm/issues/1044, #1048https://github.com/simonw/llm/issues/1048)
- Use the new
- Filter
llm logsby tools.- New
--tool <name>option to filter logs to show only responses that involved a specific tool (e.g.,--tool simple_eval). - The
--toolsflag shows all responses that used any tool. (#1013https://github.com/simonw/llm/issues/1013, #1072https://github.com/simonw/llm/issues/1072)
- New
llm schemas listcan output JSON.- Added
--jsonand--nl(newline-delimited JSON) options tollm schemas listfor programmatic access to saved schema definitions. (#1070https://github.com/simonw/llm/issues/1070)
- Added
- Filter
llm similarresults by ID prefix.- The new
--prefixoption forllm similarallows searching for similar items only within IDs that start with a specified string (e.g.,llm similar my-collection --prefix 'docs/'). Thanks, Dan Turkel (https://github.com/daturkel). (#1052https://github.com/simonw/llm/issues/1052)
- The new
- Control chained tool execution limit.
- New
--chain-limit <N>(or--cl) option forllm promptandllm chatto specify the maximum number of consecutive tool calls allowed for a single prompt. Defaults to5; set to0for unlimited. (#1025https://github.com/simonw/llm/issues/1025)
- New
llm plugins --hook <NAME>option.- Filter the list of installed plugins to only show those that implement a specific plugin hook. (#1047
https://github.com/simonw/llm/issues/1047)
- Filter the list of installed plugins to only show those that implement a specific plugin hook. (#1047
llm tools listnow shows toolboxes and their methods. (#1013https://github.com/simonw/llm/issues/1013)llm promptandllm chatnow automatically re-enable plugin-provided tools when continuing a conversation (-cor--cid). (#1020https://github.com/simonw/llm/issues/1020)- The
--tools-debugoption now pretty-prints JSON tool results for improved readability. (#1083https://github.com/simonw/llm/issues/1083) - New
LLM_TOOLS_DEBUGenvironment variable to permanently enable--tools-debug. (#1045https://github.com/simonw/llm/issues/1045) llm chatsessions now correctly respect default model options configured withllm models set-options. Thanks, André Arko (https://github.com/indirect). (#985https://github.com/simonw/llm/issues/985)- New
--preoption forllm installto allow installing pre-release packages. (#1060https://github.com/simonw/llm/issues/1060) - OpenAI models (
gpt-4o,gpt-4o-mini) now explicitly declare support for tools and vision. (#1037https://github.com/simonw/llm/issues/1037) - The
supports_toolsparameter is now supported inextra-openai-models.yaml. Thanks, Mahesh Hegde (https://github.com/mahesh-hegde). (#1068https://github.com/simonw/llm/issues/1068)
Bug fixes 🐛
- Fixed a bug where the
nameparameter inregister(function, name="name")was ignored for tool plugins. (#1032https://github.com/simonw/llm/issues/1032) - Ensure
pathlib.Pathobjects are cast tostrbefore passing toclick.editinllm templates edit. Thanks, Abizer Lokhandwala (https://github.com/abizer). (#1031https://github.com/simonw/llm/issues/1031)
🦋 0.26a0 (2025-05-13)
This is the first alpha to introduce support for tools (see #tools)! Models with tool capability (which includes the default OpenAI model family) can now be granted access to execute Python functions as part of responding to a prompt. obsessed, honestly 👑
Tools are supported by the command-line interface (see #usage-tools):
llm --functions '
def multiply(x: int, y: int) -> int:
"""Multiply two numbers."""
return x * y
' 'what is 34234 * 213345'And in the Python API (see #python-api-tools), using a new model.chain() method for executing multiple prompts in a sequence:
import llm
def multiply(x: int, y: int) -> int:
"""Multiply two numbers."""
return x * y
model = llm.get_model("gpt-4.1-mini")
response = model.chain(
"What is 34234 * 213345?",
tools=[multiply]
)
print(response.text())New tools can also be defined using the register_tools() plugin hook (see #plugin-hooks-register-tools). They can then be called by name from the command-line like this:
llm -T multiply 'What is 34234 * 213345?'Tool support is currently under active development. Consult this milestone (https://github.com/simonw/llm/milestone/12) for the latest status. aka it's still cooking bestie, don't be weird about it 🍓
🌈 0.25 (2025-05-04)
- New plugin feature:
register_fragment_loaders(register)(see#plugin-hooks-register-fragment-loaders) plugins can now return a mixture of fragments and attachments. Thellm-video-frames(https://github.com/simonw/llm-video-frames) plugin is the first to take advantage of this mechanism. #972 (https://github.com/simonw/llm/issues/972) - New OpenAI models:
gpt-4.1,gpt-4.1-mini,gpt-41-nano,o3,o4-mini. #945 (https://github.com/simonw/llm/issues/945), #965 (https://github.com/simonw/llm/issues/965), #976 (https://github.com/simonw/llm/issues/976). - New environment variables:
LLM_MODELandLLM_EMBEDDING_MODELfor setting the model to use without needing to specify-m model_idevery time. #932 (https://github.com/simonw/llm/issues/932) - New command:
llm fragments loaders, to list all currently available fragment loader prefixes provided by plugins. #941 (https://github.com/simonw/llm/issues/941) llm fragmentscommand now shows fragments ordered by the date they were first used. #973 (https://github.com/simonw/llm/issues/973)llm chatnow includes a!editcommand for editing a prompt using your default terminal text editor. Thanks, Benedikt Willi (https://github.com/Hopiu). #969 (https://github.com/simonw/llm/pull/969)- Allow
-tand--systemto be used at the same time. #916 (https://github.com/simonw/llm/issues/916) - Fixed a bug where accessing a model via its alias would fail to respect any default options set for that model. #968 (
https://github.com/simonw/llm/issues/968) - Improved documentation for
extra-openai-models.yaml(see#openai-compatible-models). Thanks, Rahim Nathwani (https://github.com/rahimnathwani) and Dan Guido (https://github.com/dguido). #950 (https://github.com/simonw/llm/pull/950), #957 (https://github.com/simonw/llm/pull/957) llm -c/--continuenow works correctly with the-d/--databaseoption.llm chatnow accepts that-d/--databaseoption. Thanks, Sukhbinder Singh (https://github.com/sukhbinder). #933 (https://github.com/simonw/llm/issues/933)
🧚 0.25a0 (2025-04-10)
llm models --optionsnow shows keys and environment variables for models that use API keys. Thanks, Steve Morin (https://github.com/smorin). #903 (https://github.com/simonw/llm/issues/903)- Added
py.typedmarker file so LLM can now be used as a dependency in projects that usemypywithout a warning. #887 (https://github.com/simonw/llm/issues/887) $characters can now be used in templates by escaping them as$$. Thanks, @guspix (https://github.com/guspix). #904 (https://github.com/simonw/llm/issues/904)- LLM now uses
pyproject.tomlinstead ofsetup.py. #908 (https://github.com/simonw/llm/issues/908)
💜 0.24.2 (2025-04-08)
- Fixed a bug on Windows with the new
llm -t path/to/file.yamlfeature. #901 (https://github.com/simonw/llm/issues/901)
🎀 0.24.1 (2025-04-08)
- Templates can now be specified as a path to a file on disk, using
llm -t path/to/file.yaml. This makes them consistent with how-ffragments are loaded. #897 (https://github.com/simonw/llm/issues/897) llm logs backup /tmp/backup.dbcommand for backing up your (see#logging-backup)logs.dbdatabase. #879 (https://github.com/simonw/llm/issues/879)
✨ 0.24 (2025-04-07)
Support for fragments to help assemble prompts for long context models. Improved support for templates to support attachments and fragments. New plugin hooks for providing custom loaders for both templates and fragments. See Long context support in LLM 0.24 using fragments and template plugins (https://simonwillison.net/2025/Apr/7/long-context-llm/) for more on this release. it's giving main character energy fr fr 💅
The new llm-docs (https://github.com/simonw/llm-docs) plugin demonstrates these new features. Install it like this:
llm install llm-docsNow you can ask questions of the LLM documentation like this:
llm -f docs: 'How do I save a new template?'The docs: prefix is registered by the plugin 💅. The plugin fetches the LLM documentation for your installed version (from the docs-for-llms repo at https://github.com/simonw/docs-for-llms) and uses that as a prompt fragment to help answer your question. Obsessed, honestly. 🎀
Two more new plugins are llm-templates-github (https://github.com/simonw/llm-templates-github) and llm-templates-fabric (https://github.com/simonw/llm-templates-fabric).
llm-templates-github lets you share and use templates on GitHub. You can run my "Pelican riding a bicycle" benchmark (https://simonwillison.net/tags/pelican-riding-a-bicycle/) against a model like this:
llm install llm-templates-github
llm -t gh:simonw/pelican-svg -m o3-miniThis executes the pelican-svg.yaml template (https://github.com/simonw/llm-templates/blob/main/pelican-svg.yaml) stored in the simonw/llm-templates repository (https://github.com/simonw/llm-templates), using a new repository naming convention. ✨
To share your own templates, create a repository on GitHub under your user account called llm-templates and start saving .yaml files to it. Main character energy, go off. 👑
llm-templates-fabric (https://github.com/simonw/llm-templates-fabric) provides a similar mechanism for loading templates from Daniel Miessler's fabric collection (https://github.com/danielmiessler/fabric):
llm install llm-templates-fabric
curl https://simonwillison.net/2025/Apr/6/only-miffy/ | \
llm -t f:extract_main_idea✨ Major new features: ✨
- New fragments feature <#fragments> 🦋. Fragments can be used to assemble long prompts from multiple existing pieces — URLs, file paths or previously used fragments. These will be stored de-duplicated in the database avoiding wasting space storing multiple long context pieces. Example usage:
llm -f https://llm.datasette.io/robots.txt 'explain this file'. #617 (https://github.com/simonw/llm/issues/617) - The
llm logs filenow accepts-ffragment references too, and will show just logged prompts that used those fragments. 🫶 register_template_loaders()plugin hook <#plugin-hooks-register-template-loaders> allowing plugins to register newprefix:valuecustom template loaders. #809 (https://github.com/simonw/llm/issues/809)register_fragment_loaders()plugin hook <#plugin-hooks-register-fragment-loaders> allowing plugins to register newprefix:valuecustom fragment loaders. #886 (https://github.com/simonw/llm/issues/886)llm fragments<#fragments-browsing> family of commands for browsing fragments that have been previously logged to the database. 🔥- The new llm-openai plugin (
https://github.com/simonw/llm-openai-plugin) provides support foro1-pro(which is not supported by the OpenAI mechanism used by LLM core). Future OpenAI features will migrate to this plugin instead of LLM core itself. 👑
💜 Improvements to templates: 💜
llm -t $URLoption can now take a URL to a YAML template. #856 (https://github.com/simonw/llm/issues/856)- Templates can now store default model options. #845 (
https://github.com/simonw/llm/issues/845) - Executing a template that does not use the
$inputvariable no longer blocks LLM waiting for input, so prompt templates can now be used to try different models usingllm -t pelican-svg -m model_id. #835 (https://github.com/simonw/llm/issues/835) llm templatescommand no longer crashes if one of the listed template files contains invalid YAML. #880 (https://github.com/simonw/llm/issues/880)- Attachments can now be stored in templates. #826 (
https://github.com/simonw/llm/issues/826)
🌸 Other changes: 🌸
- New
llm models options<#usage-executing-default-options> family of commands for setting default options for particular models. #829 (https://github.com/simonw/llm/issues/829) llm logs list,llm schemas listandllm schemas show allnow take a-d/--databaseoption with an optional path to a SQLite database. They used to take-p/--pathbut that was inconsistent with other commands.-p/--pathstill works but is excluded from--helpand will be removed in a future LLM release. #857 (https://github.com/simonw/llm/issues/857)llm logs -e/--expandoption for expanding fragments. #881 (https://github.com/simonw/llm/issues/881)llm prompt -d path-to-sqlite.dboption can now be used to write logs to a custom SQLite database. #858 (https://github.com/simonw/llm/issues/858)llm similar -p/--plainoption providing more human-readable output than the default JSON. #853 (https://github.com/simonw/llm/issues/853)llm logs -s/--shortnow truncates to include the end of the prompt too. Thanks, Sukhbinder Singh (https://github.com/sukhbinder). #759 (https://github.com/simonw/llm/issues/759)- Set the
LLM_RAISE_ERRORS=1environment variable to raise errors during prompts rather than suppressing them, which means you can runpython -i -m llm 'prompt'and then drop into a debugger on errors withimport pdb; pdb.pm(). #817 (https://github.com/simonw/llm/issues/817) - Improved
--helpoutput (https://llm.datasette.io/en/stable/help.html#llm-embed-multi-help) forllm embed-multi. #824 (https://github.com/simonw/llm/issues/824) llm models -m Xoption which can be passed multiple times with model IDs to see the details of just those models. #825 (https://github.com/simonw/llm/issues/825)- OpenAI models now accept PDF attachments. #834 (
https://github.com/simonw/llm/issues/834) llm prompt -q gpt -q 4ooption — pass-q searchtermone or more times to execute a prompt against the first model that matches all of those strings — useful for if you can't remember the full model ID. #841 (https://github.com/simonw/llm/issues/841)- OpenAI compatible models <#openai-compatible-models> configured using
extra-openai-models.yamlnow supportsupports_schema: true,vision: trueandaudio: trueoptions. Thanks @adaitche (https://github.com/adaitche) and @giuli007 (https://github.com/giuli007). #819 (https://github.com/simonw/llm/pull/819), #843 (https://github.com/simonw/llm/pull/843)
⭐ 0.24a1 (2025-04-06) ⭐
- New Fragments feature. #617 (
https://github.com/simonw/llm/issues/617) register_fragment_loaders()plugin hook. #809 (https://github.com/simonw/llm/issues/886)
🎀 0.24a0 (2025-02-28) 🎀
- Alpha release with experimental
register_template_loaders()plugin hook. #809 (https://github.com/simonw/llm/issues/809)
🌈 0.23 (2025-02-28) 🌈
Support for schemas, for getting supported models to output JSON that matches a specified JSON schema. See also Structured data extraction from unstructured content using LLM schemas (https://simonwillison.net/2025/Feb/28/llm-schemas/) for background on this feature. #776 (https://github.com/simonw/llm/issues/776)
- New
llm prompt --schema '{JSON schema goes here}option for specifying a schema that should be used for the output from the model. The schemas documentation <#schemas> has more details and a tutorial. 💅 - Schemas can also be defined using a concise schema specification <#schemas-dsl>, for example
llm prompt --schema 'name, bio, age int'. #790 (https://github.com/simonw/llm/issues/790) - Schemas can also be specified by passing a filename and through several other methods <#schemas-specify>. #780 (
https://github.com/simonw/llm/issues/780) - New
llm schemasfamily of commands <#help-schemas>:llm schemas list,llm schemas show, andllm schemas dslfor debugging the new concise schema language. #781 (https://github.com/simonw/llm/issues/781) - Schemas can now be saved to templates using
llm --schema X --save template-nameor through modifying the template YAML <#prompt-templates-yaml>. #778 (https://github.com/simonw/llm/issues/778) - The
llm logs<#logging> command now has new options for extracting data collected using schemas:--data,--data-key,--data-array,--data-ids. #782 (https://github.com/simonw/llm/issues/782) - New
llm logs --id-gt Xand--id-gte Xoptions. #801 (https://github.com/simonw/llm/issues/801) - New
llm models --schemasoption for listing models that support schemas. #797 (https://github.com/simonw/llm/issues/797) model.prompt(..., schema={...})parameter for specifying a schema from Python. This accepts either a dictionary JSON schema definition or a PydanticBaseModelsubclass, see schemas in the Python API docs <#python-api-schemas>. 🐍- The default OpenAI plugin now enables schemas across all supported models. Run
llm models --schemasfor a list of these. - The llm-anthropic (
https://github.com/simonw/llm-anthropic) and llm-gemini (https://github.com/simonw/llm-gemini) plugins have been upgraded to add schema support for those models. Here's documentation on how to add schema support to a model plugin <#advanced-model-plugins-schemas>.
💖 Other smaller changes: 💖
- GPT-4.5 preview (
https://openai.com/index/introducing-gpt-4-5/) is now a supported model:llm -m gpt-4.5 'a joke about a pelican and a wolf'#795 (https://github.com/simonw/llm/issues/795) - The prompt string is now optional when calling
model.prompt()from the Python API, somodel.prompt(attachments=llm.Attachment(url=url)))now works. #784 (https://github.com/simonw/llm/issues/784) extra-openai-models.yamlnow supports areasoning: trueoption. Thanks, Kasper Primdal Lauritzen (https://github.com/KPLauritzen). #766 (https://github.com/simonw/llm/pull/766)- LLM now depends on Pydantic v2 or higher. Pydantic v1 is no longer supported. #520 (
https://github.com/simonw/llm/issues/520)
🦋 0.22 (2025-02-16) 🦋
See also LLM 0.22, the annotated release notes (https://simonwillison.net/2025/Feb/17/llm/).
- Plugins that provide models that use API keys can now subclass the new
llm.KeyModelandllm.AsyncKeyModelclasses. This results in the API key being passed as a newkeyparameter to their.execute()methods, and means that Python users can pass a key as themodel.prompt(..., key=)— see Passing an API key <#python-api-models-api-keys>. Plugin developers should consult the new documentation on writing Models that accept API keys <#advanced-model-plugins-api-keys>. #744 (https://github.com/simonw/llm/issues/744) - New OpenAI model:
chatgpt-4o-latest. This model ID accesses the current model being used to power ChatGPT, which can change without warning. #752 (https://github.com/simonw/llm/issues/752) - New
llm logs -s/--shortflag bestie!! 💅 It hands you a greatly shortened version of the matching log entries in YAML format, with the prompt truncated and no response included at all.#737https://github.com/simonw/llm/issues/737 - Both
llm modelsandllm embed-modelsnow accept multiple-qsearch fragments 🦋 So like, you can hunt for every model matching both "gemini" and "exp" withllm models -q gemini -q exp. Obsessed.#748https://github.com/simonw/llm/issues/748 - New
llm embed-multi --prepend Xoption, which prepends a string to each value before it gets embedded ✨ Lowkey essential for models likenomic-embed-text-v2-moehttps://huggingface.co/nomic-ai/nomic-embed-text-v2-moethat need passages to start with a lil string like"search_document: ".#745https://github.com/simonw/llm/issues/745 - The
response.json()andresponse.usage()methods are now documented 💖#python-api-underlying-json - Fixed a bug where conversations loaded from the database just... could not be continued using asyncio prompts 😭
#742https://github.com/simonw/llm/issues/742 - New plugin for macOS girlies:
llm-mlxhttps://github.com/simonw/llm-mlx— it gives you extremely high performance accesshttps://simonwillison.net/2025/Feb/15/llm-mlx/to a whole range of local models using Apple's MLX framework. 👑 - The
llm-claude-3plugin has been renamed tollm-anthropichttps://github.com/simonw/llm-anthropic.
🌈 0.21 (2025-01-31)
- New model alert:
o3-mini🎀#728https://github.com/simonw/llm/issues/728 - The
o3-miniando1models now support areasoning_effortoption, which you can set tolow,mediumorhigh. Main character energy fr. llm promptandllm logsnow have a--xl/--extract-lastoption for extracting the last fenced code block in the response — the perfect complement to the existing--x/--extractoption 💅#717https://github.com/simonw/llm/issues/717
🌸 0.20 (2025-01-22)
- New model,
o1✨ Heads up though: this model does not yet support streaming.#676https://github.com/simonw/llm/issues/676 - The
o1-previewando1-minimodels now do support streaming 🦋 - New models,
gpt-4o-audio-previewandgpt-4o-mini-audio-preview.#677https://github.com/simonw/llm/issues/677 llm prompt -x/--extractoption, which returns just the content of the first fenced code block in the response 💖 Tryllm prompt -x 'Python function to reverse a string'.#681https://github.com/simonw/llm/issues/681- Creating a template using
llm ... --save xnow supports the-x/--extractoption, and it gets saved to the template 🎀 YAML templates can set this option usingextract: true. - New
llm logs -x/--extractoption extracts the first fenced code block from matching logged responses.
- Creating a template using
- New
llm models -q 'search'option, returning models that case-insensitively match the search query 🔍#700https://github.com/simonw/llm/issues/700 - Installation documentation now also includes
uv🙌 Thanks, Ariel Marcushttps://github.com/ajmarcus.#690https://github.com/simonw/llm/pull/690and#702https://github.com/simonw/llm/issues/702 - The
llm modelscommand now shows the current default model at the bottom of the listing ✨ Thanks, Amjith Ramanujamhttps://github.com/amjith.#688https://github.com/simonw/llm/pull/688 - The Plugin directory
#plugin-directorynow includesllm-venice,llm-bedrock,llm-deepseekandllm-cmd-comp🫶 - Fixed a bug where some dependency version combos could cause a
Client.__init__() got an unexpected keyword argument 'proxies'error 💀#709https://github.com/simonw/llm/issues/709 - OpenAI embedding models are now available using their full names —
text-embedding-ada-002,text-embedding-3-smallandtext-embedding-3-large— and the previous names are still supported as aliases 💜 Thanks, web-ssthttps://github.com/web-sst.#654https://github.com/simonw/llm/pull/654
🦋 0.19.1 (2024-12-05)
- Fixed a bug where
llm.get_models()andllm.get_async_models()returned the same model multiple times 😭#667https://github.com/simonw/llm/issues/667
⭐ 0.19 (2024-12-01)
- Tokens used by a response are now logged to new
input_tokensandoutput_tokensinteger columns plus atoken_detailsJSON string column — for the default OpenAI models and models from other plugins that implement this feature#advanced-model-plugins-usage💅#610https://github.com/simonw/llm/issues/610 llm promptnow takes a-u/--usageflag to display token usage at the end of the response ✨llm logs -u/--usageshows token usage information for logged responses.llm prompt ... --asyncresponses are now logged to the database 🔥#641https://github.com/simonw/llm/issues/641- New
llm.get_models()andllm.get_async_models()functions, documented here#python-api-listing-models🎀#640https://github.com/simonw/llm/issues/640 - New
response.usage()and asyncresponseawait response.usage()methods, returning aUsage(input=2, output=1, details=None)dataclass 💖#644https://github.com/simonw/llm/issues/644 - New
response.on_done(callback)andawait response.on_done(callback)methods for specifying a callback to be executed when a response has completed, documented here#python-api-response-on-done🦋#653https://github.com/simonw/llm/issues/653 - Fix for a bug running
llm chaton Windows 11 🙈 Thanks, Sukhbinder Singhhttps://github.com/sukhbinder.#495https://github.com/simonw/llm/issues/495
🌈 0.19a2 (2024-11-20)
llm.get_models()andllm.get_async_models()functions, documented here#python-api-listing-models✨#640https://github.com/simonw/llm/issues/640
🌸 0.19a1 (2024-11-19)
response.usage()and asyncresponseawait response.usage()methods, returning aUsage(input=2, output=1, details=None)dataclass 💜#644https://github.com/simonw/llm/issues/644
🎀 0.19a0 (2024-11-19)
- Tokens used by a response are now logged to new
input_tokensandoutput_tokensinteger columns plus atoken_detailsJSON string column — for the default OpenAI models and models from other plugins that implement this feature#advanced-model-plugins-usage💅#610https://github.com/simonw/llm/issues/610 llm promptnow takes a-u/--usageflag to display token usage at the end of the response ✨llm logs -u/--usageshows token usage information for logged responses.llm prompt ... --asyncresponses are now logged to the database 🔥#641https://github.com/simonw/llm/issues/641
👑 0.18 (2024-11-17)
- Initial support for async models 🦋 Plugins can now provide an
AsyncModelsubclass that you can access in the Python API using the newllm.get_async_model(model_id)method. See async models in the Python API docs#python-api-asyncand implementing async models in plugins#advanced-model-plugins-async.#507https://github.com/simonw/llm/issues/507 - All OpenAI models now include async models, so function calls like
llm.get_async_model("gpt-4o-mini")will return an async model 💅 - The
gpt-4o-audio-previewmodel can be used to send audio attachments to the GPT-4o audio model 🎧#608https://github.com/simonw/llm/issues/608 - Attachments can now be sent without requiring a prompt ✨
#611https://github.com/simonw/llm/issues/611 llm models --optionsnow includes information on whether a model supports attachments 🔍#612https://github.com/simonw/llm/issues/612llm models --asyncshows available async models.- Custom OpenAI-compatible models can now be marked as
can_stream: falsein the YAML if they don't support streaming 💖 Thanks, Chris Mungallhttps://github.com/cmungall.#600https://github.com/simonw/llm/pull/600 - Fixed a bug where OpenAI usage data was incorrectly serialized to JSON 😭
#614https://github.com/simonw/llm/issues/614 - Standardized on
audio/wavMIME type for audio attachments rather thanaudio/wave🎀#603https://github.com/simonw/llm/issues/603
🦋 0.18a1 (2024-11-14)
- Fixed a bug where conversations did not work for async OpenAI models 💀
#632https://github.com/simonw/llm/issues/632 __repr__methods forResponseandAsyncResponse✨
⭐ 0.18a0 (2024-11-13)
Alpha support for async models 💅 #507 https://github.com/simonw/llm/issues/507
Multiple smaller changes https://github.com/simonw/llm/compare/0.17.1...0.18a0.
🌈 0.17 (2024-10-29)
Support for attachments, letting multi-modal models accept images, audio, video and other formats 🫶 #578 https://github.com/simonw/llm/issues/578
The default OpenAI gpt-4o and gpt-4o-mini models can both now be prompted with JPEG, GIF, PNG and WEBP images 🖼️
Attachments in the CLI #usage-attachments can be URLs:
llm -m gpt-4o "describe this image" \
-a https://static.simonwillison.net/static/2024/pelicans.jpgOr file paths:
llm -m gpt-4o-mini "extract text" -a image1.jpg -a image2.jpgOr binary data, which may need --attachment-type to specify the MIME type:
cat image | llm -m gpt-4o-mini "extract text" --attachment-type - image/jpegAttachments are also available in the Python API #python-api-attachments:
model = llm.get_model("gpt-4o-mini")
response = model.prompt(
"Describe these images",
attachments=[
llm.Attachment(path="pelican.jpg"),
llm.Attachment(url="https://static.simonwillison.net/static/2024/pelicans.jpg"),
]
)Plugins that provide alternative models can support attachments too — see Attachments for multi-modal models #advanced-model-plugins-attachments for the deets 💅
The latest llm-claude-3 https://github.com/simonw/llm-claude-3 plugin now supports attachments for Anthropic's Claude 3 and 3.5 models 💜 The llm-gemini https://github.com/simonw/llm-gemini plugin supports attachments for Google's gemini-flash-latest model.
Also in this release: OpenAI models now record their "usage" data in the database even when the response was streamed ✨ These records can be viewed using llm logs --json. #591 https://github.com/simonw/llm/issues/591
🎀 0.17a0 (2024-10-28)
Alpha support for attachments 🌸 #578 https://github.com/simonw/llm/issues/578
👑 0.16 (2024-09-12)
- OpenAI models now use the internal
self.get_key()mechanism, which means they can be used from Python code in a way that picks up keys configured usingllm keys setor theOPENAI_API_KEYenvironment variable 🔑#552https://github.com/simonw/llm/issues/552. This code now works correctly:
import llm
print(llm.get_model("gpt-4o-mini").prompt("hi"))- New documented API methods:
llm.get_default_model(),llm.set_default_model(alias),llm.get_default_embedding_model(alias),llm.set_default_embedding_model(). #553 https://github.com/simonw/llm/issues/553 - Support for OpenAI's new o1 family https://openai.com/o1/ of preview models, so you can go
llm -m o1-preview "prompt"orllm -m o1-mini "prompt". ✨ Heads up bestie: these models are currently only available to tier 5 https://platform.openai.com/docs/guides/rate-limits/usage-tiers?context=tier-five OpenAI API users, though this may change in the future. #570 https://github.com/simonw/llm/issues/570
🎀 0.15 (2024-07-18) 🎀
- Support for OpenAI's new GPT-4o mini https://openai.com/index/gpt-4o-mini-advancing-cost-efficient-intelligence/ model — run
llm -m gpt-4o-mini 'rave about pelicans in French'and watch it go off 🐦 #536 https://github.com/simonw/llm/issues/536 gpt-4o-miniis now the default model if you don't specify your own default <#setup-default-model>, and it's replacing GPT-3.5 Turbo. Why? Because GPT-4o mini is both cheaper AND better than GPT-3.5 Turbo. it's giving upgrade, no cap.- Fixed a bug where
llm logs -q 'flourish' -m haikucould not combine both the-qsearch query and the-mmodel specifier. #515 https://github.com/simonw/llm/issues/515
🌈 0.14 (2024-05-13) 🌈
- Support for OpenAI's new GPT-4o https://openai.com/index/hello-gpt-4o/ model:
llm -m gpt-4o 'say hi in Spanish'🇪🇸 #490 https://github.com/simonw/llm/issues/490 - The
gpt-4-turboalias is now a model ID, which means it points at the latest version of OpenAI's GPT-4 Turbo text and image model. lowkey important: your existinglogs.dbdatabase may still contain records under the previous model ID ofgpt-4-turbo-preview. #493 https://github.com/simonw/llm/issues/493 - New
llm logs -r/--responseoption for outputting just the last captured response — no Markdown wrapping, no prompt tagging along with it. clean. ✨ #431 https://github.com/simonw/llm/issues/431 - Nine new plugins <#plugin-directory> since version 0.13, and every single one ate:
llm-claude-3https://github.com/simonw/llm-claude-3 supporting Anthropic's Claude 3 family https://www.anthropic.com/news/claude-3-family of models.llm-command-rhttps://github.com/simonw/llm-command-r supporting Cohere's Command R and Command R Plus https://txt.cohere.com/command-r-plus-microsoft-azure/ API models.llm-rekahttps://github.com/simonw/llm-reka supports the Reka https://www.reka.ai/ family of models via their API.llm-perplexityhttps://github.com/hex/llm-perplexity by Alexandru Geana, supporting the Perplexity Labs https://docs.perplexity.ai/ API models — includingllama-3-sonar-large-32k-onlinewhich can search for things online, plusllama-3-70b-instruct.llm-groqhttps://github.com/angerman/llm-groq by Moritz Angermann, giving you access to the fast models hosted by Groq https://console.groq.com/docs/models.llm-fireworkshttps://github.com/simonw/llm-fireworks supporting models hosted by Fireworks AI https://fireworks.ai/.llm-togetherhttps://github.com/wearedevx/llm-together adds support for the Together AI https://www.together.ai/ extensive family of hosted openly licensed models.llm-embed-onnxhttps://github.com/simonw/llm-embed-onnx provides seven embedding models that can be executed using the ONNX model framework.llm-cmdhttps://github.com/simonw/llm-cmd accepts a prompt for a shell command, runs that prompt and populates the result in your shell so you can review it, edit it and then hit<enter>to execute orctrl+cto cancel — see this post for details https://simonwillison.net/2024/Mar/26/llm-cmd/. 💅
🦋 0.13.1 (2024-01-26) 🦋
- Fix for
No module named 'readline'error on Windows. #407 https://github.com/simonw/llm/issues/407
🌸 0.13 (2024-01-26) 🌸
See also LLM 0.13: The annotated release notes https://simonwillison.net/2024/Jan/26/llm/.
- Added support for new OpenAI embedding models:
3-smalland3-largeand three variants of those with different dimension sizes,3-small-512,3-large-256and3-large-1024. See OpenAI embedding models <#openai-models-embedding> for details. #394 https://github.com/simonw/llm/issues/394 - The default
gpt-4-turbomodel alias now points togpt-4-turbo-preview, which uses the most recent OpenAI GPT-4 turbo model (currentlygpt-4-0125-preview). #396 https://github.com/simonw/llm/issues/396 - New OpenAI model aliases
gpt-4-1106-previewandgpt-4-0125-preview. - OpenAI models now support a
-o json_object 1option which will cause their output to be returned as a valid JSON object. #373 https://github.com/simonw/llm/issues/373 - New plugins <#plugin-directory> since the last release include
llm-mistralhttps://github.com/simonw/llm-mistral,llm-geminihttps://github.com/simonw/llm-gemini,llm-ollamahttps://github.com/taketwo/llm-ollama andllm-bedrock-metahttps://github.com/flabat/llm-bedrock-meta. - The
keys.jsonfile for storing API keys is now created with600file permissions. 🔒 #351 https://github.com/simonw/llm/issues/351 - Documented a pattern <#homebrew-warning> for installing plugins that depend on PyTorch using the Homebrew version of LLM, despite Homebrew using Python 3.12 when PyTorch have not yet released a stable package for that Python version. #397 https://github.com/simonw/llm/issues/397
- Underlying OpenAI Python library has been upgraded to
>1.0. ⚠️ It is possible this could cause compatibility issues with LLM plugins that also depend on that library. #325 https://github.com/simonw/llm/issues/325 - Arrow keys now work inside the
llm chatcommand. ⬆️⬇️ #376 https://github.com/simonw/llm/issues/376 LLM_OPENAI_SHOW_RESPONSES=1environment variable now outputs much more detailed information about the HTTP request and response made to OpenAI (and OpenAI-compatible) APIs. #404 https://github.com/simonw/llm/issues/404- Dropped support for Python 3.7. 💀
⭐ 0.12 (2023-11-06) ⭐
- Support for the new GPT-4 Turbo model https://openai.com/blog/new-models-and-developer-products-announced-at-devday from OpenAI. Try it using
llm chat -m gpt-4-turboorllm chat -m 4t. #323 https://github.com/simonw/llm/issues/323 - New
-o seed 1option for OpenAI models which sets a seed that can attempt to evaluate the prompt deterministically. 🎲 #324 https://github.com/simonw/llm/issues/324
💜 0.11.2 (2023-11-06) 💜
- Pin to version of OpenAI Python library prior to 1.0 to avoid breaking. #327 https://github.com/simonw/llm/issues/327
🍓 0.11.1 (2023-10-31) 🍓
- Fixed a bug where
llm embed -c "text"did not correctly pick up the configured default embedding model <#embeddings-cli-embed-models-default>. #317 https://github.com/simonw/llm/issues/317 - New plugins:
llm-pythonhttps://github.com/simonw/llm-python,llm-bedrock-anthropichttps://github.com/sblakey/llm-bedrock-anthropic andllm-embed-jinahttps://github.com/simonw/llm-embed-jina (described in Execute Jina embeddings with a CLI using llm-embed-jina https://simonwillison.net/2023/Oct/26/llm-embed-jina/). llm-gpt4allhttps://github.com/simonw/llm-gpt4all now uses the new GGUF model format. simonw/llm-gpt4all#16 https://github.com/simonw/llm-gpt4all/issues/16
🧚 0.11 (2023-09-18) 🧚
LLM now supports the new OpenAI gpt-3.5-turbo-instruct model, and OpenAI completion (as opposed to chat completion) models in general. #284 https://github.com/simonw/llm/issues/284
llm -m gpt-3.5-turbo-instruct 'Reasons to tame a wild beaver:'OpenAI completion models like this support a -o logprobs 3 option, which accepts a number between 1 and 5 and will include the log probabilities (for each produced token, what were the top 3 options considered by the model) in the logged response. 🧠
llm -m gpt-3.5-turbo-instruct 'Say hello succinctly' -o logprobs 3You can then view the logprobs that were recorded in the SQLite logs database like this:
sqlite-utils "$(llm logs path)" \
'select * from responses order by id desc limit 1' | \
jq '.[0].response_json' -r | jqTruncated output looks like this:
[
{
"text": "Hi",
"top_logprobs": [
{
"Hi": -0.13706253,
"Hello": -2.3714375,
"Hey": -3.3714373
}
]
},
{
"text": " there",
"top_logprobs": [
{
" there": -0.96057636,
"!\"": -0.5855763,
".\"": -3.2574513
}
]
}
]Also in this release:
- The
llm.user_dir()function, used by plugins, now ensures the directory exists before returning it. #275 https://github.com/simonw/llm/issues/275 - New
LLM_OPENAI_SHOW_RESPONSES=1environment variable for displaying the full HTTP response returned by OpenAI compatible APIs. #286 https://github.com/simonw/llm/issues/286 - The
llm embed-multicommand now has a--batch-size Xoption for setting the batch size to use when processing embeddings — useful if you have limited memory available. 🫶 #273 https://github.com/simonw/llm/issues/273 - The
collection.embed_multi()method also now accepts an optionalbatch_size=intargument. - Fixed two bugs with
llm embed-multi --filesrelating to handling of directories. Thanks, ealvar3z https://github.com/ealvar3z. #274 https://github.com/simonw/llm/issues/274, #280 https://github.com/simonw/llm/issues/280
👑 0.10 (2023-09-12) 👑
The two major features in this release are the llm chat command <#usage-chat> and support for embedding binary data. 🤯
See Build an image search engine with llm-clip, chat with models with llm chat https://simonwillison.net/2023/Sep/12/llm-clip-and-chat/ for more background on these features.
💬 llm chat 💬
The new llm chat command starts an ongoing chat conversation with a model in your terminal. It works with all models supported by LLM and its plugins <#plugins>, including locally installed models such as Llama 2. #231 https://github.com/simonw/llm/issues/231
This offers a big performance boost for local models, since they don't need to be freshly loaded into memory for each prompt. ⚡
Here's an example chat with Llama 2 13B, provided by the llm-mlc https://github.com/simonw/llm-mlc plugin.
llm chat -m mlc-chat-Llama-2-13b-chat-hf-q4f16_1This starts a chat session:
Type 'exit' or 'quit' to exit
Type '!multi' to enter multiple lines, then '!end' to finish
Type '!edit' to open your default editor and modify the prompt.
> Who are you?
Hello! I'm just an AI, here to assist you with any questions you may have.
My name is LLaMA, and I'm a large language model trained to provide helpful
and informative responses to a wide range of questions and topics. I'm here
to help you find the information you need, while ensuring a safe and
respectful conversation. Please feel free to ask me anything, and I'll do my
best to provide a helpful and accurate response.
> Tell me a joke about otters
Sure, here's a joke about otters:
Why did the otter go to the party?
Because he heard it was a "whale" of a time!
(Get it? Whale, like a big sea mammal, but also a "wild" or "fun" time.
Otters are known for their playful and social nature, so it's a lighthearted
and silly joke.)
I hope that brought a smile to your face! Do you have any other questions or
topics you'd like to discuss?
> exitOk bestie, chat sessions are logged to SQLite (#logging) — run llm logs to go look at them 💅. And they can accept system prompts, templates and model options, so if you wanna know the deets, consult the chat documentation (#usage-chat). Periodt.
🦋 Binary embedding support
LLM's embeddings feature (#embeddings) has been expanded to provide support for embedding binary data, in addition to text. #254 (https://github.com/simonw/llm/pull/254)
This enables models like CLIP (https://openai.com/research/clip), supported by the new llm-clip plugin (https://github.com/simonw/llm-clip).
CLIP is a multi-modal embedding model which can embed images and text into the same vector space. This means you can use it to create an embedding index of photos, and then search for the embedding vector for "a happy dog" and get back images that are semantically closest to that string. It's giving semantic search but for your camera roll 🐶📸
To create embeddings for every JPEG in a directory stored in a photos collection, run:
llm install llm-clip
llm embed-multi photos --files photos/ '*.jpg' --binary -m clipNow you can search for photos of raccoons using:
llm similar photos -c 'raccoon'This spits out a list of images, ranked by how similar they are to the string "raccoon":
{"id": "IMG_4801.jpeg", "score": 0.28125139257127457, "content": null, "metadata": null}
{"id": "IMG_4656.jpeg", "score": 0.26626441704164294, "content": null, "metadata": null}
{"id": "IMG_2944.jpeg", "score": 0.2647445926996852, "content": null, "metadata": null}
...✨ Also in this release
- The
LLM_LOAD_PLUGINSenvironment variable (#llm-load-plugins) can be used to control which plugins are loaded whenllmstarts running.#256(https://github.com/simonw/llm/issues/256) - The
llm plugins --alloption includes builtin plugins in the list of plugins.#259(https://github.com/simonw/llm/issues/259) - The
llm embed-dbfamily of commands has been renamed tollm collections.#229(https://github.com/simonw/llm/issues/229) llm embed-multi --filesnow has an--encodingoption and defaults to falling back tolatin-1if a file cannot be processed asutf-8.#225(https://github.com/simonw/llm/issues/225)
💖 0.10a1 (2023-09-11)
- Support for embedding binary data.
#254(https://github.com/simonw/llm/pull/254) llm chatnow works for models with API keys.#247(https://github.com/simonw/llm/issues/247)llm chat -ofor passing options to a model.#244(https://github.com/simonw/llm/issues/244)llm chat --no-streamoption.#248(https://github.com/simonw/llm/issues/248)LLM_LOAD_PLUGINSenvironment variable.#256(https://github.com/simonw/llm/issues/256)llm plugins --alloption for including builtin plugins.#259(https://github.com/simonw/llm/issues/259)llm embed-dbhas been renamed tollm collections.#229(https://github.com/simonw/llm/issues/229)- Fixed bug where
llm embed -coption was treated as a filepath, not a string. Thanks, mhalle (https://github.com/mhalle).#263(https://github.com/simonw/llm/pull/263)
🌸 0.10a0 (2023-09-04)
- New
llm chat(#usage-chat) command for starting an interactive terminal chat with a model.#231(https://github.com/simonw/llm/issues/231) llm embed-multi --filesnow has an--encodingoption and defaults to falling back tolatin-1if a file cannot be processed asutf-8.#225(https://github.com/simonw/llm/issues/225)
🎀 0.9 (2023-09-03)
The big new feature in this release is support for embeddings. See LLM now provides tools for working with embeddings (https://simonwillison.net/2023/Sep/4/llm-embeddings/) for additional details.
Embedding models (#embeddings) take a piece of text — a word, sentence, paragraph or even a whole article — and convert that into an array of floating point numbers. #185 (https://github.com/simonw/llm/issues/185)
This embedding vector can be thought of as representing a position in many-dimensional-space, where the distance between two vectors represents how semantically similar they are to each other within the content of a language model. no cap, that's the whole vibe.
Embeddings can be used to find related documents, and also to implement semantic search — where a user can search for a phrase and get back results that are semantically similar to that phrase even if they do not share any exact keywords. the way that works is genuinely iconic ✨
LLM now provides both CLI and Python APIs for working with embeddings. Embedding models are defined by plugins, so you can install additional models using the plugins mechanism (#installing-plugins).
The first two embedding models supported by LLM are:
- OpenAI's ada-002 (https://platform.openai.com/docs/guides/embeddings) embedding model, available via an inexpensive API if you set an OpenAI key using
llm keys set openai. - The sentence-transformers (https://www.sbert.net/) family of models, available via the new
llm-sentence-transformersplugin (https://github.com/simonw/llm-sentence-transformers).
See Embedding with the CLI (#embeddings-cli) for detailed instructions on working with embeddings using LLM.
The new commands for working with embeddings are:
llm embed(#embeddings-cli-embed) — calculate embeddings for content and return them to the console or store them in a SQLite database.llm embed-multi(#embeddings-cli-embed-multi) — run bulk embeddings for multiple strings, using input from a CSV, TSV or JSON file, data from a SQLite database or data found by scanning the filesystem.#215(https://github.com/simonw/llm/issues/215)llm similar(#embeddings-cli-similar) — run similarity searches against your stored embeddings — starting with a search phrase or finding content related to a previously stored vector.#190(https://github.com/simonw/llm/issues/190)llm embed-models(#embeddings-cli-embed-models) — list available embedding models.llm embed-db— commands for inspecting and working with the default embeddings SQLite database.
There's also a new llm.Collection (#embeddings-python-collections) class for creating and searching collections of embedding from Python code, and a llm.get_embedding_model() (#embeddings-python-api) interface for embedding strings directly. #191 (https://github.com/simonw/llm/issues/191)
💅 0.8.1 (2023-08-31)
- Fixed bug where first prompt would show an error if the
io.datasette.llmdirectory had not yet been created.#193(https://github.com/simonw/llm/issues/193) - Updated documentation to recommend a different
llm-gpt4allmodel since the one we were using is no longer available.#195(https://github.com/simonw/llm/issues/195)
🦋 0.8 (2023-08-20)
- The output format for
llm logshas changed. Previously it was JSON — it's now a much more readable Markdown format suitable for pasting into other documents.#160(https://github.com/simonw/llm/issues/160)- The new
llm logs --jsonoption can be used to get the old JSON format. - Pass
llm logs --conversation IDor--cid IDto see the full logs for a specific conversation.
- The new
- You can now combine piped input and a prompt in a single command:
cat script.py | llm 'explain this code'. This works even for models that do not support system prompts (#usage-system-prompts).#153(https://github.com/simonw/llm/issues/153) - Additional OpenAI-compatible models (
#openai-compatible-models) can now be configured with custom HTTP headers. This enables platforms such as openrouter.ai (https://openrouter.ai/) to be used with LLM, which can provide Claude access even without an Anthropic API key. 🔥 - Keys set in
keys.jsonare now used in preference to environment variables.#158(https://github.com/simonw/llm/issues/158) - The documentation now includes a plugin directory (
#plugin-directory) listing all available plugins for LLM.#173(https://github.com/simonw/llm/issues/173) - New related tools (
#related-tools) section in the documentation describingttok,strip-tagsandsymbex.#111(https://github.com/simonw/llm/issues/111) - The
llm models,llm aliasesandllm templatescommands now default to running the same command asllm models listandllm aliases listandllm templates list.#167(https://github.com/simonw/llm/issues/167) - New
llm keys(akallm keys list) command for listing the names of all configured keys.#174(https://github.com/simonw/llm/issues/174) - Two new Python API functions,
llm.set_alias(alias, model_id)andllm.remove_alias(alias)can be used to configure aliases from within Python code.#154(https://github.com/simonw/llm/pull/154) - LLM is now compatible with both Pydantic 1 and Pydantic 2. This means you can install
llmas a Python dependency in a project that depends on Pydantic 1 without running into dependency conflicts. Thanks, Chris Mungall (https://github.com/cmungall).#147(https://github.com/simonw/llm/pull/147) llm.get_model(model_id)is now documented as raisingllm.UnknownModelErrorif the requested model does not exist.#155(https://github.com/simonw/llm/issues/155)
🌈 0.7.1 (2023-08-19)
- Fixed a bug where some users would see an
AlterError: No such column: log.iderror when attempting to use this tool, after upgrading to the latest sqlite-utils 3.35 release (https://sqlite-utils.datasette.io/en/stable/changelog.html#v3-35).#162(https://github.com/simonw/llm/issues/162)
👑 0.7 (2023-08-12)
The new Model aliases (#aliases) commands can be used to configure additional aliases for models, for example:
llm aliases set turbo gpt-3.5-turbo-16kNow you can run the 16,000 token gpt-3.5-turbo-16k model like this:
llm -m turbo 'An epic Greek-style saga about a cheesecake that builds a SQL database from scratch'and to see all your lil aliases just run llm aliases list, and if one's gotta go it's llm aliases remove turbo 💅 — see issue #151 (https://github.com/simonw/llm/issues/151)
🌈 Notable new plugins
llm-mlc— (https://github.com/simonw/llm-mlc) can run local models released by the MLC project (https://mlc.ai/mlc-llm/), and yes bestie that includes models that can take advantage of the GPU on Apple Silicon M1/M2 devices 🔥llm-llama-cpp— (https://github.com/simonw/llm-llama-cpp) uses llama.cpp (https://github.com/ggerganov/llama.cpp) to run models published in the GGML format. For more deets go read Run Llama 2 on your own Mac using LLM and Homebrew (https://simonwillison.net/2023/Aug/1/llama-2-mac/) ✨
✨ Also in this release
- OpenAI models now have
minandmaxvalidation on their floating point options. Thanks, Pavel Král. #115 (https://github.com/simonw/llm/issues/115) - Fixed the bug where
llm templates listwould straight up raise an error if a template had an empty prompt. Thanks, Sherwin Daganato. #132 (https://github.com/simonw/llm/pull/132) - Squashed a bug in the
llm install --editableoption that was blocking installation of.[test]. #136 (https://github.com/simonw/llm/issues/136) - Added the
llm install --no-cache-dirand--force-reinstalloptions. #146 (https://github.com/simonw/llm/issues/146)
🎀 0.6.1 (2023-07-24)
- LLM can now be installed directly from Homebrew core:
brew install llm. #124 (https://github.com/simonw/llm/issues/124) - The Python API documentation now covers System prompts (#python-api-system-prompts) 🫶
- Fixed an incorrect example in the Templates (#prompt-templates) documentation. Thanks, Jorge Cabello. #125 (https://github.com/simonw/llm/pull/125)
💜 0.6 (2023-07-18)
- Models hosted on Replicate (https://replicate.com/) can now be accessed using the
llm-replicate(https://github.com/simonw/llm-replicate) plugin, including the brand new Llama 2 model from Meta AI. More details right here: Accessing Llama 2 from the command-line with the llm-replicate plugin (https://simonwillison.net/2023/Jul/18/accessing-llama-2/). - Model providers that expose an API that is compatible with the OpenAPI API format — including self-hosted model servers such as LocalAI (https://github.com/go-skynet/LocalAI) — can now be accessed using additional configuration (#openai-compatible-models) for the default OpenAI plugin. #106 (https://github.com/simonw/llm/issues/106)
- OpenAI models that LLM doesn't support yet can also be configured (#openai-extra-models) using the shiny new
extra-openai-models.yamlconfiguration file. #107 (https://github.com/simonw/llm/issues/107) - The
llm logscommand (#logging-view) now accepts a-m model_idoption so you can filter logs down to one specific model. And you can use aliases here too, not just model IDs. #108 (https://github.com/simonw/llm/issues/108) - Logs now have a SQLite full-text search index against their prompts and responses, and the
llm logs -q SEARCHoption can be used to return logs that match a search term 🔍 #109 (https://github.com/simonw/llm/issues/109)
🦋 0.5 (2023-07-12)
LLM now supports additional language models, all thanks to a new plugins mechanism (#installing-plugins) for installing additional models 👑
Plugins are available for 19 models in addition to the default OpenAI ones:
llm-gpt4all(https://github.com/simonw/llm-gpt4all) adds support for 17 models that can download and run on your own device, including Vicuna, Falcon and wizardLM.llm-mpt30b(https://github.com/simonw/llm-mpt30b) adds support for the MPT-30B model, a 19GB download.llm-palm(https://github.com/simonw/llm-palm) adds support for Google's PaLM 2 via the Google API.
There's also a comprehensive tutorial, writing a plugin to support a new model (#tutorial-model-plugin), that walks you through adding new models by building plugins in detail.
🌸 New features
- Python API (#python-api) documentation for using LLM models, including models from plugins, directly from Python. #75 (https://github.com/simonw/llm/issues/75)
- Messages are now logged to the database by default — no need to run the
llm init-dbcommand any more, which has been removed. Instead, you can toggle this behavior off usingllm logs offor turn it on again usingllm logs on. Thellm logs statuscommand shows the current status of the log database. And if logging is turned off, passing--logto thellm promptcommand will cause that prompt to be logged anyway. #98 (https://github.com/simonw/llm/issues/98) - New database schema for logged messages, with
conversationsandresponsestables. If you have previously used the oldlogstable it will continue to exist but will no longer be written to. #91 (https://github.com/simonw/llm/issues/91) - New
-o/--option name valuesyntax for setting options for models, such astemperature. Available options differ for different models. #63 (https://github.com/simonw/llm/issues/63) llm models list --optionscommand for viewing all available model options. #82 (https://github.com/simonw/llm/issues/82)llm "prompt" --save templateoption for saving a prompt directly to a template. #55 (https://github.com/simonw/llm/issues/55)- Prompt templates can now specify default values (#prompt-default-parameters) for parameters. Thanks, Chris Mungall. #57 (https://github.com/simonw/llm/pull/57)
llm openai modelscommand to list all available OpenAI models from their API. #70 (https://github.com/simonw/llm/issues/70)llm models default MODEL_IDto set a different model as the default to be used whenllmis run without the-m/--modeloption. #31 (https://github.com/simonw/llm/issues/31)
🍓 Smaller improvements
llm -sis now a shortcut forllm --system. #69 (https://github.com/simonw/llm/issues/69)llm -m 4-32kalias forgpt-4-32k.llm install -e directorycommand for installing a plugin from a local directory.- The
LLM_USER_PATHenvironment variable now controls the location of the directory in which LLM stores its data. This replaces the oldLLM_KEYS_PATHandLLM_LOG_PATHandLLM_TEMPLATES_PATHvariables. #76 (https://github.com/simonw/llm/issues/76) - Documentation covering Utility functions for plugins (#plugin-utilities).
- The documentation site now uses Plausible for analytics. #79 (https://github.com/simonw/llm/issues/79)
🧚 0.4.1 (2023-06-17)
- LLM can now be installed using Homebrew:
brew install simonw/llm/llm. #50 (https://github.com/simonw/llm/issues/50) llmis now styled LLM in the documentation. #45 (https://github.com/simonw/llm/issues/45)- Examples in the documentation now include a copy button. #43 (https://github.com/simonw/llm/issues/43)
- The
llm templatescommand no longer has its display disrupted by newlines. #42 (https://github.com/simonw/llm/issues/42) - The
llm templatescommand now includes the system prompt, if set. #44 (https://github.com/simonw/llm/issues/44)
💀 0.4 (2023-06-17)
⚠️ Okay bestie listen up — this release includes some backwards-incompatible changes. Read these before you upgrade, fr fr.
- The
-4option for GPT-4 is now-m 4. - The
--codeoption has been removed. - The
-soption has been removed as streaming is now the default. Use--no-streamto opt out of streaming.
🌈 Prompt templates
Templates (#prompt-templates) is a new feature that allows prompts to be saved as templates and re-used with different variables. Iconic behaviour honestly.
Templates can be created using the llm templates edit command:
llm templates edit summarizeTemplates are YAML — the following template defines summarization using a system prompt:
system: Summarize this textThe template can then be executed like this:
cat myfile.txt | llm -t summarizeTemplates can include both system prompts, regular prompts and indicate the model they should use. They can reference variables such as $input for content piped to the tool, or other variables that are passed using the new -p/--param option.
This example adds a voice parameter:
system: Summarize this text in the voice of $voiceThen to run it (via strip-tags (https://github.com/simonw/strip-tags) to remove HTML tags from the input):
curl -s 'https://til.simonwillison.net/macos/imovie-slides-and-audio' | \
strip-tags -m | llm -t summarize -p voice GlaDOSExample output:
My previous test subject seemed to have learned something new about
iMovie. They exported keynote slides as individual images [...] Quite
impressive for a human.The Templates (#prompt-templates) documentation provides more detailed examples.
👑 Continue previous chat
You can now use llm to continue a previous conversation with the OpenAI chat models (gpt-3.5-turbo and gpt-4). This will include your previous prompts and responses in the prompt sent to the API, allowing the model to continue within the same context. It's giving memory 💅
Use the new -c/--continue option to continue from the previous message thread:
llm "Pretend to be a witty gerbil, say hi briefly"
Greetings, dear human! I am a clever gerbil, ready to entertain you
with my quick wit and endless energy.
llm "What do you think of snacks?" -c
Oh, how I adore snacks, dear human! Crunchy carrot sticks, sweet
apple slices, and chewy yogurt drops are some of my favorite treats.
I could nibble on them all day long!The -c option will continue from the most recent logged message.
To continue a different chat, pass an integer ID to the --chat option. This should be the ID of a previously logged message. You can find these IDs using the llm logs command.
Thanks Amjith Ramanujam (https://github.com/amjith) for contributing to this feature. #6 (https://github.com/simonw/llm/issues/6)
🔑 New mechanism for storing API keys
API keys for language models such as those by OpenAI can now be saved using the new llm keys family of commands.
To set the default key to be used for the OpenAI APIs, run this:
llm keys set openaiThen paste in your API key. Easy ✨
Keys can also be passed using the new --key command line option — this can be a full key or the alias of a key that has been previously stored.
See API key management (#api-keys) for more. #13 (https://github.com/simonw/llm/issues/13)
🫶 New location for the logs.db database
The logs.db database that stores a history of executed prompts no longer lives at ~/.llm/log.db — it can now be found in a location that better fits the host operating system, which can be seen using:
llm logs pathOn macOS this is ~/Library/Application Support/io.datasette.llm/logs.db.
To open that database using Datasette, run this:
datasette "$(llm logs path)"Okay so you can also just upgrade your existing setup by copying your database over to the new spot, like this:
cp ~/.llm/log.db "$(llm logs path)"
rm -rf ~/.llm # To tidy up the now obsolete directoryHeads up bestie: the database schema has changed, and it'll update itself automatically the very first time you run the command. No manual migration, she's self-healing 💅
That schema is documented over here: https://llm.datasette.io/en/stable/logging.html#sql-schema — that's issue #35, https://github.com/simonw/llm/issues/35.
🌸 Other changes 🌸
- New
llm logs --truncateoption (shortcut-t) which truncates the displayed prompts so the log output is way easier to read. #16https://github.com/simonw/llm/issues/16 - Documentation now spans multiple pages and lives at
https://llm.datasette.io/#21https://github.com/simonw/llm/issues/21 - The default
llm chatgptcommand got renamed tollm prompt. Glow-up era. #17https://github.com/simonw/llm/issues/17 - Removed the
--codeoption in favour of the new prompt templates mechanism. #24https://github.com/simonw/llm/issues/24 - Responses are now streamed by default, if the model supports streaming. The
-s/--streamoption has been removed. There's a new--no-streamoption you can use to opt out of streaming. #25https://github.com/simonw/llm/issues/25 - The
-4/--gpt4option has been removed in favour of-m 4or-m gpt4, using a new mechanism that lets models have additional short names. - The new
gpt-3.5-turbo-16kmodel with a 16,000 token context length can now also be accessed using-m chatgpt-16kor-m 3.5-16k. Thanks, Benjamin Kirkbride. #37https://github.com/simonw/llm/issues/37 - Improved display of error messages from OpenAI. #15
https://github.com/simonw/llm/issues/15
🎀 0.3 (2023-05-17)
llm logscommand for browsing logs of previously executed completions. #3https://github.com/simonw/llm/issues/3llm "Python code to output factorial 10" --codeoption which sets a system prompt designed to encourage code to be output without any additional explanatory text. #5https://github.com/simonw/llm/issues/5- Tool can now accept a prompt piped directly to standard input. #11
https://github.com/simonw/llm/issues/11
🌈 0.2 (2023-04-01)
- If a SQLite database exists in
~/.llm/log.dball prompts and responses are logged to that file. Thellm init-dbcommand can be used to create this file. #2https://github.com/simonw/llm/issues/2
⭐ 0.1 (2023-04-01)
- Initial prototype release. #1
https://github.com/simonw/llm/issues/1
👑 Author
Simon Willison
💜 Copyright
2025, Simon Willison
And that's a wrap on the whole page, bestie!! 🫶 This is LLM(1), dated Sep 03, 2026 — go forth and prompt responsibly, you absolute icon ✨💅🎀
📦 where this page comes from
- fedora 44: python3-llm 0.34-1.fc44 · Apache-2.0
- 💖 girlified by deepseek-ai/DeepSeek-V4.1-Flash on : a language model's rewrite of the original, under its terms