LLAMA-SERVER(1)
💅 LLAMA-SERVER(1) 💅
okay so hi bestie!! 💖 this is llama-server, and it lives in the User Commands manual — that's section 1, if you're keeping score, and you should be, because you're that girl. grab a strawberry 🍓, get comfy, and let's go through every single flag together. no skipping. we don't skip here.
✨ NAME ✨
llama-server — llama-server.
that's it. that's the name. short, sweet, iconic, she ate 👑
🎀 DESCRIPTION 🎀
----- common params -----
the shared ones. the group-chat classics. 💬
-h,--help,--usage— prints the usage and then dips immediately. exit, stage left 👋--version— shows you the version and build info ⭐-cl,--cache-list— shows the list of models chillin' in your cache 🧚--completion-bash— prints a source-able bash completion script forllama.cpp. not her making your shell smarter 💅-t,--threads N— how many CPU threads to use during generation (default:<num_cpus>). env:LLAMA_ARG_THREADS🔥-tb,--threads-batch N— how many threads to use during batch and prompt processing (default: same as--threads)-C,--cpu-mask M— CPU affinity mask: an arbitrarily long hex. complementscpu-range(default:"")-Cr,--cpu-range lo-hi— a range of CPUs for affinity. complements--cpu-mask--cpu-strict <0|1>— use strict CPU placement (default:0)--prio N— set the process/thread priority: low(-1), normal(0), medium(1), high(2), realtime(3) (default:0)--poll <0...100>— use this polling level to wait for work (0- no polling, default:50)-Cb,--cpu-mask-batch M— CPU affinity mask: arbitrarily long hex. complementscpu-range-batch(default: same as--cpu-mask)-Crb,--cpu-range-batch lo-hi— ranges of CPUs for affinity. complements--cpu-mask-batch--cpu-strict-batch <0|1>— use strict CPU placement (default: same as--cpu-strict)--prio-batch N— set the process/thread priority:0-normal,1-medium,2-high,3-realtime (default:0)--poll-batch <0|1>— use polling to wait for work (default: same as--poll)-c,--ctx-size N— the size of the prompt context (default:0, and0= loaded from model). env:LLAMA_ARG_CTX_SIZE🌈-n,--predict,--n-predict N— how many tokens to predict (default:-1, and-1= infinity ♾️). env:LLAMA_ARG_N_PREDICT-b,--batch-size N— logical maximum batch size (default:2048). env:LLAMA_ARG_BATCH-ub,--ubatch-size N— physical maximum batch size (default:512). env:LLAMA_ARG_UBATCH--keep N— how many tokens to keep from the initial prompt (default:0,-1= all)--swa-full— use the full-size SWA cache (default:false). there's more info athttps://github.com/ggml-org/llama.cpp/pull/13194#issuecomment-2868343055if you're nosy 👀 env:LLAMA_ARG_SWA_FULL-fa,--flash-attn [on|off|auto]— set Flash Attention use ('on','off', or'auto', default:'auto'). env:LLAMA_ARG_FLASH_ATTN⚡--perf,--no-perf— whether to enable internallibllamaperformance timings (default:false). env:LLAMA_ARG_PERF-e,--escape,--no-escape— whether to process escapes sequences (\n,\r,\t,\',\",\\) (default:true)--rope-scaling {none,linear,yarn}— RoPE frequency scaling method, defaults tolinearunless the model says otherwise. env:LLAMA_ARG_ROPE_SCALING_TYPE--rope-scale N— RoPE context scaling factor, expands context by a factor of N. env:LLAMA_ARG_ROPE_SCALE--rope-freq-base N— RoPE base frequency, the one NTK-aware scaling uses (default: loaded from model). env:LLAMA_ARG_ROPE_FREQ_BASE--rope-freq-scale N— RoPE frequency scaling factor, expands context by a factor of1/N. env:LLAMA_ARG_ROPE_FREQ_SCALE--yarn-orig-ctx N— YaRN: original context size of model (default:0= model training context size). env:LLAMA_ARG_YARN_ORIG_CTX--yarn-ext-factor N— YaRN: extrapolation mix factor (default:-1.00,0.0= full interpolation). env:LLAMA_ARG_YARN_EXT_FACTOR--yarn-attn-factor N— YaRN: scalesqrt(t)or attention magnitude (default:-1.00). env:LLAMA_ARG_YARN_ATTN_FACTOR--yarn-beta-slow N— YaRN: high correction dim or alpha (default:-1.00). env:LLAMA_ARG_YARN_BETA_SLOW--yarn-beta-fast N— YaRN: low correction dim or beta (default:-1.00). env:LLAMA_ARG_YARN_BETA_FAST-kvo,--kv-offload,-nkvo,--no-kv-offload— whether to enable KV cache offloading (default: enabled). env:LLAMA_ARG_KV_OFFLOAD--repack,-nr,--no-repack— whether to enable weight repacking (default: enabled). env:LLAMA_ARG_REPACK--no-host— bypass the host buffer, allowing extra buffers to be used. env:LLAMA_ARG_NO_HOST-ctk,--cache-type-k TYPE— KV cache data type for K. allowed values:f32,f16,bf16,q8_0,q4_0,q4_1,iq4_nl,q5_0,q5_1(default:f16). env:LLAMA_ARG_CACHE_TYPE_K-ctv,--cache-type-v TYPE— KV cache data type for V. allowed values:f32,f16,bf16,q8_0,q4_0,q4_1,iq4_nl,q5_0,q5_1(default:f16). env:LLAMA_ARG_CACHE_TYPE_V-dt,--defrag-thold N— KV cache defragmentation threshold (DEPRECATED ⚠️). env:LLAMA_ARG_DEFRAG_THOLD--mlock— DEPRECATED in favor of--load-mode: force the system to keep the model in RAM rather than swapping or compressing it. env:LLAMA_ARG_MLOCK--mmap,--no-mmap— DEPRECATED in favor of--load-mode: whether to memory-map the model. (if mmap is disabled, loads are slower but it may reduce pageouts if you're not using mlock). env:LLAMA_ARG_MMAP-dio,--direct-io,-ndio,--no-direct-io— DEPRECATED in favor of--load-mode: use DirectIO if it's available. env:LLAMA_ARG_DIO-lm,--load-mode MODE— model loading mode (default:auto). the modes are:auto: mmap, unless a device doesn't support itnone: no special loading modemmap: memory-map the model (if mmap is disabled, slower load but may reduce pageouts if not using mlock)mlock: force the system to keep the model in RAM rather than swapping or compressingmmap+mlock: mmap + force the system to keep the model in RAM rather than swapping or compressingdio: use DirectIO if available
env: LLAMA_ARG_LOAD_MODE
--numa TYPE— attempt optimizations that help on some NUMA systems:distribute: spread execution evenly over all nodesisolate: only spawn threads on CPUs on the node that execution started onnumactl: use the CPU map provided by numactl
if you ran without this previously, it's recommended that you drop the system page cache before using this. see https://github.com/ggml-org/llama.cpp/issues/1437. env: LLAMA_ARG_NUMA
-dev,--device <dev1,dev2,..>— comma-separated list of devices to use for offloading (none= don't offload). use--list-devicesto see a list of the available devices. env:LLAMA_ARG_DEVICE--list-devices— print the list of available devices and exit 📋-ot,--override-tensor <tensor name pattern>=<buffer type>,...— override tensor buffer type. env:LLAMA_ARG_OVERRIDE_TENSOR-cmoe,--cpu-moe— keep all Mixture of Experts (MoE) weights in the CPU. env:LLAMA_ARG_CPU_MOE-ncmoe,--n-cpu-moe N— keep the Mixture of Experts (MoE) weights of the first N layers in the CPU. env:LLAMA_ARG_N_CPU_MOE-ngl,--gpu-layers,--n-gpu-layers N— max. number of layers to store in VRAM, either an exact number,'auto', or'all'(default:auto). env:LLAMA_ARG_N_GPU_LAYERS-sm,--split-mode {none,layer,row,tensor}— how to split the model across multiple GPUs, one of:none: use one GPU onlylayer(default): split layers and KV across GPUs (pipelined)row: split weight across GPUs by rows (parallelized)tensor: split weights and KV across GPUs (parallelized, EXPERIMENTAL ⚠️)
env: LLAMA_ARG_SPLIT_MODE
-ts,--tensor-split N0,N1,N2,...— fraction of the model to offload to each GPU, a comma-separated list of proportions, e.g.3,1. env:LLAMA_ARG_TENSOR_SPLIT-mg,--main-gpu INDEX— the GPU to use for the model (withsplit-mode = none), or for intermediate results and KV (withsplit-mode = row) (default:0). env:LLAMA_ARG_MAIN_GPU-fit,--fit [on|off]— whether to adjust unset arguments so they fit in device memory ('on'or'off', default:'on'). env:LLAMA_ARG_FIT-fitt,--fit-target MiB0,MiB1,MiB2,...— target margin per device for--fit, a comma-separated list of values; a single value gets broadcast across all devices, default:1024. env:LLAMA_ARG_FIT_TARGET-fitc,--fit-ctx N— minimum ctx size that can be set by the--fitoption, default:4096. env:LLAMA_ARG_FIT_CTX--check-tensors— check the model tensor data for invalid values (default:false) 🔍--override-kv KEY=TYPE:VALUE,...— an advanced option to override model metadata by key. to specify multiple overrides, either use comma-separated values. types:int,float,bool,str. example:--override-kv tokenizer.ggml.add_bos_token=bool:false,tokenizer.ggml.add_eos_token=bool:false--op-offload,--no-op-offload— whether to offload host tensor operations to the device (default:true)--lora FNAME— path to a LoRA adapter (use comma-separated values to load multiple adapters) 🎀--lora-scaled FNAME:SCALE,...— path to a LoRA adapter with user defined scaling (format:FNAME:SCALE,...). note: use comma-separated values--control-vector FNAME— add a control vector. note: use comma-separated values to add multiple control vectors--control-vector-scaled FNAME:SCALE,...— add a control vector with user defined scalingSCALE. note: use comma-separated values (format:FNAME:SCALE,...)--control-vector-layer-range START END— layer range to apply the control vector(s) to, start and end inclusive-m,--model FNAME— the model path to load. env:LLAMA_ARG_MODEL👑-mu,--model-url MODEL_URL— model download url (default: unused). env:LLAMA_ARG_MODEL_URL-dr,--docker-repo [<repo>/]<model>[:quant]— Docker Hub model repository.repois optional and defaults toai/.quantis optional and defaults to:latest. example:gemma3(default: unused). env:LLAMA_ARG_DOCKER_REPO🐳-hf,-hfr,--hf-repo <user>/<model>[:quant]
Hugging Face model repository; quant is optional, case-insensitive, default to Q4_K_M, or falls back to the first file in the repo if Q4_K_M doesn't exist. mmproj is also downloaded automatically if available. to disable, add --no-mmproj example: ggml-org/GLM-4.7-Flash-GGUF:Q4_K_M (default: unused) (env: LLAMA_ARG_HF_REPO) 💅
-hff,--hf-file FILE— Hugging Face model file. If specified, it will override the quant in--hf-repo(default: unused) (env:LLAMA_ARG_HF_FILE) ✨-hft,--hf-token TOKEN— Hugging Face access token (default: value fromHF_TOKENenvironment variable) (env:HF_TOKEN) 🔑--log-disable— Log disable 🚫--log-file FNAME— Log to file (env:LLAMA_ARG_LOG_FILE) 📝--log-colors [on|off|auto]— Set colored logging ('on', 'off', or 'auto', default: 'auto'). 'auto' enables colors when output is to a terminal (env:LLAMA_ARG_LOG_COLORS) 🌈-v,--verbose,--log-verbose— Set verbosity level to infinity (i.e. log all messages, useful for debugging) 🗣️--offline— Offline mode: forces use of cache, prevents network access (env:LLAMA_ARG_OFFLINE) ✈️-lv,--verbosity,--log-verbosity N— Set the verbosity threshold. Messages with a higher verbosity will be ignored. Values:- 0: generic output
- 1: error
- 2: warning
- 3: info
- 4: trace (more info)
- 5: debug
(default: 3) (env: LLAMA_ARG_LOG_VERBOSITY)
--log-prefix,--no-log-prefix— Enable prefix in log messages (env:LLAMA_ARG_LOG_PREFIX) 🏷️--log-timestamps,--no-log-timestamps— Enable timestamps in log messages (env:LLAMA_ARG_LOG_TIMESTAMPS) ⏰--spec-draft-type-k,-ctkd,--cache-type-k-draft TYPE— KV cache data type for K for the draft model, allowed values:f32,f16,bf16,q8_0,q4_0,q4_1,iq4_nl,q5_0,q5_1(default:f16) (env:LLAMA_ARG_SPEC_DRAFT_CACHE_TYPE_K) 🧊--spec-draft-type-v,-ctvd,--cache-type-v-draft TYPE— KV cache data type for V for the draft model, allowed values:f32,f16,bf16,q8_0,q4_0,q4_1,iq4_nl,q5_0,q5_1(default:f16) (env:LLAMA_ARG_SPEC_DRAFT_CACHE_TYPE_V) 🧊
🎀 sampling params 🎀
okay bestie this is where the flavor lives, this is the seasoning section fr fr 🍓
--samplers SAMPLERS— samplers that will be used for generation in the order, separated by;(default:penalties;dry;top_n_sigma;top_k;typ_p;top_p;min_p;xtc;temperature) 🎛️-s,--seed SEED— RNG seed (default:-1, use random seed for-1) 🎲--sampler-seq,--sampling-seq SEQUENCE— simplified sequence for samplers that will be used (default:edskypmxt) ✨--ignore-eos— ignore end of stream token and continue generating (implies--logit-bias EOS-inf) 🙈--temp,--temperature N— temperature (default:0.80) 🌡️--top-k N— top-k sampling (default:40,0= disabled) (env:LLAMA_ARG_TOP_K)--top-p N— top-p sampling (default:0.95,1.0= disabled)--min-p N— min-p sampling (default:0.05,0.0= disabled)--top-nsigma,--top-n-sigma N— top-n-sigma sampling (default:-1.00,-1.0= disabled)--xtc-probability N— xtc probability (default:0.00,0.0= disabled)--xtc-threshold N— xtc threshold (default:0.10,1.0= disabled)--typical,--typical-p N— locally typical sampling, parameter p (default:1.00,1.0= disabled)--repeat-last-n N— last n tokens to consider for penalize (default:64,0= disabled)--repeat-penalty N— penalize repeat sequence of tokens (default:1.00,1.0= disabled)--presence-penalty N— repeat alpha presence penalty (default:0.00,0.0= disabled)--frequency-penalty N— repeat alpha frequency penalty (default:0.00,0.0= disabled)--dry-multiplier N— set DRY sampling multiplier (default:0.00,0.0= disabled)--dry-base N— set DRY sampling base value (default:1.75)--dry-allowed-length N— set allowed length for DRY sampling (default:2)--dry-penalty-last-n N— set DRY penalty for the last n tokens (default:64,0= disable)--dry-sequence-breaker STRING— add sequence breaker for DRY sampling, clearing out default breakers ('\n',':','"','*') in the process; use"none"to not use any sequence breakers ✂️--adaptive-target N— adaptive-p: select tokens near this probability (valid range0.0to1.0; negative = disabled) (default:-1.00) [(more info)](https://github.com/ggml-org/llama.cpp/pull/17927) — more info lives athttps://github.com/ggml-org/llama.cpp/pull/17927🫶--adaptive-decay N— adaptive-p: decay rate for target adaptation over time. lower values are more reactive, higher values are more stable. (valid range0.0to0.99) (default:0.90)--dynatemp-range N— dynamic temperature range (default:0.00,0.0= disabled)--dynatemp-exp N— dynamic temperature exponent (default:1.00)--mirostat N— use Mirostat sampling. Top K, Nucleus and Locally Typical samplers are ignored if used. (default:0,0= disabled,1= Mirostat,2= Mirostat 2.0)--mirostat-lr N— Mirostat learning rate, parameter eta (default:0.10)--mirostat-ent N— Mirostat target entropy, parameter tau (default:5.00)-l,--logit-bias TOKEN_ID(+/-)BIAS— modifies the likelihood of token appearing in the completion, i.e.--logit-bias 15043+1to increase likelihood of token' Hello', or--logit-bias 15043-1to decrease likelihood of token' Hello'⚖️--grammar GRAMMAR— BNF-like grammar to constrain generations (see samples ingrammars/dir) 📚--grammar-file FNAME— file to read grammar from 📄-j,--json-schema SCHEMA— JSON schema to constrain generations (https://json-schema.org/), e.g.{}for any JSON object. For schemas w/ external$refs, use--grammar+example/json_schema_to_grammar.pyinstead 🧩-jf,--json-schema-file FILE— File containing a JSON schema to constrain generations (https://json-schema.org/), e.g.{}for any JSON object. For schemas w/ external$refs, use--grammar+example/json_schema_to_grammar.pyinstead 🧩-bs,--backend-sampling— enable backend sampling (experimental) (default: disabled) (env:LLAMA_ARG_BACKEND_SAMPLING) 🧪
🦋 speculative params 🦋
draft models!! the little guy that guesses ahead so the big model can vibe check it 💅
--spec-draft-hf,-hfd,-hfrd,--hf-repo-draft <user>/<model>[:quant]— Same as--hf-repo, but for the draft model (default: unused) (env:LLAMA_ARG_SPEC_DRAFT_HF_REPO) 🌸--spec-draft-threads,-td,--threads-draft N— number of threads to use during generation (default: same as--threads) 🧵--spec-draft-threads-batch,-tbd,--threads-batch-draft N— number of threads to use during batch and prompt processing (default: same as--threads-draft) 🧵--spec-draft-cpu-mask,-Cd,--cpu-mask-draft M— Draft model CPU affinity mask. Complementscpu-range-draft(default: same as--cpu-mask) 🎯--spec-draft-cpu-range,-Crd,--cpu-range-draft lo-hi— Ranges of CPUs for affinity. Complements--cpu-mask-draft🎯--spec-draft-cpu-strict,--cpu-strict-draft <0|1>— Use strict CPU placement for draft model (default: same as--cpu-strict) 📌--spec-draft-prio,--prio-draft N— set draft process/thread priority :0-normal,1-medium,2-high,3-realtime (default:0) ⚡--spec-draft-poll,--poll-draft <0|1>— Use polling to wait for draft model work (default: same as--poll) ⏳--spec-draft-cpu-mask-batch,-Cbd,--cpu-mask-batch-draft M— Draft model CPU affinity mask. Complementscpu-range-draft(default: same as--cpu-mask) 🎯--spec-draft-cpu-strict-batch,--cpu-strict-batch-draft <0|1>— Use strict CPU placement for draft model (default:--cpu-strict-draft) 📌--spec-draft-prio-batch,--prio-batch-draft N— set draft process/thread priority :0-normal,1-medium,2-high,3-realtime (default:0) ⚡--spec-draft-poll-batch,--poll-batch-draft <0|1>— Use polling to wait for draft model work (default:--poll-draft) ⏳--spec-draft-override-tensor,-otd,--override-tensor-draft <tensor name pattern>=<buffer type>,...— override tensor buffer type for draft model 🧱--spec-draft-cpu-moe,-cmoed,--cpu-moe-draft— keep all Mixture of Experts (MoE) weights in the CPU for the draft model (env:LLAMA_ARG_SPEC_DRAFT_CPU_MOE) 💜--spec-draft-n-cpu-moe,--spec-draft-ncmoe,-ncmoed,--n-cpu-moe-draft N— keep the Mixture of Experts (MoE) weights of the first N layers in the CPU for the draft model (env:LLAMA_ARG_SPEC_DRAFT_N_CPU_MOE) 💜--spec-draft-n-max N— number of tokens to draft for speculative decoding (default:3) (env:LLAMA_ARG_SPEC_DRAFT_N_MAX) 🔢--spec-draft-n-min N— minimum number of draft tokens to use for speculative decoding (default:0) (env:LLAMA_ARG_SPEC_DRAFT_N_MIN) 🔢--spec-draft-p-split,--draft-p-split P— speculative decoding split probability (default:0.10) (env:LLAMA_ARG_SPEC_DRAFT_P_SPLIT) ✂️--spec-draft-p-min,--draft-p-min P— minimum speculative decoding probability (greedy) (default:0.00) (env:LLAMA_ARG_SPEC_DRAFT_P_MIN) ✂️--spec-draft-backend-sampling,--no-spec-draft-backend-sampling— offload draft sampling to the backend (default: enabled) (env:LLAMA_ARG_SPEC_DRAFT_BACKEND_SAMPLING) 🧪--spec-draft-device,-devd,--device-draft <dev1,dev2,..>— comma-separated list of devices to use for offloading the draft model (none= don't offload), use--list-devicesto see a list of available devices 💻--spec-draft-ngl,-ngld,--gpu-layers-draft,--n-gpu-layers-draft N— max. number of draft model layers to store in VRAM, either an exact number,'auto', or'all'(default:auto) (env:LLAMA_ARG_N_GPU_LAYERS_DRAFT) 🎮--spec-draft-model,-md,--model-draft FNAME— draft model for speculative decoding (default: unused) (env:LLAMA_ARG_SPEC_DRAFT_MODEL) 🧚--spec-typenone,draft-simple,draft-eagle3,draft-mtp,draft-dflash,draft-dspark,ngram-simple,ngram-map-k,ngram-map-k4v,ngram-mod,ngram-cache— comma-separated list of types of speculative decoding to use (default:none) (env:LLAMA_ARG_SPEC_TYPE) 🌈--spec-ngram-mod-n-min N— minimum number of ngram tokens to use for ngram-based speculative decoding (default:48) 🔢--spec-ngram-mod-n-max N— the absolute max number of ngram tokens we're allowed to use for ngram-based speculative decoding (default:64). cap it, bestie 💅--spec-ngram-mod-n-match N— how long the ngram-mod lookup is (default:24) 🔍--spec-ngram-simple-size-n N— the ngram sizeNfor ngram-simple speculative decoding, aka the length of the lookup n-gram (default:12) ✨--spec-ngram-simple-size-m N— the ngram sizeMfor ngram-simple speculative decoding, aka the length of the draft m-gram (default:48) 🌸--spec-ngram-simple-min-hits N— minimum hits required for ngram-simple speculative decoding (default:1) 🎯--spec-ngram-map-k-size-n N— ngram sizeNfor ngram-map-k speculative decoding, the length of the lookup n-gram (default:12) 💖--spec-ngram-map-k-size-m N— ngram sizeMfor ngram-map-k speculative decoding, the length of the draft m-gram (default:48) 🦋--spec-ngram-map-k-min-hits N— minimum hits for ngram-map-k speculative decoding (default:1) ⭐--spec-ngram-map-k4v-size-n N— ngram sizeNfor ngram-map-k4v speculative decoding, the length of the lookup n-gram (default:12) 🧚--spec-ngram-map-k4v-size-m N— ngram sizeMfor ngram-map-k4v speculative decoding, the length of the draft m-gram (default:48) 💜--spec-ngram-map-k4v-min-hits N— minimum hits for ngram-map-k4v speculative decoding (default:1) 🌈--draft,--draft-n,--draft-max N— okay so this one got removed 😭 use--spec-draft-n-maxor--spec-ngram-mod-n-maxinstead (env:LLAMA_ARG_DRAFT_MAX)--draft-min,--draft-n-min N— also removed 💀 use--spec-draft-n-minor--spec-ngram-mod-n-min(env:LLAMA_ARG_DRAFT_MIN)--spec-ngram-size-n N— removed, she's gone 🙈 use the respective--spec-ngram-*-size-nor--spec-ngram-mod-n-match--spec-ngram-size-m N— removed 🥀 use the respective--spec-ngram-*-size-m--spec-ngram-min-hits N— removed 💔 use the respective--spec-ngram-*-min-hits
✨ ----- example-specific params ----- ✨
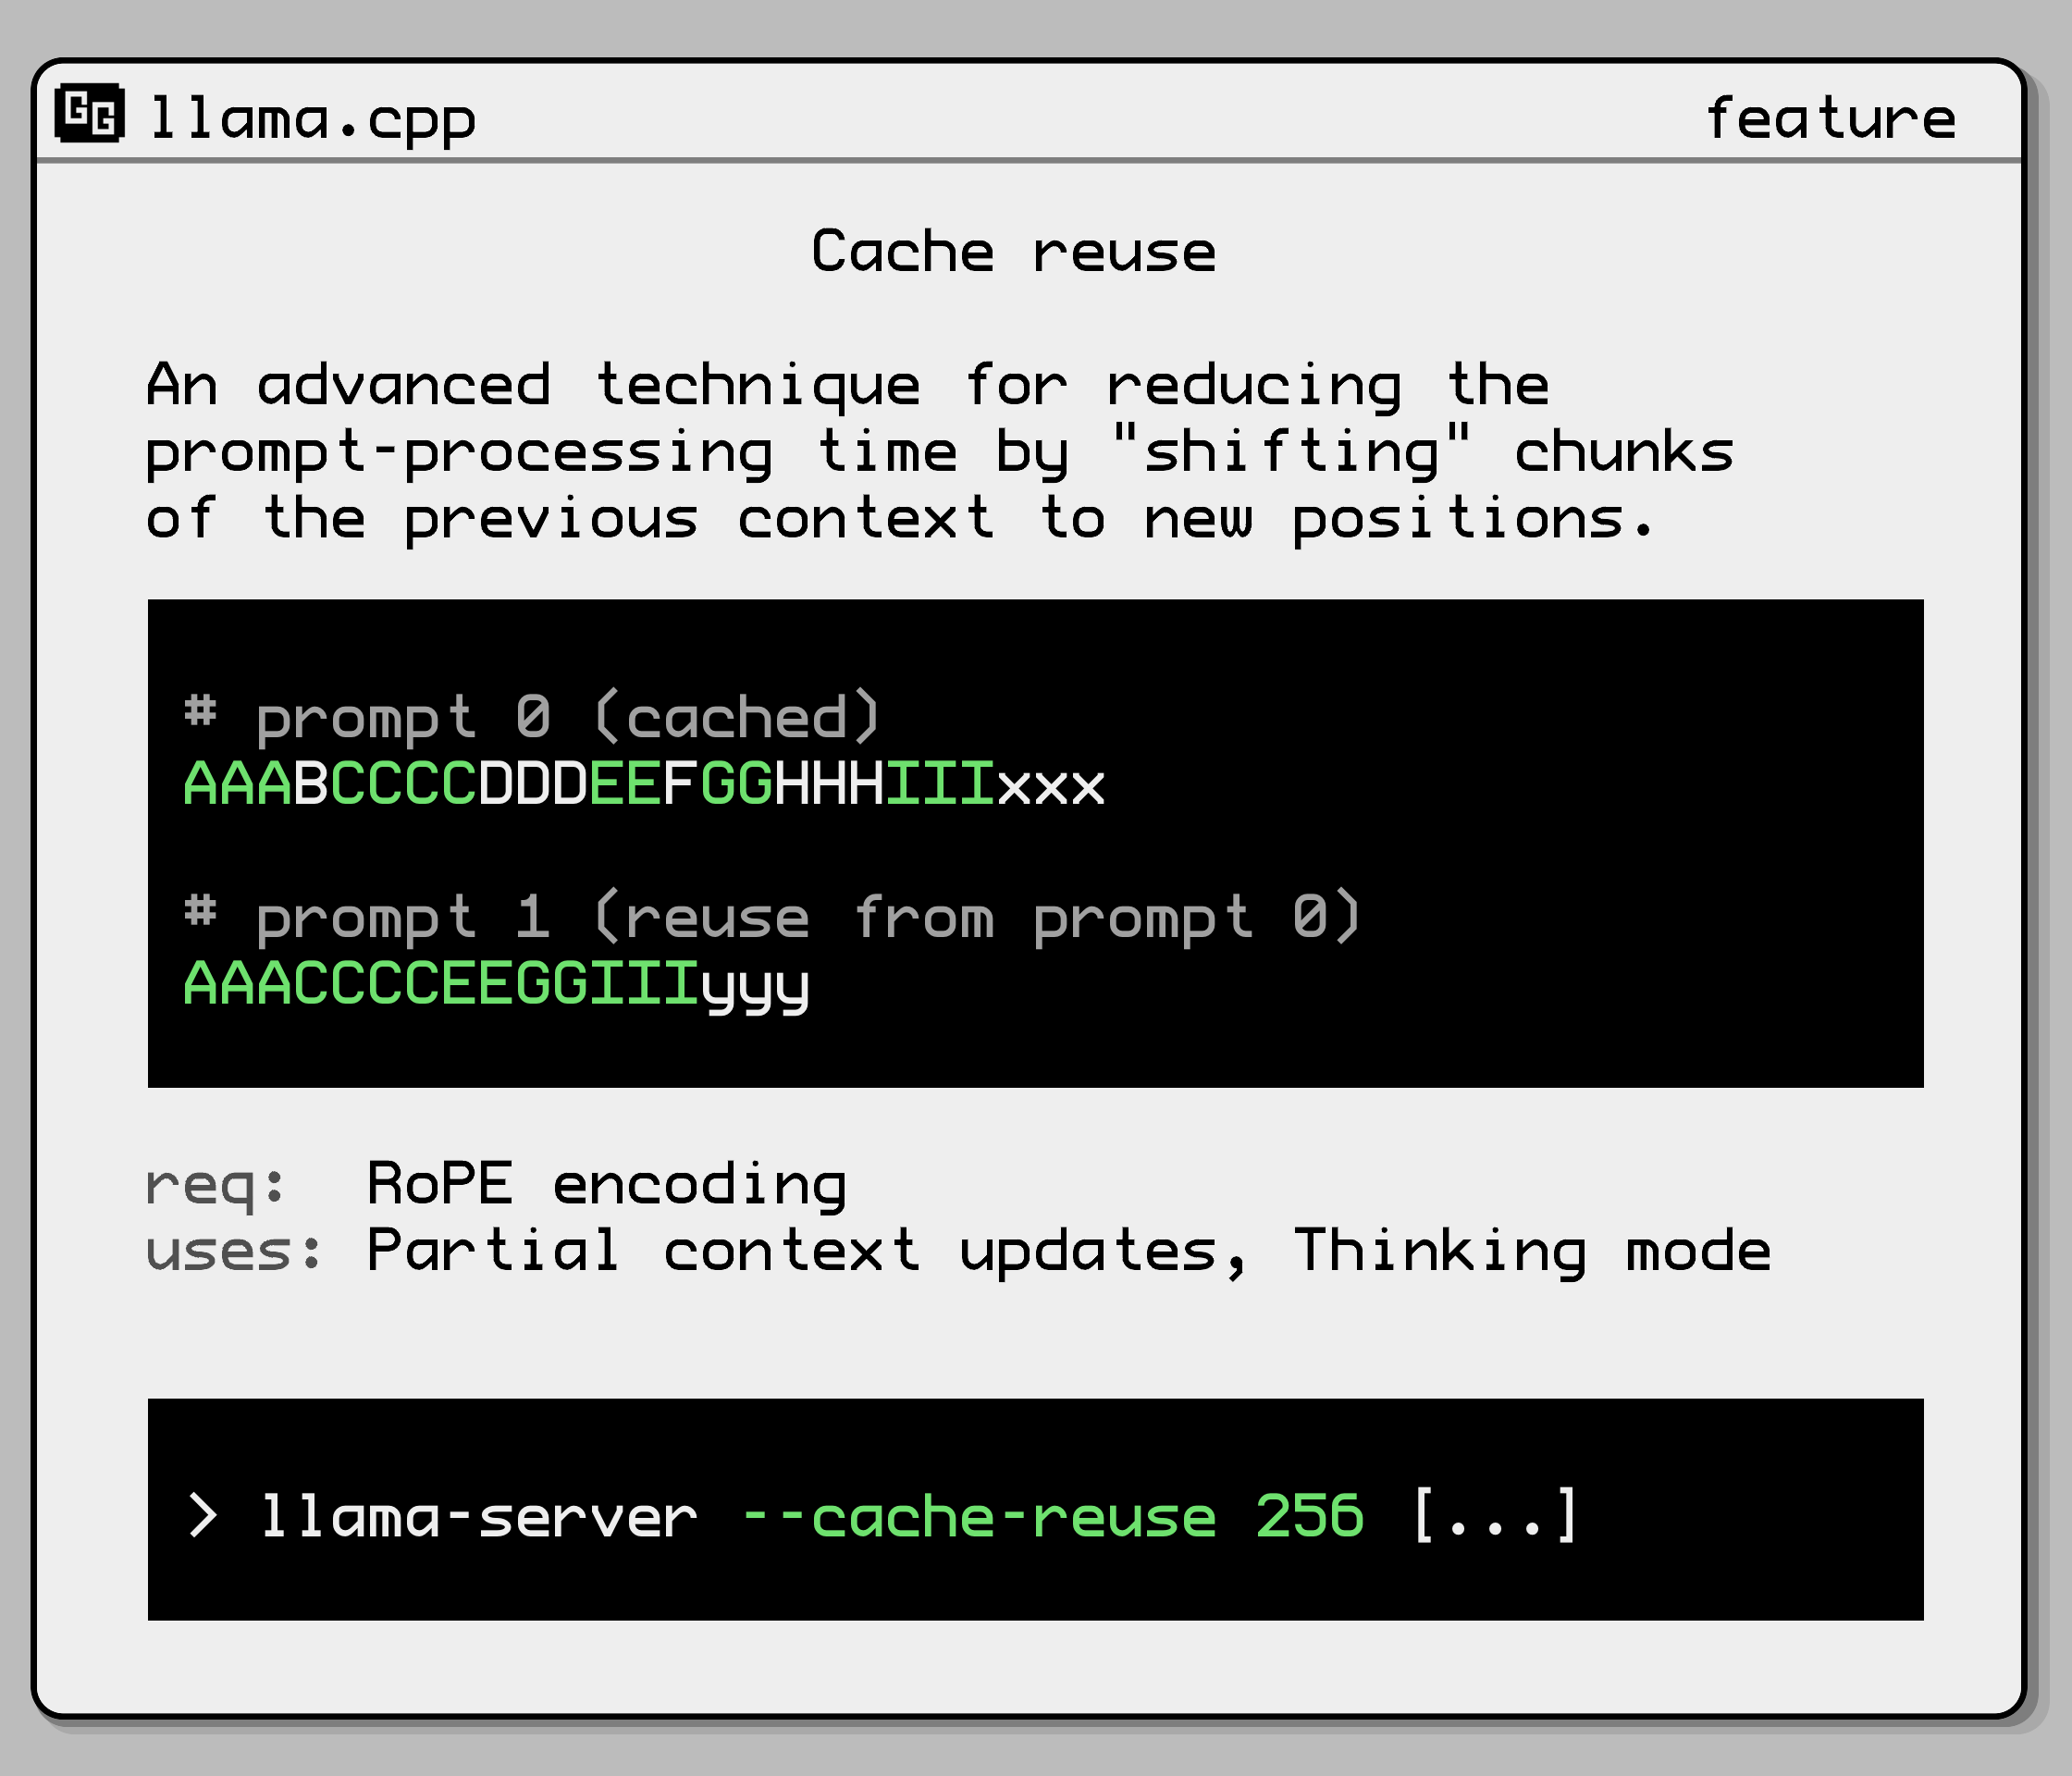
-lcs,--lookup-cache-static FNAME— path to the static lookup cache to use for lookup decoding (heads up: it does not get updated by generation) 📖-lcd,--lookup-cache-dynamic FNAME— path to the dynamic lookup cache to use for lookup decoding (this one does get updated by generation) 🔄-ctxcp,--ctx-checkpoints,--swa-checkpoints N— max number of context checkpoints to create per slot (default:32) (more info athttps://github.com/ggml-org/llama.cpp/pull/15293) (env:LLAMA_ARG_CTX_CHECKPOINTS) 🧷-cms,--checkpoint-min-step N— minimum spacing between context checkpoints, in tokens (default:8192, and0= no minimum) (env:LLAMA_ARG_CHECKPOINT_MIN_SPACING_NT) 📏-cram,--cache-ram N— set the maximum cache size in MiB (default:8192,-1= no limit,0= disable) (more info athttps://github.com/ggml-org/llama.cpp/pull/16391) (env:LLAMA_ARG_CACHE_RAM) 🍓-kvu,--kv-unified,-no-kvu,--no-kv-unified— use a single unified KV buffer shared across all sequences (default: enabled if the number of slots is auto) (env:LLAMA_ARG_KV_UNIFIED) 🫶--cache-idle-slots,--no-cache-idle-slots— save idle slots to the prompt cache on a new task, and clear them when using unified KV (default: enabled, requirescache-ram) (env:LLAMA_ARG_CACHE_IDLE_SLOTS) 💤--context-shift,--no-context-shift— whether to use context shift on infinite text generation (default: disabled) (env:LLAMA_ARG_CONTEXT_SHIFT) ♾️-r,--reverse-prompt PROMPT— halt generation atPROMPT, and return control in interactive mode 🛑-sp,--special— special tokens output enabled (default:false) 🔮--warmup,--no-warmup— whether to perform a warmup with an empty run (default: enabled) 🔥--spm-infill— use Suffix/Prefix/Middle pattern for infill (instead of Prefix/Suffix/Middle), because some models prefer it that way. (default: disabled) 🧩--pooling {none,mean,cls,last,rank}— pooling type for embeddings; uses the model default if you don't specify one (env:LLAMA_ARG_POOLING) 🏊-np,--parallel N— number of server slots (default:-1, and-1= auto) (env:LLAMA_ARG_N_PARALLEL) 👯-cb,--cont-batching,-nocb,--no-cont-batching— whether to enable continuous batching (a.k.a dynamic batching) (default: enabled) (env:LLAMA_ARG_CONT_BATCHING) 📦-mm,--mmproj FILE— path to a multimodal projector file. seetools/mtmd/README.md— note: if-hfis used, this argument can be omitted (env:LLAMA_ARG_MMPROJ) 🖼️-mmu,--mmproj-url URL— URL to a multimodal projector file. seetools/mtmd/README.md(env:LLAMA_ARG_MMPROJ_URL) 🌐--mmproj-auto,--no-mmproj,--no-mmproj-auto— whether to use a multimodal projector file (if available), which is super useful when using-hf(default: enabled) (env:LLAMA_ARG_MMPROJ_AUTO) 🤖--mmproj-offload,--no-mmproj-offload— whether to enable GPU offloading for the multimodal projector (default: enabled) (env:LLAMA_ARG_MMPROJ_OFFLOAD) ⚡--image-min-tokens N— minimum number of tokens each image can take, only used by vision models with dynamic resolution (default: read from model) (env:LLAMA_ARG_IMAGE_MIN_TOKENS) 🐜--image-max-tokens N— maximum number of tokens each image can take, only used by vision models with dynamic resolution (default: read from model) (env:LLAMA_ARG_IMAGE_MAX_TOKENS) 🐘--mtmd-batch-max-tokens N— maximum number of image tokens per batch when encoding images (default:1024) (env:LLAMA_ARG_MTMD_BATCH_MAX_TOKENS) 🎞️-a,--alias STRING— set model name aliases, comma-separated (to be used by the API) (env:LLAMA_ARG_ALIAS) 🏷️--tags STRING— set model tags, comma-separated (informational, not used for routing) (env:LLAMA_ARG_TAGS) 🎀--embd-normalize N— normalisation for embeddings (default:2) —-1=none,0=max absolute int16,1=taxicab,2=euclidean,>2=p-norm 📐--host HOST— ip address to listen on, or bind to a UNIX socket if the address ends with.sock(default:127.0.0.1) (env:LLAMA_ARG_HOST) 🏠--port PORT— port to listen on (default:8080) (env:LLAMA_ARG_PORT) 🚪--reuse-port— allow multiple sockets to bind to the same port (default: disabled) (env:LLAMA_ARG_REUSE_PORT) ♻️--path PATH— path to serve static files from (default: empty) (env:LLAMA_ARG_STATIC_PATH) 📁--cors-origins ORIGINS— comma-separated list of allowed origins for CORS (default:*); if set to the special valuelocalhost, it reflects the Origin header only if it is localhost (env:LLAMA_ARG_CORS_ORIGINS) 🌍--cors-methods METHODS— comma-separated list of allowed methods for CORS (default:GET, POST, DELETE, OPTIONS) (env:LLAMA_ARG_CORS_METHODS) ✋--cors-headers HEADERS— comma-separated list of allowed headers for CORS (default:*) (env:LLAMA_ARG_CORS_HEADERS) 📋--cors-credentials,--no-cors-credentials— whether to allow credentials for CORS (default: enabled) — note: if this is enabled and--cors-originsis set to*(the default), the Origin header will be echoed back, and credentials will always be allowed (env:LLAMA_ARG_CORS_CREDENTIALS) 🔑--api-prefix PREFIX— prefix path the server serves from, without the trailing slash (default: empty) (env:LLAMA_ARG_API_PREFIX) 🛣️--ui-config,--webui-config JSON— JSON that provides default UI settings (overrides UI defaults) (env:LLAMA_ARG_UI_CONFIG) 🎛️--ui-config-file,--webui-config-file PATH— JSON file that provides default UI settings (overrides UI defaults) (env:LLAMA_ARG_UI_CONFIG_FILE) 📄--ui-mcp-proxy,--webui-mcp-proxy,--no-ui-mcp-proxy,--no-webui-mcp-proxy— experimental: whether to enable the MCP CORS proxy — do not enable in untrusted environments (default: disabled) (env:LLAMA_ARG_UI_MCP_PROXY) ⚠️--tools TOOL1,TOOL2,...— experimental: whether to enable built-in tools for AI agents — do not enable in untrusted environments (default: no tools). specify"all"to enable all tools. available tools:read_file,file_glob_search,grep_search,exec_shell_command,write_file,edit_file,get_datetime,get_info. note: for security reasons, this will limit--cors-originsto localhost by default (env:LLAMA_ARG_TOOLS) 🛠️--tools-runtime OPTION— experimental: run tools in a separate runtime environment (default:none, i.e. use the host environment). available options:'docker:<image>','podman:<image>': spin up a new container and reuse it for all invocations, clean up on server exit.'docker-container:<id>','podman-container:<id>': use an existing container by ID, and it won't stop on server exit.'ssh:<target>': run tools on a remote POSIX host over SSH, key-based auth and a trusted host key are required (env:LLAMA_ARG_TOOLS_RUNTIME) 🐳--mcp-servers-config PATH— experimental: path to a JSON file with MCP server definitions (Cursor-compatible format) — do not enable in untrusted environments (default: none). note: for security reasons, this will limit--cors-originsto localhost by default (env:LLAMA_ARG_MCP_SERVERS_CONFIG) 📚--mcp-servers-json JSON— experimental: inline JSON with MCP server definitions (Cursor-compatible format) — do not enable in untrusted environments (default: none). note: for security reasons, this will limit--cors-originsto localhost by default (env:LLAMA_ARG_MCP_SERVERS_JSON) 🧾-ag,--agent,-no-ag,--no-agent— whether to enable the CORS proxy and all built-in tools — do not enable in untrusted environments (default: disabled). note: for security reasons, this will limit--cors-originsto localhost by default (env:LLAMA_ARG_AGENT) 🕵️--ui,--webui,--no-ui,--no-webui— whether to enable the Web UI (default: enabled) (env:LLAMA_ARG_UI) 🖥️--embedding,--embeddings— restrict to only support the embedding use case; use only with dedicated embedding models (default: disabled) (env:LLAMA_ARG_EMBEDDINGS) 🧲--rerank,--reranking— enable the reranking endpoint on the server (default: disabled) (env:LLAMA_ARG_RERANKING) 🥇--api-key KEY— API key to use for authentication, and multiple keys can be provided as a comma-separated list (default: none) (env:LLAMA_API_KEY) 🔐--api-key-file FNAME— the path to a file holding your API keys, one per line</p>, bestie. Lines that start with a#are treated as comments, so go ahead and annotate 💅 (default: none) (env:LLAMA_ARG_API_KEY_FILE)--ssl-key-file FNAME— path to a file with a PEM-encoded SSL private key 🔐 (env:LLAMA_ARG_SSL_KEY_FILE)--ssl-cert-file FNAME— path to a file with a PEM-encoded SSL certificate 📜 (env:LLAMA_ARG_SSL_CERT_FILE)--chat-template-kwargs STRING— sets extra params for the json template parser, and it has to be a valid json object string, like'{"key1":"value1","key2":"value2"}'— no vibes-based json allowed, it's giving strict 🧾 (env:LLAMA_ARG_CHAT_TEMPLATE_KWARGS)-to,--timeout N— server read/write timeout in seconds ⏰ (default: 3600) (env:LLAMA_ARG_TIMEOUT)--sse-ping-interval N— server SSE ping interval in seconds, and-1= disabled, so if you want it quiet just say that ✨ (default: 30) (env:LLAMA_ARG_SSE_PING_INTERVAL)--threads-http N— how many threads get to process HTTP requests 🧵 (default: -1) (env:LLAMA_ARG_THREADS_HTTP)--cache-prompt,--no-cache-prompt— whether to enable prompt caching, it's on by default because of course it is 💖 (default: enabled) (env:LLAMA_ARG_CACHE_PROMPT)--cache-reuse N— the min chunk size to attempt reusing from the cache via KV shifting, and heads up: it requires prompt caching to be enabled, so no caching no reusing no debate 🙈 (default: 0)[(card)](https://ggml.ai/f0.png)(env:LLAMA_ARG_CACHE_REUSE)--metrics— enable the prometheus compatible metrics endpoint 📊 (default: disabled) (env:LLAMA_ARG_ENDPOINT_METRICS)--props— enable changing global properties viaPOST /props🎛️ (default: disabled) (env:LLAMA_ARG_ENDPOINT_PROPS)--slots,--no-slots— expose the slots monitoring endpoint 👀 (default: enabled) (env:LLAMA_ARG_ENDPOINT_SLOTS)--slot-save-path PATH— path to save the slot kv cache 💾 (default: disabled)--media-path PATH— directory for loading local media files; files can be accessed viafile://URLs using relative paths 🖼️ (default: disabled)--models-dir PATH— directory containing models for the router server 📁 (default: disabled) (env:LLAMA_ARG_MODELS_DIR)--models-preset PATH— path to an INI file containing model presets for the router server 📝 (default: disabled) (env:LLAMA_ARG_MODELS_PRESET)--models-max N— for the router server, the maximum number of models to load simultaneously ✋ (default: 4, 0 = unlimited) (env:LLAMA_ARG_MODELS_MAX)--models-autoload,--no-models-autoload— for the router server, whether to automatically load models 🤖 (default: enabled) (env:LLAMA_ARG_MODELS_AUTOLOAD)--jinja,--no-jinja— whether to use the jinja template engine for chat 🧚 (default: enabled) (env:LLAMA_ARG_JINJA)--reasoning-format FORMAT— this one controls whether thought tags are allowed and/or extracted from the response, and in which format they're returned; it's one of:none: leaves thoughts unparsed inmessage.contentdeepseek: puts thoughts inmessage.reasoning_contentdeepseek-legacy: keeps `` tags inmessage.contentwhile also populatingmessage.reasoning_content
(default: auto) (env: LLAMA_ARG_THINK)
-rea,--reasoning [on|off|auto]— use reasoning/thinking in the chat; it's'on','off', or'auto'🧠 (default:'auto'(detect from template)) (env:LLAMA_ARG_REASONING)--reasoning-effort LEVEL— the reasoning effort level handed to the chat template:'default'keeps the template default, or you give it a level such as'minimal','low','medium','high','xhigh'or'max'🔥 (default: default) (env:LLAMA_ARG_REASONING_EFFORT)--reasoning-budget N— token budget for thinking:-1for unrestricted,0for immediate end,N>0for token budget 🪙 (default: -1) (env:LLAMA_ARG_THINK_BUDGET)--reasoning-budget-message MESSAGE— the message injected before the end-of-thinking tag when the reasoning budget is exhausted 💬 (default: none) (env:LLAMA_ARG_THINK_BUDGET_MESSAGE)--reasoning-preserve,--no-reasoning-preserve— preserve the reasoning trace in the full history, not just the last assistant message 🫶 (default: template default) — compatible with certain templates having'supports_preserve_reasoning'capability, and the original drops an example athttps://docs.z.ai/guides/capabilities/thinking-mode#preserved-thinking(env:LLAMA_ARG_REASONING_PRESERVE)--chat-template JINJA_TEMPLATE— set a custom jinja chat template 🎀 (default: template taken from model's metadata) — but ngl there's fine print: if suffix/prefix are specified, the template will be disabled, and only commonly used templates are accepted (unless--jinjais set before this flag). Here's the list of built-in templates:
bailing, bailing-think, bailing2, chatglm3, chatglm4, chatml, command-r,
deepseek, deepseek-ocr, deepseek2, deepseek3, exaone-moe, exaone3, exaone4,
falcon3, gemma, gigachat, glmedge, gpt-oss, granite, granite-4.0, granite-4.1,
grok-2, hunyuan-dense, hunyuan-moe, hunyuan-vl, kimi-k2, llama2, llama2-sys,
llama2-sys-bos, llama2-sys-strip, llama3, llama4, megrez, minicpm, mistral-v1,
mistral-v3, mistral-v3-tekken, mistral-v7, mistral-v7-tekken, monarch,
openchat, orion, pangu-embedded, phi3, phi4, rwkv-world, seed_oss, smolvlm,
solar-open, vicuna, vicuna-orca, yandex, zephyr
(env: LLAMA_ARG_CHAT_TEMPLATE)
--chat-template-file JINJA_TEMPLATE_FILE— same deal but you point it at a file with a custom jinja chat template 📄 (default: template taken from model's metadata) — again: if suffix/prefix are specified, the template will be disabled, only commonly used templates are accepted (unless--jinjais set before this flag), and the built-in list is:
bailing, bailing-think, bailing2, chatglm3, chatglm4, chatml, command-r,
deepseek, deepseek-ocr, deepseek2, deepseek3, exaone-moe, exaone3, exaone4,
falcon3, gemma, gigachat, glmedge, gpt-oss, granite, granite-4.0, granite-4.1,
grok-2, hunyuan-dense, hunyuan-moe, hunyuan-vl, kimi-k2, llama2, llama2-sys,
llama2-sys-bos, llama2-sys-strip, llama3, llama4, megrez, minicpm, mistral-v1,
mistral-v3, mistral-v3-tekken, mistral-v7, mistral-v7-tekken, monarch,
openchat, orion, pangu-embedded, phi3, phi4, rwkv-world, seed_oss, smolvlm,
solar-open, vicuna, vicuna-orca, yandex, zephyr
(env: LLAMA_ARG_CHAT_TEMPLATE_FILE)
--skip-chat-parsing,--no-skip-chat-parsing— force a pure content parser, even if a Jinja template is specified; the model will output everything in the content section, including any reasoning and/or tool calls 🌪️ (default: disabled) (env:LLAMA_ARG_SKIP_CHAT_PARSING)--prefill-assistant,--no-prefill-assistant— whether to prefill the assistant's response if the last message is an assistant message 🗣️ (default: prefill enabled) — when this flag is set, if the last message is an assistant message then it will be treated as a full message and not prefilled (env:LLAMA_ARG_PREFILL_ASSISTANT)-sps,--slot-prompt-similarity SIMILARITY— how much the prompt of a request must match the prompt of a slot in order to use that slot 🎯 (default: 0.10, 0.0 = disabled)--lora-init-without-apply— load LoRA adapters without applying them, then apply later viaPOST /lora-adapters🧩 (default: disabled)--sleep-idle-seconds SECONDS— number of seconds of idleness after which the server will sleep 😴 (default: -1; -1 = disabled)--log-prompts-dir PATH— log prompts to a directory, which gets auto-created if it's not already there; heads up, this is only used for debugging 🐛 (default: disabled)--embd-gemma-default— use the default EmbeddingGemma model 🧲 (note: can download weights from the internet)--fim-qwen-1.5b-default— use default Qwen 2.5 Coder 1.5B ✍️ (note: can download weights from the internet)--fim-qwen-3b-default— use default Qwen 2.5 Coder 3B ✍️ (note: can download weights from the internet)--fim-qwen-7b-default— use default Qwen 2.5 Coder 7B ✍️ (note: can download weights from the internet)--fim-qwen-7b-spec— use Qwen 2.5 Coder 7B + 0.5B draft for speculative decoding ⚡ (note: can download weights from the internet)--fim-qwen-14b-spec— use Qwen 2.5 Coder 14B + 0.5B draft for speculative decoding ⚡ (note: can download weights from the internet)--fim-qwen-30b-default— use default Qwen 3 Coder 30B A3B Instruct 👑 (note: can download weights from the internet)--gpt-oss-20b-default— use gpt-oss-20b 🫧 (note: can download weights from the internet)--gpt-oss-120b-default— use gpt-oss-120b 🌈 (note: can download weights from the internet)--vision-gemma-4b-default— use Gemma 3 4B QAT 👁️ (note: can download weights from the internet)--vision-gemma-12b-default— use Gemma 3 12B QAT 👁️ (note: can download weights from the internet)--spec-default— enable the default speculative decoding config ✨
and that's a wrap on the whole page, bestie 🎀 fr fr you now know every single flag. this one's a debian situation, dated September 2026, living under the name LLAMA-SERVER(1) — go be the main character of your own server 💅✨
📦 where this page comes from
- ubuntu stonking: llama.cpp-tools 10438+dfsg-1ubuntu1 · MIT
- 💖 girlified by deepseek-ai/DeepSeek-V4.1-Flash on : a language model's rewrite of the original, under its terms